Steven Hé (Sīchàng)
Hello there, Steven here:
- Systems programmer, Rustacean, Pythonista, Elixirist, Vimmer.
- Analytical, skeptical, empirical, optimistic nihilist.
- Computer Science Ph.D. student, Networked Systems Lab (NSL), University of Southern California (USC).
- Advisor: Harsha V. Madhyastha.
- Also work with Ramesh Govindan.
- Research Interests: the Web, Networking, SE, PL, HPC.
- 👉 For USC undergrads/MS students interested in CS/EE/DS research.
- For experiences, publications, contact, etc., please see the CV linked below. For more personal info, see About.

Link farm
 GitHub
 Channel
2026 News
- (2026-04-30) 📖🌐 See our paper preprint: DeGenTWeb: A First Look at LLM-Dominant Websites.
2025 News
- (2025-11-08) 💬🌐 I recorded a retroactive presentation for my DeGenTWeb talk at IMC 2025 Student Workshop.
- (2025-10-10) 🪧🌐 See our ACM IMC Poster (accepted earlier, edit: and student workshop slides): Poster: Did I Just Browse A Website Written by LLMs?
- (2025-08-11) 📖🌐 ACM IMC accepted our 2-page student workshop paper: Preprint: Did I Just Browse A Website Written by LLMs?.
- (2025-01-09) 🌐🤖 I sketched the DeGenTWeb project to detect and study LLM-generated text content on the Web.
2024 Fall News
(2024-12-13) 🤖💀 I posted a survey of generative AI problems and countermeasurements, which showed many business, cryptography, and computer vision problems remain in this field.
(2024-11-27) ⭕💀 We paused the JSphere project that classifies the use of JavaScript on the Web by browser API calls. Preliminary results are in a report for a course and a colorful poster.
Feel free to take over this project.
(2024-11-05) 💬🌐 I recorded a retroactive presentation for my RPSLyzer talk at IMC ’24.
(2024-11-05) 💬🌐 I presented the RPSLyzer paper at IMC ’24 in Madrid and met nice people at the conference. The conference has no recordings, unfortunately.
(2024-09-15) 🐍🥲 My Battlesnake “TinyViTMCTS” will go down on the leaderboard because Duke is shutting down the VM it runs on.
(2024-09-12) 📖🌐 I posted the camera-ready PDF version of the RPSLyzer paper. Download it from the Internet Route Verification repository’s Releases.
(2024-08-27) 📖💵 The IMC Student Travel Grant committee generously awarded me funds, so that I can go present my paper at the conference.
(2024-08-23) 🏠🔬 I moved to Los Angeles and joined the USC Networked Systems Lab as a Ph.D. student, working with Professor Harsha V. Madhyastha.
(2024-07-31) 📖🎉 ACM Internet Measurement Conference (IMC) 2024 accepted our paper, RPSLyzer: Characterization and Verification of Policies in Internet Routing Registries, by Sichang He, Italo Cunha, and Ethan Katz-Bassett. We will post drafts in the Internet Route Verification repository.
(2024-07-24) 🌐⭕ I sketched the JSphere project to study the overuse of JavaScript in websites.
(2024-07-03) 🐙🇬🇧 I started developing the Natural Syntax Language Server to highlight part-of-speech for ease of reading.
To comment on the news, please go to the news page.
Press s to search, press → for next page!
Last edited:
About
Research Interests
Current:
- Anti-MLsys: Detect and understand LLM-generated web content.
- Efficient LLM agents for the Web/ programming through domain knowledge.
- Efficient scalable agentic software development with strong correctness and reliability guarantees.
Wider areas:
- Understanding the Web’s structures and contents.
- Intersections with sciences.
- Efficient and high-performance computing with CPU cache optimization.
- Automation for software engineering tasks with LLMs.
- Robust and user-friendly distributed computing like for websites and databases.
- Programming language infrastructure to enable robust static analysis.
Previous: Federated learning, Internet routing, content provenance (C2PA).
Leisure Interests & Personal Trivia
- Programming languages: Rust, Elixir, and other modern expression languages with algebraic types, first-class pattern matching, function composition, etc. without class inheritance.
- Sports: I walk and jog outdoor and do casual GYM workout regularly, and I sometimes hike. Played badminton before. Trying bouldering sometimes now.
- Physical science & technology: human health, general Biology, aviation, spaceflight. I have a background in Biology and organic Chemistry.
- Art: I go to cities like Shanghai, NYC, and Chicago only for museum and gallery. I like some of the classical music, much of impressionist paintings, and some simplistic modern art. I regard most modern songs, pop culture, and “contemporary art” as unworthy, and do not appreciate makeups and heavy decorations people wear.
- Food: I like food from natural ingredients and simple cooking. Hate random food being sweet. High tolerance on spicy food. I look down upon general US food as bad tasting and unhealthy, so I cook a lot.
Contact
- Email: See the address in my CV. I get notifications and reply.
- I block whoever sends spam immediately.
- Ping me if I do not reply in three days.
- GitHub: Ping me for code-related discussions. I get emails.
Name
The legal name is “Sichang He” (何思畅, or 何思暢). Steven is the preferred English name. The name used in publications is Sichang Steven He.
Name pronunciation
Google Translate pronounces it correctly (Click Listen). Serializing it into English is impossible; the best you can get is h-ehh? ss—↑ ch-ah-ng↓, where you pronounce the syllabic consonant “ss—” by vibrating your vocal chord while saying the consonant “ss” so it sounds like there’s a vowel.
Prior Mentees
At Edge Intelligence Lab, DKU:
- Qingning Zeng when we worked on the FedCampus App. He got his ECE MS at Duke and went to Snowflake.
- Luyao Wang when we worked on the FedCampus App. He went to UCI for a CS MS.
- Boyan Zhang (Johnny) when we worked on FedCampus. He had been an undergrad at DKU.
- Aicha Slaitane (briefly) when she explored research directions. She went to KAUST for a CS PhD.
- Beilong Tang when we worked on the FedCampus App and campus-wide federated analytics experiments. He went to NCSU for an ECE PhD.
I also recruited these folks to Edge Intelligence Lab:
- Ningyuan Yang. He went to Duke for an ECE PhD.
- Yuxiang Lin. He went to UC Riverside for a CS PhD.
For Undergrads/MS
I am looking for you if you want to 1) participate in research (≠ want to do a PhD) and b) are suitable for working on something we are both interested in. I teach, so don’t worry about lacking specific skills.
You are welcome to email me succinctly to discuss your interests and suitability.
Necessary qualities:
- Ambition: You always want to achieve something greater and self improve.
- Dedication: If you do something, you do it well.
- Availability: You can spend lots of high-quality time on research.
Necessary skills (learnable):
- Learning: You learn new things quickly.
- Language: You can input (read/listen) and output (write/speak) technical and proper English (≠ technical papers), including instructions and docs of libraries.
- Computer: You are fluent in typing, a text editor, a scripting language, a systems language, and are generally familiar with basic OS terms.
Very helpful skills (non-exhaustive):
- You can implement complex systems.
- You can analyze & visualize messy domain-specific data.
- You can do literature review.
- You can read technical papers.
Last edited:
News
2025 News
- (2025-11-08) 💬🌐 I recorded a retroactive presentation for my DeGenTWeb talk at IMC 2025 Student Workshop.
- (2025-10-10) 🪧🌐 See our ACM IMC Poster (accepted earlier, edit: and student workshop slides): Poster: Did I Just Browse A Website Written by LLMs?
- (2025-08-11) 📖🌐 ACM IMC accepted our 2-page student workshop paper: Preprint: Did I Just Browse A Website Written by LLMs?.
- (2025-01-09) 🌐🤖 I sketched the DeGenTWeb project to detect and study LLM-generated text content on the Web.
Last edited:
2024 Fall
2024 Fall News
(2024-12-13) 🤖💀 I posted a survey of generative AI problems and countermeasurements, which showed many business, cryptography, and computer vision problems remain in this field.
(2024-11-27) ⭕💀 We paused the JSphere project that classifies the use of JavaScript on the Web by browser API calls. Preliminary results are in a report for a course and a colorful poster.
Feel free to take over this project.
(2024-11-05) 💬🌐 I recorded a retroactive presentation for my RPSLyzer talk at IMC ’24.
(2024-11-05) 💬🌐 I presented the RPSLyzer paper at IMC ’24 in Madrid and met nice people at the conference. The conference has no recordings, unfortunately.
(2024-09-15) 🐍🥲 My Battlesnake “TinyViTMCTS” will go down on the leaderboard because Duke is shutting down the VM it runs on.
(2024-09-12) 📖🌐 I posted the camera-ready PDF version of the RPSLyzer paper. Download it from the Internet Route Verification repository’s Releases.
(2024-08-27) 📖💵 The IMC Student Travel Grant committee generously awarded me funds, so that I can go present my paper at the conference.
(2024-08-23) 🏠🔬 I moved to Los Angeles and joined the USC Networked Systems Lab as a Ph.D. student, working with Professor Harsha V. Madhyastha.
(2024-07-31) 📖🎉 ACM Internet Measurement Conference (IMC) 2024 accepted our paper, RPSLyzer: Characterization and Verification of Policies in Internet Routing Registries, by Sichang He, Italo Cunha, and Ethan Katz-Bassett. We will post drafts in the Internet Route Verification repository.
(2024-07-24) 🌐⭕ I sketched the JSphere project to study the overuse of JavaScript in websites.
(2024-07-03) 🐙🇬🇧 I started developing the Natural Syntax Language Server to highlight part-of-speech for ease of reading.
Last edited:
2024 Spring
2024 Spring News
- (2024-03-15) 💬🌻 I gave of a talk and presented a poster at Flower AI Summit 2024. The talk is FedCampus: A Privacy-preserving Smart Campus by Bing Luo and Sichang He.
- (2024-02-13) 🎬📱 IEEE INFOCOM 2024 accepted our demo paper, FedKit: Enabling Cross-Platform Federated Learning for Android and iOS, by Sichang He, Beilong Tang, Boyan Zhang, Jiaqi Shao, Xiaomin Ouyang, Daniel Nata Nugraha, and Bing Luo. The demo video is on YouTube.
Last edited:
Steven Hé (Sīchàng)’s Notes
Last edited:
Android
run android studio emulator without android studio:
~/Library/Android/sdk/emulator/emulator -avd <DEVICE_NAME>
Last edited:
Automation Software
Youtube/other video downloader: yt-dlp or https://cobalt.tools
Last edited:
Chatbot Prompt
general requirements:
I am a computer scientist working on systems. Follow Clear Writing Principles, clearly distinguish fact/claim/belief/assumption/opinion/inference, be nuanced, concrete, direct; avoid any repetition, be complete but terse, use as few words as possible "but not simpler".
requirements for writing outlines:
keep the whole outline as one big nested unordered list of short items and never number the items, never write complete sentences and always only use simple keywords, never capitalize non-special words and always use lower case for ordinary words, and never use bold or other styling on texts.
Coder agent
requirement for coding & behavior (need .config cloned; fetches AGENTS.md):
You MUST **IMMEDIATELY** run: ~/.config/getagentsmd
ask agent to explain changes bit-by-bit instead of doing huge dump
Now, compile a list of things to go over w/ a new PLAN.md per AGENTS.md instructions
To avoid overwhelming the human, go over them 1 by 1, waiting for the human to ask questions or give feedback before going to the next one
Last edited:
ChatGPT
enhanced Read Aloud button for web UI: chatgpt_injection.js
Last edited:
Command-Line Utilities
wrap lines to a maximum width of 80 in FILE
fold -w 80 -s FILE
extract all images from PDF
pdfimages -all PDF_FILE "$(pwd)/"
convert PDF to HTML and preserve layout
docker run -t --rm -v $(pwd):/pdf -w /pdf pdf2htmlex/pdf2htmlex:0.18.8.rc2-master-20200820-alpine-3.12.0-x86_64 PDF_FILE
shared directory using group
# fill these in
export GROUP=
export SHARED_PATH=
export ANOTHER_USER=
# make group
sudo groupadd $GROUP
sudo usermod -aG $GROUP $USER
sudo usermod -aG $GROUP $ANOTHER_USER
# ownership and permissions
sudo chown -R $USER:$GROUP $SHARED_PATH
sudo chmod -R g+rwxs $SHARED_PATH
# check: should be 0002
umask
# if above not working: clear ACL
sudo find $SHARED_PATH -type d -exec setfacl -b -k {} +
sudo find $SHARED_PATH -type f -exec setfacl -b {} +
# final permission
sudo chmod -R g+rws $SHARED_PATH
flamegraph on running process
# fill this in
export PID=
# record perf data
sudo perf record -F 997 -g -p $PID -- sleep 30
# generate flamegraph
sudo env "PATH=$PATH" flamegraph --perfdata perf.data -o "profile$(date +%Y%m%d-%H%M%S).svg"
memory usage of process $PID and its children, recursively
ps_mem -p "$(bash -lc 'pid="$1"; f(){ printf "%s\n" "$1"; for c in $(cat "/proc/$1/task/$1/children" 2>/dev/null); do f "$c"; done; }; f "$pid" | sort -u | paste -sd, -' _ "$PID")"
Last edited:
Hammerspoon
add stuff: open config, type in LaTeX, save, reload config
bind function to hotkey
hs.hotkey.bind({"functionKey", …}, "key",…, function()
…
end)
functionKey: cmd alt ctrl
key: X \\ Left
the {} must stay even if it`s empty
show alert message
hs.alert.show("message")
generate system notification with title and content
hs.notify.new({title="title", informativeText="content"}):send()
define the current window as win
local win = hs.window.focusedWindow()
define win’s window frame as f
local f = win:frame()
position of f is (f.x, f.y) its width and height f.w, f.h
define the screen win at as screen
local screen = win:screen()
define screen’s screen frame as max
local max = screen:frame()
update the frame of win as f
win:setFrame(f)
hs.pathwatcher.new(.....):start()
reload config
hs.reload()
automatically reload config
function reloadConfig(files)
doReload = false
for _,file in pairs(files) do
if file:sub(-4) == ".lua" then
doReload = true
end
end
if doReload then
hs.reload()
end
end
myWatcher = hs.pathwatcher.new(os.getenv("HOME") .. "/.hammerspoon/", reloadConfig):start()
hs.alert.show("Config loaded")
get the home direction of the system
os.getenv("HOME")
connect string to path
..
call function whenever changes in direction
hs.pathwatcher.new("direction", function):start()
Last edited:
Browsers
Type clipboard into browser: type_clipboard.js
clear browser cache
browser DNS cache
Chrome:
chrome://net-internals/#dns
Firefox:
about:networking#dns
Last edited:
Computer Science
Last edited:
Discrete Mathematics for Computer Science
proof by induction
steps with example
- variable
- property
- base case
- induction hypothesis
- weak induction
assume is true - strong induction
assume is true
- weak induction
- induction step
induction hypothesis is true
Last edited:
Machine Learning
general problem format
given input , want output
- traditional approach
hand-craft the function - machine learning
build another function and use it to generate an approximation
machine learning is about building a function
- training data
- class of allowed function
use a predefined algorithm to compute with the goal:
simplification using feature vector
convert input into a 1d vector, making machine learning generally applicable
- feature vector
- training set
- hypothesis space
predefined algorithm produce so that
loss
estimation of the error of
zero-one loss
quadratic loss
empirical risk
average lost based on the training set
three types of machine learning problems
classification problem
label given data
- classifier (predictor) : the produced function
all possible training set
signature of machine learning function
- learn (or train) classifier from training set
- inference: apply classifier on any data
- testing: apply classifier on unseen data
classifier define a partition of
regression problem
given data, return a vector
clustering problem
group given data
supervised/ unsupervised machine learning
supervised learning: classification, regression
unsupervised learning: clustering
polynomial data fitting
not machine learning but similar
- number of monomial
interpolation in polynomial data fitting
achieve loss
- always interpolate
- overfitting
k-nearest neighbors predictor
remember the whole training set
return average of s corresponding to the closest s to
- useful for both classification and regression
- smaller results in worse overfitting
- good interpolation and poor extrapolation
Voronoi diagram
gradient descent
stochastic gradient descent (SGD)
group training set randomly into mini-batch, use gradient from each mini-batch to descent
- mini-step are in the right direction on average
- epoch: using all data once
step size
fixed
decreasing
momentum
line search
subgradient
logistic-regression classifier
- score-based
score function for linear boundary
signed distance to hyperplane
hyperplane
is perpendicular to
distance of from origin
signed distance of from
logistic function
then the score function is
- activation is signed distance scaled
softmax function
softmax function in activation
cross entropy loss for binary classification
cross entropy loss of assigning score to point whose true label is
- differentiable so we can do gradient descent
- base of does not matter
- resulting risk function is weakly convex
cross entropy loss for -class case
- true label
- prediction
- one hot encoding of
support vector machine (SVM)
binary support vector machine
separating hyperplane for binary support vector machine
decision rule
margin for with parameter
margin of training set
linearly separable if
hinge loss
reference margin
where
- separating hyperplane
empirical risk of binary support vector machine
- bigger smaller
soft linear support vector machine
subgradient of hinge function
support vector machine with kernel
representer theorem
loss function in the form
where increasing, ,
s.t.
proof: by writing
and proving by contradiction
support vector
sample that are misclassified or classified correctly with a margin not larger than
only support vector contribute to
kernel for support vector machine
where kernel
for some
is a kernel of
where
Mercer’s condition: s.t.
is finite,
Gaussian kernel
- radial basis function (RBF) SVM
Last edited:
Networking
encoding/decoding
- non-return to zero (NRZ)
- baseline wander
- synchronization problem
- non-return to zero inverted (NRZI): invert signal on 1
- Manchester encoding: xor clock and bit
- only 50% efficiency
- 4b/5b encoding
- 64b/66b
- 128b/130b
- modulation
framing
- sentinel-based framing
- BISYNC, PPP
- framing byte may appear in payload
- escape byte
- count-based framing: body length before body
- DDCMP
- bitwise sentinel framing
- HDLC
- bit stuffing: add extra 0 after 5 consecutive 1
- close-based framing
- fixed size frame
- need precise clock & synchronization phase
- high efficiency
error handling for framing
parity bit: whether number of 1 is odd
e.g. server RAM
- fast, easy in hardware
- miss many error
- high overhead
checksum: add up all sequence of certain length
e.g. internet checksum
- easy in software
- miss many error
cyclic redundancy check (CRC): divide message as a polynomial by generator polynomial
e.g. BISYNC, DDCMP, HDLC, ethernet, Wi-Fi
- easy in hardware with shift register
- good implementation ensure catching
- all single-bit error
- double bit error
- odd number of error
- burst of error shorter than bit
reliable transmission
- acknowledgement (ACK)
- timeout
stop-and-wait transmission
if ACK arrive before timeout, send next frame, else, send same frame again
- timeout hard to choose
- need 1 bit for frame identifier and in ACK
- waste bandwidth
continuous transmission: sliding window algorithm
sender
- send window size (SWS)
- last ACK received (LAR)
- last frame sent (LFS)
receiver
- receive window size (RWS)
- largest frame acceptable (LFA)
- last frame received (LFR)
go-back-
resend all frame since first lost frame
duplicate ACK
- sender: resend on duplicate ACK
- receiver: resend ACK for the last in-order frame when frame out of order
selective ACK
- sender: resend missing frame between last ACK and SACK
- receiver: send SACK for out-of-order frame
sliding window performance
utilize bandwidth
frame size ,
bandwidth ,
transmission time ,
round trip time ,
time to first ACK ,
number of packet
sliding window frame identifier count
- smaller is better since overhead
- ≥ SWS + RWS: prevent overlap of sequence
Ethernet
- carrier sense: idle/busy
- multiple access: share medium and broadcast
- collision detection
- collision avoidance: exponential back-off
Ethernet switch
- usually point-to-point
- high collision
Ethernet address
48 bit printed in hex separated per byte by colon
- unique
- manufacturer are allocated 3-byte OUI
- broadcast address FF:FF:FF:FF:FF:FF
Wi-Fi
- carrier sense
- multiple access
- collision avoidance
- request to send (RTS): inform future send
- clear to send (CTS): reserve medium
Wi-Fi distribution system
- access point connected to Ethernet
- automatic handover
- support client mobility
- new access point inform old one
network switch
interconnect link of the same type
- many port
- can connect to each other
forwarding
- require unique address
packet forwarding (frame-based forwarding)
- each frame contain enough information of destination (overhead)
- no reachability information
- independent forwarding
- congestion
- network switch keep forwarding table
- map destination to outgoing port
circuit-based forwarding
- need establish circuit (stateful)
- virtual circuit established on demand
- circuit establishment request use frame forwarding
- network switch keep virtual circuit table
- input port, input id, output port, output id
source-based routing
- origin provide forwarding information
- specify each output port in switch
- intermediate switch shift array
- address of each switch
- specify each output port in switch
- origin need global view
- frame header size undefined
usage
- establish virtual circuit
- go around failure
- hide origin of packet for attack
- mostly disabled
Ethernet switch device
multiple Ethernet interface
- build forwarding table
- broadcast if destination not on forwarding table
- remove old entry
spanning tree algorithm
- disable some link to eliminate loop
- switch with lowest ID is the root
- each switch start with self as root and broadcast root and distance
- alternative: TRILL, shortest path bridging
reason
- broadcast storm: broadcast cycle
drawback
- waste bandwidth
- where is diameter of network, slow to converge if large
repeater
- increase collision
virtual local area network (VLAN)
- additional field in frame header
- block invalid address
- scoped broadcast
interconnect network
- failed attempt to convert packet
internet protocol (IP)
- service model
- no guarantee
- most basic requirement on link layer, work everywhere
- packet header
IP fragmentation
what to do when packet size exceed frame size
- reassemble packet at destination
- in frame header
- use same identifier
- indicate following fragment with flags
- help reassemble with offset
- alternative: drop packet
- default in IPv6
- tell sender maximum valid size
IP address
- hierarchical
- network identifier
- node identifier
network information center (NIC)
IPv4
- class A: big network, first byte < 128, 1 byte reserved
- class B: smaller, first byte 129 ~ 191, 2 byte reserved
- class C: small, first byte ≥ 192, 3 byte reserved
- private address: 10.0.0.0/8, 172.16.0.0/12, 192.168.0.0/16
IPv6
- 16 byte
- written in hex, 2 byte between each colon, s omitted
subnet/CIDR
split address
- length
x.y.z.w/l- bit not masked determine subnet size
- network smaller than
/24usually not allowed in routing table
- netmask: same as length, s followed by s
- can split large subnet/ aggregate small subnet and advertise big network
- routing table can have overlapping entry, specific one used
network address translation (NAT)
enable computer in network share same globally routed public address
- engineering solution (hack)
- connection mapping: NAT table, use local port and remote IP and port to multiplex packet
- IP no longer unique across device
- port forwarding (UPNP) so incoming connection arrive
IP forwarding by router
- if interface is connected to destination network, translate to link-layer address (e.g. MAC) and deliver over local network
- else, find a router nearer to destination and do the above to it
address translation
- build link-layer address from IP
- does not work, e.g. IPv4 address (4 byte) to MAC (6 byte)
- privacy leak, e.g. IPv6 EUI-64 deprecated
- address resolution protocol (ARP)
- source broadcast ARP request
- matching node send ARP response with link-layer address to requester
- neighbor discovery protocol (NDP) for IPv6
default route
just deliver to this route if not in my routing table
routing table
- can configure manually but usually automatically by routing protocol
- distilled into forwarding table
- map destination to potentially many next port
- additional information than forwarding table
distance vector protocol
- used by routing information protocol (RIPv2)
- each router periodically broadcast all its best route to each neighbor
- count to infinity problem
- solution: limit maximum distance to 15
- split horizon optimization: do not send route back to where it is from
link-state protocol
- used by open shortest path first (OSPF)
- each router globally broadcast all its link at change
- reliable flooding
- costly
- send link-state packet (LSP)
- list of neighbor and metric (cost) of link
- sequence number: increasing
- guaranteed delivery via ACK
- time-to-live
- resend if no ACK
- receiver discard LSP with lower sequence number than seen
- receiver forward LSP
- receiver optimization: wait for other LSP for a while
- only needed when topology change
- metric
- usually fixed
- dynamic metric cause route oscillation and unpredictable performance
node configuration
- manual configuration: maintain IP allocation table
- autoconfiguration: DHCP
dynamic host configuration protocol (DHCP)
- client without IP address broadcast DHCP discover message
- DHCP server respond with configuration
- IP address
- DNS server
- default gateway
- lease duration
- DHCP server reserve IP prefix and give new device unallocated IP address
- DHCP relay allow multiple network to use 1 DHCP server
internet control message protocol (ICMP)
- report error, transmit metadata
- for troubleshoot
message type
0: echo reply
3: destination unreachable
- 0/1/2/3: network/host/protocol/port unreachable
- 4 fragmentation needed, for maximum transmission unit (MTU) discovery
8: echo request
interdomain routing
autonomous system (AS)
set of router following same policy, a.k.a domain
- distinct operator
- transit traffic: traffic across two AS
- stub AS: on the border, no transit trafic
- transit AS: opposite; promise to route you anywhere
- multihoming: network with multiple provider
- peering point: host network equipment
border gateway protocol (BGP)
- de facto standard
- policy-based routing
- oblivious to performance
- goal: find loop-free policy-compliant path
- no obligation to accept or propagate route
- can withdraw route
- focus on scalability
- only propagate most preferred route
- only need to run on router that connect two AS
- configure BGP session manually
- sometimes require contract and service agreement
- small/regional network pay larger network for transit
routing relationship and policy
- whatever make them money
- provider-client/client-provider: client pay for transit
- provider export all route to client
- client export only its route to provider
- peer-to-peer: exchange route for free
- peer export client route to peer
user datagram protocol (UDP)
multiplex packet for different application
- demultiplexing key (network port) in packet
- add packet to queue for socket. packet stay until application call
recv() - datagram: packet
network port
- 2 byte, local to each node
- which port
- in the spec
- portmap
- well-know port: SSH: 22, DNS: 53, HTTP: 80, HTTPS: 443
transport control protocol (TCP)
- demultiplexing
- guaranteed delivery
- dynamic retransmission timer
- in-order delivery
- dynamic sliding window
- bidirection transmission
- flow control
- accommodate for slowest endpoint
- congestion control
- coordinate across nodes
end-to-end principle
functionality should be provided at a layer only if it can be complete there
- guarantee on each link does not guarantee end-to-end
- TCP/IP push reliable delivery to transport layer
TCP header
- number each byte: SequenceNum
- ACK for each byte: Acknowledgment
- control sliding window: AdvertisedWindow
TCP connection establishment
- three-way handshake
- 4 messages to tear down
TCP flow control
- receiver set AdvertisedWindow to remaining buffer space
- sender set sliding window size according to AdvertisedWindow
- block
send()on buffer full
- block
- sender send 1 byte periodically to check AdvertisedWindow
- prevent chicken-egg problem: hang on 0 AdvertisedWindow
- 32 bit sequence number, sliding window can have up to byte
- prevent sequence number wrap around
- increase sequence number to 64 bit with option flag
- use all bandwidth
- AdvertisedWindow has 16 bit, maximum sliding window size is 64KiB
- option flag to multiply value in AdvertisedWindow
- Nagle’s algorithm: sender wait for ACK if cannot send full frame
- silly window syndrome: sender send tiny frame due to tiny AdvertisedWindow
- adaptive transmission: EstimatedRTT , MeasuredRTT , Timeout
Karn/Partridge algorithm with parameter :
Jacobson/Karels algorithm with DeviationRTT , parameter :
ignore retransmitted packet
hypertext transfer protocol (HTTP)
- universal resource locator (URL)
protocol:path- for HTTP
http[s]://[user[:pass]@]host/path[?query][#fragment]
HTTP message
- command/status line
- request: command
GET / HTTP/1.1 - response: status line
HTTP/1.1 200 OK
- request: command
- headers
- mandatory
Content-Length: 69
- mandatory
- empty line
\r\n - content
🤖 Agent-added L7 systems research (2026-06-07)
- 🤖 Insight: L7 protocols should expose machine-checkable transaction meaning for agents: preconditions, authority, side effects, idempotence, rollback, commit points, and postcondition evidence.
- 🤖 Why not merely engineering: this turns HTTP/API/browser workflows into a state-machine and contract problem, closer to session types and runtime verification than to “add an API wrapper”.
- 🤖 Transfer: OpenAPI/AsyncAPI contracts, typestate/session types, object capabilities, runtime monitors, API contract testing, and model checking.
- 🤖 Why now: API/hybrid web agents can outperform browser-only agents, runtime traffic API discovery is improving, and generated API integrations still make endpoint/argument/sequence errors.
- 🤖 Sketch: build a small L7 proxy/monitor that observes UI and API traffic, reconstructs transaction contracts, checks UI/API equivalence, and blocks duplicate commits or missing authority evidence.
- 🤖 Stronger scout variant: verify a narrow HTTP/fetch normalizer before the contract layer. The trusted core should canonicalize method, authority, body length, transfer coding, cookies, side-effect class, and commit id, then feed temporal monitors such as approve-before-submit and no-duplicate-commit.
- 🤖 Anchors: Beyond Browsing, Internal APIs, APISENSOR, OASBuilder, WAPIIBench, CommaSuite, ST-WebAgentBench, HDiff, HTTP Garden, HTTP Request Synchronization, L7FP.
remote procedure call (RPC)
client request & server respond (minimum 2 transmission)
- message oriented
- lower overhead than TCP
- stub
- allow function call
- protocol
- encode high-level data
- acknowledgement model
- send ACK
- response as ACK
- ping/working
- sync/async
popular example: REST/gRPC
real-time protocol (RTP)
- latency is vital
- monitor path property
- let application handle packet drop
stream control transmission protocol (SCTP)
- media delivery
- built-in media stream sync
- not depend on low-layer functionality
- common: IP + UDP
- example: WebRTC
simple mail transfer protocol (SMTP)
- user send mail to domain server
- domain server send to other domain server
- other domain server push to other user
- other user retrieve message using IMAP or POP3
- plain text: encode binary to string
- optional authentication: usually only between user/server
congestion control
- router-based vs endhost-based
- priori resource reservation vs transmission-time feedback
- window-based vs rate-based
- throughput vs latency: power = throughput / latency
traffic flow
- defined as (Source IP, Destination IP) or (Source IP, Source Port, Destination IP, Destination Port)
- aid router track soft state
resource allocation fairness
Jain’s fairness for flow with throughput
- 1 is most fair
TCP queue discipline
- FIFO queue with tail-drop
- prevalent
- priority queing
- absolute priority: higher priority always first
- reserve a fraction of bandwidth
- diffserv: buy priority
- fair queuing
- number of flow variable and large
- flow send packet of different size
- random early drop (RED): drop packet before queue fill
- no drop below minTreshold
- increasing drop probability between minTreshold and maxThreshold
classic TCP congestion control
- utilizing bandwidth & fairness
- introduced during “congestion collapse”
- implicit signal: drop packet
congestion window cwnd
limit number of unacknowledged byte
additive increase/ multiplicative decrease (AI/MD)
- packet dropped:
cwnd = max(cwnd / 2, packet_size) - not dropped:
cwnd += packet_size - mathematically proved to converge to same throughput
TCP slow start
- exponentially increase
cwndat start: each ACK:cwnd += 1 - when dropped
- slow start threshold
SSthresh = cwnd / 2 - each RTT:
cwnd = packet_size- actual: each ACK:
cwnd += packet_size / cwnd
- actual: each ACK:
- slow start threshold
- slow start while
cwnd < SSthresh, do AI/MD afterwards
TCP fast retransmit
- receiver send duplicated ACK for each packet out of order
- sender retransmit on multiple duplicated ACK
TCP cubic
- default in Linux since 2006
- hybrid slow start
- identify ACK slowdown and do AI/MD
- stay at expected maximum
cwnd, do AI after no drop for a while
domain name system (DNS)
- first try: “hosts” file
/etc/hosts - top-level domain by ICANN
- domain level hierarchy
- name resolution: ask name server from root up
- 13 root server each use different implementation
- distributed database
DNS entry
- canonical name
- nick name
- subdomain entry
attack
authenticity attack
- phishing: impersonation
- spoofing: hide source of attack
countermeasure: HTTPS
anonymity attack
- censorship
- persecution
- blackmail
countermeasure: VPN, TOR
availability attack
- DDoS
- ransom
firewall
- block incoming, usually allow outgoing
- software/hardware
- cheap, flexible vs expensive, opaque
- low vs high performance
- stateful/stateless
- have vs no memory
- cheap, easy vs expressive
firewall access policy
- accept, drop, reject
- default allow vs default deny
- IP, transport protocol, port, application data
demilitarized zone
- allow closely watched device to access more
intrusion detection system (IDS)
monitor software/hardware to detect malicious activity
- network intrusion detection system (NIDS)
- host intrusion detection system (HIDS)
virtual private network (VPN)
- tunneling protocol
- end-to-end encryption
usage
- remote access
- site-to-site
- bypass firewall/proxy
secure tunnel
- TLS, SSL
- IPsec
- authentication header (AH): after IP header
- encryption header (EH): after AH, before encrypted TCP header
- wrap all above as payload into another IP-AH-EH-encrypted payload
the onion router (Tor)
overlay network
- internet is overlay IP network over physical link
- VPN is overlay IP network over internet
example
- overlay multicast
peer-to-peer network
- unstructured peer-to-peer network: messy
- super node: big machines, store what file neighbor have
- coordination: maintain after super node leave
- tracker: broadcast what peer interested in same file
- peer exchange (PEX): list of known peer
BitTorrent
- dedicated tracker track peer and torrent
- direct connection between peer for data transfer
- select peer by speed (tic-for-tat)
- seeder: peer with file
- leecher: peer looking for file
- distributed hash table (DHT)
- no need for tracker
Last edited:
Data Science
Last edited:
Visualization
data type
item
discrete entry
attribute
measured property
attribute type
nominal (categorical)
with equality relationship
ordinal
with order
quantitative (numerical)
with algebra
- ratio: with meaningful
- interval
link
relationship between item
position
spatial location
grid
sampling strategy for continuous data
structured data
- table: item & attribute
- flat
- multi-dimensional
- network: item & attribute & link
- field: grid & attribute
- geometry: position
unstructured data
text, audio, graphics…
symbolic display
- parallel coordinate
- treemap
- field
- choropleth map
- star plot
graph
- framework
- scale
- content
- mark
- label
- title
- axis
mark
represent item, link
- point
- line
- area
channel
represent attribute
- position
- color
- hue
- saturation
- luminance
- shape
- glyph
- tilt
- size
- area
- texture
characteristic of channel
- selective
- associative
- quantitative
- order
- length
analysis framework
four level
- domain situation
- data/task abstraction
- visual encoding/interaction idiom
- algorithm
three question
- what
- why
- how
user task
- query
- retrieve value
- find extremum
- determine range
- search
- sort
- filter
- consume
- compute derived value
- characterize distribution
- find anomaly
- cluster
- correlate
graph theory
- independent set: no edge
- clique: all possible edge
- path: all edge can be consecutively traversed
- tree: no cycle
- network
- unconnected graph
- biconnected graph: no articulation point
- articulation point: break the graph if deleted
- bipartite graph: edge between only vertex for two set
centrality
quantity to measure vertex importance
degree of vertex
number of connected node
- in-degree/ out degree for directed graph
betweeness of vertex
sum of number of shortest path through the vertex divided by number of shortest path between each pair of vertex
closeness of vertex
sum of geodesic distance between the vertex and every other
geodesic distance between vertex
number of edge between them on the shortest path
eigenvector of vertex
adjacency matrix dot vector of degree
clustering coefficient
time
Last edited:
Documentation
Last edited:
Pandoc
How to use Pandoc to produce a research paper
create paper.pdf from paper.md and paper.bib
pandoc --pdf-engine latexmk -C --bibliography=paper.bib \
-M reference-section-title=Bibliography \
-V classoption=twocolumn -V papersize=a4paper -V fontsize=12pt \
-V geometry:margin=0.1in -V mainfont=Times \
-s paper.md -o paper.pdf
deal with CJK
pandoc --pdf-engine xelatex -C --bibliography=paper.bib \
-M reference-section-title=Bibliography \
-V classoption=twocolumn -V papersize=a4paper -V fontsize=12pt \
-V geometry:margin=0.1in -V mainfont=Times -V CJKmainfont='Songti SC' \
-s paper.md -o paper.pdf
using HTML as intermedia and wkhtmltopdf to create PDF
pandoc -s paper.md -o paper.pdf -t html5 \
-V margin-top=0 -V margin-bottom=0 -V margin-left=0 -V margin-right=0
word count
pandoc --lua-filter ~/.config/helper.lua/wc.lua input
convert docx to md:
cat INPUT_FILENAME.docx | pandoc --from docx --to markdown_strict \
--extract-media=. -o OUTPUT_FILENAME.md &&
sed -i -e 's/\\\_/_/g' \
-e 's/\\\\\[/[/g' \
-e 's/\\\\\]/]/g' \
-e 's/\\\\\*/*/g' \
-e 's/\\\\left\\\\\\\\ /\\\\left\\\\{/g' \
-e 's/>/>/g' \
-e 's/</</g' \
OUTPUT_FILENAME.md
Last edited:
Exams
Cheatsheet CSS
html body {
font-size: 12.5px;
}
* {
line-height: 1 !important;
margin-top: 0 !important;
margin-bottom: 0 !important;
padding-top: 0 !important;
padding-bottom: 0 !important;
}
h1,
h2,
h3,
h4,
h5,
h6 {
font-size: 1em !important;
}
main,
div,
section {
margin: 0 !important;
padding: 0 !important;
}
:not(span, code, pre) {
font-family: Arial Narrow !important;
}
main {
display: block !important;
}
a.anchor {
display: none;
}
section.markdown-body {
column-count: 3;
column-gap: 0;
}
html body ul,
html body ol {
padding-left: 1em;
}
Last edited:
TOEFL
reading
inference
- do not jump away from choice contradicting to article
summary
- do not choose choice that are not main point
speaking
do not add stuff not on notes
defend personal choice
- give example
campus-related passage + dialog
- summarize passage first
academic course passage + lecture
- directly go into lecture, mention passage in the way
academic course passage
- get example
- omit details, keep summary
Last edited:
Financial
Last edited:
Monero
p2pool mining setup using Monero GUI: add below to
Daemon startup flagsin node setting (from https://www.reddit.com/r/MoneroMining/comments/19dvhpg/unable_to_set_up_p2pool_node/)--zmq-pub tcp://127.0.0.1:18083- save space by pruning blockchain:
--prune-blockchain
- save space by pruning blockchain:
“couldn’t connect to daemon”: try directly running
/Applications/monero-wallet-gui.app/Contents/MacOS/monerod
Last edited:
Stocks
Last edited:
Robinhood Markets
options
- to see price history for an option, use legend or watch list
web UI JS injection
robinhood_options_injection.jsrobinhood_donut_injection.js
Last edited:
Tax
Online Taxes (OLT)
Notes by previous agent for future agents
UI. “Other Forms” in the sidebar is a dropdown, not a page. Collapsed income rows can show misleading subtotals; the dividend summary showed 5,000 treaty exclusion was implemented in OLT as negative Other Income; Form 8833 did not reduce income by itself.
For 1099, choose “income not effectively connected with a U.S. trade or business” and select 30% tax rate. Only for dividends, select 10% tax rate due to tax treaty w/ China.
Do not repeat what’s included in other tabs in Schedule NEC. On Schedule NEC, OLT enforces “Tax rate should be more than 30%” and prevents e-filing otherwise.
California workflow. Federal changes dirty the CA return and can leave it “Unfinished.” In this session, the agent had to re-enter the CA flow and click the section-completion button at the bottom of each section. OLT also generated Form 3853 for the F-1 coverage exemption.
What future agents should actually do
Never trust summary rows. Open the detail page before concluding an entry is missing, duplicated, or zero.
Treat OLT-generated article labels and mappings as untrusted until the PDF is reviewed. OLT can accept a package that is numerically consistent but textually inconsistent.
For California, assume federal changes will leak through. Re-open the CA return after federal edits and re-check sourcing, not just totals. The notes confirm CA had to be revisited after federal changes.
Never click links. They will redirect you to other pages and you will get logged out when you navigate back. Instead, open links in new tabs.
Last edited:
Government
Last edited:
United States
- apply for visa outside US
Enter US checklist
- passport w/ > 6 months validity
- visa & all related document
Last edited:
macOS
get ID of app:
osascript -e 'id of app "SomeApp"'
stop mds_store going crazy: disable Spotlight indexing
sudo mdutil -a -i off
# enable later
sudo mdutil -a -i on
add big folders to Spotlight privacy ignore list
flush DNS cache:
sudo dscacheutil -flushcache
sudo killall -HUP mDNSResponder
restart audio control, useful when audio is not working:
sudo killall coreaudiod
install xcode-select w/o using the garbage CLI that hangs: find the version for the corresponding Xcode version here https://developer.apple.com/download/all/?q=command%20line%20tools%20for%20Xcode, download the .dmg file, and install
MagSafe not working: reboot
no sleep w/ lid closed
sudo pmset -a disablesleep 1
connect to host … port 22: Can't assign requested address ⇒ reboot
Last edited:
Sucklessfy
allow apps from anywhere
sudo spctl --master-disable
DS.Store
remove all .DS_Store in subfolder
find . -name '.DS_Store' -type f -delete
key repeat
disable alternate character and enable key repeat for APP_NAME
defaults write APP_NAME ApplePressAndHoldEnabled -bool false
disable bloat daemon
cd /System/Library/LaunchDaemons
sudo launchctl unload com.apple.mobile.softwareupdated.plist
Last edited:
Mathematics
Last edited:
Abstract Algebra
integer
natural number
well-ordering axiom
s.t.
division algorithm
, s.t.
divisibility
, or divide , s.t.
- , or do not divide
greatest common divisor
, s.t.
or
Euclidean algorithm
let
apply division algorithm on until
Bézout’s identity
s.t.
- find : substitute from the last equation in Euclidean algorithm up
relatively prime
are relatively prime
prime number
, then is prime , the only divisor of are
- composite number: not prime
Euclid’s lemma
prime, or
- , then prime if , then or
- prime,
fundamental theorem of arithmetic
can be factored uniquely into product of primes
relation
relation on is a subset
or is related to
- or is not related to
partition of set
is a non-empty set, partition of
s.t.
- is equivalence relation
equivalence relation
- reflexive:
- symmetric:
- transitive:
equivalence class
equivalence class of representative
are either disjoint or identical
quotient set of by
is partition of
modular arithmetic
, then
or (mod ) or is congruent to modulo
congruence module
( mod ) or quotient set of by
- is equivalence relation on
congruence class
equivalence class of modulo
- there are distinct congruence classes
addition and multiplication in modular arithmetic
- addition and multiplication are well-defined
- additive inverse
- either has unique multiplicative inverse or it has not
unit
- is unit
zero divisor
, then
is prime
, is unit
or , or no zero divisor
group
ordered pair
- set
- binary operation
axiom group satisfy:
- is associative
- identity:
- inverse:
property
- is unique
- , has unique inverse
- and has unique solution, cancellation law work
- value of is independent of the bracketing
abelian group (commutative group)
is commutative
- under
- under
nonabelian group
- dihedral group of order ,
general linear group of degree over
special linear group of degree over
binary operation
associative binary operation
commutative binary operation
order of group
, or order of , is the number of distinct elements in
order of element in group
, or order of , is the smallest s.t.
or if DNE
- are distinct
Torsion group
is a Torsion group, then is finite
Torsion-free group:
Torsion subgroup of : for abelian group ,
is abelian Torsion group, then has largest order
dihedral group
rotation () and reflection () of n-gon
- order
- degree
permutation of set
permutation of : bijection
symmetric group on set
set
, the set of permutation of
, symmetric group on
- , symmetric group of degree
- nonabelian
array notation of permutation
is permutation on
cycle notation of permutation
cyclically permute and fix the rest
- -cycle (or cycle of length )
transposition
-cycle
- can be expressed as product of transposition
- not unique
- even permutation: length of such transposition is even
- odd permutation
disjoint cycle
no common number
- disjoint
- can be uniquely expressed as product of disjoint cycle of length at least 2
subgroup
, or is a subgroup of
- , or is a proper subgroup of
subgroup test
centralizer of group
- if
center of group
normalizer of group
where
for group and subset
- abelian
cyclic group
- generator
- cyclic group are abelian
fundamental theorem of cyclic group
homomorphism
are group
well-defined map is homomorphism
property
- monomorphism: injective
- epimorphism: surjective
- , or isomorphism: bijective
well-defined map
is well-defined
automorphism
isomorphism from to
- inner automorphism of ,
isomorphism
property
- abelian abelian
- have same number of elements of order
- prime
equivalence relation from isomorphism
is set of groups
is equivalence relation on
cyclic isomorphism
Cayley’s theorem
group , permutation , s.t.
kernel and image of homomorphism
is homomorphism
kernel of
- measure how much is not injective
- is injective
image of
- is injective
fiber of under
- is surjective
coset
,
left coset of in
- bijection between and
- or
right coset of in
- bijection between and
- or
is representative
- left and right coset are not necessarily equal
set of coset
set of left coset
set of right coset
- bijection between and
index of subgroup in group
index of in
is number of distinct left (right) coset
Lagrange’s theorem
for finite
normal subgroup
, or is normal in
normal subgroup test
- if , then
quotient subgroup
is the quotient group of by
under operation :
natural projection
natural projection of onto
homomorphism
- is epimorphism
isomorphism theorem
first isomorphism theorem
homomorphism
under
second isomorphism theorem (diamond theorem)
third isomorphism theorem
-
under
forth isomorphism theorem
, natural projection
bijection
property of
ring
a triple s.t.
is abelian group
is associative
distributive
commutative ring
ring with identity
- is unique
division ring
is ring with identity and
field
commutative division ring
zero divisor of ring
is zero divisor
- is not zero divisor, or
integral domain
commutative ring
is integral domain no zero divisor:
- or
- is finite is field
unit of ring
is ring with identity,
is unit
- group of units of ,
- zero divisor cannot be unit
subring
is subring of
- is a subgroup of
- is closed under multiplication
relationship between identity
- , unit in are unit in
subring test
is subring of
is finite subring of
center of ring
is ring with
- is subring with
- is division ring is field
characteristic of ring
if s.t.
then , else
- is integral domain is or prime
- finite
nilpotent of commutative ring with identity
commutative ring with
is nilpotent
- is or zero divisor
- is nilpotent
- is unit
- unit is unit
polynomial ring
is commutative ring with identity, is indeterminate
ring of polynomial in with coefficient in
- commutative
- identity
- is subring of
- is subring of is subring of
- is integral domain,
- is integral domain
polynomial in with coefficient in
- degree
matrix ring
is ring,
matrix ring of degree over
- has identity
- is not commutative
- has zero divisor
- set of scalar matrix in is a subring
- is subring of is subring of
scalar matrix
ring homomorphism
are ring
well-defined map is ring homomorphism
- monomorphism, epimorphism, isomorphism, kernel, image
- is subring
- is subring
- they have the same property (commutative, identity, inverse)
ideal of ring
subring is ideal of
- proper ideal: proper subset that is ideal
ideal test
subset of ring
is ideal
maximal ideal
ideal of is maximal ideal
- is ideal of , or
- easily seen in lattice
- not necessarily exist
- every proper ideal is contained in a maximal ideal
- is commutative, is field
prime ideal
ideal of is prime ideal
- or
- is commutative,
- is prime ideal is integral domain
- is integral domain is prime ideal
- every maximal ideal is prime ideal
quotient ring
is ideal of
is quotient ring of by
commutative commutative
natural projection
isomorphism theorem for ring
first isomorphism theorem for ring
is ring homomorphism
- is ideal of
second isomorphism theorem for ring
are subring of , is ideal
- is subring of
- is ideal of
- is ideal of
third isomorphism theorem for ring
are ideal of ,
- is ideal of
forth isomorphism theorem for ring
is ideal of , natural projection
bijection
are subring of ,
- is ideal of is ideal of
Last edited:
Arithmetics
sigma notation
- linear
common sum
trigonometric transformation
greatest integer smaller or equal than
binomial coefficient
triangle inequality
reverse triangle inequality
power when
Last edited:
Calculus
function
piecewise defined function
different formula for different part of domain
- step function
composite function
mathematical model
empirical model
model based entirely on data
limit
is defined on interval containing except possibly
limit exist iff limit from both side exist
limit law
linear: sum law, difference law, constant multiplication law
product law, power law
quotient law
derivative rule
rational
- limit calculation technique
divide numerator and denominator by highest power of
- limit calculation technique
direct substitution property
polynomial limit can be pulled out
limit comparison
near
squeeze theorem (sandwich theorem)
near ,
e.g.
continuity
is continuous at
- continuous from the left/ right
- continuous on an interval continuous at every point in interval
- continuous function after operation in limit law are still continuous
- function continuous in domain
- polynomial
- rational
- (inverse) trigonometric
- exponential
- logarithmic
discontinuity
- removable
redefining at single point remove discontinuity - unremovable
- infinite discontinuity
- jump discontinuity
intermediate value theorem
continuous on ,
derivative
derivative of at
derivative function
differential operator ,
differentiability
is differentiable at
exist
is differentiable on interval
is differentiable at every point in the interval
- differentiable at continuous at
second derivative
derivative rule
linear: constant multiplication, sum, difference rule
definition of
product rule
quotient rule
chain rule
implicit differentiation
differentiate both side of equation
derivative of (inverse) trigonometric function
derivative of logarithmic function
logarithmic differentiation
take the logarithm of both side of equation and differentiate
differential
hyperbolic function
- hyperbolic identity similar to trigonometric identity
- inverse hyperbolic function composed of logarithm
- derivative of hyperbolic function compose of hyperbolic functions
- derivative of inverse hyperbolic function have similar form like that of trigonometric function
extremum
extreme value theorem
continuous on closed interval
has absolute maximum and absolute minimum in the interval
Fermat’s theorem
has extremum at , exist
critical number
or DNE
closed interval method
find absolute extremum of continuous function on closed interval by checking the value of the critical number and endpoint
mean value theorem
continuous on , differentiable on
Rolle’s theorem
continuous on , differentiable on ,
derivative test
first derivative test
- increasing/ decreasing
- extremum
second derivative test
concave upward/ downward
graph of lie above/ below all its tangent
inflection point
indeterminate form
form that can transform to indeterminate form
L’Hospital’s rule
differentiable, near (excluding ), is in indeterminate form
antiderivative
- are also antiderivative of
integral
definite integral
integrable
integral sign
integrand
limit of integration
- lower limit
- upper limit
Riemann sum
midpoint rule
choose to be the midpoint
property of definite integral
- linear
fundamental theorem of calculus
continuous on
continuous on and differentiable on
is any antiderivative of
indefinite integral
mean
net change theorem
substitution rule
chain rule
trigonometric integral and trigonometric substitution
from
from
rational function integral
symmetric integral
volume from integral
from to , rotate and about -axis, volume:
from to , rotate and about -axis, volume:
arc length from integral
surface area from integral
from to , rotate about -axis, surface area:
average of function
mean value theorem for integral
continuous
integration by part
power rule
improper integral
integral with infinite interval
- continuous on
- exist
- opposite for
- convergent if limit exist
- divergent if limit DNE
- both side exist is their sum
discontinuous integral
- continuous on , discontinuous at
- exist
- opposite for when continuous on , discontinuous at
- convergent if limit exist
- divergent if limit DNE
- both side exist can connect them
improper integral comparison
, converge
converge
Last edited:
Differential Equation
an equation that contains an unknown function and one or more of its derivatives.
- order
highest derivative - solution
function that satisfy the equation - initial condition
- initial value problem
direction field
sketch lines as a grid with direction from derivative from the equation
Euler’s method
- step size
first order equation
separable equation
below old class note
ordinary differential equation ODE
- general form
order of differential equation
the order of the highest order derivative
solution
any function that satisfy the equation
general solution
collection of all solution
initial value problem
- initial condition
use the general solution and the initial condition
direction field
solving first-order differential equation
numerical approximation
- Euler’s method example code
f[x0_, y0_] := x0 y0
step[{x0_, y0_}] := {x0 + 0.01, y0 + 0.01 f[x0, y0]}
{x100, y100} = Nest[step, {1, 1}, 100]
separable equation
use separation of variable
- consider
- integrate both side
- explicit solution
- implicit solution relationship between variable
linear equation
where are continuous,
standard form
multiply both side to construct chain rule form where is the integration factor
substitution
Bernoulli equation
solution
substitution reduce the Bernoulli equation to linear equation
Ricatti equation
solution
- one solution
- substitution reduce the Ricatti equation to linear equation
existence and uniqueness theorem
is continuous on and satisfy Lipschitz condition
Lipschitz condition
metric space
- denote distance
- can be defined using
limit
sequence converge to limit in
- the limit is unique
Cauchy sequence
complete metric space
every Cauchy sequence converge to some point in
fixed point
point stand for function for operator
initial value problem integral form
for let operator : then is a fixed point for operator
Banach fixed point theorem
is complete metric space is a contraction has a unique fixed point in
- contraction is a contraction if
Picard iteration
sequence where with
one-dimensional (smooth) dynamical system
continuously differentiable function
- flow of dynamic system
autonomous equation
assume satisfy condition of existence and uniqueness theorem
time-shift immunity
if the solution of is then the solution of is
equilibrium
,
- asymptotically stable move towards from both side
- unstable move away from from both side
phase line
draw the sign graph of
linearization (approximate linear dynamic)
let
- blow up and unstable
- shrink down and asymptotically stable
- cannot linearize, need higher order
differential equation to dynamical system
where
dynamical system to differential equation
and convert to initial value problem with autonomous equation
discrete dynamical system
map
invertible
fixed point
not change when apply
stability
linearization
- dynamics
- unstable
- asymptotically stable
Poincaré map
time-periodic non-autonomous system
where
periodic time-shift immunity
if the solution of is then the solution of is
Poincaré map for the system
define function : , let be the solution to
periodic solution
fixed point of Poincaré map
stability
- asymptotically stable
- unstable
example code
P[h_,x0_] := NDSolveValue[
x'[t] == x[t](1-x[t]) - h x[t] Sin[t] && x[0] == x0,
x[2 Pi], {t, 0, 2 Pi}]
second-order linear equation
second-order homogeneous linear equation with constant coefficient
solution
a linear combination of two solution where is not constant (linearly independent)
auxiliary equation
under the hood: try
- two distinct real root
- double real root two solution
- two complex root
- alternatively where
- alternatively: real-valued solution
- complex-valued solution
second-order non-homogeneous linear equation
solution
- let then satisfy
- find one particular solution therefore
linear differential operator
given ,
linear operator
apply operator on function linear
find a particular solution
polynomial
use the degree of as the degree of the particular solution
exponential
where is polynomial same as the polynomial method but multiply the same exponential
- when is one root of auxiliary equation, multiply the polynomial solution by
- when is double root of auxiliary equation, multiply the polynomial solution by
trigonometric
same as polynomial but degree needs to be the maximum between and need two polynomial
- when is one root of auxiliary equation, multiply the polynomial solution by
combination of above case
split to that match above case
higher order differential equation
-th order where are continuous on
existence and uniqueness
above equation with has unique solution are continuous,
system in matrix form
Wronskian
determinant
linear dependency and Wronskian
linearly independent in
- linearly dependent function linearly dependent in
homogeneous linear equation with constant coefficient
auxiliary equation
complex root counting multiplicity
general solution
linear combination of solution time repeatedly if a solution has multiplicity or more
autonomous planar system of differential equation
with respect to
initial value problem
- autonomous can start wherever wanted, let
integral curve
parameterized curve of
velocity vector
phase plane
-plane
- phase space higher dimension
phase portrait
phase plane with several solution
equilibrium
- equilibrium solution
solution
- convert to differential equation with one variable
- conserved quantity / integral of motion
- reduce to non-autonomous first order equation
non-autonomous planar system
where are periodic in with period
periodic time-shift immunity
similar to periodic time-shift immunity in one dimension if is solution to then is solution to
Poincaré map for non-autonomous periodic dynamical system
- also known as stroboscopic map
example: mass on spring with external forcing
forced duffing equation
period
Poincaré map for forced duffing equation
P[b_,F_,γ_][{x0_, y0_}]:=
NDSolveValue[
x'[t]==y[t]&&y'[t]==-by[t]+x[t]-x[t]^3+F Sin[γ t]&&x[0]==x0&&y[0]==y0,
{x[2Pi/γ],y[2Pi/γ]},
{t,0,2Pi/γ}
]
chaos
sensitive dependence on initial condition
- two initial condition close to each other deviate exponentially fast
- the exact state of the system is fundamentally unpredictable though the system is deterministic
- chaotic attractor of the two initial condition look identical
Poincaré map for autonomous system
Henon-Heiles system
- conserved quantity
- hyperplane on consider an initial condition on corresponding to value for , when the solution reach again still conserve it is enough to know to know the rest define Poincaré map for
poincareMap[h_][{x0_,y0_}]:=Module[{stopTime},
NDSolveValue[
x1'[t]==y1[t]
&&y1'[t]==-x1[t]-2x1[t] x2[t]
&&x2'[t]==y2[t]
&&y2'[t]==-x1[t]^2-x2[t]+2[t]^2
&&x1[0]==0
&&y1[0]=Sqrt[2h-y0^2-x0^2+2/3 x0^3]
&&x2[0]=x0
&&y2[0]=y0
&&WhenEvent[x1[t]==0&&y1[t]>0,stopTime=t;"StopIntegration"],
{x2[stopTime],y2[stopTime]},
{t,0,Infinity}
]
]
linear system
planar linear system
where continuous
homogeneity
- homogeneous
- otherwise non-homogeneous
convert linear differential equation to linear system
linear differential equation define get a linear system
existence and uniqueness
If , are continuous functions in an interval and then for any initial vector there exists a unique solution of in that satisfies the initial condition .
linearity
linear combination of solution are also solution
linear dependency
linearly dependent vector
Wronskian
for solution
linear dependency and Wronskian
- solution are linearly dependent in
fundamental solution
collection of linearly independent solution
fundamental matrix
corresponding matrix
- invertible
- general solution for the linear system
- solution for the initial value problem with
- that is another fundamental matrix
- is a fundamental matrix
- let , then
linear system with constant coefficient
where is constant
find a solution
where satisfy
eigenvalue problem
is the solution to eigenvalue equation is non-zero eigenvector corresponding to is a root of characteristic polynomial
- is a complex eigenvalue is eigenvalue
- is eigenvector corresponding to is eigenvector corresponding to
linearly independent eigenvector and general solution
has linearly independent eigenvector corresponding to real eigenvalue general solution for is
real distinct eigenvalue
are real distinct eigenvalue of corresponding eigenvector are linearly independent a fundamental matrix is
complex eigenvalue
eigenvalue with eigenvector eigenvalue with eigenvector solution
matrix exponential
property
- , series converge
-
- trace of
diagonal matrix
diagonal matrix
matrix exponential and linear system
unique solution to the initial value problem with is
- derivative
exponential matrix as fundamental matrix
linear system has fundamental matrix
generalized eigenvector
a non-zero vector generalized eigenvector of associated with ,
- generalized eigenvector are also standard eigenvector
- is eigenvalue of with eigenvector
generalized eigenvector given characteristic polynomial
has characteristic polynomial linearly independent generalized eigenvector
compute
- find generalized eigenvector
- compute solution for
- fundamental matrix
planar linear system
where
characteristic polynomial
real distinct eigenvalue
- real eigenvalue
transformation
define by
- case 1a. (or ) all arrow point away from origin
- unstable node
- case 1b. (or ) all arrow point towards origin
- stable node
- case 1c. (or ) all arrow point towards origin on -axis, point away from origin on -axis
- saddle
- case 1d. (or ) all arrow point away from -axis parallel to -axis
- case 1e. (or ) all arrow point towards -axis parallel to -axis
complex conjugate eigenvalue
conjugate eigenvalue with corresponding eigenvector where
- complex eigenvalue
polar coordinate transformation
- case 2a. (or ) arrow rotate around origin moving away
- unstable spiral
- case 2b. (or ) arrow rotate around origin moving towards
- stable spiral
- case 2c. (or ) solution are closed curve with period
- center
rotation direction
- rotation direction on -plane
- , clockwise
- rotation direction on -plane
- same direction as on -plane
real repeated eigenvalue
generated eigenvalue of
- real eigenvalue
- case c1. (or both and are eigenvalue of ) all arrow point away from origin
- unstable node
- case c2. (or only is eigenvalue of ) all arrow point away from origin
- turn to the right with
- turn to the left with
- unstable
almost linear system
- almost linear system at
- is an equilibrium of
- is an almost linear system at the origin where
- almost linear system at the origin
- is an equilibrium of
- is continuous around
- are continuous near
- jacobian of
planar system
equilibrium
point
stability
- stable in English, given a bigger disk, one can always find a smaller disk, so that if you start from the smaller disk, you don’t go out of the bigger disk
- asymptotically stable stable and
- unstable not stable
open disk
linearization theorem (Hartman-Grobman theorem)
transform the dynamics of system to the dynamics of system where
- system is almost linear at
- is hyperbolic
- coordinate transformation near ,
hyperbolic linear system
hyperbolic matrix
all eigenvalue have non-zero real part
hyperbolic equilibrium
equilibrium of is hyperbolic matrix
energy method
mechanical system
potential
antiderivative of
energy function
conserved quantity
level set
fix to
- graph of is only defined where
- the two parts above and below -axis mirror each other
- intersection with -axis are where
- curve is vertical at intersection
potential plane
-plane
equilibrium
linearization
are continuous near system is almost linear at equilibrium
- Jacobian corresponding to
- , minimum at linear system is a center linearization does not hold use Taylor series quadratic term level curve are approximate ellipse
- , maximum at linear system is a saddle by linearization theorem, level curve also saddle
Lyapunov’s Method
isolated equilibrium
open disk of radius centered at does not contain other equilibrium
positive/ negative definite/ semidefinite function in
is open disk centered at is continuous in
- positive definite function in
- positive semidefinite function in
- negative definite function in
- negative semidefinite function in
- positive definite (/ semidefinite) function in negative definite (/ semidefinite) function in
directional derivative of along vector field (derivative of along the flow of )
planar system real-valued function
Lyapunov’s stability theorem
planar system is an isolated equilibrium
- positive definite function in an open disk centered at is negative definite in is asymptotically stable
- explanation increase going away from origin decrease along vector field going away from origin will always go towards origin along vector field
- positive definite function in an open disk centered at is negative semidefinite in is stable
Lyapunov function
a function that satisfy the condition of either part of Lyapunov’s stability theorem
Lyapunov’s instability theorem
planar system is an isolated equilibrium
- continuous function in an open disk centered at is positive definite in open disk centered at , is unstable
- explanation increase along vector field going away from origin is higher somewhere than the origin will go away from origin at some point
- alternatively, instability for restrict system mean instability for whole system
non-constant periodic solution
limit cycle
closed curve
- planar system
- is a non-constant -periodic solution
- non-constant mean the periodic solution is not a single point
- at least one other solution , or
- distance
- explanation this solution go to the closed curve as time roll back or go forward
example of limit cycle
- coordinate transformation
- is constant for the specific
- dynamic in radial direction have equilibrium when
- stability can be determined using phase line
- each equilibrium correspond to a circular limit cycle
limit cycle enclose equilibrium
enclose at least one equilibrium
- enclose equilibrium the equilibrium cannot be saddle
Bendixson’s negative criterion
- planar system
- simply connected domain
- have continuous partial derivative in
- does not change sign in
- system have no non-constant periodic orbit in
Poincaré-Bendixson Theorem
- planar system
- solution
- isolated region
- closed bounded
- solution stay in forever
- have continuous partial derivative in
- no equilibrium in
- is either periodic or approach a limit cycle in
bifurcation in one-dimensional system
is changing parameter
implicit function theorem
- smooth function
- , unique defined on ,
persistence of equilibrium
- is a smooth function
- , is an equilibrium when
- , unique smooth function defined on
- is equilibrium
fold bifurcation (saddle-node bifurcation)
smooth curve near in English: curve of equilibria (bifurcation diagram) near look like parabola
condition
- is a smooth function
- , is an equilibrium when
- equilibrium do not persist
- transversality condition
- system undergo fold bifurcation at
stability
check
- stability depend on sign of , regardless of
- equilibrium is stable equilibrium is unstable
- equilibrium is unstable equilibrium is stable
proof
- , , implicit function theorem smooth function near ,
- define
- Evaluate at .
- Then we take the derivative of the relation with respect to . We find Evaluating at and using that we find Since and we can solve for to find
bifurcation in planar system
is the parameter
persistence of equilibrium
equilibrium persist where is equilibrium when
fold bifurcation (saddle-node bifurcation)
- supercritical bifurcation stable limit cycle + unstable spiral
- subcritical bifurcation unstable limit cycle + stable spiral
Last edited:
Geometric Vector
vector
- displacement vector
- initial point
- terminal point
- zero vector
- unit vector
vector addition
- triangle law
- parallelogram law
scalar multiplication
component of vector
standard basis vector
dot product (scalar product, inner product)
angle between ,
perpendicular vector
direction angle
relation
conclusion
projection
cross product
- right hand rule determine direction of
magnitude of cross product
- equal to area of parallelogram by
parallel vector
property of cross product
- linear
triple product
scalar triple product
volume of parallelepiped by
coplanar
vector triple product
line
vector equation
parametric equation
where
symmetric equation
plane
vector equation
- normal vector
scalar equation
where
linear equation
plane-plane relation
- parallel plane
normal vector parallel - angle between plane
acute angle between normal vector
point-plane distance
cylinder
consist of parallel ruling through a plane curve
quadratic surface
second degree equation in three variable
standard form of quadratic surface
obtained after translation and rotation
or
- ellipsoid
all traces are ellipses - cone
horizontal traces are ellipses vertical traces in the planes and are hyperbolas if but are pairs of lines if . - elliptic paraboloid
horizontal traces are ellipses
vertical traces are parabolas
variable to the first power indicate axis of paraboloid - hyperboloid of one sheet
horizontal traces are ellipses
vertical traces are hyperbolas
axis of symmetry corresponds to variable with negative coefficient - hyperbolic paraboloid
horizontal traces are hyperbolas
vertical traces are parabolas - hyperboloid of two sheets
horizontal traces in are ellipses if or vertical traces are hyperbolas two minus signs indicate two sheets.
vector function (vector-valued function)
where are component function of
limit of vector function
take limit of its component function
continuity of vector function
continuous at
space curve
set of all point
- parametric equation
- parameter
- visualization
draw projection onto three plane
derivative of vector function
tangent vector
- all derivative rule apply except quotient rule
- dot product and cross product have separate rule
- inner part of chain rule must be scalar function
unit tangent vector
integral of vector function
integrate each component function
arc length
curvature
smooth parametrized curve
continuous and
(principal) unit normal vector
osculating plane
determined by
osculating circle (circle of curvature)
in osculating plane
tangent the curve
center towards
radius
binormal vector
normal plane
determined by
velocity vector
speed (magnitude of velocity vector)
acceleration vector
Last edited:
Multivariate Calculus
multivariate function
level curve (contour curve)/ level space
curve/ space with equation
- is constant
limit of multivariate function
approach as approach from any path within domain
- proof for the opposite using counterexample:
point out that the function approach different value from two different direction - the squeeze theorem hold
continuity of multivariate function
continuous
partial derivative
where
higher partial derivative
Clairaut’s theorem
defined on containing , continuous
tangent plane
line approximation
increment
differentiable function
differential
for differentiable function
implicit function
implicit function theorem
given
- differentiable by and
take derivative of both side
gradient
- product rule,
directional derivative
is unit vector
only when have the same direction
level surface
level surface
line curve on the surface of the level surface
is normal vector of tangent plane
- for level curve, is perpendicular to the curve
tangent plane of level surface
extrema
point
maximum or minimum or saddle point
-
- local minimum
- local maximum
- saddle point
extrema subject to constraint
constraint
- Lagrange multiplier
for additional constraint
two constraint’s intersection curve
surface area
Jacobian
line integral
piecewise-smooth curve
line integral of along with respect to
change orientation of
work
fundamental theorem of line integral
conservative vector field
vector field and s.t.
on open connected region,
on simply-closed region,
independence of path of line integral
with the same ends
closed path integral
is conservative
Green’s theorem
positively oriented, piecewise-smooth, simple closed,
is boundary of ,
have continuous partial derivative
- extension: multiple-connected region
nabla
Laplace operator
curl
- conservative on simply-connected region,
- irrotational
divergence
- incompressible
- source
- sink
-
- Laplace’s equation,
- for vector field,
- product rule,
Green’s theorem in vector form
for 2-dimension
outward unit normal vector
parametric surface
grid curve
normal vector for tangent plane at ,
smooth,
surface integral
area
for sphere,
oriented surface
normal vector field
flux
Stoke’s theorem
divergence theorem (Gauss’s theorem)
Last edited:
Parametric Equation
- parameter
- parametric curve
- initial point/ terminal point
derivative
arc length
polar coordinates
- pole
- polar axis
transformation between Cartesian coordinates and polar coordinates
polar curve
graph of polar equation
area
arc length in polar coordinates
Last edited:
Sequence and Series
sequence
list of number in definite order
sequence convergence
converge
otherwise, diverge
prove sequence convergence by function
sequence converge if corresponding function converge
- all limit law on function can be applied on sequence
sequence convergence preserve by chaining continuous function
convergence of
sequence monotonicity
increasing sequence
- the opposite is decreasing sequence
bounded sequence
bounded above
- the opposite is bounded below
- bounded sequence: both bounded above and below
monotonic sequence theorem
monotonic bounded sequence converge
series (infinite series)
or
th partial sum
series convergence
convergent
- sum of series
- the opposite is divergent
- linear combination of convergent series is convergent
example series
geometric series
power series
harmonic series
divergent
-series
divergence test
converge
diverge
integral test
continuous decreasing positive on
converge converge
remainder estimate for integral test
decreasing on
comparison test
converge,
converge
diverge,
diverge
limit comparison test
alternating series
alternating series test
alternating series
alternating series estimation theorem
satisfy alternating series test
absolute convergence
absolutely converge
- converge
conditional convergence
converge but not absolutely converge
conditionally converge
ratio test
root test
convergence test strategy
- special series
- -series
- geometric series
- similar form to special series
(limit) comparison test - divergence test
- alternating series test
- absolute convergence
- ratio test
- root test
- integral test
power series
power series centered at (power series about )
- coefficient
radius of convergence
converge when is within to
converge iff
converge for
converge if , diverge if
interval of convergence
⏎
find interval of convergence
- find radius of convergence using ratio test/ root test
- check endpoint
differentiation or integration of power series
equal to each term different or integrate
convergence and differentiability of power series
power series
has radius of convergence
function
differentiable on
derivative
- start from because the term at is
integral
function ’s power series expansion
Taylor series
Taylor series of at (/ about / centered at )
Maclaurin series
Taylor series at
-th degree Taylor polynomial
-th degree Taylor polynomial of at
remainder of Taylor series
for
equal sum of its Taylor series
Taylor’s inequality
for
for
used to prove equivalence between function and sum of Taylor series
a convergent sequence
Maclaurin series for
- let
Maclaurin series for trigonometric function
binomial series
Last edited:
Complex Analysis
complex number
in complex plane where
- real part,
- imaginary part,
complex plane
- real axis/ imaginary axis
- pure imaginary number,
binary operation of complex number
- addition,
- multiplication,
complex number short syntax
where
Argand diagram
diagram in given by
modulus, Euclidean length in Argand diagram
triangle inequality hold
complex conjugation
Euler’s formula
- , argument of
- , principal argument of
-
de Moivre’s formula
complex root
th root of
- distinct root
- principal root, when
standard topology
see context in Topology
open -neighborhood
region
nonempty connected set
- domain, open region
connectedness
is connected
polygonal line with finitely many segment between ,
bounded
circle of finite radius containing the set
complex infinity
or
Riemann sphere
intersection of the sphere with line through north poll and complex number
- north poll: , correspond to complex infinity
- Argand plane
limit
s.t.
- unique if exist
- independent of direction of approach
connection between complex limit and real limit
limit on the RHS exist
continuity
is continuous at
- exist
- exist
differentiation
differentiable at
exist
- depend on not differentiable
- differentiable differentiable
Cauchy-Riemann equations
exist at
Cauchy-Riemann equations in polar coordinate
differentiability from Cauchy-Riemann equations
defined around ,
at
- are continuous
- satisfy Cauchy-Riemann equations
exist
holomorphicity
holomorphic at
differentiable at each point in
- a.k.a. analytic/ regular
- and are harmonic function in
entire function
holomorphic at every finite point
constancy from holomorphicity
holomorphic, in
is constant
holomorphic in
is constant
parametric curve
complex-valued function
- simple does not intersect self injection
- simple closed (Jordan curve) simple except two end meet
- oriented
- positively oriented simple closed counterclockwise
- negatively oriented
parametric derivative
continuous
differentiable,
- velocity
- speed
- smooth differentiable and
has unit tangent vector in Argand diagram
parametric integral
- both real part and imaginary part commute
- antiderivative
- mean value theorem of integral fail
reparametrization
- curve length persist
parametric curve length
contour
piecewise smooth curve joined from finite smooth parametric curve
- continuous
- piecewise continuous
- vertex, point where not smooth
- length, orientation, simple closed like parametric curve
Jordan curve theorem
simple closed contour separate into
- a bounded interior
- an unbounded exterior
contour integral
contour ,
function piecewise continuous on
independent of parametrization
linearity
for contour
traversed in opposite direction
upper bound theorem for contour integral (ML theorem)
contour of length ,
piecewise continuous on ,
bounded by
proof using lemma
proof of lemma
lemma hold for . for
path independence of contour integral
continuous in
antiderivative s.t. in from to
closed,
Cauchy-Goursat theorem
on ,
simple closed contour in ,
holomorphic on and within
Cauchy’s theorem
same as Cauchy-Goursat theorem, except continuousproof using Green's theorem and Cauchy-Riemann equations
Cauchy-Goursat theorem on simply connected domain
on simply connected domain ,
closed contour in ,
holomorphic on
- simply connected domain: every simple closed contour enclose only point in
- multiply connected domain
- holomorphic function on simply connected domain has antiderivative
- entire function has antiderivative
adoption of Cauchy-Goursat theorem on multiply connected domain
on multiply connected domain ,
positively oriented contour , negatively oriented simple closed contour ,
inside of and disjoint from ,
holomorphic on and on the region between
path deformation principle
for the following case, deformation of contour integral persist its value
positively oriented contour ,
holomorphic between
Cauchy’s integral formula (Cauchy’s formula)
positively oriented contour,
holomorphic inside and on
inside
derivative
at , holomorphic exist and holomorphic
holomorphic have continuous partial derivative at all order
proof
show using upper bound theoremevaluating integral with Cauchy’s integral formula
on positively oriented contour , evaluate integral
find s.t. inside and
calculate
apply Cauchy’s integral formula
Morera’s theorem
continuous on
closed contour
holomorphic throughout
Liouville’s theorem
bounded entire function is constant
fundamental theorem of algebra
non-constant polynomial of degree has root
maximum modulus principle
non-constant holomorphic function on open
has no maximum on
- for on , reach maximum always on , never on interior
analyticity
analytic
Laurent series
annual domain , ,
any closed contour in ,
function holomorphic in
- punctured disk,
- unique
residue
Cauchy residue theorem
positively oriented contour ,
analytic on and within except on finite number of singularities
residue at infinity
all singularity are inside negatively oriented contour
Cauchy residue theorem can be rewritten as
by replacing with
singularity
is singularity
holomorphic in and not at
isolated singularity
analytic in deleted neighborhood
is isolated singularity
- has Laurent series about
- not branch point
- isolated singular at infinity s.t. analytic for
essential isolated singularity
s.t.
is essential isolated singularity
Casorati-Weierstrass theorem
s.t
pole
s.t.
pole of order at
simple pole
removable singularity
- removed by setting
residue at pole
only usable for
zero of order
analytic at ,
,
s.t.
- identically zero
- otherwise, the zero is isolated
zero and pole
analytic,
has zero of order at at ,
has pole of order at
has simple pole at ,
improper integral
Cauchy principal value
if RHS exist
- is even
improper integral for even rational function
real, continuous, even, irreducible rational function ,
has finitely many zero above the real axis
has pole above the real axis,
let be upper semicircle with missing side , then
if , then
Fourier integral
integrate instead
Jordan’s lemma
analytic above the imaginary axis outside ,
semicircle contour
proof by parametric integral and Jordan’s inequality
Jordan’s inequality
indented path
improper integral with singularity on real axis
circumvent each singularity on real axis by upper semicircle with
lemma for indented path
analytic on ,
clockwise upper semicircle ,
Laurent series of about contain no even negative power
proof by integrating Laurent series of parametric line integral term by term
lemma hold at simple pole
can prove
lemma for integral over branch point
circular segment of ,
continuous on
proof by definition of limit and upper bound theorem
trigonometric integral
define
Laplace transform
Laplace transform of
Bromwich formula
inverse Laplace transform
to the right of all sinularity of ,
line contour from to
meromorphic
is analytic except possibly for poles
theorem for meromorphic function
simple closed contour ,
non-zero and analytic on , meromorphic within
- , number of zero of within counted with order
- , number of pole of within counted with order
winding number
closed contour ,
on ,
difference in argument
winding number of with respect to
argument principle
Rouché’s theorem (dog on a leash theorem)
analytic on and within ,
on
have the same number of zero counted with order inside
- constrain location of polynomial root using Rouché’s theorem
- split polynomial where
on- root of are within
Brouwer’s fixed point theorem special version
,
analytic
s.t. (fixed point)
- when changing continuously without crossing , is topological invariant
Hopf’s theorem
closed curve ,
one can be continuously deformed into another without crossing point
vector field index theorem
vector field ,
simple closed contour enclose singularity of with index
vector field singularity
zero or pole of
vector field index
positively oriented contour enclose singularity of
vector field index is integer number of rotation of traversing
Möbius transformation
extended complex plane
only singularity is simple pole
inverse
derivative non-zero
- analytic except at pole
- non-constant mapping
is composition of linear transformation and inversion
they are a group
map circle to circle in
- line are circle of infinite radius through
need point to specify
circle in Argand diagram
cross-ratio
map distinct point to by
- can be canceled
conformal transformation
- analytic
- Möbius transformation
inverse function theorem
analytic at ,
analytic
derivative
conformal transformation preserve angle
conformal,
smooth at and intersect with acute angle
intersect at with acute angle
proof by taking through and and their equality
conformal transformation preserve harmonic
proof by constructing s.t.
- on smooth
harmonic function
with continuous second partial derivative satisfy Laplace’s equation
Dirichlet problem
hormonic ,
prescribed ,
find
- Neumann problem, prescribed
maximum principle
simply connected bounded by simple closed ,
harmonic on
attain extremum on boundary
proof by constructing s.t. and using maximum modulus principle
uniqueness of solution to Dirichlet problem
simply connected bounded by simple closed
is unique
proof by assuming both are solutions and arguing their difference is using maximum principle
Last edited:
Complex function
logarithm
where
- branch point
- multi-valued function
branch of logarithm
introduce s.t.
- branch cut , not continuous across
- principal branch , branch cut for principal value
- branch point , point common to all branch cut
derivative of logarithm
- holomorphic
exponential
- nonzero
- periodic,
- entire function
derivative of exponential
trigonometric function
entire
hyperbolic function
inverse trigonometric function
- are multi-valued
- holomorphic in branch
derivative of inverse trigonometric function
Contour integral of power function on circle
Last edited:
Complex Sequence and Series
sequence
sequence convergence
series
series convergence
converge to partial sum converge to
remainder
- converge
power series
see also power series
- converge to for
absolutely convergent in circle- circle of convergence, biggest such circle
- is continuous function inside circle of convergence
power series integration
can integrate term by term within circle of convergence
holomorphic
proof
let be any closed contour and set
by Morera’s theorem, is holomorphic
can differentiate term by term
Taylor’s theorem
holomorphic in
analytic,
when by the upper bound theorem, for , as proof using Cauchy's integral formula
uniqueness of Taylor series
in , power series converge to
it is the Taylor series of about proof using power series integration and Cauchy's integral formula
Last edited:
Linear Algebra
determinant
Last edited:
Numerical Analysis
gradient descent
line search
gradient descent momentum
stochastic gradient descent (SGD)
integration
followed from Riemann sum
, partition evenly into subinterval
first-order method
second-order method
midpoint rule
Last edited:
Proof
proof by induction
- variable
- property
- base case
- induction hypothesis
- induction step
direct proof
contrapositive proof
implies is equivalent to implies
proof by contradiction
assume is true, get a contradiction
circular proof
to prove , need only prove
Last edited:
Real Analysis
set
complement of set
cardinality
one-to-one correspondence
finite set
empty or has cardinality of for some
infinite set
countable set
has cardinality of
- countable, infinite and countable
- countable countable
real number
- real number are complete
every Cauchy sequence in converge to - real number satisfy the Archimedian property
Archimedian property
function
function from to is subset
is the value of at :
or
- domain
- range
- onto:
- one-to-one:
- one-to-one correspondence: onto and one-to-one
inverse function
for one-to-one function , inverse function of
sequence
or
see also Sequence and Series
sequence convergence
or converge to limit
integer , so that ,
sequence diverge to infinity
, so that ,
bounded sequence
is bounded iff
so that
- bounded monotone sequence converge
limit theorem
- bounded sequence
- squeeze theorem
- limit are linear
- multiplication and division can be extracted
Cauchy sequence
so that, if , then
- convergent sequence are Cauchy sequence
- axiom of completeness
Cauchy sequence in converge to finite number in
subsequence
subsequence of ,
limit point
limit point of
- is limit point subsequence
Bolzano-Weierstrass Theorem
bounded s.t.
- proof: successively shrink interval by half and keep the half with infinite element
- s.t.
continuity
is continuous at
is continuous at
continuous function on closed interval
is continuous on is bounded:
continuous on
and
and is uniformly continuous on
supremum
infimum
intermediate value theorem
continuous on , , is between
uniform continuity
is uniformly continuous
Lipschitz continuity
is Lipschitz continuous on
integral
partition
partition of is any finite collection of point
where
upper sum/ lower sum
for subinterval of partition
lower sum
upper sum
for any partition
for partition that contain all point of and additional point
Riemann integrability
on is Riemann integrable
partition s.t.
is Riemann integrable
continuous on Riemann integrable
Riemann integral
Riemann integrable on
Riemann integral
Riemann sum
where
continuous on , is sequence of partition s.t. maximum length of subinterval as , is any Riemann sum corresponding to
differentiation
continuously differentiable
differentiable on and continuous on , or
- continuous on is denoted as
Rolle’s theorem
differentiable on ,
mean value theorem
differentiable on ,
Taylor’s theorem
, exist on ,
where is define in Sequence and Series
proof
fix , let s.t.
apply Rolle’s theorem time to show between s.t.
sequence of function
, defined on
sequence of function pointwise convergence
converge pointwise to limiting function
sequence of function uniform convergence
converge uniformly to limiting function
sequence of function , , , converge ,
, . , . on ,
,
supremum norm
bounded on
supremum norm or sup norm of
- sup norm is a metric
function converge in the sup norm
on converge in the sup norm to
- converge to uniformly on
Cauchy sequence in the sup norm
on is Cauchy sequence in the sup norm
- converge in the sup norm
- is complete in the sup norm
integral equation
, ,
has unique continuous solution
proof of existence
define any continuous and
show that by induction
show that
show by iteration that is Cauchy in sup norm
proof of uniqueness by contradiction: subtract equation of two solution function
calculus of variation
functional
function with domain containing function
Euler equation
is twice continuously differentiable functional of three variables
is extremal for satisfy Euler equation
metric space
metric
sequence of point in metric space converge
,
converge to
also denoted as
equivalent metric
metric on are equivalent
- in in
Cauchy sequence of point in metric space
complete metric space
contraction
is contraction
fixed point of contraction
stable
contraction mapping principle
complete
- has unique fixed point
series of function
converge s.t.
converge
linearity
limit superior and limit inferior
,
limit superior
-
- s.t.
- s.t.
limit inferior
-
- s.t.
- s.t.
partial sum
partial sum of series
- series convergence is the same as its sequence of partial sum
series convergence test
series absolute convergence
converge absolutely converge
- otherwise, conditionally converge or diverge
- is bijection (rearrangement)
- absolutely converge absolutely converge
comparison test
- converge converge
- diverge diverge
root test
- converge absolutely
- diverge
ratio test
- converge absolutely
- diverge
series of function converge
- converge to converge to
Weierstrass M-test
- s.t.
- converge
converge uniformly
integral of uniformly convergent series of function
converge uniformly to on
,
derivative of uniformly convergent series of function
- converge uniformly to on
- converge uniformly on
power series
radius of convergence of
convergence of power series
- converge on
- diverge outside
- converge uniformly on
property of in power series
- is Taylor series of about
Last edited:
Shorthand
DNE = doesn’t exist
near = , on
NOS = need only show
thm = theorem
WLOG = without loss of generality
WTS = want to show
WHP = with high probability
Last edited:
Topology
set
set with all its element open
- point,
open
- closed, where
- are both open and closed
topological space
set and choice of set of open subset
- chaotic topology,
- discrete topology,
neighborhood
neighborhood of :
- deleted neighborhood,
closure
closure of ,
interior point
point
s.t.
- interior of , set of all interior point of
exterior point
point
s.t.
- exterior of , set of all exterior point of
boundary point
neither interior nor exterior of
- , boundary of , set of all boundary point of
limit point
limit point of
sequence convergence
s.t.
- in chaotic topology, every sequence converge to every point
continuity
topological space
map continuous
Brouwer’s fixed point theorem
continuous
at least one fixed point
assign each fixed point index
Lefschetz number is topological invariant
Last edited:
Package Manager
Last edited:
Cargo
install binary
cargo install <binary name>
update all binaries installed
cargo install-update --all
Last edited:
Homebrew
search package
brew search <package>
install package
brew install <package>
update
brew update --force \
&& brew upgrade --greedy \
&& brew cleanup \
&& brew autoremove
list installed packages
brew list
show dependency tree of package
brew deps -t <package>
export package and cask name to reproduce environment
brew leaves > brew_leaves.txt
brew list --cask > brew_list_cask.txt
display information about package
brew info <package>
clean up junk
brew cleanup && brew autoremove
no stop-the-world auto update
export HOMEBREW_NO_AUTO_UPDATE=1
Last edited:
Gem
install a_gem
gem instal a_gem
install all gem in project
bundle
remove outdated gems
gem cleanup
Last edited:
Nix
find package: search online
install prebuilt package
nix-env -ibA <PACKAGE>
install package
nix-env -iA <PACKAGE>
update nix and all nix package (use sudo -i instead if nix-channel not found)
sudo nix-channel --update && nix-env -ibA nixpkgs.nix && nix-env -ub
check and fix nix store
sudo nix-store --verify
Last edited:
NPM
help node find global module (change the path if necessary)
module.paths.push("/opt/homebrew/lib/node_modules");
Last edited:
Pacman
get the fastest mirror (France for example)
curl -s "https://archlinux.org/mirrorlist/?country=FR&protocol=https&use_mirror_status=on" | sed -e 's/^#Server/Server/' -e '/^#/d' | rankmirrors -n 5 -
set mirror
sudo vim /etc/pacman.d/mirrorlist
resolve untrusted packages when updating
sudo pacman -Sy archlinux-keyring
Last edited:
pip
always use python3 -m pip instead of pip
- make sure using the same pip as python
- use
python -m pipon Windows
upgrade pip3
python3 -m pip install --upgrade pip
update all
python3 -m pip list --outdated --format=json \
| python3 -c "import json, sys
print('\n'.join([x['name'] for x in json.load(sys.stdin)]))" \
| grep -v '^\-e' \
| cut -d = -f 1 \
| xargs -n1 python3 -m pip install -U
check version
python3 -m pip -V
remove cache
python3 -m pip cache purge
Last edited:
TeXLive Manager (tlmgr)
The horrible package manager.
find which package to download for a missing file
tlmgr search --file <name_of_missing_file> --global
install package
tlmgr install <package_name>
Last edited:
Rye
force version of dependency incompatible w/ some other dependency (https://github.com/astral-sh/rye/issues/505)
[tool.uv]
override-dependencies = ["PACKAGE_NAME>=VERSION"]
Last edited:
Programming
Last edited:
C
type
primitive type
charintfloatdoublelong
and the unsigned variant
array
d0 × d1 × … × dn int array
int arrayName[d0][d1] /*…*/[dn] = {
{ /*…*/ },
/*…*/
};
- can declare without initializing
- if value given, can omit
d0 - can just supply one array and it will split
- array is pointer to the first element
string
char array, null terminated
immutable string
char* name = "text";
mutable string
char name[] = "text";
in this case, same as
char name[5] = "text";
string method
strlen(str)length ofstrstrncmp(str0,str1,n)comparestr0andstr1to at mostnstrncat(dest, src, n)concatenatesrctodestfor at mostn
function
declare before use
empty declaration is fine
static
static variable
near global variable (file only)
- won’t initialize twice if in a function
static function
file scope function
pointer
number representing memory address
explicitly create pointer
int* ptr = &8;
implicitly convert to pointer
char* ptr = "bla";
struct
declare struct
struct keyword
struct point {
int x;
int y;
};
struct point p;
p.x = 0;
p.y = 0;
typedef keyword
typedef struct {
int x;
int y;
} point;
point p;
recursive definition
typedef struct node_t {
int val;
struct node_t* next;
} node;
access struct’s field
.->for pointer struct
nested struct
typedef struct {
struct {
int x;
int y;
};
int z;
} nested;
- access inner struct’s field directly from the outer struct
union
struct with overlapped field
typedef union {
int theInt;
char chars[4];
} intChar;
- field in union share the same bytes
- read field of union like read field of struct
- assign to union itself assign the the first field
union for struct index
union Coins {
struct {
int quarter;
int dime;
int nickel;
int penny;
};
int coins[4];
};
dynamic allocation
person* p = malloc(sizeof(person));
malloc return void pointer, implicitly converted
explicitly typecasting has the same effect
person* p = (person*) malloc(sizeof(person));
clean the dynamic allocation
free(person);
dynamically allocated array
int* arr = malloc(n * sizeof(int));
- do not need to know size at compile time
- can index
arr[i]like ordinary array
pointer arithmetics
- incrementing pointer skip an amount of byte according to the pointer type
- e.g.
int*skip by 4 byte
- e.g.
pointer function
int real_function(int n) {
return n * n;
}
int (*function_name)(int arg) = &real_function;
- used as argument in another function
call pointer function
(function_name)(5);
array of pointer function
void f1();
void f2();
void (*function_name[2])() = {&f1, &f2};
Last edited:
clang
usually what you do
clang program.c -c -o program.o
clang program.o -o program
compile and detect memory leak
clang program.c \
-fsanitize=address,leak,undefined \
program
Last edited:
Elixir
print Charlist as list of integer
[1, 2, 3] |> inspect(charlists: :as_lists) |> IO.puts()
control sequence introducer \e instead of \033[
function
anonymous function
f = fn arg0, arg1, … -> result end
need a dot to call
f.(a0, a1, …)
capture syntax
&fn1/n_args
&(&1…)
&1for the first argument,&2for the second, etc.
Last edited:
Git
Checkout
git clone without downloading
git clone <repo> --no-checkout
check what are the branches
git fetch && git branch
force sync from origin
git reset --hard origin/main
pull main without checking out main
git fetch origin main:main
fetch only 1 commit
git fetch --depth 1 git@github.com:username/repo.git FULL_SHA_FOR_COMMIT
Config
sane config
git config --global pull.rebase true # rebase on pull conflict
git config --global rebase.autoStash true # stash before rebase
git config --global submodule.recurse true # always recur submodule
Commit
commit with message
git commit -m "<msg>"
stage all changes and commit
git commit -am "<msg>"
revert to the last commit
git reset HEAD~
or
git revert …
change the last commit
--amend
create orphan branch
git switch --orphan <branch>
add coauthor to commit
git commit -m "Commit message.
Co-authored-by: Name <email@example.com>"
Bookkeeping
delete all history of a certain file (deprecated)
FILTER_BRANCH_SQUELCH_WARNING=1 git filter-branch --index-filter \
'git rm -rf --cached --ignore-unmatch <path_to_file>' HEAD
delete all history of a certain file using git-filter-repo
git filter-repo --invert-paths --path '<path_to_file>' --use-base-name
ignore all symlink
find * -type l -not -exec grep -q "^{}$" .gitignore \; -print >> .gitignore
git commit sizes
bash -c "git rev-list --objects --all |
git cat-file --batch-check='%(objecttype) %(objectname) %(objectsize) %(rest)' |
sed -n 's/^blob //p' |
sort --numeric-sort --key=2 |
cut -c 1-12,41- |
$(command -v gnumfmt || echo numfmt) --field=2 --to=iec-i --suffix=B --padding=7 --round=nearest"
verify no change since commit
git diff --exit-code HEAD
remove uncommitted files
git clean -f
remove ignored files
# see what will be removed
git clean -n
# do it
git clean -fX
go back and clean up history
git rebase -i COMMIT_BEFORE_CHANGES
squash merge
git merge --squash <branch>
Multiple repo
add repo as submodule
git submodule add <repo>
clone all submodules
git submodule update --init --recursive
clone w/ submodule all w/ depth 1
git clone --depth 1 --recurse-submodules --shallow-submodules $URL
clone all submodules w/ depth 1
git submodule update --init --recursive --depth 1
after changing .gitmodule
git submodule sync --recursive
pull every repo under the current folder
fd .git -H -t d -x git --git-dir={} pull
solve fatal: src refspec '…' must name a ref fatal: process for submodule '…' failed:
git push --no-recurse-submodules
fetch and status every repo under the current folder
fd .git -H -t d -x git --git-dir={} fetch \; -x git --git-dir={} --work-tree {}/.. status
rebase upstream while submodule has local changes (fatal: cannot rebase with locally recorded submodule modifications)
git pull --rebase --autostash --no-recurse-submodules
Multiple origin
push all branch to all remote
git remote | xargs -L1 git push --all
push main to all remote
git remote | xargs -L1 -I R git push R main
Last edited:
Gleam
control sequence introducer \u{1b}[ instead of \033[
Last edited:
Java
built-in data type
primitive type
bool
1B
&&||!assert (a && b) == (!(!a || !b))
number
two’s complement, e.g.
Integer.MAX_VALUE + 1 = Integer.MIN_VALUE = -Integer.MIN_VALUE
short
2B
int
4B
float
4B
long
8B
double
8B
- special value
InfinityNaN
numerical operator
- cast to precise type when different type
+ - */integer division if both integer else float division%remainder
Math library
operation: abs, max, sin, asin, exp, log, pow, round, random, sqrt variable: PI, E
char
2B
- use ASCII
- auto cast from and to int
convert to String
String.valueOf(charArray)
cast
(target_type) var_to_convert
wrapper type
built-in reference type corresponding to primitive type
- object
- autoboxing and unboxing convert from and to primitive type and wrapper type automatically in assignment and function call
String
concatenation
+
string1.append(string2)
StringBuilderbetter way to concatenate string
array
{literal1,…}//an array
arr1.length//length attribute of array
Arrays.sort(arr1)//sort array arr1
- copy: copy the length and every single value
- assign: refer to the same array (aliasing)
- array overhead 3B = object reference 1B + object overhead 2B
declaration
type1[] arr1; //declare array name of type type1
initialization
new double[length] //an array of length length, all 0.0s
- default value for number is 0
- default value for object is
null
access & mutate
arr1[i] = literal; //refer to array arr1 by index i
two-dimensional array
an array of array
basic syntax
conditioning
if
if (bool1) { execution1; }
else if (bool2) { execution2; }
// …
else { execution0; }
switch
switch (var1) {
case value1: execution1;
break;
// …
}
- work with primitive type and wrapper
- work with enum
- work with String
loop
while
while (bool1) { execution; }
do while
do { execution; } while (boolean);
at least do once
for
for (initialization_statement1, …; bool1; increment_statement1, …) { execution; }
access modifier
default
access from same package
public
public …;
access everywhere
protected
protected …;
access from same package or subclass
private
private …;
access from same class
mutability modifier
final … var1 …;
make the variable immutable
static vs instance
… static …;
make variable or function static, as opposed to instance
- static mean belong to type itself
- instance mean belong to an instance of class
comment
// inline
/* block */
docstring
/**
* doc
*/
support HTML
assertion
assert bool1 : "error message";
throw the error if bool1 == false
input
command-line argument
args[i]
- start from
0
stdin
scanner:
import java.util.Scanner; //import scanner
Scanner sc= new Scanner(System.in); //define a scanner
Type1 var1 = sc.nextType1();//let variable be input
output
System.out.println(output)//print output \n
System.out.print(output)//print output
formatted print
System.out.printf(“string1%w1.p1c1… string2”,output1,…)
//print string1 output1… string2
// with field width w, precision .p, and conversion code c
- negative
wcounts from the right - for c
d: decimalf: floatinge: scientifics: stringb: boolean
- must have
%andc - standard string format in Java
pretty print object
Gson gson = new GsonBuilder().setPrettyPrinting().serializeNulls().create();
gson.toJson(object0);
class
class as function library
public class ProgramName {
public static void main(String[] args) {
// main function
}
}
global variable
public class ProgramName {
static type1 var1;
}
class as abstract data type
public class ClassName {
type1 ins1; // instance variable …
/*
* constructor
*/
public ClassName(arg…) {
// …
ins1 = …; // need to initialize all instance variable …
}
public type2 method1(arg…) {
// …
} // instance method …
public static void main(String[] args) {
// test
}
}
- use short name for instance variables for convenience
- use full name for parameter variables as the client can see them
constructor
same method name as class
use constructor
ClassName var1 = new ClassName(arg…);
access instance variable
var1.ins1
use instance method
var1.method1(arg…);
common instance method
equals method
public boolean equals(Object x)
{
if (x == null) return false;
if (this.getClass() != x.getClass()) return false;
return (this.ins1 == x.ins1) && …;
}
hashCode method
public int hashCode() {
return Objects.hash(ins1,…);
}
interface
public interface InterfaceName {
type1 var1; // instance variable …
public abstract type1 method1(arg…); // empty abstract method …
}
- interface enables a method name to call different methods according to the object
- functional interface: single method
abstract method
include nothing
implement
public class ClassName implements InterfaceName{
// …
}
- the class must have methods corresponding to all abstract methods in the interface
implement Iterator
import java.util.Iterator;
class ClassName implements Iterator<K> {
// …
// must-need method for Iterator
public boolean hasNext() {
// …
}
public Item next() {
// …
}
public void remove() {
// …
}
}
subclass
public class SubClassName extends ClassName {
// …
}
have everything super class have
generic programming
generic class
public class GenericClass<typeParameter> {
// …
}
a class that can be fed with different data type
use constructor
GenericClass<type1> var1 = new GenericClass<type1>(var0);
functional programming
lambda expression
(arg…) -> stuffToReturn;
package
import
static import
import static package1
imports the method so that its prefix can be omitted don’t use
timing
System.currentTimeMillis()
System.nanoTime()
Last edited:
JavaScript
data type
- no char
- undefined
- nullish coalescing operator
??
give default value if the expression before isnullorundefined - optional chaining
?
skip method chain and returnundefinedif expression before isundefined
- nullish coalescing operator
assignment
- fallback
||execute if the former one fail
array […]
can contain multiple types of data
access data array1[index1]
.length.push().pop()work like stack.unshift().shift()work like queue.splice(index,number,…)removenumberitems fromindexand insert….reduce(fun1)take variable into function and put result back- spread (deep copy)
[...arr1] - rest
[attr1, ...arr2] = arr1
loop array
- the C way
for… ofloop.forEach(callback)
string
is just immutable array
formatted string
`blah ${var1}…`
.toUpperCase().toLowerCase().trim().slice(start,end)a.slice(1)return substring excludinga[0]a.slice(-1)returna[a.length - 1]
function
function fun1(var1,…) {
// …
}
anonymous function
(var1,…) => {
// …
}
minimum var1 => expression1
variadic function
argumentsmagic variable: array-like object- rest parameter
(arg0, …, ...args): array
comparison
- strong comparison
===!==does not convert type - weak comparison
==!=convert type
object
{
attr1: lit1,
// …
}
rather dictionary
deleteattribute.hasOwnProperty(attr)check if hasattr- rest
{attr1, ...obj2} = obj1 - spread
obj2 = {...obj1, attr1: val1}
quick initialization
{
attr1,
attr2,
// …
}
is equivalent to
{
attr1: attr1,
attr2: attr2,
// …
}
access attribute
.attr1object1[attr1]
immutable object Object.freeze(…)
method
defined inside of the object block
class class Class1{…}
constructor constructor(…){…}
use constructor new
getter/setter get var1() {…}/set var1(…) {…}
Last edited:
MathJax
enable $…$ inline math
<script type="text/x-mathjax-config">
MathJax.Hub.Config({ tex2jax: {inlineMath: [["$","$"]]} })
</script>
Last edited:
Julia
use latex symbol
type \… and tab
built-in
constant
π or pi = 3.1415926535897... Inf and NaN im
math function
sqrt()
variable
check type
typeof()
numerical type
extreme representable value
typemin(Type1) / typemax(Type1)
convert to bits bitstring()
avoid overflow using big()
create BigInt or BigFloat or use big"…" if the number if too big for Int or Float
machine epsilon eps(Type1)
implicit numeric multiplication
2x^2x is equivalent to 2 * x^(2 * x)
arithmetic operation
÷integer division^power.make the next operator element-wise
e.g..+element-wise add
numeric comparison
Julia support real Unicode operator
isequal()compare objectisfinite()isinf()isnan()
Julia support arbitrary comparison chaining
conversion Type1(…)
pattern matching
_ can be assigned value
string
Use double or triple quote for string literal
index take raw bytes
index start at 1
can use begin and end for index
r"…"regex stringb"…"byte stringv"…"version literalraw"…"raw string
string concatenation
string(str1, str2, …) combine multiple string
str1 * str2 concatenate them
"$str1 and $(str2)." formatted string
tuple and list
(a, b, c)tuple[a, b, c]list
match tuple or list or variable length
first, second, rest... = (a, b, c, d, e)
# rest = (c, d, e)
function
traditional syntax
function func1(args)
# …
end
assignment form
func1(args) = # …
- the last expression is returned
nothingis returned without a return value
function argument type annotation
func1(arg1::Type1, …)
optional argument
func1(arg1, opt_arg1=default_val1, …)
- optional argument are positional
keyword argument
func1(arg1, ¬; keyword_arg1=default_val1, …)
- keyword argument must have the keyword specified when called
- keyword argument does not need a default value, but then it will be mandatory
- keyword name is implied as the variable name if it appear after
;when called
function taking function as argument
func1(f::Function, arg2, …)
call with named function
use with anonymous function
func1(x -> …, val2, …)use with do-block
func1(val2, …) do arg1_for_function_passed_in, … # … end
dispatch
function can have different method for different type
anonymous function
(args…) -> # …
or
function (args)
# …
end
function composition
(f ∘ g)(args)
is equivalent to
f(g(args))
function chaining (function piping)
args |> g |> f
is equivalent to example above
use piping with broadcasting
.|> apply piping element-wise
vectorize function
func1.(args)
apply func1 to each element in each argument, equivalent to
broadcast(f, args)
Last edited:
Kotlin
pattern matching
when (var0) {
LITERAL -> // …
in 0..5 -> // …
is TYPE -> // …
else -> // …
}
nullability
declare nullable variable
var0: TYPE?
late-initialized variable
lateinit var var0: Type0
- no need for null check when accessing
- crash at runtime if no initialized
access field in nullable variable
return null if var0 is null using safe-call operator
var0?.field
assume not-null using non-null assertion operator
var0!!.field
return default_var0 if null using Elvis operator
var0?.field ?: default_var0
anonymous function
refer to existing function
fun fn0(arg0: TYPE0): RETURN_TYPE0 {
// …
}
val lambda0: (TYPE0 -> RETURN_TYPE0) = ::fn0
create anonymous function directly
val lambda0: (TYPE0 -> RETURN_TYPE) = { arg0 ->
// …
}
or refer to the only argument as it
val lambda0 = {
doStuffWith(it) // …
}
call function using trailing lambda syntax
fnUsingLambda(arg0) {
// Body of anonymous function.
}
suspend function
suspend fun fn0(arg0: TYPE0): RETURN_TYPE0 {
// …
}
can only call in a
CoroutineScope, execute seemingly sequentiallybrainless scope
GlobalScopescope of current function
val scope = CoroutineScope(Job())android UI component can use
val scope = MainScope()
can be started in background using
launchorasyncof aCoroutineScopeuse context to choose
Dispatcher:withContext(Dispatchers.IO) {/*IO tasks*/} withContext(Dispatchers.Default) {/*CPU tasks*/}
Misc
prettry print Arrays: .contentToString()
Last edited:
Lua
data type
nil
string
str1 .. str2 concatenation
string.format("literal and %s…", variables…) formatted string
boolean
only false and nil are falsy
map
map1 = {
key1 = val1,
-- …
}
loop through map in order
for index, element in ipairs(map1) do
-- …
end
pairs loop not necessarily in order
#map1 length
array
array is just map with key 1, 2, 3, …
insert element into array in order
list = {}
for element in iterable1 do
table.insert(list, element)
end
sort array
table.sort(list)
arithmetic operation
~ not ~= not equal
variable
- variable are global by default
localmake variable local
function
function func1(args)
-- …
return …
end
- missing argument is nil
{ ... }put
use a variable amount of argument
function func1(...)
local args = { ... }
-- …
end
condition
if statement
if bool1 then
-- …
else if bool2 then
-- …
end
else
-- …
end
while statement
while bool1 do
-- …
end
for statement
for element in iterable1 do
-- …
end
emulate ternary operator (neither option can be falsy)
result = bool1 and option1 or option2
input/output
command line argument
local args = { ... }
get script file parent directory
debug.getinfo(1).source:match("@?(.*/)")
get home directory
os.getenv('HOME')
run command
function run_command(command, pattern)
handle = io.popen(command)
result = handle:read(pattern or "*a")
handle:close()
return result
end
module
load a module
mod1 = require("mod1")
reload module eagerly (Lua does not read the file again by default at the second require)
local function use(module)
package.loaded[module] = nil
return require(module)
end
create a module
- file name is module name
Mod1 = {}
function Mod1.func1(args)
-- …
end
return Mod1
Last edited:
Perl
install package A/B
cpanm install A::B
Last edited:
Python
environment
- Python REPL (Read-Evaluate-Print Loop)/ Python shell
- script script file
variable
operator
- assignment operator
=
naming convention
- camelCase
- snake_case
PEP 8 guideline
inspect (in REPL)
unassign (delete)
del var1
data type
- fundamental data type
- compound data type (data structure)
- check data type
type()
string str
- character
- length
len(string1) - sequence
string literal "string literal"
delimiter
""or''multiline string
"first and \ second"or
"""first line second line"""raw string
r"raw string"
string operation
- concatenation
string1 + string2
need to manually make sure both are string - indexing
string1[index1]→ character
negative index count from right - slicing (slicing)
string1[index1:index2]
return string consisting ofstring1[index1]tostring1[index2 - 1]
leavingindex1orindex2empty means0or-1by default
exceeding string length return empty string''for those parts\ - multiplication
string1 * nrepeatntime
immutability
string method
- convert case
.lower().upper() - remove whitespace
.rstript()from the rightlstript()from the leftstript()both side - check start/ end
.startswith().endswith()→ boolean - find substring
.find(substring1)→ int index of the first found;-1if not found - replace
.replace(string1,string2)
input
input(prompt_string) → str
string conversion
- anything to string
str(var1)
output
print(string1, string2…)
each part must be string' 'are added between stringformatted string literals (f-string)
f"{string1}string_literal…"→ strenclose variable name in
{}
number int float
number literal 1
- separate by
_ignored - exponential notation (E-notation)
1e2→ float - too big →
inf/ too small →-inf
arithmetic operation
- operand and operator
- addition
+subtraction-multiplication*→ int iff both operand int, else float - division
/→ float - integer division
//→ int iff both operand int, else float, round down
no0denominator allowed regardless of type - exponent
**→ int iff both operand positive int, else *float - modulus
%→ int iff both operand int, else *float
number method
- round tie to even
round(num1,n)
by default, blank precision → int withNoneprecision
with intn→ int iff both int, else float withnfloating digit (negative precision go beyond decimal) - absolute value
abs()return same type - power
pow(base1,exponent1) = base1 ** exponent1,pow(base1,exponent1,mod1) = (base1 ** exponent1) % mod1 - check if float is int
float1.is_integer()→ boolean
number conversion
- string to int
int(string1)can only take string in integer form
output
fixed-point number f"{num1:format}"
format language format
.ptprecisionptypete.g..2f.pt%in percentage form,separate digit with comma
complex number
format n =num_real + num_imaginej
- getting real part and imaginary part
n.realn.imag→ float - conjugate number
n.conjugate()
*intandfloatalso have these
None NoneType
no data
data structure
tuple
- ordered sequence (iterable)
- immutable
- can hold multiple type of element at the same time
tuple literal (elem1,…)
- empty tuple
() - tuple with only 1 element
(element1,)
built-in create method
tuple(converted1) convert iterable converted1 into tuple
length len(tuple1)
indexing tuple1[index1]
slicing tuple1[index1:index2] → shallow copy
packing/ unpacking
- packing
tuple1 = elem1,… - unpacking
var1,… = tuple1 - combined
var1,…,varN = literal1,…literalN
check contain elem1 in tuple1 → boolean
list
- same as tuple
- mutable
- use
[]
create
list(iterable1)string1.split(separator1)- list comprehension
[expression1 for elem in iterable1]
mutate
- replace element
list1[index1] = elem1 - slice replace
list1[index1:index2] = list2not necessarily same length - insert
list1.insert(index1,elem1)
index too big is seen as last index - append
list1.append(elem1)append to last space, equivalent tolist1.insert(list1.__len__(),elem1) - extend
list1.extend(iterable1)append an iterable - pop
list1.pop(index1)return and removelist1[index1]
list method
- sum number
sum(list1)iff all element are number min()max()- shallow copy
list1[:]orlist1.copy() - sort
list1.sort()
keylist1.sort(key=func1)sort by return value offunc1(elem)
dictionary
- key-value pair
create dictionary
- dictionary literal
{key1:val1,…} - from tuple of tuple
((key1:val1),…) - empty dictionary
{}ordict()
access
dict1[key1]→ value corresponding- index
dict[index1] - convert to dict_items
dict1.items()
mutate dictionary
- add or overwrite
dict1[key1] = val1 - remove
del dict1[key1]
set
dictionary without value
create set
set(a) # or
{a, b, c}
set method
some method map to arithmetic operator but those only work on other set instead of any iterable
.union(iter1)≈|.difference(iter1)≈-.symmetrical_difference(iter1)≈^issubset(set1)≈<=issuperset(set1)≈>=
function
- argument
- return value
- side effect
property
function are values
function name are variable
side effect
change something external to the function itself
anatomy
- function signature
def fun_name(parameter_list): - function body
fun_signature
fun_body
parameter
placeholder for variable
- default value
fun_name(para1=val1,…)
return statement return return_value
automatically return None if no return statement
call function_name(args,…)
built-in function
- get the usage of the function
help(fun_name)
user-defined function
- define first and then call
- docstring—triple-quoted above function body
closure
- foot gun: defining closure in a loop only capture variable value at the last iteration of the loop
- ⇒ need to call another function to return different closure every iteration
loop
while loop
- while statement
while test_condition: - loop body
for loop
- for statement
for membership_expression: - loop body
- else statement
else:execute if not break
membership expression
a in bi in range(n)
break out
exit loop break
next iteration continue
scope
- local scope
- global scope
- enclosing scope
LEGB rule
Local Enclosing Global Built-in
- violate scope
global var_namelet local access global
class
class Class1: CamelCase
empty structure to contain data
dunder method .__method1__()
local method _method1() naming convention
(instance) method
function in class
- change what is printed
.__str__()
instance
object built from class
instantiate
Class1(para1,…)
attribute
mutable
class attribute
variable with initial value every object of this class has, defined right under the class structure
instance attribute
initialize method
.__init__()def __init__(self,para1,…):
access object1.attribute1 dot notation
inheritance
- create child class
class ChildClass1(ParentClass1): - common ancestor
object - check class and parent class of instance
isinstance(object1,Class1)
method inheritance
- completely overwrite parent method
- access parent (direct, not grand) method using
super().method1(arg1,…)
module
calling module import module1
variation (can be combined)
import module1 as name1from module1 import name1,…
namespace module1 in module1.name1
specify different options for import and ran directly
if __name__ == '__main__':
package
a folder to group modules
must-have module __init__.py
for the package to be recognized
import module from package import package1.module1
from package1.module1 import name1
subpackage
a package under a package
package manager
automate install, update, remove of third-party package
de facto package manager pip
virtual environment is used to make sure things work after some update
file input/ output
path library module pathlib
Path object
- file or directory name
path1.name - component of file name
path1.stempath1.suffix - check existence
path1.exists()→ boolean - check if is file
path1.is_file()→ boolean - check if is directory
path1.is_dir()→ boolean
create
- from string
Path(string1) Path.home()orPath.cwd()path1 / string1orpath1 / path2
absolute/ relative path
absolute path
start from root
- test
path1.is_absolute()→ boolean - access root directory
path1.anchor
relative path
start from cwd
path1.anchor→''
path component
all level of directory from low to high path1.parents → iterable
one level up path1.parent → Path
manipulation
- make directory
path1.mkdir()
avoid error if directory already existpath1.mkdir(exist_ok=True)
create all the parents directory if not existpath1.mkdir(parents=True) - make file
path1.touch()
trying to make file that already exist do nothing - iterate all content of directory
path1.iterdir()→ iterable - move
src_path1.replace(des_path1)overwrite destination by default - delete file
path1.unlink()
avoid error if not existpath1.unlink(missing_ok=True)
search for file in directory
path1.glob(pattern1) → iterable
- wildcard character
*—any number of character?—1 character[abc]—any included character
- match to a pattern
- recursive matching
use**/search in the subtree
or usepath1.rglob(pattern1)
shutil module
remove subtree shuril.rmtree(path1)
os module
both pathlib and shutil are implemented using os
file
text file
character encoding
line ending
- carriage return
\r - line feed
\n
csv file
csv module
write
- writer object
csv.writer(file1)- write one line
writer1.writerow(list_of_str1)add','between all item and\nat the end - write multiple lines
writer1.writerows(list_of_list_of_str1)
- write one line
- dictionary writer object
csv.DictWriter(file1,fieldname=list_of_str1)write header
DictWriter1.writeheader()→ int of character writtenwrite one line
DictWriter1.writerow(dict1)write multiple line
DictWriter1.writerows(list_of_dict1)it in fact work with any object with
write()method
read
- reader object
csv.reader(file1)→ iterable of list of str - dictionary reader object
csv.DictReader(file1)→ *iterable of dict ofheader:val
binary file
can only interact with byte directly
file object
create
path1.open() from pathlib
- mode
path1.open(mode=mode1)"r"—read"w"—write"a"—append"~b"—for binary file with~be one of the mentioned
- encoding
path1.open(encoding=encoding1)."ascii""utf-8"
open(string1) built-in
exactly like path1.open() except using a string
with statement with … as file1:
close file1.close()
read
- all at once
file1.read()→ str - line by line
file1.readlines()→ iterable of str
write
create file if not exist and parent exist
write a string
file1.write(string1) → int of character written
- overwrite when in write mode
- append when in append mode
write a list of string
file1.writelines(list1)
regular expression (regex)
meta-character
wild card
*any number of the character left to it, greedy, excluding\n.a character, excluding\n*?any number of the character left to it, non-greedy, excluding\n
string method
- find all
re.findall(pattern_string1,checked_string1)→ list of str - not case sensitive
re.meth1(…,re.IGNORECASE) re.search(pattern_string1,checked_string1)→ MatchObjectmatch_object1.group()→ the first greedy result
- find replace
re.sub(pattern_string1,replace_string1,checked_string1)
mistake
error
- syntax error
- run-time error
try
try:
execution1
except ErrorClass as error_name:
execution2
finally:
execution3
- multiple kinds of error
except (error_name1,error_name2): - catch error individually using multiple
except - bare exception clause
except:catch any error
comment
- block comment
# block comment - in-line comment
code # in-line comment - document code
docstring"""description of this program"""
Last edited:
tqdm
kill the current tqdm progress bar:
from tqdm import tqdm
tqdm._instances.pop().close()
Last edited:
Mathematica
- space is seen as
approximation
exact result by default, to get approximation
- add a dot at the end
…. - use
N[]
complex number
imaginary unit I
variable assignment
- unassigned variable treated as symbol
- assigned variable work like in other language
- clear variable
Clear[]
data structure
list `
- getter
list1[[index1]] - slicing
list1[[start1;;end1]] - show as list
FullForm[]
vector
vector are represented as list
- dot
.orDot[,] - cross
esc+cross+escorCross[,]
matrix
a list of list
- show as matrix
MatrixForm[]
hide output ;
force simplify Simplify[]
math function
define f[var1_]:=…
calculate f[…]
integration
- indefinite
Integrate[fun1[var1],var1] - definite
Integrate[fun1[var1],{var1,start1,end1}] - numerical
NIntegrate
equation
polynomial
SolveValue[] gives precise solution NSolveValue[] gives approximate solution
non-polynomial
FindRoot[] uses Newton’s Method
plot
search help
Last edited:
MATLAB
syntax
number
special variable
- most recent answer
ans - accuracy of floating-point precision
eps
special constant
- not a number
Nan -
Inf -
iorj -
pi
numerical operator
- plus
+minus- - matrix multiplication
* - array multiplication
.* - matrix exponential
^ - array exponential
.^ - left-division
\ - array left-division
.\ - right-division
/ - array right-division
./ - square root
sqrt()
character syntax
- regularly spaced elements or entire row or column
: - enclose function argument, array index; override precedence
() - enclosure array element
[] - decimal point
. - line-continuation
... - separate statement and element in a row
, - quote sign and transpose
_ - non-conjugated transpose
._
semicolon ;
- end of statement
- hide output of statement
percentage sign %
- inline comment
% comment - multiline comment
% {
comment
% }
save and load
- save all variable in workspace as
.matfilesave file_name - load the file
load file_name
variable
assign
- all variable is either array or matrix
- no
nulltype - unassigned value are assigned to
ans - long assignment
var1 = command1 ...
command2
- declare global variable
global
vector
1D array
- row vector
[num1 …] - column vector
[row1;…]
matrix
2D array [r1c1 r1c2 …; r2c1 …]
solve
x = A\B
variable management
- display all variable name
who- with information
whos
- with information
- delete all variable
clear- delete variable
var1clear var1
- delete variable
- check existence of variable
exist var1
session management
shell environment
- open shell
matlab -nodisplay -nodesktop - close shell
quitorexit
file system
- shell script
cddirdeletepwd
format format arg1
- short format (default, 4 decimal place)
format short - display 16 decimal place
format long - display 2 decimal place
format bank - display in exponential form
format arg1 e - display as the closest rational form
format rat
find help
- help topic
help - search help entry
lookfor
Last edited:
MIPS Assembly
register
$0: always 0$v0,$v1: expression evaluation and function return value$a0~$a3: argument$t0~$t9: temporary variable saved by caller$s0~$s7: temporary variable saved by callee$gp: global area pointer$sp: stack pointer$fp: frame pointer$ra: return address
memory declaration
.data
var0: .word number0, number1, …
var1: .space number_of_bytes
var2: .byte character0, character1, …
var3: .asciiz string
var4: .float floating_point_number
.text
.align 2
.global main
main: …
function0: …
line label
label: instruction0
…
inner label
start with underscore to distinguish from function
instruction format
| opcode | operands |
|---|---|
| 6 bits | 26 bits |
- Op: opcode
- Rs: source register
R-type
| name | Op | Rs | Rt | Rd | Sh | Func |
|---|---|---|---|---|---|---|
| bits | 6 | 5 | 5 | 5 | 5 | 6 |
- Rt: the other source register
- Rd: destination register
- Sh: shift register
- Func: function code
I-type
| name | Op | Rs | Rt | Immed |
|---|---|---|---|---|
| bits | 6 | 5 | 5 | 16 |
- Rt: target register
- Immed: immediate value
| name | Op | Target |
|---|---|---|
| bits | 6 | 26 |
system call syscall
- load syscall code into
$v0 - put argument into
$a0,$a1,$f12(float) syscall- return value in
$v0,$f0(float)
syscall code
- 1: print integer
- 2: print float
- 3: print double
- 4: print string
- 5: read integer
- 6: read float
- 7: read double
- 8: read string
arguments: buffer, length - 9: sbrk (malloc)
- 10: exit
Last edited:
PostgreSQL
Query optimization
- need to write query in certain ways sometimes, cannot rely on Postgres being smart
- source of truth: replace placeholders w/ real value, prepend
EXPLAIN, run, see query plan- given query + plan to LLM, ask to optimize
avoid join after getting max per group:
SELECT DISCINT ON (group_key) group_key, other_columns
FROM table_name
ORDER BY group_key, column_sorted_on DESC
Last edited:
Racket
language type
specify the language used in the first line of a program
#lang racket
data type
string
string literal can have new line
boolean
#t #f
- non-
#fare considered#t
variable
(define var_name expression)
function (procedure)
(define (func_name args) (output))
call function
(func_name args)
special form
(if test1 do_if_true do_if_false)
(cond (test1 do_if_test1)
(test2 do_if_test2)
(else fallback_expr))
(begin first_thing_to_do second_to_do)
Last edited:
Ruby
string
string literal
simple string
'parsed as is'
string considering \
"string where \nis parsed"
formatted string
str = "yes
"say #{str}"
match string
match a string with regex and return index of match
str =~ regex
match string with regex and name each part
comp = /\[(?<comp1>.*)\](?<comp2>.*)/.match(str)
comp1 = comp[:comp1]
comp2 = comp[:comp2]
get all word from string
str1.split(/[^[[:word:]]]+/)
array
arr = [ "a", 1, true ]
arr[0] # => "a"
arr[1, 2] # => [ 1, true ]
array method
.length .push(ele) .pop
# loop through
arr.each do |ele|
# …
end
# join with `str`
arr.join(str)
# map
arr.map do |ele|
# …
end
# map with index
arr.map.with_index do |ele, index|
# …
end
string array
%w(this will be split) # => [ "this", "will", "be", "split" ]
hash
# old way
ha = {
'a' => 1,
'b' => 2
}
ha['a'] # => 1
ha['c'] # => nil
# new way
ha = {
'a': 1,
'b': 2
}
ha[:a] # => 1
block
{ |args|
# …
}
# or
do |args|
# …
end
call block
yield {|ele| puts ele}
control flow
if
if a
# …
elsif b
# …
else
# …
end
case
case a
when b
# …
when c
# …
end
while
while a
# …
end
statement modifier
do_something if a
function
yield execute a block
eval evaluate a string as code
define function
def func1(arg = default_value)
# …
# return last expression
end
main function
if __FILE__ == $0
# main function
end
class
class ClassName
# called with `new`
def initialize(arg)
# …
end
end
instance variable
@name
access instance variable
attr_accessor :name
method
# all instance method of class
ClassName.instance_methods
# instance method excluding inherited
ClassName.instance_methods(false)
inherited method
.respond_to?(str) check if object has method str
.to_s convert to string
.nil? check if nil
static method
def self.static_method_name(arg)
# …
end
safe navigation syntax &.
same as optional chaining
module
module ModuleName
def self.static_method1
# …
end
end
exception
class CustomError < RuntimeError
end
Last edited:
Rails
new rails project
rails new <project_name>
start rails server
rails s
routing
in config/routes.rb
Rails.application.routes.draw do
# root route is special
root 'articles#index'
# non-root route like this
# trigger `index` action in `articles` when GET request on `articles`
get 'articles', to: 'articles#index'
# route with variable use `:`
# the variable is passed to controller in the hash `params`
# in this case `params[:id]`
get 'articles/:id', to: 'articles#show'
end
resourceful routing
Rails.application.routes.draw do
resources :articles
end
this map route
| URI pattern | controller#action |
|---|---|
| articles | articles#index |
| articles/new | articles#new |
| articles/:id | articles#show |
| (POST) articles | articles#create |
| articles/:id/edit | articles#edit |
| (PATCH) article/:id | articles#update |
| (DELETE) article/:id | articles#destroy |
and set up URL and path helper method
| method | return |
|---|---|
| article_path | “articles/#{article.id}” |
model
in app/models
- singular name
generate model
generate model Article with two field
rails g model Article title:string body:text
- also generate database migration
generate and save new model object
# generate new article object
article = Article.new(title: 'Example', body: 'Example text.')
# save to database
article.save # => true
update model object
article.update # => true
validation of model object when save or update
# declare a `article_params` method to validate
def article_params
params.require(:article).permit(:title, :author, :body, :status)
end
# use the method when try saving or updating
if @article.update(article_params)
redirect_to @article
else
render :edit, status: :unprocessable_entity
end
query model object from database
# query article by id
Article.find(1) # => 1 Article object or Nil
# query all articles
Article.all # => 1 ActiveRecord::Relation object
view
in app/views
html.erb file
embedded Ruby in HTML
run ruby code
<% … %>run ruby code and render the return value
<%= … %>write comment that does not render in result
<%# comment %>
access instance variable in view
<ul>
<% @articles.each do |article| %>
<li>
<%= article.title %>
</li>
<% end %>
</ul>
link to other page in view
product a link with some_text to
article_path<%= link_to some_text, article %>redirect to show a model object
redirect_to @article- the browser make a new request
- use
redirect_toto mutate database
render image
<%= image_tag image_path %>link to the same page with different params
<%= link_to some_text, url_for(params.permit!.merge(field_to_change: field_value)) %>
partial template
partial has name starting with _
e.g.
_form.html.erb
access partial template from another view
<%= render 'comments/form' %>
relative path without
_add argument
render 'form', article: @article # or the longer format render partial: 'form', locals: { article: @article } # or even longer format render partial: 'form', object: @article, as: 'article'render a collection
render @products # or longer format render partial: 'product', collection: @productsor even longer format
<% @products.each do |product| %> <%= render partial: "product", locals: { product: product } %> <% end %>
controller
in app/controllers
controller for articles is articles_controller.rb
- plural name
generate controller
generate ArticlesController and its index action
rails g controller Articles index
by default, index action of Articles render app/views/articles/index.html.erb
instance variable in controller
instance variable in controller can be accessed in view
# this will be accessed in `articles/index.html.erb`
def index
@article = Article.all
end
controller method for resourceful routing
index method in controller
show method in controller
need to query model object by params[:id]
new method in controller
only initialize new model object
create method in controller
assign value to new model object and attempt to save it
def create
@article = Article.new(title: '…', body: '…')
if @article.save
redirect_to @article
else
render :new, status: :unprocessable_entity
end
- strong parameter
database
SQLite3 by default
migration
in db/migrate
rails db:migrate
console
open a rails irb console
rails console
Hotwire
Turbo
Last edited:
Rust
function fn
main function
fn main(){}
associated function
a function that is implemented on a type
`type1::fun1()`method
- call method on instance
instance1
.method1();variable
immutable by default
declare
let
- declare mutable variable
let mut
type
String
new string String::new()
str
"str literal" // str literal
r#"str
literal"# /* raw str
literal */enumeration
variant
result Result
enumeration with variant Ok or Err
handle error and convert to
Option:result.map_err(|e|/*…*/).ok()`convert error to value:
result.map_or_else(|e|/*…*/, identity)using
anyhow, bothResultandOptioncan be wrapped asResultusing.context
Ok variant
indicate successful run, contain result
Err variant
indicate failure, contain reason
.expect() method
crash on Err and display argument
statement
represent instruction for action
end with ;
expression
- represent a value
- end without
; - can be used as return statement
reference
- refer to variable
&var1 - mutable reference
&mut var1
input/ output use std::io
input
io::stdin()→ an instance of typestd::io::Stdin- standard input handle type
std::io::Stdin
macro
print println!()
debug print dbg!()
pass it a reference because it take ownership of argument
todo todo!()
unreachable unreachable!()
comment
inline comment //
package
crate
root convention
- binary crate root
src/main.rs - library crate root
src/lib.rs
both same name as package
import crate use
- absolute path
crate::… - relative path
self::…
import function
use the parent path
import struct or enum
use the whole path
alias
use … as …
re-exporting
pub use …
nesting path
- both are children
use common_path::{path1,path2…} - parent and children
use common_path::{self,path1…}
glob operator *
brings everything into scope
trait
define
pub trait Trait1 {…}
trait method
empty method
`fn fun1(&self,…)->Type1;`default implementation
`fn fun1(&self,…)->Type1 {…}`
implement trait on type
`impl Trait1 for Type1 {…}`implement trait method
use default implementation—do nothing
override implementation
`fn fun1(&self,…)->Type1 {…}`
use trait as parameter
shorthand
`pub fn fun1(para1: &impl Trait1) {…}`trait bound syntax
pub fn fun1<T: Trait1>(para1: &T) {…}
multiple trait bound +
- shorthand
pub fn fun1(para1: &(impl Trait1 + Trait2)) {…} - trait bound syntax
pub fn fun1<T: Trait1 + Trait2>(para1: &T) {…}
where clause
fn fun1<T,U>(t: &T, u: &U)->Type1
where T: Trait1 + Trait2,
U: Trait3 + Trait4
{…}return type implement trait
`fn fun1(…)->impl Trait1 {…}`closure
anonymous function stored as variable that can capture its environment
`let closure1 = |var1,…| {return_value};`implement FnOnce trait
- more overhead than function
- automatically detect and decide type and cannot have multiple set of them
type annotation
|var1: type1,…| -> return_type {return_value};
storing closure
struct Store1<T>
where
T: Fn(type_for_var1,…) -> return_type,
{
attr1: T,
…
}- use a
Option<…> - use a hashmap
capture environment
borrow by default implement
Fntrait, mutable as needed implementFnMuttraitadopt ownership using
move`move |var1,…| {return_value}`
misc
rustc limitation: returning a non-'static variable var0 in any branch keep borrowing what var0 borrows, even in other branch
Last edited:
R lang
naming
character allowed
letter, ., _
- cannot start with
_ - cannot start with
..
basic syntax
command separation
; or \n
comment
# last to the end of line
assignment
= assignee <- assigner assigner -> assignee
function
execute from .R file
source("filename.R")
manipulate data storage
show all object
objects()
remove object
rm(obj1,obj2,…)
store to disk
choose y when quit q() stored as .RData
data structure
vector
c(ele1,ele2,…) can also take vector as element, will expand
package managing
install package
install.packages("package_name")
- install multiple packages
use a vectorinstall.packages(c("package1","package2",…))
Last edited:
Shell
switch user to root and do
sudo
file & directory
print working directory
pwd
list file in path
ls [path]
change working directory to path, by default to ~
cd [path]
go up one directory
cd ..
go back to the last directory
cd -
copy one file to a given directory [and name it as instructed (the new name cannot be a local folder’s name, or it will just copy it there)]
cp <original file path> <new copy’s parent folder path>[/<new copy’s name>]
copy recursively one folder to a given directory
if the new directory does not exist, the command will create it
cp -r <original folder path> <new copy’s parent folder path>
remove one file
rm <file path>
remove recursively one folder
rm -r <folder path>
remove one empty folder
rmdir <folder path>
make directory
mkdir
run the file
./<file name>
system information
display [human-readable (i.e., in MB, GB, etc.)] file system disk space usage
df [-h]
disk usage for this directory
du [path]
free and used memory in the system [in megabytes]
free [-m]
table of processes
top
print all system information: name, kernel, etc.
uname -a
print version information for the linux release
lsb_release -a
user
add a new user
adduser <new user’s name>
assign password to the user
passwd <user name>
manual
manual for the command
man <command>
introduction to linux command-line
man intro
search in manual what is <string>
whatis -r <string>
history
show command you input with numbers before them
history
Ctrl + R
search for command you input
cursor navigation
Ctrl + A/ Home
move cursor to start of line
Ctrl + E/ End
move cursor to end of line
Ctrl + B
move cursor to beginning of word
Ctrl + K
delete to the end of line
Ctrl + U
delete to start of line
Ctrl + W
delete word
Alt + B
go back one word
Alt + F
go forward one word
Alt + C
capitalize the letter and move cursor to end of word
ANSI terminal escape sequence
control sequence introducer (CSI): \033[
clear screen and return to home: \033[2J\033[H
clear line and return to left: \033[2K\r
Last edited:
TimescaleDB (TigerDB)
Compression
- for large text/binary field, Postgres first TOAST, then TimescaleDB stupidly compresses the TOAST pointer
- manually change chunk w/
merge_chunk,split_chunk,convert_to_rowstore,convert_to_columnstore- can make job to manually merge/split/compress chunk
check hypertable compression rates (not including TOAST):
SELECT
pg_size_pretty(before_compression_total_bytes) as before,
pg_size_pretty(after_compression_total_bytes) as after
FROM hypertable_columnstore_stats('HYPERTABLE_NAME');
check chunk compression rates:
SELECT
pg_size_pretty(pg_total_relation_size(chunk_schema||'.'||chunk_name)) AS tot,
pg_size_pretty(before_compression_total_bytes) AS tot_be4,
pg_size_pretty(after_compression_total_bytes) AS tot_aft,
pg_size_pretty(before_compression_table_bytes) AS tab_be4,
pg_size_pretty(after_compression_table_bytes) AS tab_aft,
chunk_name, range_start_integer, range_end_integer, is_compressed
FROM chunk_columnstore_stats('HYPERTABLE_NAME')
NATURAL JOIN timescaledb_information.chunks
ORDER BY range_start_integer
Last edited:
The Trail Language
Silly ideas about how a language should have all its syntax trailing.
- Identifiers can be used as procedure arguments.
- Blocks are a comptime primitive type and can contain undefined identifiers.
- All code can be marked to be comptime.
- No generics. Instead, generate types or procedures needed using comptime procedure execution.
- No grouping executions using parentheses.
Syntax
- Keywords are capitalized letters.
- They will look fine with syntax highlighting.
- White spaces separate tokens.
a+bis a single token, it can not involve procedure call.
- Expressions are evaluated left to right, with no operator precedence.
- Tuples are space-separated and expressions inside are lazy-evaluated.
=and many other side-effects-only procedures return( ).
1 = a -- Assign `1` to `a` by calling procedure `=` at comptime.
true =M b -- Mutable variable.
a / 2.0 = a/2 -- Call procedure `/` with `a` and `2.0` and assign to `a/2`.
false =R b -- Reassign `b`.
0 .. 10 do { "Hey" print } -- Print "Hey" 10 times.
( 1 2 ) nth 0 assert_eq 1
Procedures
=>is a comptime procedure that takes a tuple of identifiers and a block as arguments and returns a procedure.- The last expression of a block is its return value.
- No “return” keyword.
- Procedures that take arguments are automatically called with the expression before it and the appropriate number of expressions after it.
- If a procedure does not take any arguments, it cannot be called by itself and requires a comptime procedure
callto call it. - If an expression is not callable, the expression before it is discarded when the execution reaches it.
- If a procedure does not take any arguments, it cannot be called by itself and requires a comptime procedure
- Procedure
+doctakes anything and a string as its two arguments, and apply the string as documentation to the first argument. - Limited polymorphism: the first argument of the procedure decides what the rest of the procedure arguments could be.
( a b ) => { a + b } = add -- Procedure `add`.
( ) => { "hell" ++ "o" } +doc "Return \"hello\"." = greet -- Procedure `greet`.
greet doc starts_with "Return" assert -- Assert the documentation of `greet`.
greet = also_greet
greet call = hello -- => "hello"
Names
Symbols can be names.
( a b ) => { a pow b } = ** -- Procedure `**`.
Compile-time (comptime) computation
The program is interpreted into a program that gets compiled.
- During interpretation, expressions marked with
Care calculated. - Global variables are always calculated at compile time and immutable at run time.
- Comptime variables can also be declared “mutable at comptime.”
32 * 32 = TWO_TO_TEN -- Comptime.
( a b ) => {
b * b = b_square -- Run-time.
a * TWO_TO_TEN + b_square -- Run-time.
} = hyperbole -- Comptime.
( x ) => {
2 hyperbole 7 C = LUCKY_NUMBER -- Comptime.
LUCKY_NUMBER is_comptime assert -- Assert that `LUCKY_NUMBER` is comptime.
x + LUCKY_NUMBER -- Run-time.
} = add_luck -- Comptime.
2 =M TO_BE_CHANGED -- Comptime mutable.
0 .. 10 do { TO_BE_CHANGED * TO_BE_CHANGED =R TO_BE_CHANGED } -- Comptime
-- `TO_BE_CHANGED` = 4294967296
-- Assign a procedure type that take one argument of `Any` type and returns
-- an instance of `( )` to `equal_type`.
( Any ) proc_type ( ) = equal_type
= s_type assert_eq equal_type -- Assert `=`'s type.
Last edited:
Referral Links
- Capital One https://i.capitalone.com/GaOMotu45
- Discover ($100) https://refer.discover.com/sichangh!cce487f692!a
- Interactive Brokers ($0~$1000 of stock based on deposit) https://ibkr.com/referral/sichang832
- Perplexity (Pro on student status verification) https://perplexity.ai/pro?referral_code=2GQCN9O0
- Tello https://tello.com/account/register?_referral=P3JD3XJS
Payment
- Monero (XMR): 46SFFN7dFmA7e1BHuWbckMUXFdaPaAyqRim6UVuAqWCeMrcTrpfifQtHzmak44eAFmD9iZ8MfhYAyaHpfQRB6zrGPUWrMWs
Last edited:
Research Notes
Topic
want:
- significant & popular, easy sell
- easy to implement
meta question:
- how to fight misinformation
- how to fight content theft
- how to fight scam
- how to fight censorship
- how to find knowledge among spam on the web
- how to avoid the monotonic growth of software complexity
- what are the huge security holes
ideas:
- search engine exclude spam
- social media bot campaign
- GitHub scam
🤖 evidence-backed studies
Last edited:
Formal Disco: open-ended verified-program generation
(authored by agents unless marked 🧑)
- paper
- Gabriel Poesia, Simon Henniger, Tzu-Han Hsu, Yilun Du, and Nada Amin
- Formal Disco: Scalable Open-Ended Generation of Formally Verified Programs
- arXiv
2607.04631v1, submitted 2026-07-06 - archival record: https://arxiv.org/abs/2607.04631v1
- full text: https://arxiv.org/pdf/2607.04631v1
- code: https://github.com/metareflection/formal-disco
- datasets: https://huggingface.co/collections/metareflection/formal-disco
decision
- walkthrough rank: first of the 23 accepted canonical papers
- it directly targets VL’s central scaling constraint
- scarce verifier-checked Verus training data
- expensive frontier-model proof generation
- narrow diversity in self-generated proof corpora
- it reports both a scalable production loop and a trained Verus capability
- most other candidates address one adjacent layer
- benchmarks
- language foundations
- one verification domain
- repository retrieval or migration
- prior completed studies already cover CryptoProver and repository-level RAG-Verus
- no active study owner was recorded for canonical discovery
vpsd_c678c7ff1a09998c79f7ed70caba49f88fdd38efd93d9db9bdd44b248b420b31
- it directly targets VL’s central scaling constraint
- confidence: high on identity and reported results, medium on generality
- identity and bytes match the arXiv v1 archival record
- the record is a preprint with no venue or peer-review claim
- results are author-reported and were not independently reproduced here
evidence boundary
- abstract-level screening established only that the work generates verified programs in Dafny, Verus, and Frama-C
- this walkthrough is based on the complete 46-page v1 paper
- main method and objective in sections 3.1 through 3.3
- system and empirical evidence in sections 4.1 through 4.4
- limitations in section 5
- hyperparameters, qualitative examples, implementation details, features, and prompts in appendices A through E
- no VL experiment or reproduction was run
- claims below are paper claims unless labeled inference or recommendation
direct answer
- what it does
- coordinates three asynchronous LLM workers around a shared agenda
- an initiator sketches a small verified program from a random repository README and up to two language-documentation snippets
- a fixer patches compilation or verification failures for at most three attempts
- an extender grows a passing program and sends failures back for repair
- records prompts, outputs, outcomes, program ancestry, and verifier feedback
- bootstraps an open Qwen 2.5-Coder 32B model from Claude-generated traces
- iteratively fine-tunes only successful traces whose programs contribute most to chosen diversity measures
- uses compiler and verifier acceptance as the scalable correctness filter
- coordinates three asynchronous LLM workers around a shared agenda
- central idea
- raw corpus size is insufficient because duplicated or trivial programs can be arbitrarily numerous
- the paper instead maximizes Shannon entropy over selected program features
- annotation counts
- lemma-body sizes
- method-body sizes
- loop skeletons
- each training round retains the paper’s quoted
top 1/3 successful examplesranked by minimum surprisal rank
- why the architecture matters
- incremental initiate-repair-extend work reaches larger verified programs than one-shot generation
- external README themes reduce topic collapse
- documentation snippets expose rare language features
- verifier feedback supplies a deterministic signal at much larger scale than human review
full-paper results
- worker scaling, section 4.1
- Claude initiation succeeds 11 percent of the time for Verus
- Claude extension succeeds above 40 percent in both evaluated languages
- after five self-improvement iterations, Qwen matches or exceeds the seed Claude workers across the reported worker tasks and languages
- diversity, section 4.2
- entropy rises across iterations for all four optimized features and all three languages, with one reported exception
- Verus lemma-body-size entropy remains below the Claude seed corpus at iteration five
- the final Qwen Verus corpus contains a 105-line verified lemma versus an 86-line maximum in the Claude seed corpus
- Formal Disco leads compared Verus corpora on three of four sampled feature views only up to their respective sample lengths
- VeruSAGE remains most diverse for Verus loop skeletons
- entropy rises across iterations for all four optimized features and all three languages, with one reported exception
- downstream Verus annotation, section 4.3
- evaluation set: 149 filtered VerusBench programs
- Qwen 2.5-Coder 32B base pass@1: 8.7 percent
- the Formal-Disco-trained model pass@1: 43.0 percent
- reported Claude 4.5 Opus pass@1: 43.0 percent
- the SAFE-trained comparison pass@1: 40.9 percent
- at pass@32, Formal Disco reaches 59.1 percent while SAFE plateaus at 51 percent from pass@16 onward
- ablations, section 4.4
- three workers yield verified programs on 29.8 percent of LLM calls versus 23.0 percent for the monolithic agent in the Dafny ablation
- the iterative system averages 268 lines per program versus 85 for the monolithic agent
- removing README seeds lowers subject-word entropy from 8.1 to 5.9 bits at the matched sample size and lowers yield from 23.0 to 12.8 percent
- removing documentation snippets leaves four of 30 tracked Dafny features unseen
what was already done
- SAFE identified multi-level Verus data scarcity and synthesized about 20,000 programs from Python and Rust seed tasks
- VeruSyn expanded SAFE with tutorial-driven Verus feature coverage and reports a much larger corpus
- Dafny work includes ATLAS, DafnySynth, and DafnyBench
- theorem-proving systems already use proof checking to filter large synthetic corpora
- AlphaGeometry
- DeepSeek-Prover
- Goedel-Prover
- Formal Disco’s incremental contribution
- one language-agnostic agenda and worker loop across three auto-active tools
- joint open-ended generation of specifications, implementations, and proofs
- explicit measurement and optimization of corpus diversity
- downstream Verus evidence on human-written benchmark programs
- scope boundary
- this paper does not claim the first synthetic Verus data
- it does not establish repository-level autonomous verification
- it does not establish that generated specifications express human intent
what VL should learn
- treat verified traces as compounding product data
- retain task input, model output, patches, verifier diagnostics, attempt outcome, program ancestry, cost, and toolchain identity
- distinguish passing attempts from training-worthy attempts
- make diversity a first-class selection objective
- track coverage of Verus language features, proof patterns, dependency shapes, failure classes, specification structures, and repository domains
- compare corpora at matched sample sizes instead of citing only raw counts
- preserve rare successes during training and retrieval
- separate roles around a mechanically owned state machine
- sketch a bounded seed
- repair against fresh verifier output
- extend only a known passing checkpoint
- reverify after every accepted transition
- inject grounded external entropy
- use real repository requirements, APIs, issue histories, and Verus reference fragments
- do not let the model invent all tasks from its own prior outputs
- preserve VL’s repository-level differentiator
- add dependency-aware and change-aware features beyond single-program syntax
- measure specification adequacy, executable fidelity, whole-repository build, proof maintenance under change, and integration regressions
- keep the runner, not the model, responsible for acceptance
recommended integration
- immediate, no experiment authorized by this note
- add a corpus-quality specification for future VL data work
- verifier pass is necessary but not sufficient
- define explicit coverage and diversity features before generation
- record distributions and rarefaction curves per iteration
- add a durable trace schema to the VL design
- immutable input and toolchain identity
- patch lineage and verifier response
- specification origin and trust boundary
- repository and dependency context
- deterministic acceptance reason
- define training eligibility as a conjunction
- verifies under the intended toolchain
- satisfies anti-cheat and trust-boundary gates
- preserves executable and repository behavior
- contributes new task, language, proof, or repository coverage
- add a corpus-quality specification for future VL data work
- later evaluation proposal requiring separate authorization
- compare ordinary success filtering with diversity-aware filtering
- use held-out real repositories and chronological repository changes
- report specification review, whole-repository success, maintenance success, and cost in addition to local proof pass rate
product threat
- overall: high strategic threat, medium current substitution threat
- high capability threat
- verifier-filtered synthetic data can rapidly erase a scarce-data advantage
- open 32B models can acquire useful Verus annotation behavior from generated data
- the public code and datasets reduce replication cost for competitors
- high data-moat threat
- a competitor can bootstrap from frontier-model traces, replace expensive generation with an open model, and improve repeatedly
- diversity-aware filtering makes a large corpus less dependent on human seed examples
- medium architecture threat
- the shared agenda, specialized workers, checkpoint lineage, and verifier loop overlap with core mechanics needed by VL
- these mechanics are now prior art and should not anchor a novelty claim
- low-to-medium current product substitution threat
- evaluation is program-level, not repository-level
- the Verus result measures annotation recovery on 149 filtered benchmarks
- no evidence covers requirement discovery, specification adequacy, cross-module integration, build and test preservation, or proof maintenance
- the method assumes a usable verifier and hand-selected diversity features
- inference
- Formal Disco narrows VL’s defensible product to trustworthy repository transformation, specification governance, durable integration, and evidence quality rather than generic multi-agent proof generation
limitations and cautions
- verification proves conformance to the supplied specification, not that the specification matches human intent
- entropy is measured only over chosen syntactic and structural features
- optimizing a proxy can increase its diversity without increasing downstream utility
- human-written data remains more diverse on unoptimized annotation structure
- open-endedness still depends on external README and documentation seeds
- the strongest Verus number is a benchmark annotation task
- it is not end-to-end program synthesis
- it is not repository verification
- the model comparison is budget-sensitive
- the headline Verus equality is pass@1
- open models are sampled to 32 attempts, while Claude is capped at four
- the system uses 48 worker processes
- Qwen runs take about eight to 12 hours on four 80 GB H100 GPUs
- the paper does not provide a complete end-to-end dollar-cost comparison
- the paper’s own conclusion calls richer reasoning traces and verifier-based reinforcement learning future work
source-linked claims
- method and worker definitions: full paper sections 3.2 and appendix C
- source phrase:
distributed agenda
- source phrase:
- training selection: full paper section 3.3
- source phrase:
top 1/3 successful examples
- source phrase:
- Verus benchmark result: full paper section 4.3 and figure 5
- source phrase:
exactly 43%
- source phrase:
- diversity boundary: full paper sections 4.2 and 5
- source phrase:
small, hand-chosen set
- source phrase:
- source authenticity and exact bytes
- arXiv API record for
2607.04631v1 - local PDF SHA-256 equals a fresh download from the archival PDF endpoint
- evidence directory contains the checksum and provenance audit
- arXiv API record for
next discussion question
- should VL first adopt Formal Disco’s diversity-aware trace selection for training data, or prioritize the repository-level evaluation gate that this paper leaves open
canonical walkthrough manifest
- scope
- 23 accepted, unique discovery IDs from the reviewed intake handoff
- ordering is by expected value to VL
- direct product-capability overlap
- reusable data or evaluation leverage
- product-threat magnitude
- need for foundations before narrower applications
- this is not a paper-quality or publication-prestige ranking
- one paper may have only one active study owner
- rank one is complete after independent-evaluator PASS and the human memo
- rank two may start only when the manager records one distinct study owner
- all others remain queued without a new study owner
- prior completed studies will be reused, not duplicated
- ordering may change only when full-text evidence supplies a documented reason
- ranked queue
- 1 — Formal Disco: Scalable Open-Ended Generation of Formally Verified Programs
- canonical ID:
vpsd_c678c7ff1a09998c79f7ed70caba49f88fdd38efd93d9db9bdd44b248b420b31 - status: full-paper walkthrough complete after evaluator PASS and human memo
- first because it directly attacks VL’s scarce-data and model-scaling moat
- canonical ID:
- 2 — KVerus: Scalable and Resilient Formal Verification Proof Generation for Rust Code
- canonical ID:
vpsd_bbec77f6358b67e0cdadfe57627f4141fc72b29d01f9fc24710e077e258706a9 - next because scalable resilient Verus proof generation most directly overlaps VL’s core automation capability
- canonical ID:
- 3 — Towards Repository-Level Program Verification with Large Language Models
- canonical ID:
vpsd_e13b0628a0e1f43a3d3e669ddf8b278282fb40fc20d3212f328caaad67dccc69 - directly tests the repository-scale boundary that differentiates VL
- reuse the completed RAG-Verus sources and literature notes
- canonical ID:
- 4 — An AI Approach to Verified Production Cryptographic Libraries
- canonical ID:
vpsd_1d115669f942f903c6180a82e4edfce92f7505c6e0a4ed1b44b5569b8577b37d - production-library proof and specification synthesis is strong prior work
- reuse the completed CryptoProver source-mapped note and collection
- canonical ID:
- 5 — Propose, Solve, Verify: Self-Play Through Formal Verification
- canonical ID:
vpsd_d665b5a597a81fc278a6b0e2e40a129f59d83885b04844c2ea7d7db9ca701776 - verifier-grounded self-play could compound VL’s data and model capability
- canonical ID:
- 6 — Verus-SpecGym: An Agentic Environment for Evaluating Specification Autoformalization
- canonical ID:
vpsd_70efd668cd7a5dee4a7eab0365f3c67c43ae18c36b138221014c3a9f16a1f7c3 - specification formation is a central unresolved trust and evaluation layer
- canonical ID:
- 7 — The Rewrite Before The Proof: Agentic Translation of Rust to Verus
- canonical ID:
vpsd_bd11a18544f233b93ac26facb2fae5b2274d533a5f18374e3fed400abce0771b - translation strategy may change VL’s front-end architecture and scope
- canonical ID:
- 8 — From C to Verifiable Rust: Towards Practical Migration of Code and Specifications
- canonical ID:
vpsd_1be656b793966f3c49603537efa9e6cc73f88581a0c9376b3975d5e6b4e2f82e - migration of both code and contracts broadens VL’s practical input market
- canonical ID:
- 9 — VeriContest: A Competitive-Programming Benchmark for Verifiable Code Generation
- canonical ID:
vpsd_423d8f9fd60e9adbb7afcdfc23ddac1c8f04dc62973e02702a04bbfa80090bca - end-to-end specification, implementation, and proof scoring can sharpen VL’s evaluation decomposition
- canonical ID:
- 10 — A Benchmark for Vericoding: Formally Verified Program Synthesis
- canonical ID:
vpsd_6205243810c9b2dec10fc5c71df4ddc2620c5eee2df4ec281f9f91094db07622 - a second synthesis benchmark helps separate benchmark-specific progress from general capability
- canonical ID:
- 11 — Enhancing LLM-Based Proof Synthesis for Rust Programs via Semantic Chunking and Hierarchical Context Expansion
- canonical ID:
vpsd_156d8f98665d9b846c904aab6b8f242be81ebedab5d946c459e40420af98004d - context selection is directly reusable for repository-scale proof search
- canonical ID:
- 12 — Stop Means Stop: Measuring and Repairing the Enforcement Gap in Agent-Framework Control Primitives
- canonical ID:
vpsd_a826c5df48dfde560a7d99e08650d267401af3c42f302cce6d3b94e2689ec60c - agent-control enforcement affects trustworthy orchestration around VL
- canonical ID:
- 13 — Verified Detection and Prevention of Concurrency Anomalies in Multi-Agent Large Language Model Systems
- canonical ID:
vpsd_05b0a9d8876cb935314651b1a016f754007c9878c621e22dd1eb5dd4901ad534 - multi-agent correctness is relevant infrastructure but not the verifier core
- canonical ID:
- 14 — VerusBelt: A Semantic Foundation for Verus’s Proof-Oriented Extensions to the Rust Type System
- canonical ID:
vpsd_f21ced5228321216b6b28181047398ea9652a85a642fab2dc9094b25e51c7749 - the semantic trust base controls what Verus proofs mean
- canonical ID:
- 15 — Verifying Verus: A Lean 4 Formalization of the SST-to-AIR Expression Translation
- canonical ID:
vpsd_23c5712463d2c5dcb5f02934d3315b550f22911b49e97bac40f59bcf9dc96286 - verifier validation matters to VL’s assurance story but is narrower than proof-generation capability
- canonical ID:
- 16 — Verus: A Practical Foundation for Systems Verification
- canonical ID:
vpsd_07b26a64f757d16b745ce3c50b23da1fa8da2c8a46a6c6ce6a10333672c4851d - practical system design is foundational context for all later Verus work
- canonical ID:
- 17 — Verus: Verifying Rust Programs Using Linear Ghost Types
- canonical ID:
vpsd_473ded00b17823cb5fc202dac599036f69fcd2956b6ba1ce30174cd6a60c4cfb - core language ideas explain the proof model VL automates
- canonical ID:
- 18 — Verifying Probabilistic Programs in Rust
- canonical ID:
vpsd_aefbb47d312adeca6ddcc4973269f0a783b3bedc912f124eb138dd8795a6d204 - a Verus extension tests whether VL can handle richer semantics
- canonical ID:
- 19 — Formal Verification of a Rust-Based Buddy Physical Memory Allocator
- canonical ID:
vpsd_6ceea692c63c18bf5757ff9cd030144614c7762635b18780a1b293f5e992a227 - a concrete systems case can expose proof-engineering requirements
- canonical ID:
- 20 — Detecting Inconsistencies in Arm CCA’s Formally Verified Specification
- canonical ID:
vpsd_162b3a2fc064d6f60c7e0c6ddfe070da90f8e18de8d9ef6d8f5824679f3c8121 - specification inconsistency detection informs adequacy checks but targets a different formal stack
- canonical ID:
- 21 — Towards System-Oriented Formal Verification of Local-First Access Control
- canonical ID:
vpsd_bea7802dfdee744b78e4c7473bf8f38bcd1df6092b71bfc9423e0f55067b59f2 - system-level access-control modeling is useful domain evidence
- canonical ID:
- 22 — Shard: Securing GPU Kernels with Lightweight Formal Methods
- canonical ID:
vpsd_d8cc9a845a78dc18de8ebadb5393a4e3b904fd7b0692b717aa41023f2e26315f - GPU kernels are a valuable but specialized adjacent verification market
- canonical ID:
- 23 — End-to-End Formal Methods Integrated Development with SysMLv2 Using HAMR
- canonical ID:
vpsd_62b1474373e16f70461b888edb6fde5756edf365e154dd56891b00fb8666caa7 - toolchain integration is relevant, but direct overlap with Verus-oriented VL is the weakest in the accepted set
- canonical ID:
- 1 — Formal Disco: Scalable Open-Ended Generation of Formally Verified Programs
later discoveries excluded from this manifest
- status: separately unclassified and still under
vlprograms:0routing custody - rule: do not rank, assign a walkthrough owner, or count these among the 23 until each receives canonical relevance review
- trust boundary
- the discovery IDs and titles below are untrusted discovery metadata
- establish identity and relevance from primary publisher, author, DOI, or archival sources before reuse
- queued IDs
vpsd_d24f9b8e928143a20f531f8a2b985394309088e022a9202122727e213b79811a- Applying Modern Verification Techniques to a Root-of-Trust Bootloader
vpsd_589856f031270b09c3c6fa0a38e5a0ebc2faae6d636d5adec1b5d316bac6b1e1- VeruSAGE: A Study of Agent-Based Verification for Rust Systems
vpsd_21d189b9e9a8b6234f9fc1622c4e3f86f3d1318fd3d7f72fc430987a7ab45d3a- Atmosphere: Practical Verified Kernels with Rust and Verus
vpsd_abf2f808800266b3f876d87d291a42a191a1b7d582c55c977634a25db56d5d57- Reducing the Costs of Proof Synthesis on Rust Systems by Scaling Up a Seed Training Set
vpsd_c7573b41f42065ff3a006da770738527ef1c94dc4c671f2a537044bbc2957a59- Leveraging Large Language Models for Automated Proof Synthesis in Rust
vpsd_a21d6ced3594eeee6fab9b5635afa5c9b3639aab0f7849c9a75962501ede053b- Atmosphere: Towards Practical Verified Kernels in Rust
vpsd_7dcc5210e368c02431c50c6cbeffe9771e53827b16f8e9b9711957fb72ba1517- AutoVerus: Automated Proof Generation for Rust Code
vpsd_c7cd32f1cc95e061c711aa9e35182ce20627036a888680c15a1657bcd4adb5bf- Surveying the Rust Verification Landscape
vpsd_3f8adf0c1bd46a7e3954ae1676cac6e3ffbf6378eb83a945da8507cb06d67ace- RefinedRust: A Type System for High-Assurance Verification of Rust Programs
vpsd_20e930f8c3672ec7cab1965966fadf35ccc24c1f71c51ca2fbb4587533831b54- Verifying the Rust Standard Library
- confirm identity against the completed arXiv
2606.17374study before reuse
vpsd_0afb0f867a034bfa9a427997d33ac0df1ca615a1beaf3facd21452410c1799f4- A Hybrid Approach to Semi-Automated Rust Verification
Last edited:
🤖 Agave verification sizing and pilot scope
This records the July 2026 public-source sizing study. It is planning evidence, not a security finding, audit, defect hunt, or whole-validator verification estimate
takeaways
- Agave is too large and mixed to price as one verification job
- pinned Rust total: 531,500 code lines
- path-classified production: 450,054 lines
- inline tests make test-free production conservatively 69,606–450,054 lines
- a useful first Agave target is the compute-budget instruction sanitizer
- exact pre-test boundary: 349 production lines
- exact goal: equivalence to an independent left-to-right model for malformed and duplicate errors, defaults, validation, and clamps
- the best related-project pilot is Address Lookup Table state views
- exact pre-test boundary: 119 production lines
- exact goal: immutable and mutable indexed views agree for every 0–256-address well-formed buffer and every
u8index
- both are better first targets than end-to-end consensus or networking
- they are synchronous, bounded, and have explicit observable results
- they avoid distributed liveness, adversarial timing, transport, and cryptographic implementation in the proof boundary
pinned basis and count
- repository: https://github.com/anza-xyz/agave
- default branch:
master - commit:
88345aa0e6c3ef985d59f9e7a4e7350cf1b48b93 - retrieval completed:
2026-07-26T14:09:01Z - counter: Tokei 13.0.0 over paths from
git ls-files -z- code lines exclude blanks and comments
- dependencies, build output, untracked files, and macro expansion are excluded
- Cargo root workspace: 125 members
- repository total: 199 tracked manifests, 197 package manifests
Rust inventory:
- production-classified: 1,060 files, 450,054 code lines
- tests and dedicated test support: 92 files, 70,091 lines
- benchmarks and examples: 59 files, 9,387 lines
- generated or vendor: 4 files, 1,968 lines
- total: 1,215 files, 531,500 lines
- non-Rust Tokei code: 40,047 lines
- configuration and data are included
- a narrower implementation/protocol subset is 16,357 lines
production/test uncertainty
- mixed source files remain in their path category
- 533 production-classified files contain exact
#[cfg(test)] - 546 contain a detected test gate or test attribute
- those mixed files contain 380,448 code lines
- 533 production-classified files contain exact
- the production number is therefore a ceiling
- possible inline-test contamination: 0–380,448 lines
- possible test-free production: 69,606–450,054 lines
- the bound is deliberately loose
- it avoids pretending that a path classifier is an AST-level split
- the per-file ledger supports alternate classification rules
bounded effort tiers
Assumption: experienced Rust verification engineers, a selected verifier that supports the pinned source, and part-time Agave domain review. The ranges exclude fixing findings, proving dependencies, and upstream review delay
- arithmetic fee leaf: 9 production lines, 1–2 engineer-weeks
- proof/harness: 0.5–1 week
- integration/tests: 0.5–1 week
- compute-budget instruction sanitizer: 349 lines, 5–8 weeks
- proof/harness: 3–5 weeks
- integration/tests: 2–3 weeks
- complete compute-budget conversion: 582 lines, 9–15 weeks
- proof/harness: 6–10 weeks
- integration/tests: 3–5 weeks
- compute budget plus cost tracker: 1,440 lines, 18–30 weeks
- proof/harness: 12–20 weeks
- integration/tests: 6–10 weeks
These bands do not extrapolate to consensus, replay, scheduling, transport, or the whole validator
smaller related candidates
- Solana SDK
- pinned total Rust: 48,208 lines
- production-classified: 45,375 lines; root workspace: 112 members
- the project calls itself the “Rust SDK for the Solana blockchain, used by on-chain programs and the Agave validator.”
- broad unsafe-memory, signature/hash, serialization, and feature surfaces make a repository-wide pilot unattractive
- sources: README, security policy
- SPL Token
- pinned total Rust: 15,423 lines
- production-classified: 5,360 lines; tests: 10,063 lines
- the program is compact but has stateful authority/balance transitions and explicit unsafe memory operations
- its policy places
spl-tokenin bounty scope - sources: repository, security policy
- Address Lookup Table
- pinned total Rust: 3,541 lines
- production-classified: 898 lines; generated/vendor: 1,618 lines
- the hand-written program has no observed unsafe, async, network, or cryptographic implementation
- its policy places the on-chain program in bounty scope
- sources: state code, security policy
All maintenance claims are limited to the recorded repository activity. They do not infer company ownership or policy beyond the linked first-party text
recommended proof boundaries
Agave:
- source: the 349-line pre-test compute-budget instruction sanitizer ranges
- dependency contracts: Borsh decoding, program-ID tables, feature membership, and caller-sanitized instruction indexes
- excluded: execution, cost model, bank, consensus, async runtime, cryptography, and networking
- completion: prove model equivalence for every list of length 0–255, every instruction value, all four request variants, and feature configurations; run differential tests through real dependencies
Address Lookup Table:
- source:
program/src/state.rsbefore its test module, 119 code lines - dependency contracts:
bincodeserialization andbytemuckalignment/cast - excluded: lifecycle processor, authority checks, PDA derivation, slot hashes, generated clients, validator integration, consensus, and networking
- completion: prove view/suffix equivalence for every address count, index, and byte value under the contracts; test real dependencies and malformed layouts
durable evidence
The following are local durable links outside the notes repository and are not part of the deployed site:
- concise analysis
- Agave machine summary
- Agave per-file ledger
- pilot source ranges
- pilot range counts
- repository pins
- first-party source record
- consistency result
unknowns
- the verification tool and dependency-model strategy are not selected
- intended semantics need independent domain review; mirroring implementation behavior is not an adequate specification
- tool support for pinned Rust 1.97.1 may change the effort ranges
- repository activity after the recorded commits is outside this study
Last edited:
agent frontier: useful workers, unreliable autonomy 🤖
short version
- inference: modern agents are useful as bounded, supervised, restartable workers
- inference: they are not reliable autonomous employees, researchers, or operators
- the strongest evidence is conditional
- narrow task contract
- stable tools and environment
- strong current model plus a tuned scaffold
- enough inference budget and permission to retry
- cheap, independent verification
- the central frontier is dependable progress under compounding uncertainty, not another best-case demo
evidence labels
- accepted evidence: 21 peer-reviewed papers in the fixed set
- first-party preprint evidence: BrowseComp only
- inference: conclusions drawn across non-comparable studies
- recommendation: proposed research, not a demonstrated capability
- source cards preserve method, result, limitation, uncertainty, short quotes, and local OCR paths
what works now
- accepted evidence: frontier agents complete some well-specified software tasks that take skilled humans hours
- the measured 50% completion horizon reached about 110 human-minutes for o3 on a 170-task software and research suite
- its 80% horizon was four to six times shorter
- time-horizon evidence
- accepted evidence: agents can repair real repositories when the issue, environment, tests, and interface are prepared
- interface design itself changes outcomes
- harder professional and freelance sets sharply reduce the success and economic value recovered
- SWE-agent
- SWE-Bench Pro
- SWE-Lancer
- accepted evidence: agents can execute portions of web, desktop, customer-service, and workplace workflows
- success depends on a controlled environment, available APIs or actions, explicit policy, and recoverable mistakes
- tau-bench
- OSWorld
- WorkArena
- TheAgentCompany
- accepted evidence: agents can produce useful work on bounded ML and research tasks
- they can win some Kaggle medals, outperform expert humans at short R&D budgets, and partially reproduce ML papers
- humans retain an advantage as the horizon grows, and end-to-end paper replication remains weak
- MLE-bench
- RE-Bench
- PaperBench
- accepted evidence: training and memory mechanisms can improve narrow agent behavior
- WebRL improves one open-model web agent through online curriculum reinforcement learning
- memory systems trade retrieval, updating, long-range understanding, and forgetting rather than solving all four
- WebRL
- MemoryAgentBench
- first-party preprint evidence: a specialized deep-research agent solved 51.5% of BrowseComp
- the model was trained for BrowseComp-like tasks
- more test-time compute and selection improved results
- short-answer fact finding is not a normal web-query distribution
- BrowseComp
what remains brittle or weakly evidenced
- reliability collapses before headline capability does
- tau-bench reports strong single-run results but under 25% retail
pass^8for GPT-4o - the time-horizon study finds the 80% horizon four to six times shorter than the 50% horizon
- repeated success is a different capability from occasional success
- tau-bench reports strong single-run results but under 25% retail
- longer work compounds state, judgment, and recovery errors
- UltraHorizon, SWE-Bench Pro, TheAgentCompany, and OSWorld expose failure over many dependent actions
- more tokens or retries can hide fragility while raising cost
- benchmark scores often reward proxies
- unit tests can accept invalid patches
- rubric or model graders can miss scientific defects
- public tasks can leak into training, tool traces, or scaffold tuning
- UTBoost
- ScienceAgentBench
- human comparisons are narrow
- human expertise, familiarization, time limits, tools, and incentives differ across studies
- BrowseComp humans and the specialized model did not operate under equivalent conditions
- PaperBench and RE-Bench are informative within their designs, not labor-market forecasts
- multi-agent results do not establish a general team advantage
- extra agents also add samples, tokens, coordination paths, and correlated errors
- MultiAgentBench
- safety is not a side constraint
- prompt injection, harmful-task compliance, policy violations, and intentional subversion can directly defeat useful autonomy
- existing defenses are benchmark-specific and often trade utility for safety
- AgentDojo
- AgentHarm
- ST-WebAgentBench
- AI Control
important gaps
- high-probability success across repeated runs, not mean success
- recovery after an early wrong assumption, tool error, or environment change
- fresh hidden tasks with independent semantic verification
- causal memory that updates and forgets without importing stale or poisoned state
- budget-matched evidence that separates better coordination from more compute
- joint usefulness and policy compliance under conflicting instructions
- human-agent complementarity measured across hours or days
- comparable cost, latency, intervention, and irreversible-error reporting
- external validity beyond software-heavy, synthetic, or sandboxed task distributions
what is reachable now
- inference: no missing scientific breakthrough blocks better evidence
- the near frontier is experimental discipline
- fresh or mutable tasks
- repeated trials and lower confidence bounds
- fixed model, tool, token, time, and dollar budgets
- counterfactual controls for memory, retries, and team size
- independent artifact checks
- human baselines with matched tools and onboarding
- recommendation: optimize the joint frontier of task value, reliability, cost, and harm
- do not optimize benchmark completion alone
research missions
- measure dependable horizon
- why now
- accepted evidence links human task time to success and shows repeated-run collapse
- time horizons
- tau-bench
- first experiment
- run one frozen agent on fresh tasks binned by human completion time with 20 independent seeds
- fit 50%, 80%, and 95% horizons under one fixed dollar budget
- success metric
- preregistered increase in the lower 95% confidence bound of the 95% horizon without higher cost
- main confounder
- task-family mix and choice of reference humans
- explicit non-claim
- a longer software-task horizon is not general autonomous labor
- make recovery a first-class capability
- why now
- long-horizon benchmarks expose compounding failures but usually score only final success
- UltraHorizon
- SWE-Bench Pro
- first experiment
- inject matched tool failures, stale observations, and plausible wrong hypotheses
- compare baseline, checkpoint, explicit replan, and rollback agents under equal budgets
- success metric
- conditional recovery probability and verified value per dollar after injection
- main confounder
- recovery methods may simply spend more inference
- explicit non-claim
- recovery from scripted faults does not establish open-world robustness
- close the proxy-to-truth gap
- why now
- coding and science benchmarks show that tests and graders can accept defective artifacts
- UTBoost
- PaperBench
- ScienceAgentBench
- first experiment
- create fresh tasks with hidden semantic tests and an independent expert audit
- forbid the producer agent from querying the final verifier
- success metric
- lower false-accept rate at unchanged verified task success and audit cost
- main confounder
- the verifier may encode the same assumptions as the task author
- explicit non-claim
- passing hidden checks does not prove a generally correct solution
- test memory causally across sessions
- why now
- current systems differ sharply across retrieval, learning, long-range integration, and forgetting
- MemoryAgentBench
- WebRL
- first experiment
- compare real memory with shuffled, stale, poisoned, no-memory, and equal-token full-context controls
- success metric
- future-task gain per stored byte with bounded stale-fact and poisoned-retrieval rates
- main confounder
- extra context and extra inference masquerade as memory quality
- explicit non-claim
- better benchmark memory is not human-like continual learning
- optimize task success and policy compliance together
- why now
- tool agents fail domain rules, and web agents remain vulnerable to malicious or conflicting instructions
- tau-bench
- AgentDojo
- ST-WebAgentBench
- first experiment
- cross product fresh user tasks, unseen policy clauses, and adaptive prompt injections
- use diverse simulators plus a blinded human audit subset
- success metric
- worst-group joint completion-and-compliance
pass^10at a fixed intervention budget
- worst-group joint completion-and-compliance
- main confounder
- simulator behavior may define the apparent safety result
- explicit non-claim
- benchmark compliance does not establish safe deployment
- find the human-agent R&D crossover
- why now
- agents can win short-budget R&D comparisons while humans overtake them at longer budgets
- RE-Bench
- PaperBench
- MLE-bench
- first experiment
- randomize experts to human-only, agent-only, and human-with-agent conditions at 1, 4, and 16 hours
- success metric
- independently scored quality-time-cost frontier and human uplift over human-only work
- main confounder
- participant selection, agent familiarity, and task-specific expertise
- explicit non-claim
- winning a bounded R&D task is not autonomous scientific discovery
- isolate real coordination gains
- why now
- multi-agent systems are measurable, but more agents also mean more compute and more failure channels
- MultiAgentBench
- AI Control
- first experiment
- compare one agent, independent best-of-n, communicating peers, and a trusted-monitor team under equal token and tool budgets
- randomize role assignment and communication topology
- success metric
- verified performance gain beyond best-of-n with lower correlated-error and undetected-subversion rates
- main confounder
- architecture-specific prompting can favor one topology
- explicit non-claim
- a gain in simulated teams is not evidence of emergent collective intelligence
bottom line
- accepted evidence supports useful bounded agency, not dependable general autonomy
- first-party preprint evidence supports deep browsing under specialization and high test-time compute, not general web competence
- inference: reliability, verification, recovery, and control are capability research
- recommendation: pursue the seven missions above before scaling task horizon or permissions
- residual uncertainty
- search and omission limits are explicit in the search log
- every absolute result may move with model, scaffold, budget, and benchmark version
Last edited:
Browser Agent
- WebVoyager: Building an End-to-End Web Agent with Large Multimodal Models, Hongliang He, Wenlin Yao, Kaixin Ma, Wenhao Yu, Yong Dai, Hongming Zhang, Zhenzhong Lan, Dong Yu, ACL, 2024
- vision-first end-to-end web agent on real websites
- useful mainly bc benchmark uses real rendered sites, not static snapshots
- good historical starting point; later papers usually have sharper systems ideas
- Towards Specialized Web Agents Using Production-Scale Workflow Data, Junhong Shen, Atishay Jain, Zedian Xiao, Ishan Amlekar, Mouad Hadji, Aaron Podolny, Ameet Talwalkar, arXiv, 2024
- main claim: real workflow data + finetuning matter more than prompt engineering
- paper reports specialized open models can beat proprietary baselines
- good paper if you care about data + training, not just inference-time scaffolding
- AgentOccam: A Simple Yet Strong Baseline for LLM-Based Web Agents, Ke Yang, Yao Liu, Sapana Chaudhary, Rasool Fakoor, Pratik Chaudhari, George Karypis, Huzefa Rangwala, ICLR, 2025
- simple but important: align action space + observation space to model priors
- remove low-value actions, compress page, use planning-tree memory
- nice “simplicity wins” baseline
- Navigating the Infinite Dynamic Web Space: Effective In-Context Exploration via Cognitive Multi-Agent Collaboration, Guozhao Mo, Yanjiang Liu, Yafei Shi, Jiawei Chen, Yang Li, Yaojie Lu, Hongyu Lin, Ben He, Le Sun, Bo Zheng, Xianpei Han, EACL, 2026
- split “history”: environment observation vs action trajectory
- 2 separate agent
- backtrack using “go back” or “go to”
- to avoid getting stuck/trapped
- argue state backtrack often impossible bc irreversible actions
- by citing “Is your llm secretly a world model of the internet? model-based planning for web agents”
- achieve better performance w/ open source than previous methods + proprietary LLMs
- contain good list of prior web agents
- split “history”: environment observation vs action trajectory
- WebRL: Training LLM Web Agents via Self-Evolving Online Curriculum Reinforcement Learning, Zehan Qi, Xiao Liu, Iat Long Iong, Hanyu Lai, Xueqiao Sun, Jiadai Sun, Xinyue Yang, Yu Yang, Shuntian Yao, Wei Xu, Jie Tang, Yuxiao Dong, ICLR, 2025
- online curriculum RL for open web agents
- tackles task scarcity, sparse rewards, and unstable online training
- paper reports a large jump on WebArena-Lite; read if you care about training agents
- WebCoach: Self-Evolving Web Agents with Cross-Session Memory Guidance, Genglin Liu, Shijie Geng, Sha Li, Hejie Cui, Sarah Zhang, Xin Liu, Tianyi Liu, arXiv, 2025
- adds cross-session episodic memory w/o retraining
- condenser + memory store + runtime coach retrieve past lessons
- good “memory helps” paper; more practical than foundational
- Building Browser Agents: Architecture, Security, and Practical Solutions, Aram Vardanyan, arXiv, 2025
- strongest point is architectural / security perspective, not benchmark novelty
- paper argues prompt injection makes open-ended browser autonomy unsafe in production
- pro specialized constrained tools, anti general browser-first agent
- BrowserAgent: Building Web Agents with Human-Inspired Web Browsing Actions, Tao Yu, Zhengbo Zhang, Zhiheng Lyu, Junhao Gong, Hongzhu Yi, Xinming Wang, Yuxuan Zhou, Jiabing Yang, Ping Nie, Yan Huang, Wenhu Chen, arXiv, 2025
- pushes direct browser interaction instead of converting web to static text
- staged finetuning + explicit memory
- seems more useful for browse-for-information / open QA than transactional web tasks
- Prune4Web: DOM Tree Pruning Programming for Web Agent, Jiayuan Zhang, Kaiquan Chen, Zhihao Lu, Enshen Zhou, Qian Yu, Jing Zhang, AAAI, 2026
- nice low-level idea: use generated program to prune DOM before grounding
- paper reports a large grounding boost by shrinking candidate elements aggressively
- read if you care about DOM/action grounding details
- Investigating the Impact of Dark Patterns on LLM-Based Web Agents, Devin Ersoy, Brandon Lee, Ananth Shreekumar, Arjun Arunasalam, Muhammad Ibrahim, Antonio Bianchi, Z. Berkay Celik, IEEE S&P, 2026
- paper positions itself as a first systematic dark-pattern eval for web agents
- paper reports stronger agents can be more vulnerable bc they bulldoze through UI traps
- paper reports vision can hurt and prompt countermeasures help only a bit
- From Super-Apps to Agent Economies: Delegated AI Requires Transaction Closure, Chaoyue He, Xin Zhou, Di Wang, Hong Xu, Wei Liu, Chunyan Miao, preprints.org, 2026
- position paper, not core web-agent algorithm paper
- main idea: judge agent systems by transaction closure, not just task completion
- useful for governance / ecosystem framing
- WebOperator: Action-Aware Tree Search for Autonomous Agents in Web Environment, Mahir Labib Dihan, Tanzima Hashem, Mohammed Eunus Ali, Md Rizwan Parvez, arXiv, 2026
- ICLR 2026 Rejected
- “most of the individual components have been explored in prior work”
- still useful: explicit safe/speculative backtracking is the key idea
- best-first tree search ranks actions by reward + safety, then filters / merges actions
- paper claims strong WebArena results; read mainly as a tree-search integration paper
- read after
Branch-and-Browse, not before the API / safety papers
- ICLR 2026 Rejected
- LongHorizonUI: A Unified Framework for Robust long-horizon Task Automation of GUI Agent, Bin Kang, Shaoguo Wen, Yifei Bi, Shunlong Wu, Xinbin Yuan, Rui Shao, Junle Wang, Zhuotao Tian, ICLR, 2026
- long-horizon GUI agent paper more than web-specific paper
- benchmark + reflection / validation machinery for >15-step tasks
- useful if your concern is horizon / robustness, not web semantics
Industry
- AutoWebGLM: A Large Language Model-based Web Navigating Agent, Hanyu Lai, Xiao Liu, Iat Long Iong, Shuntian Yao, Yuxuan Chen, Pengbo Shen, Hao Yu, Hanchen Zhang, Xiaohan Zhang, Yuxiao Dong, Jie Tang, KDD, 2024
- early strong open web-agent baseline
- bilingual dataset + html pruning + staged training
- mostly useful as history / baseline reference now
- The Adoption and Usage of AI Agents: Early Evidence from Perplexity, Jeremy Yang, Noah Yonack, Kate Zyskowski, Denis Yarats, Johnny Ho, Jerry Ma, arXiv, 2025
- field study of real agent usage, not an algorithm paper
- useful for “what people actually use agents for”
- read only if product / adoption angle matters
Internal API
- Beyond Browsing: API-Based Web Agents, Yueqi Song, Frank F. Xu, Shuyan Zhou, Graham Neubig, ACL Findings, 2025
- important framing paper: APIs can be better machine interface than browsers
- paper reports api-only and hybrid agents beat browser-only on WebArena
- read early if you care about practical systems
- Internal APIs Are All You Need: Shadow APIs, Shared Discovery, and the Case Against Browser-First Agent Architectures, Lewis Tham, Nicholas Mac Gregor Garcia, Jungpil Hahn, arXiv, 2026
- clear systems argument against browser-first agents
- core idea is shared discovery of first-party / shadow APIs so each agent does less rediscovery work
- provocative but high-value paper
- APISENSOR: Robust Discovery of Web API from Runtime Traffic Logs, Yanjing Yang, Chenxing Zhong, Ke Han, Zeru Cheng, Jinwei Xu, Xin Zhou, He Zhang, Bohan Liu, arXiv, 2026
- runtime traffic method for reconstructing undocumented APIs
- useful enabling paper if you buy the internal-api direction
- more reverse-engineering paper than agent paper
Branching
- Branch-and-Browse: Efficient and Controllable Web Exploration with Tree-Structured Reasoning and Action Memory, Shiqi He, Yue Cui, Xinyu Ma, Yaliang Li, Bolin Ding, Mosharaf Chowdhury, arXiv, 2025
- tree-structured reasoning + page action memory + replay
- better companion to WebOperator than most earlier branching work
- read to compare memory-guided branching vs safe-backtracking branching
Agents in general
- Affordance Representation and Recognition for Autonomous Agents, Habtom Kahsay Gidey, Niklas Huber, Alexander Lenz, Alois Knoll, ECAI, 2025
- conceptual paper on world-model construction from structured data
- two useful abstractions: DOM transduction + affordance recognition
- light on empirical results; mainly good for framing
- Intelligent AI Delegation, Nenad Tomašev, Matija Franklin, Simon Osindero, arXiv, 2026
- delegation is framed as authority + responsibility + trust, not just decomposition
- good conceptual / safety framing for multi-agent systems
- not web-agent-specific enough to prioritize early
- Repo2Run: Automated Building Executable Environment for Code Repository at Scale, Ruida Hu, Chao Peng, XinchenWang, Junjielong Xu, Cuiyun Gao, NeurIPS, 2025
- not really a browser-agent paper
- good agent-infra paper on building executable repo environments automatically
- read only if you care about code / environment agents
🤖 Agent-added related work deepening (2026-05-24): browser-agent infrastructure and benchmarks
Fact: browser-agent work has split into three layers: benchmark environments, agent scaffolds, and safer machine interfaces. BrowserGym is now the most useful systems anchor because it unifies previously fragmented benchmarks. Its README says it includes “MiniWoB”, “WebArena”, “WebArenaVerified”, “VisualWebArena”, “WorkArena”, “AssistantBench”, “WebLINX”, “OpenApps”, and “TimeWarp” (https://github.com/ServiceNow/BrowserGym). The BrowserGym paper says the system uses Chromium and Playwright through a Gymnasium API (https://ar5iv.labs.arxiv.org/html/2412.05467), while the README warns it is “not meant to be a consumer product”; that matters because it is a research harness, not a production safety design.
Benchmarks/projects that should shape any browser-agent direction:
- WebArena: canonical self-hosted realistic web benchmark (https://github.com/web-arena-x/webarena); its repo now points researchers toward BrowserGym/AgentLab for improved parallel experiments, unified benchmark integration, leaderboard reporting, and edge-case handling.
- VisualWebArena: 910 visually grounded tasks over Classifieds, Shopping, and Reddit (https://aclanthology.org/2024.acl-long.50.pdf). The paper reports best VLM success at 16.4% vs human 88.7%, which is a reminder that screenshots are not a solved grounding layer.
- WorkArena / WorkArena++: enterprise ServiceNow workflows. The ICML paper says it evaluates tasks spanning “typical daily work of knowledge workers” (https://proceedings.mlr.press/v235/drouin24a.html) and exposes a large gap to full automation. This is closer to useful automation than toy webpage clicking.
- BrowserGym + AgentLab: the practical evaluation substrate for comparing observation choices: DOM, accessibility tree, screenshots, coordinates, high-level actions, Python actions, and chat.
- OpenEnv / TRL BrowserGym examples (https://github.com/meta-pytorch/OpenEnv, https://github.com/huggingface/trl/blob/main/examples/scripts/openenv/browsergym.py): useful implementation precedent for wrapping BrowserGym as an RL environment, including text-only accessibility observations and multimodal screenshot + accessibility observations.
- Safety/infrastructure papers:
Building Browser Agents,DoomArena(https://github.com/ServiceNow/DoomArena), dark pattern evaluation, and prompt-injection work imply that open-ended browser control should be wrapped by policy, provenance, and irreversible-action guards. - API-first line:
Beyond Browsing,Internal APIs Are All You Need, andAPISENSORargue that browser UI is often a poor machine interface. The systems opportunity is a hybrid agent that discovers stable first-party APIs from runtime traces, audits their provenance, and falls back to UI only when necessary.
Inference: another WebArena prompt scaffold is unlikely to be deep enough. A stronger systems direction is a browser/API instrumentation layer that records rendered evidence, DOM/accessibility provenance, network/API consequences, and transaction state. The agent should know when not to click: irreversible actions, prompt-injected pages, dark patterns, policy-sensitive flows, and API-vs-UI tradeoffs are the core systems problems.
Concrete evaluation plan:
- Use BrowserGym for reproducible baselines across MiniWoB, WebArena, VisualWebArena, and WorkArena, then add a small transaction-closure suite with explicit irreversible-action and audit requirements.
- Measure task success plus action provenance completeness, unsafe-action blocking, replayability, and UI-vs-API fallback decisions.
- Compare browser-only, API-only, and hybrid agents. The important ablation is not just success rate; it is whether the hybrid path reduces rediscovery, lowers unsafe clicks, and makes outcomes auditable.
Paper repository status: existing PDFs/notes include several browser-agent papers such as AgentOccam, BrowserAgent, Branch-and-Browse, Beyond Browsing, APISENSOR, and internal-API work. Missing high-value PDFs for BrowserGym, WorkArena, and VisualWebArena could not be downloaded by this agent because the paper repository ACL denies writes to the agent account.
🤖 Agent-added broad directions (2026-06-07): beyond receipts-as-infra
- 🤖 Causal receipts: keep the flight-recorder idea, but frame it as causal semantics for delegated action. The interesting question is which rendered evidence, API response, source label, or authority check changes whether an action is safe and complete.
- 🤖 L7 transaction contracts: treat browser clicks and API calls as typestate transitions with preconditions, side effects, idempotence, rollback, commit points, and authority. This makes hybrid UI/API work more than reverse engineering.
- 🤖 Semantic efficiency: prune DOM/resources/scripts only when the removed state cannot affect the task postcondition. This transfers program slicing and dependency analysis into web-agent efficiency.
- 🤖 Taint-aware interpretability: label observations by source class (user/site/ad/hidden/private/archive/API) and audit whether untrusted sources influenced privileged sinks. This connects prompt-injection defense to interpretable trajectory analysis.
🤖 See literature_directions.md for the question-first fields: surprising question, intuition tested, convincing evidence, literature gap, minimal instrument, and pitch.
Last edited:
Execution
(code and discussion are taken private; please ask Steven for repo access)
- see also
arguments.mdandliterature.md - development:
development.md - web search and crawling:
web_search.md
Overall steps
- improve ground truth & get robust classifier
- ~100 human/AI websites baseline and still do well
- check if doing well
- apply to 10,000 websites in the wild
- apply broadly to websites in the wild?
- ways to discover them
- determine why they do this (money/misinformation)?
By order
want:
- how much need to crawl
- compute CDF of per-subdomain filter pass portions
- estimate expectation of crawl-to-sample ratio
- sampling sensitivity in the wild
- confirm Dolma filter works well against non-prose false positives on Common Crawl data
- apply Dolma filter
- confirm Dolma filter works well against non-prose false positives on Common Crawl data
- cluster pages into two Gaussians per site for bimodal Binoculars score
- idea: sample unsure, crawl more
- inspect bimodal sites manually
- inspect near-border sites
- inspect filtered-out sites to confirm they are non-AI pages
- expand baseline dataset per reviewer feedback
- collect additional true positive and true negative scenarios
- broaden beyond Wix-style generators
- measure accuracy on larger baseline with pre-GPT sites and Playwright-generated AI pages
- characterize known generated versus self-generated websites
- historical trend shift from Common Crawl windows
- monitor search-result trends
- schedule periodic query sampling
- run time series analysis on website changes
- measure impact of “humanizer” tools on Binoculars scores
- what are those website w/ many “positive” page
- finish review UI for manual inspection
- content farm w/ many ad (
ad_extraction.md)- infer search queries targeted by content farms
- inspect outgoing links for clusters of AI-dominant content
- infer search queries targeted by content farms
- content farm selling product
- identify scam seller
perhaps use blacklist used by RefinedWebfew matches
- detect affiliate links
- identify scam seller
- false positive: forum/support
- find zero-ad zero-affiliate link site and study it
- fake e-commerce site with AI-generated product descriptions?
- clustering
- check existing clustering approaches
- find comment about similar AI sites
- keywords: DOM structure, JS frameworks, structural similarity, technology stack, template identification, website fingerprinting, layout similarity, homology detection
- most literature targets traffic-based attacks
- analyze Binoculars score versus publication timing
- study burst versus gradual ramps of AI content
- examine whether AI enables faster publication speed
- hard to quantify publication speed without sitemap coverage
- validate date extraction reliability with
htmldate - inspect sites where many pages share the same date stamp
- no correlation observed between score and date so far
- ❗️ derive sitemap-based publication speed signal
- distinguish sites appearing across multiple search results
- inspect site source code for tooling clues
- identify website technologies via Wappalyzergo and correlate findings
- measure similarity among pages within the same site
- investigate middle-ground websites between obvious AI and human content
- investigate get-rich-quick scheme hypothesis
- attempted archiving Reddit posts but originals missing; have related passive income post
- continue evidence gathering
- search Google/Bing/Brave/Perplexity/ChatGPT/ChatNoir
- fetch deeper than 20 results when queries yield many AI hits
nice-to-have:
- reduce text extraction overhead (CPU-bound)
- fix browser controller memory leak
- verify whether modem.tools is generated
- catalog ways to use LLMs to write content
- study HTML and JS feature dependencies
- ask Yacin Alhamwy & Adrian Kunz to crawl dependency for sites
- crawling improvements
- click cookie banner
- SSO sign in
- training data memorization risks
- segment non-single-text pages
- explore non-website detection applications
- Reddit LLM user detection
- OpenReview detection similar to ICML study
- student cheating detection
- Amazon fake reviewer detection
- fake news, resume, and bot detection scenarios
- build SearXNG plugin to filter AI-generated sites
- posted on r/Searx; received upvotes but no responses
done:
- preliminary: run Binoculars over Common Crawl; see if result make sense (
preliminary_binoculars_eval.md) edit: … and WikiHow search result - crawl top 20 results/reference
- extract body text
DOM Distiller Reading Mode- Trafilatura
- Binoculars
- speed enhancement for large scale
Meta question
- decide which web subsets to sample
- study domain registration recency
- evaluate RDAP creation-date reliability (thanks Xiao & Wes)
- DNS registration records proved unreliable
- review WhoisXML API data availability and pricing
- study domain registration recency
- analyze why existing page reviews yield few insights
- examine ad network bottlenecks for AI sites
- focus on Google Ads limiting revenue for LLM ad farms while profiting off reduced search quality
- evaluate how hard it is to create AI websites that rank high
- quantify SEO effort versus generation effort versus ranking
- gather evidence that adversarial perplexity inflation hurts quality
- assess economic viability versus human writing
- consider signing up to work for a content farm
- evaluate harms from AI sites
- quantify misinformation impact
- measure scam prevalence
- test search or RAG quality improvements after filtering
- assess degradation of search or LLM results
- assess whether text detection alone suffices
- examine generated imagery on detected sites such as https://burstofstyle.com/messi-blonde-hair/
- survey openly available detectors of AI-generated images
- inspect Bing sites in the ~2% LLM cohort with >200 images
- count video-heavy pages and manually inspect representative examples
- design deterministic confirmation steps after detector pre-filtering
Reading backlog
- review phishing detection papers
- review genre detection papers
- review AI text detection papers
- review EU AI disclosure compliance research
- review synthetic data impact on LLM performance https://sichanghe.github.io/notes/research/web_user_facing.html#search-engine-optimization-seo.
Cancelled
- filtering
- try other ML model on Common Crawl derived labels
- gather more ground truth
- revisit decision-tree-based filter tuning to replace heuristics
- try other ML model on Common Crawl derived labels
Last edited:
Arguments
(citation in Quarto format w/ reference.bib for future writing)
Significance
- The Web is the largest public corpus of knowledge for human consumption and machine learning training
- AI-generated text usually plagiarize prior content, often hallucinate misinformation, so it pollutes contents on the Web.
- Spammy content affects search engine user experience by disrupting search engine ranking
- Users want accountable, reliable, and informative content, but AI-generated contents are often not so.
- Arguments from Perplexity.ai: LLMs may have stale information, and do not cite their sources for verification purposes.
- Generated contents in training data may harm LLM performance
- Generated contents in RAG data may harm LLM search performance
- Laws like the EU AI Act mandate disclosure of AI-generated content, but many AI content websites do not comply and thus may be illegal.
- Hard to do general filtering as opposed to filtering only 1 site
- Misinformation reference chain can possibly form from AI-generated misinformation
Crawling
- trying to see webpage users see although scraper see different results, search result differ based on location
- main body text extraction is difficult to do well, but we do best-effort w/ SoTA method
- Trafilatura [@barbaresi2021trafilatura] is SoTA [@bevendorff2023empirical; @reeve2024evaluation]
- balancing network, CPU, and GPU load during crawling could be a contribution (Shaoyu)
Generated text detection
- Binoculars score reflect information density (substance)
- is calibrated perplexity
- generated text is bad because provide less actual information
- detect both generated and low-quality content
- statistical probability may give more info than binary classification using fixed threshold
- detection of individual webpage may yield error, but aggregate analysis per website should increase accuracy
- real-world data contain noise, so detectors must tolerate imperfect labels
- emphasize we already use SoTA LLM detection
- although NLP benchmarks evaluated individual detectors on texts, they do not reflect the results from our aggregate website analysis, so we need to run our pipeline over baseline websites
- when multiple detectors exhibit the same trend, the trend is evident
Content farm
- moral issue: some site like GeeksforGeeks look like content farm but may be useful; what is our stance?
Generalizing to non-article webpages
Text-based LLM detection cannot generalize to all webpages. Types of webpages from the viewpoint of such detection (enumeration based on Deepseek):
Single or cohesive narrative/text blocks. Blog Posts, News Articles, Research Publications, Tutorials/Guides, E-books/Whitepapers, Podcast Transcripts, Recipes, Interactive Stories, Archived Content.
👌 These can be treated as a single block of text and directly classified.
Multi-Section Text Pages. Homepage, FAQ, Glossary, Forum (boards/posts), Directory, Wiki/Knowledge Base, Portfolio, Testimonials, Case Studies, Team Directory, Event Listings, Press Releases, User Profiles, Social Feeds, Q&A Platforms.
😰 These, when treated as a single block of text, causes discontinuity in the text and degrade text detection performance. Segmenting them and classifying each segment separately may work.
Boilerplate/Legal/Standardized Content. Privacy Policy, Terms of Service, Disclaimer, Product Pages (descriptions), Download Pages, Account Settings, Pricing Pages, Services Pages, Career Listings, API Documentation, Client Dashboards, Affiliate Pages.
🤷 These have standardized forms, such that humans would write them in a similar way that LLMs do, so detection makes little sense.
Media/Non-Text Pages. Image Galleries, Video Pages, Audio Streams, 3D/Virtual Tours.
❌ Text detection is not applicable to these.
Interactive/Functional Interfaces. Dashboards, Quizzes/Surveys, Calendars, Booking/Checkout Pages, Login/Registration Forms, Search Results, Advanced Filters, Live Chat, Calculators/Converters, Games, AR/VR Interfaces. Stock Tickers, Weather Forecasts, Order Tracking, Live Streams/Webinars, Auction/Bidding Pages, Real Estate Listings, Job Boards. Comparison Tools, Financial Calculators, Medical/Appointment Systems, Code Playgrounds, Maps.
❌ These are not really text-centric content, so text detection is not applicable.
Big questions
- How accurate are our detection methods?
- How prevalent in search results vs broader web?
- Why are created, what goals?
- What harms, e.g., misinformation, scams, degraded search or LLM performance?
- Produced in batches by a few entities? Tooling used?
- Wappalyzer for technology attribution
- Topics emphasized?
- Should search engines intervene?
Directions
- spam industry bottleneck: Google Ads for LLM ad farms?
- Google profiting from reduced search quality
- explored SearXNG deployment concept; subreddit post drew only upvotes
Last edited:
Literature
Website
Content farm & scam
- Web’s ‘Content Farms’ Grow Audiences For Ads, Zoe Chace, NPR, 2011
- it’s an industry to churn out low-quality content and do Google SEO
- hire human at low cost
- Google Sets Sights On Content Farms In 2011, Matt McGee, Search Engine Land, 2011
- CEO of Demand Media, a content farm, not worried about Google warning against content farm bc “not going to hurt ad partners”
- An examination of content farms in web search using crowdsourcing An examination of content farms in web search using crowdsourcing, Richard McCreadie, Craig Macdonald, Iadh Ounis, Jim Giles, Ferris Jabr, CIKM, 2012
- Mechanical Turk to label search result
- found content farm decrease
- Polls, clickbait, and commemorative 2 bills: problematic political advertising on news and media websites around the 2020 U.S. elections, Eric Zeng, Miranda Wei, Theo Gregersen, Tadayoshi Kohno, Franziska Roesner, IMC, 2021 - content farm served political ad - extract ad w/ EasyList CSS selector - 💡 can use uBlock Origin logger - qualitative coding & BERT classifier to analyze - Analyzing the (In)Accessibility of Online Advertisements, Christina Yeung, Tadayoshi Kohno, Franziska Roesner, IMC, 2024 - use UWCSESecurityLab adscraper to extract ad, which in turn use EasyList - Plagiarism-Bot? How Low-Quality Websites Are Using AI to Deceptively Rewrite Content from Mainstream News Outlets, NewsGuard, 2023 - detection: seek "error message" like "as an AI", then human review - plagiarize from legit site like New York Times - money from Google Ads, from top brand - Scam Sites at Scale: LLMs Fueling a GenAI Criminal Revolution, Netcraft, 2024 - phishing website/ fake shop/ email use LLM - > identify thousands of websites each week using AI-generated content - example w/ LLM "error message"/ beginning sentence of response - "Certainly, here's/ here are …:" - "As of my last knownledge update…" - Funding the Next Generation of Content Farms: Some of the World’s Largest Blue Chip Brands Unintentionally Support the Spread of Unreliable AI-Generated News Websites, NewsGuard, 2023 - NewsGuard found 141 brand have ad on AI-driven site - unreliable AI-generated news website (UAIN) - NewsGuard want to charge university \$3,750 for each paper - ⇒ predator org w/ fake data? - mainly use Google Ads - publish large volume, sometimes 1000 per day - Junk websites filled with AI-generated text are pulling in money from programmatic ads, MIT Technology Review, 2023 - number for ad revenue - People Are Spinning Up Low-Effort Content Farms Using AI, Futurism, 2023 - content farm low quality, misinformation, profit from Google Ads - 💡 maybe we report them to Google bc against their ad policy - Tracking AI-enabled Misinformation: 1,254 ‘Unreliable AI-Generated News’ Websites (and Counting), Plus the Top False Narratives Generated by Artificial Intelligence Tools, NewsGuard, 2025 - AI ‘News’ Content Farms Are Easy to Make and Hard to Detect: A Case Study in Italian, Giovanni Puccetti, Anna Rogers, Chiara Alzetta, Felice Dell’Orletta, Andrea Esuli, ACL, 2024 - easy to fine-tune free model into Italian content farm model (CFM) - literature review on NewsGuard report & detector - human&DetectGPT low accuracy—infeasible to detect - fine-tuning of detector help a lot, but need to know base LLM used - Google Search Changes Are Killing Websites in an Age of AI Spam, Imad Khan, CNET, 2024 - Google search updates hurt smaller websites - benefit big authoritative site that plagiarize & do AI spam - AI Is Poisoning Reddit to Promote Products and Game Google With 'Parasite SEO', Jason Koebler, 404 Media, 2024 - ReplyGuy, a service, claim to use AI to reply to Twitter/Reddit post with product promotion ### Search Engine Optimization (SEO) See <https://sichanghe.github.io/notes/research/web_user_facing.html#search-engine-optimization-seo>. ### Website clustering and attribution - limited top-venue work on website clustering - Detecting Malware and Spam Web Sites by Mining their Structural Features, WWW, 2015 (spam parking domain look-and-feel) - scam and phishing detection literature partial coverage - technology stack analysis tools rely on regex, e.g., Wappalyzergo ### Website clustering - Identification of Web Spam through Clustering of Website Structures, Filippo Geraci, ACM WWW, 2015 ### Website ownership - Domain and Website Attribution beyond WHOIS, Silvia Sebastián, Raluca-Georgia Diugan, Juan Caballero, Iskander Sanchez-Rola, Leyla Bilge, ACSAC, 2023 - use WHOIS, passive DNS, TLS certificate, website content - website content: copyright string, metadata, policy, terms of service (TOS), contact, security.txt - F1 score 0.94 ### Web genre classification this is what detection of homepage, etc. is called - Web page genre classification, Guangyu Chen, Ben Choi, SAC, 2008 - genre: homepage, search, resource, shop, forum - ❌ manual feature design & threshold tuning w/ regex/ HTML tag - unlikely to generalize especially today - Web Genre Classification via Hierarchical Multi-label Classification, Gjorgji Madjarov, Vedrana Vidulin, Ivica Dimitrovski, Dragi Kocev, Springer IDEAL, 2015 - fancy decision tree on web page features - 2491 features from Multi-Label Approaches to Web Genre Identification, Vedrana Vidulin, Mitja Luštrek, Matjaž Gams, JLCL, 2009 - keyword in URL - specific word rate, punctuation, HTML tag, out-domain hyperlink - part of speech, sentence type - ❌ bind and brute force, bad <40% accuracy - ❌ bad 28% accuracy - Enhancing the identification of web genres by combining internal and external structures, Chaker Jebari, Elsevier Pattern Recognition Letters, 2021 - ❌ use word (term) in heading + link; combine multiple classifier - dataset: KI04, SANTINIS - \>0.85 accuracy w/ combined classifier - Web Page Classification using LLMs for Crawling Support, Yuichi Sasazawa, Yasuhiro Sogawa, Hitachi Ltd., 2025 - GPT-4o 0.89 F1 score when classify homepage vs content on extracted title + body ## Training data ### Generative AI (GenAI) See <https://sichanghe.github.io/notes/research/gen_ai.html>. ### Training data curation - CCNet: Extracting High Quality Monolingual Datasets from Web Crawl Data, Guillaume Wenzek, Marie-Anne Lachaux, Alexis Conneau, Vishrav Chaudhary, Francisco Guzmán, Armand Joulin, Edouard Grave, LREC, 2020 - Trafilatura: A Web Scraping Library and Command-Line Tool for Text Discovery and Extraction, Adrien Barbaresi, ACL 2021 - An Empirical Comparison of Web Content Extraction Algorithms, Janek Bevendorff, Sanket Gupta, Johannes Kiesel, Benno Stein, SIGIR, 2023 - The RefinedWeb Dataset for Falcon LLM: Outperforming Curated Corpora with Web Data, and Web Data Only, Guilherme Penedo, Quentin Malartic, Daniel Hesslow, Ruxandra Cojocaru, Alessandro Cappelli, Hamza Alobeidli, Baptiste Pannier, Ebtesam Almazrouei, Julien Launay, arXiv, 2023 - heuristic-based URL filtering; no ML filtering to avoid bias - 4.6M site list 💡 useful for spotting spam/scam, etc. - use Trafilatura for main content extraction - Quality at a glance: An audit of web-crawled multilingual datasets, Julia Kreutzer, Isaac Caswell, Lisa Wang, Ahsan Wahab, Daan van Esch, Nasanbayar Ulzii-Orshikh, Allahsera Tapo, Nishant Subramani, Artem Sokolov, Claytone Sikasote, et al., ACL, 2022 - Common Crawl include large portion of machine spam & porn - Dolma: an Open Corpus of Three Trillion Tokens for Language Model Pretraining Research, Luca Soldaini, Rodney Kinney, Akshita Bhagia, Dustin Schwenk, et al., Kyle Lo, arXiv, 2024 - for Dolma 1.6 - C4 NoPunc + Gopher All for quality filtering ### Synthetic data - STaR: Bootstrapping Reasoning With Reasoning, Eric Zelikman, Yuhuai Wu, Jesse Mu, Noah D. Goodman, NeurIPS, 2022 - Phi-3 Technical Report: A Highly Capable Language Model Locally on Your Phone, Marah Abdin, Jyoti Aneja, Hany Awadalla, Ahmed Awadallah, Ammar Ahmad Awan, et al., Microsoft, 2024 - Rephrasing the Web: A Recipe for Compute and Data-Efficient Language Modeling, Pratyush Maini, Skyler Seto, He Bai, David Grangier, Yizhe Zhang, Navdeep Jaitly, ACL, 2024 (below generated) ## Common Crawl processing at terabyte scale - CCNet: Extracting High Quality Monolingual Datasets from Web Crawl Data - Quote: “deduplicates documents and identifies their language.” arxiv - Quote: “augment this pipeline with a filtering step to select documents that are close to high quality corpora like Wikipedia.” arxiv - cc_net code - Quote: “The full mining pipeline is divided in 3 steps: hashes downloads one Common-Crawl snapshot, and compute hashes for each paragraph.” github - OSCAR project website - TODO: Extraction/dedup/filter details are not present in the provided source. - Ungoliant (OSCAR-related pipeline) summary - TODO: Only a brief description was available in the provided source; extraction/dedup/filter details not documented there. - Dolma: an Open Corpus of Three Trillion Tokens - Quote: “transforms the output of CCNet through URL and document-level deduplication, then quality and content filtering.” aclanthology - Quote: “filtering at a rate of 122 CPU hours per TB.” aclanthology - RedPajama-Data-v2 blog - Quote: “pass each CommonCrawl snapshot through the CCNet pipeline.” together - Quote: “deduplicated … using a Bloom filter,” with “reduction … roughly 40%.” together - Common Crawl FAQ - Quote: “stored on Amazon’s S3 service,” enabling “Map-Reduce processing in EC2.” commoncrawl - TODO: C4/mC4 extraction, dedup, and filtering details were not present in the provided sources. ## AWS cost/throughput for batch processing - Comparing Burstable and On-Demand AWS EC2 Instances using NAS Parallel Benchmarks - Quote: “Burstable instances… provide a baseline level of CPU utilization with the ability to burst… governed by CPU credits.” sol.sbc.org - Quote: “a CPU-bound workload can run similarly in all instances.” sol.sbc.org - Exploiting Hardware Heterogeneity within the Same Instance Type of Amazon EC2 - TODO: No verbatim quote provided in the search results. - Choosing the Right EC2 Instance Type for your Application - Quote: “If you are running any CPU-bound scale-out applications, you should look at compute-optimized instances first.” aws.amazon - Diving Deep into EC2 Spot Instance Cost and Operational Practices - Quote: “Spot Instances… are available at up to a 90% discount compared to On-Demand EC2 instance prices.” aws.amazon - Quote: “Spot Instance Advisor populates the frequency of interruption and average savings… based on the last 30 days of historical data.” aws.amazon - Quote: “the past interruption behavior doesn’t predict the future availability of these instances.” aws.amazon - Cost-effective Batch Processing with Amazon EC2 Spot - TODO: No verbatim quote provided in the search results. - Scientific Workflow Applications on Amazon EC2 (Montage) - Quote: “Epigenomics is considered to be CPU-bound because it spends 99% of its runtime in the CPU and only 1% on I/O…” montage.ipac.caltech - Parsing Common Crawl in a day for 60
- Measuring the Carbon Cost of Crawling Five Billion Web Pages
- Quote: “Tailpipe assessed Common Crawl’s AWS usage data for the months of February and March.” tailpipe
- Quote: “during the post-processing phase, AWS billed Common Crawl less per day… suggests that… workload was being consolidated across fewer computing instances with a higher utilization rate…”. tailpipe
- AWS EC2 Instances Benchmark
- TODO: No verbatim quote provided in the search results.
- Common Crawl on AWS Marketplace
- TODO: No verbatim quote provided in the search results.
SERP datasets and SEO spam
- Webis-PSERP-24 dataset page
- TODO: No verbatim quote provided in the search results.
- Is Google Getting Worse? A Longitudinal Investigation of SEO Spam in Search Engines
- Quote: “we created a large collection of top 20 SERPs for 7,392 product review queries.” downloads.webis
- Quote: “The SERPs were scraped repeatedly over the course of a year from Startpage … Bing, and DuckDuckGo,” with pages “archived as Web ARChive (WARC2) files.” downloads.webis
- Quote: “It’s not far-fetched to assume a connection between SEO and a per-… tially AI-generated content.” downloads.webis
LLM-generated text detection at scale
- A Survey on LLM-Generated Text Detection: Necessity, Methods …
- Quote: “The LLM-generated text detection aims to discern if a piece of text was produced by an LLM… a binary classification task.” arxiv
- An Empirical Study on Detecting LLM-Generated Text via LLMs
- Quote: “Another approach, DetectGPT … employs a zero-shot classifier.” aclanthology
- Graphite report on Common Crawl prevalence
- Quote: “randomly select 65k URLs from CommonCrawl” and “published between January 2020 and November 2022.” graphite
- LinkedIn post on Google Search prevalence
- Quote: “AI-generated content only appears 14% of the time in Google Search (n=31k).” linkedin
- Mozilla Foundation report on Common Crawl
- Quote: “Common Crawl does not contain the “entire web,” nor a representative sample of it.” mozillafoundation
- A Critical Analysis of the Largest Source for Generative AI Training …
- TODO: No verbatim quote provided in the search results.
- A Review of the Challenges with Massive Web-mined Corpora Used …
- Quote: “Pipelines like CCNet employ statistical KenLM models to assess text perplexity during the data filtering phase.” arxiv
Last edited:
Changelog
2025-12-03
- upgraded to Python 3.14 & rid torch compile
2025-11-11
- finished DB migration & bulk Git history cleanup
- re-statted search result sites and observed filtering too strict
2025-10-07
- tried decision tree/forest for filtering; default settings high FPR; tree uninterpretable
2025-09-29
- removed TimescaleDB after confirming PostgreSQL handled compression
2025-09-18
- re-crawling Common Crawl 10k subdomains; many rejected as non-articles
2025-09-09
- DB migration blocked by TimescaleDB slowness until adding index and fixing chunking
- re-crawling Common Crawl 10k subdomains remains slow after filter adjustments but likely correct
2025-07-23
- recomputed incorrect Binoculars scores
- re-downloaded Common Crawl index for uniform sampling and filtered IP hostnames
2025-07-08
- analyzed Common Crawl 10k subdomains: lower %AI overall, more when crawled later
- quantized Falcon-7B to fp8 and improved dynamic batching for Binoculars
- SVMs need only 15 pages per site; Binoculars SVMs highly confident on baseline
- enabled CDC-based dedup per site, removed unused Common Crawl downloads
2025-06-24
- NLP researchers hinted worse Binocular results from new models are due to model being less similar to ChatGPT-3.5
- removed Playwright thread bottleneck and scaled task spawning by available resources
- set up SQLite concurrent writes and Rust+Python codebase for maintenance
- building Common Crawl index DB faced gzip issues, SSL errors, and rate limiting
- sampled subdomains with 10 concurrent downloads; observed CPU-bound extraction and subdomain completion stats
- filtered by duplication rate using CDC
2025-06-03
- fixed low-hanging non-article filtering issues
- sampled subdomains from Common Crawl for classification
2025-05-06
- completed per-site deduplication and additional filtering tweaks
- decided against moving extraction and ad counting into the browser
2025-04-29
- improved ad counting by counting only elements with content and considered ads-per-token metric
- debugged asyncio crawler issues; noted resource balancing contribution
- fixed false positive on www.w3docs.com by filtering code text
2025-04-15
- settled on decile-based feature vectors
- sampled subdomains via how-to queries to broaden coverage
- generated positive websites for baseline
- built website feature vector SVM with train/test split
2025-04-08
- surveyed website generator capabilities
2025-03-25
- expanded AI and human website datasets, including IndieWeb sources
2025-02-24
- confirmed high-score pages in low-score sites rarely good
- subdomain SVMs for statistical scoring
- reviewed blacklist matching, sites near threshold, and WHOIS checks
2025-02-11
- switched to Wayback Machine prefix search instead of recursive crawling
Last edited:
Google Trends
(deprecated)
- can get top overall/related topics & queries for given time range + location + category + topic/query
- up to (and usually) 25 each
- can also get “rising” topics & queries
- but unclear how to know their popularity
- can get name + relative interest + href to Google Trends page for each topic/query entry
[ ] Google Trends block request from browser in incognito mode 💀- can use BigQuery to get data directly
plan:
- get most top topics & queries for 2024 for each category
- recursively get top related topics & queries for each topic
- depth 3 would give ~16000 queries, resulting in search result pages if each of the 6 search engines returns 5 pages on average
- which would take days if each page takes 5 seconds to classify
- Google Trends has ~1400 topics, w/ levels of subtopics
google_trends_all_cat.jsonfrom https://github.com/pat310/google-trends-api/wiki/Google-Trends-Categories
- 💀 Google Trends give off topic related queries
- e.g.,
how to→how to train y→how to train your dragon
- e.g.,
- depth 3 would give ~16000 queries, resulting in search result pages if each of the 6 search engines returns 5 pages on average
Last edited:
Preliminary Binoculars Evaluation
- dump English HTTP response from random Common Crawl WARC file
- extract main text; if longer than 2000 character, feed into Binoculars
[ ] split long page down to Falcon-7B context window 2048 tokenjust truncate- currently, simply truncate
[ ] average score weighted on token count
script: degentweb.common_crawl.classify_english
result dumped to data/common_crawl/prelim_test/; 5961 page; used 1h 20m
Manual inspection of low-score page among 1010 Common Crawl page
low-score page:
- ~19 seem indeed generate article, mostly blog & product
- 3 simply table-like listing
- 7 short listing/interaction page (scoreboard, links; only 2 are > 2000 character)
- boilerplate text: 7 cookie banner (< 2000 character); 1 legal notice
- 1 seem false positive https://catalyticconvertersolutions.com/writer/nicolas-will/
lower-score page (above FPR-threshold but around F1-threshold):
- many also seem generated, some not
- 1 page error message (MySQL)
- boilerplate text (legal)
Case studies
- short listing/interaction page
- boilerplate text:
- cookie banner from Trafilatura extraction issue
- clearly generated
Problem
filter_non_article.mdlisting/interaction page should not be in this study- cannot simply filter by markup ratio (link, button, etc.) bc some attach large description block
- ❓ ML model to distinguish article
- can base on BERT or BART
- cannot ask LLM bc unreliable (tested)
❓tested, unreliable<meta property="og:type" content="article">but not every article has this
Google Bing 500 1000 WikiHow articles
script: degentweb.browser.bing_search degentweb.classifying.google_prelim degentweb.classifying.prelim_data_analysis
not running browser;20 Bing search result per query;~133 Google query- some domain has many result w/ Binoculars score < FPR threshold
-
tend to haveseem not reliableog:typebearticle - include many ad (business model: content farm + ad?)
- e.g., https://www.solveyourtech.com https://gbtimes.com https://robots.net https://www.supportyourtech.com https://www.thetechedvocate.org https://citizenside.com https://www.live2tech.com https://www.madpenguin.org https://accountinginsights.org https://umatechnology.org https://www.clrn.org https://www.costumerealm.com https://www.neuralword.com https://www.simplymac.com https://www.gameslearningsociety.org/ https://thetechylife.com/ https://elevationvibe.com/ https://ebestcourses.com/language/accent-reduction/
- detect&count ad
- seller/scam website boosting site rank in search engine w/ AI blog
- e.g., http://www.androidphonesoft.com/ https://dashboardsexcel.com/
- detect seller/scam website
- clearly generated but unclear how they profit
- e.g., wiki https://freemwiki.com/wiki/%E9%A6%96%E9%A1%B5, blog https://www.thegadgetgazette.com/
- 💡 we are 100% sure a website is generated w/ ChatGPT w/o human review if they include something like
As an AI - sitemap show they post too often: https://bankbingo.com/ https://accountingjournalentries.com/
- explicitly generated
- sell solution for generating article https://eulogygenerator.com/
- AI search https://www.neuralword.com/
- spammy but unclear if generated (from late 2022) https://sheetsland.com/
- how are they ranked in search result?
- some appear in multiple search. double count or take median?
- stats show they rank similar to non-AI sites
-
- some clear false positive on some forum&support page
- no
og:typeor have it bewebpage - for false positive article, perhaps can filter by searching training data
- too much data (2TB) to search online, need local DB
- 🤔 some like https://www.geeksforgeeks.org/ are somewhere between content farm and educational site, w/ variable quality
- no
- no token-count correlation; search-query correlation unclear
Site crawling
script: degentweb.browser.visit_subdomains
- for each subdomain shown in search result, if < 20 page crawled, then try finding sitemap w/ ultimate-sitemap-parser
- if no sitemap, then query Wayback Machine (WM) Content Index API for last 2000 ok HTML response in the last 4 year
- if found any page, then crawl (20 – #already_crawled) page
Last edited:
Ad Extraction
extracting&counting ad may help identify content farm
Options for methods
- (currently implemented) apply EasyList CSS selectors on HTML (browser, JS enabled) using
lxmlor similar- UW use this
- only count elements w/ content →
n_non_empty_ads - use bounding box?
- compute ads-per-token normalization metric
- Huanchen idea: turn Ad blocker on/off in browser & diff visual element
- use uBlock Origin logger when running browser
- use uBlock-Origin-compatible rule parser (e.g., adblock-rust) & somehow
Browser operation
to load all ad, scroll to the bottom and top, 20 time combined, each time wait for networkidle (in degentweb.browser.save_page)
- some ad load slowly
- some ad load after a timeout
- some ad load after user interaction
re-crawled all 0-ad page after adjusting browser interaction w/ degentweb.browser.recrawl_no_ads
Ad classification
see Analyzing the (In)Accessibility of Online Advertisements
most should be Google Ads
Case study
- extreme page w/ 443 ads: https://www.minimizemymess.com/blog/types-of-dresses
- long; scrollable ad banner at the top; different sidebar ads when scrolling
Last edited:
Filter out Non-Article
Binoculars, and presumably other generated text detectors, can only perform well when detecting articles such as blog posts. Non-articles, include lists of links on a homepage, login pages, dashboards of sports scores, and spec charts of products, may cause high false positive rates.
Current method to filter out non-articles (visit_subdomains.py):
- use how-to search results. most of them are articles and forum threads, except for occasional product sales page
- discard pages w/ < 200 tokens
- discard pages w/ > 20% text in link/code
- Trafilatura sometimes extract wrong thing
- extract many link following main text, e.g. https://entrance-exam.net/annamalai-university-pg-diploma-in-automobile-maintenance-auto-garage-management-papers/
- extract only code block, e.g. for https://plaid.com/institutions/mos/
- ⇒ try Trafilatura w/
favor_precisioninstead offavor_recallif too much text in link/code
- Trafilatura sometimes extract wrong thing
- discard pages w/o any “block” > 250 characters long
- blocks are separated by newline, line break, separator; boundaries of block elements: header, paragraph, div, body, table cell, list item, code, quote
- likely not consist of paragraph
- discard pages w/ < 75% text in “large blocks”
- large block need ≥200 characters
- discard pages w/ > 20% text in list/table
- do not count long list item/ table cell: need ≤ 100 characters long
- discard pages w/ > 50% text duplicated relative to previous pages of the same subdomain
- calculate %duplication based on byte chunks from Rabin fingerprint content-defined chunking (CDC)
- 32 byte window, 96 byte target block size (1/64 probability for splitting)
- calculate %duplication based on byte chunks from Rabin fingerprint content-defined chunking (CDC)
Method used by Dolma 1.6 dataset:
- C4 NoPunc: remove lines not ending in punctuation (
.?!")- remove document w/ ≥ 50% lines not ending in above punctuation (❗️we don’t use this bc filter out valid articles)
- Gopher All (❗️we apply these after NoPunc cleaning to avoid over-filtering):
- fraction of characters in most common n-gram greater than threshold
- bigram > 0.20
- trigram > 0.18
- 4-gram > 0.16
- fraction of characters in duplicate n-grams greater than threshold
- 5-gram > 0.15
- 6-gram > 0.14
- 7-gram > 0.13
- 8-gram > 0.12
- 9-gram > 0.11
- 10-gram > 0.10
- fewer than 50 or more than 100 000 words
- median word length < 3 or > 10
- symbol / word ratio > 0.10
- fraction of words with alphabetic characters < 0.80
- contains fewer than 2 required words
- fraction of lines starting with bullet > 0.90
- fraction of lines ending with ellipsis > 0.30
- fraction of duplicated lines > 0.30
- fraction of characters in duplicated lines > 0.30
- fraction of characters in most common n-gram greater than threshold
- contains
allenai/gpt-neox-olmo-dolma-v1_5token or token sequence repeated > 100 times (❗️we don’t use this bc insignificant)- 0.003% of characters tagged for removal
Ideas for filtering:
- discard pages based on HTML structure
- but HTML structure is extremely flexible and behave differently based on CSS
- perhaps study how Trafilatura filter out non-main-body text
- feed extracted text to classifier
- BERT-based classifier for article/non-article
- prior work calls this “genre detection” and often relies on word counts
Learning-based
- tried decision tree/forest for filtering ⇒ high FPR and uninterpretable tree
Unreliable ideas:
- filter by
og:type=article. unreliable because not every article has this tag and content farm may have this tag bewebsite
Deduplication
- Finding Similar Files in a Large File System, Udi Manber, USENIX Winter, 1994
- use Rabin fingerprint (polynomial fingerprint) to randomly determine “anchor” for chunking
- polynomial fingerprint bc can efficiently compute next n-byte hash after shifting 1 byte
- find identical chunks
- use Rabin fingerprint (polynomial fingerprint) to randomly determine “anchor” for chunking
- Simhash
Segmentation for generalization
Instead of only filtering out what we cannot handle (non-article), we can also try to generalize our method to all webpages.
If we could split a webpage into sections, we could apply Binoculars to each section. For example, we could segment a homepage full of links into each of the links it contains, and subsequently filter them out based on length; we could segment a forum page into each comment.
Importantly, we need to segment after main text extraction with Trafilatura.
Webpage segmentation (WPS) tool
- Web page segmentation with structured prediction and its application in web page classification, Lidong Bing, Rui Guo, Wai Lam, Zheng-Yu Niu, Haifeng Wang, SIGIR, 2014
- too old
- webpage class: index, image, forum, product, research result, blog, download, news, video, other
- Box clustering segmentation: A new method for vision-based web page preprocessing, Jan Zeleny, Radek Burget, Jaroslav Zendulka, Information Processing Management, Elsevier, 2017
- vision-based
- no code
- Multimodal Web Page Segmentation Using Self-organized Multi-objective Clustering, Srivatsa Ramesh Jayashree, Gaël Dias, Judith Jeyafreeda Andrew, Sriparna Saha, Fabrice Maurel, Stéphane Ferrari, TOIS, 2022
- MCS: automatically choose #segment using K-means
- no code?
- Web Page Segmentation Revisited: Evaluation Framework and Dataset, Johannes Kiesel, Florian Kneist, Lars Meyer, Kristof Komlossy, Benno Stein, Martin Potthast, CIKM, 2020
- ⭐ Webis-WebSeg-20 dataset for WPS benchmark
- WebSAM-Adapter: Adapting Segment Anything Model for Web Page Segmentation, Bowen Ren, Zefeng Qian, Yuchen Sun, Chao Gao, Chongyang Zhang, Advances in Information Retrieval, Springer ECIR, 2024
- segment any model vision-based SoTA webpage segmentation
- use Webis-WebSeg-20 dataset for eval
- did not cite Multimodal Web Page Segmentation
- A DOM-structural cohesion analysis approach for segmentation of modern web pages, Hieu Huynh, Quoc-Tri Le, Vu Nguyen, Tien Nguyen, Springer World Wide Web, 2025
- use DOM structure analysis
- use Webis-WebSeg-20 dataset for eval
- did not cite WebSAM-Adapter
Last edited:
Baseline Websites
curl/seed_db.py
- assume webpage before ChatGPT (Nov 30, 2022) likely human-written
- publication date extraction: htmldate: A Python package to extract publication dates from web pages, Adrien Barbaresi, JOSS, 2020
Human-written
credible source
- Wikihow https://www.wikihow.com/
- Reddit recommended blog
personal website
- (30x) IndieWeb Wiki: registry of personal website
- after filtering by having sitemap, most are tech blog
- WordPress directory?
- (30x) IndieWeb Wiki: registry of personal website
Tranco low-rank blogs mostly dead or non-English, unsuitablecompany website
EDGAR database → company name → search for websitemany of them do not have websiteUS Business Database?no website linkLinkedIn?forbit crawling- (30x) Russell 2000
- many do not have blog; many are after ChatGPT; many have no sitemap
- after filtering by having sitemap, most are tech company
- content: most are blog/ company statement (news); some are service/product description; few functional page e.g. form
find
.*/blog/.*URL in CommonCrawl?
Machine-generated
- (2x) self-claim generated
- sell solution for generating article https://eulogygenerator.com/
- AI search https://www.neuralword.com/
- generated using Wix and B12 manually or w/ Browser-Use
- prompt generated by ChatGPT/Gemini (
curl/suggestions.py)- summarize given URL as website description; suggest name for similar site
- suggest 50 name+description for blog post
- input into Wix/B12 to generate home page + boilerplate + 20 blog post
- Browser-Use only usable w/ best model like Gemini 2.5 Pro
- expensive: spent ~$8/site just for LLM API
- 30x Wix site correspond to Russell 2000 company site
- 30x B12 site correspond to IndieWeb site
- 4x + 4x other
- prompt generated by ChatGPT/Gemini (
- (not included in dataset) clear cue, e.g., “as an AI”
- additional AI website generators beyond Wix/B12
- artificial set-level sample from benchmark datasets?
- more baseline negatives from before ChatGPT
- document prompt engineering effort needed for generator outputs
Training/test dataset 144x
- company website dataset 60x: 30x Wix vs. 30x Russell 2000
- personal website dataset 60x: 30x B12 vs. 30x IndieWeb Wiki
- other website dataset 24x: 4x Wix + 4x B12 + 2x self-claim generated vs. 8 Reddit recommended blog + 6 top blog
note:
- human site have blog, statement, service description, etc.; while generated site mostly are blog
- generated site have boilerplate page, e.g. policy, by the website generator, causing occasional high Binoculars score
AI website generator
- 10Web claim to generate&host website on name&description
- landing page & 1-paragraph sample article
- claim to have generated 1.5M+ websites
- from $13/month; need $28/month “pro” to edit&multi-site; WordPress, Cloudflare CDN
- ❌ need $49/month for each additional website
- ❌ extremely slow when generating, e.g., >10min/page
- Wix AI Website Builder
- landing page & short/long blog article on demand
- allow multiple site, sell domain&service instead of generator
- for arbitrary page, “Generate Full Page Text” produce poor result
- ❌ only generate 1 very short text block & no layout generation
- ContentBot.ai automate AI-driven content creation
- claim to be used on ABCNews, Contagious, PR Week, etc.
- no free trial; from $0.5/1000 word, $29/month for full plan
- Copy.ai go-to market AI for marketing, sales, etc.
- claim to be used by SIEMENS, Rubrik, etc.
- no free trial; $49/month for starter individual plan; mainly target business
- WebWave AI
- landing page & manually written blog
- ❌ very slow; had bug of not publishing blog
- from $3.5/month; $5/month for blog&SEO
- B12
- landing page/ medium-length blog/ service/project description/ team member, on demand
- or any page given name+description
- from $42/month
- very fast generation
- landing page/ medium-length blog/ service/project description/ team member, on demand
- Contentful AI Content Generator use OpenAI API to write content
- HubSpot AI Website Generator optimize existing company website
- only generate landing page
- Relume only generate mockup/HTML
- Webflow only generate layout
- GoDaddy Airo focus on marketing & selling
- ❌ need GoDaddy domain
- Dorik AI
- ❌ need $39/month for unlimited #page, else limit to 5 (free) or 25 ($18/month) per site
- Vzy
- $10/month/site for 100 page
- Wegic, Tilda, Shopify Magic?
Provided example generated sites
- hand-picked; probably not purely generated
- some not text-heavy (mainly image, etc.)
- commonly business w/
/blog; unlike most content farm found
each generator:
- 10Web https://help.10web.io/hc/en-us/articles/360031026572-Can-You-Provide-Examples-of-Websites-Hosted-on-10Web
- seem not purely generated
- Wix https://www.wix.com/blog/wix-artificial-design-intelligence Examples of sites created with Wix’s ADI-powered website builder
- most down
- B12 https://www.commoninja.com/blog/b12-ai-website-builder#Examples-of-Websites-Designed-with-B12%23Examples-of-Websites-Designed-with-B12
Website generator capability
- Examining the Accessibility of Generative AI Website Builder Tools for Blind and Low Vision Users: 21 Best Practices for Designers and Developers, Sushil K. Oswal, Hitender K. Oswal, ProComm, 2024
- dorik.com, relume.io, wix.com capability
- generate landing page, sitemap, wireframe on description
- customize layout, style
- generate text&image w/ prompt
- dorik.com, relume.io, wix.com capability
- most tutorial/comparison only showcase landing page generation
- product description/ event description/ tech doc/ blog
- marketing email/ social media post/ SEO
- not content: AI chat support, analytics report
- not AI functionality
- boilerplate page: FAQ/ privacy policy/ terms of service/ 404
- selling product/service/ booking/ form
What category to cover
- can only cover what AI website generator can generate
covering:
- personal/company/organization blog
want:
- personal/team project description
- news
- products
Last edited:
Classifying Websites
Binoculars optimizations
- quantize Falcon-7B and Falcon-7B-instruct to
fp8: hardly change Binoculars score, but faster&smaller - group batch by similar #tokens & decide batch size from max#tokens
SVM website classifier
classifying/site_svm.py
- webpage filtering
- filter by a URL path regex to rid index page, tag page, etc.
- filter by
Content-Type: text/html - filter by English & #tokens > 200, etc. (
filter_non_article.md)
- compute 9 Binoculars score deciles among webpage for each website
- also tried 101 percentiles, 11 deciles, 5 quartiles, 3 quartiles; little difference
- train linear SVM classifier on deciles as feature vector
- train on company/personal website dataset (
baseline_sites.md) - out-of-distribution test on personal/company/other website dataset
- perfect performance in every combination
- optionally filter by beforeGPT
- train on company/personal website dataset (
- still perform well and high SVM-sureness when sampling fewer pages/site
- Binoculars SVMs very confident on baseline data
- ⇒ aggregate Binoculars score analysis perform well regardless of the noise in data (e.g., boilerplate page)
- generalize across different kinds of website
Applying in the wild
- full SVM model: train SVM on all baseline website, w/ 9 deciles (
classifying/full_site_svm.py) - aim for 20page/site but allow at least 15page/site
Other detectors
- keeping: Fast-DetectGPT
fast_detect_gpt, mean log probabilitylog_p, likelihood log-rank ratio (LRR)lrr, mean log ranklog_rank, entropy- only Fast-DetectGPT perform perfectly on baseline; others have >90% accuracies
- FastNPR, RoBERTa, RADAR, intrinsicPHD, max probability performs badly: <0.5 Pearson correlation w/
is_generatedon baseline
Crawling websites for classification
browser/bing_search.py
- Sample 1000 WikiHow article how-to questions as queries by SHA256.
- Search Bing API for 20 results for each query.
- For each result link, extract subdomain.
- For each subdomain, fetch the sitemap.
- If no sitemap, fetch last 2000 pages from Wayback Machine CDX.
- Randomly sample pages from the sitemap to crawl until 20 non-filtered.
- respect robots.txt
- give up on 3 error connecting, e.g., DNS resolution failure, connection timeout
Last edited:
Common Crawl Dataset
Common Crawl index
Formats
path file e.g.: https://data.commoncrawl.org/crawl-data/CC-MAIN-2025-18/cc-index.paths.gz
line in path file e.g.:
cc-index/collections/CC-MAIN-2025-21/indexes/cdx-00022.gz
index file e.g.: https://data.commoncrawl.org/cc-index/collections/CC-MAIN-2025-21/indexes/cdx-00002.gz
line in index file e.g. Languages are ,-separated, English is eng:
ar,com,fusionbikes)/producto/luz-knog-blinder-mini-niner 20250512054001 {"url": "https://fusionbikes.com.ar/producto/luz-knog-blinder-mini-niner/", "mime": "text/html", "mime-detected": "text/html", "status": "200", "digest": "ZA6MPPJEFGZ53KWFSLWMF7NDO7RKOWR4", "length": "78501", "offset": "243658810", "filename": "crawl-data/CC-MAIN-2025-21/segments/1746990412231.65/warc/CC-MAIN-20250512042640-20250512072640-00410.warc.gz", "charset": "UTF-8", "languages": "spa"}
line in index file with redirect:
ar,com,futbolinterior)/component/mailto?link=b2449dac9dd9dbc27fe2d9f8c9dfc250a10eb664&template=shaper_helix3&tmpl=component 20250516140105 {"url": "http://futbolinterior.com.ar/component/mailto/?tmpl=component&template=shaper_helix3&link=b2449dac9dd9dbc27fe2d9f8c9dfc250a10eb664", "mime": "text/html", "mime-detected": "text/html", "status": "301", "digest": "OQ3OBNFR7DBCFQ4ANGEQW5P2FOXZZJRA", "length": "1103", "offset": "391196", "filename": "crawl-data/CC-MAIN-2025-21/segments/1746990412530.66/crawldiagnostics/CC-MAIN-20250516130253-20250516160253-00626.warc.gz", "redirect": "https://futbolinterior.com.ar/component/mailto/?tmpl=component&template=shaper_helix3&link=b2449dac9dd9dbc27fe2d9f8c9dfc250a10eb664"}
filtering: mime is text/html, status is 2xx, languages is eng.
ideal compression (468B → ~80B for this file, ~17%):
subdomain,path,length,offset,filename
fusionbikes.com.ar,producto/luz-knog-blinder-mini-niner/,20250512054001,78501,243658810,CC-MAIN-2025-21/segments/1746990412231.65/warc/CC-MAIN-20250512042640-20250512072640-00410.warc.gz
# after storing subdomain and filename in other tables, 68 bytes for this entry
4B, producto/luz-knog-blinder-mini-niner/,20250512054001,4B, 4B, 4B
Size and storage estimate
- 44 path files from 2020 to May 2025 (very small)
- ~301 index files per path, ~783MB per file, ~5.8GB uncompressed
- ~13244 index files
- ~230GB of index files under each path file, ~10.1TB total (too much)
- assume 5% entries left after filtering, 17% compression rate after index
- ⇒ ~14.9GB per path file, ~657GB total (managable)
- only keep 2000 entries per subdomain, ⇒ est. <10% size, <66GB (very fine)
- throw away existing entries w/ largest BLAKE3 signed 64bit hash number
- wrong estimate; actually much larger
- only sample index files w/ 1/32 probability
- 589 index files
- 166 from
cc-index/collections/CC-MAIN-2025-21/because did not filter that path file when started crawling
- 166 from
- only sample index files w/ 0-based line number (in path file) that is fully divided by 32
- 589 index files
- 36192326 subdomains
- only 153233 have 2000 records
Implementation
- Common Crawl use blocked gzip
- batch insertion to avoid slow
- SSL errors; Common Crawl 1MiB/s rate limiting
Sampling & classification
common_crawl/classify10k.py
- sample 10,000 subdomain from all index files
- 2.16%~4.30%~9.30% subdomains classified as AI-dominant, much lower compared to search results
- increasing %AI if segment by starting
crawled_atyear - 10 concurrent downloads, CPU-bound by extraction
S3
- Introducing CloudFront as a new way to access Common Crawl data as part of Amazon Web Services’ registry of open data, Sebastian Nagel, 2022
- S3 access restricted to authenticated users
Last edited:
Deprecated ideas and tasks
Keyword acquisition
- WikiHow article titles (
wikihow.md) [ ] from Google Trends (google_trends.md)- Google completion?
get topic class from Google Trends[ ] human brainstorm related keywords
Last edited:
Healthcare
Brainstorm to combine systems/ML
- Telemedicine
- Precision medicine
- Infrastructure
- Nextflow, Snakemake
- Federated learning
- EHR (Electronic Health Record) Systems
Last edited:
Generative AI (GenAI)
AI-generated text detector
- perplexity: likelihood of sequence of text according to specific language model
- bilingual evaluation understudy (BLEU): quality of machine translation compared to human translation
commercial:
- Originality.ai: proprietary paid detector, prover (that text is not generated), and fact checker
- $1 per 1000 word
- GPTZero: $8.4 per month for 150,000 word ($1 per 18,000 word)
- ❓ claim to offer free API for researcher
- list of paper using GPTZero
- Detecting AI-Generated Writing Using GPTZero, Karen Paullet, Jamie Pinchot, Evan Kinney, Tyler Stewart, ISCAP, 2024
- claim to be highly accurate, but paper seem not robust
- Copyleaks: $10/month
- list of junk or misrepresented papers supporting its “best” accuracy: Third-Party Studies Continue to Confirm Copyleaks AI Detector as the Most Accurate
paper:
- Towards Possibilities & Impossibilities of AI-generated Text Detection: A Survey, Soumya Suvra Ghosal, Souradip Chakraborty, Jonas Geiping, Furong Huang, Dinesh Manocha, Amrit Singh Bedi, arXiv, 2023
- statistical method: entropy, perplexity, n-gram frequency
- detecting all model said to be impossible
- watermark discussion
- RAID: A Shared Benchmark for Robust Evaluation of Machine-Generated Text Detectors, Liam Dugan, Alyssa Hwang, Filip Trhlik, Josh Magnus Ludan, Andrew Zhu, Hainiu Xu, Daphne Ippolito, Chris Callison-Burch, ACL, 2024
- RAID Benchmark Leaderboard: list of tested commercial and free detector
- 💡 can use binoculars
- domain matter: what type of text
- 💡 need to limit domain to validate
- repetitiveness higher for generated text: Self-BLEU
- 💡 we could check for repetitiveness instead of generation
- detector type: ML more robust than metric-based
- high false positive rate; power function of accuracy
- not robust to adversarial attack like repetition penalty
- RAID Benchmark Leaderboard: list of tested commercial and free detector
- Texygen: A Benchmarking Platform for Text Generation Models, Yaoming Zhu, Sidi Lu, Lei Zheng, Jiaxian Guo, Weinan Zhang, Jun Wang, Yong Yu, ACM SIGIR, 2018
- propose Self-BLEU for repetitiveness
- LLM-as-a-Coauthor: Can Mixed Human-Written and Machine-Generated Text Be Detected?, Qihui Zhang, Chujie Gao, Dongping Chen, Yue Huang, Yixin Huang, Zhenyang Sun, Shilin Zhang, Weiye Li, Zhengyan Fu, Yao Wan, Lichao Sun, NAACL, 2024
- dataset of mixed human+machine text
- GLTR, DetectGPT, etc. classify inconsistently in the middle
- RADAR best F1 score: 0.88
- GitHub
- ⭐️ Fast-DetectGPT: Efficient Zero-Shot Detection of Machine-Generated Text via Conditional Probability Curvature, Guangsheng Bao, Yanbin Zhao, Zhiyang Teng, Linyi Yang, Yue Zhang, ICLR, 2024
- compare perplexity after perturbation; zero-shot
- improvement in speed and accuracy on prior DetectGPT w/ conditional probability curvature sampling
- ⭐️ Spotting LLMs With Binoculars: Zero-Shot Detection of Machine-Generated Text, Abhimanyu Hans, Avi Schwarzschild, Valeriia Cherepanova, Hamid Kazemi, Aniruddha Saha, Micah Goldblum, Jonas Geiping, Tom Goldstein, ICML, 2024
- model-agnostic
- perplexity / cross-perplexity between “observer” & “performer” model
- dedicated prompt can boost perplexity of generation when observed w/o the prompt
- ❗ use Falcon-7B by default—need big GPU (16GB vRAM) and slow
(7s per input on A100)- quantization can lower to 6GB, <100ms prefill/autoregression
- ❗ memorize some training data
- not any of the training data in my few test
- The Impact of Prompts on Zero-Shot Detection of AI-Generated Text, Kouichi Sakurai, Kaito Taguchi, Yujie Gu, IJCAI, 2024
- not having prompt info cause big detector accuracy drop
- ran Binoculars w/ Phi1.5 and still got decent result
- 0.88 accuracy in black-box test; outcompete other
- ❓ code does not reveal use of Phi for Binoculars
- best accuracy in black-box setting:
- Binoculars 0.877
- FastDetectGPT 0.819
- FastNPR 0.768
- propose FastNPR as a faster NPR??
- but do not claim to have proposed it and do not list formula
- Not all tokens are created equal: Perplexity Attention Weighted Networks for AI generated text detection, Pablo Miralles-González, Javier Huertas-Tato, Alejandro Martín, David Camacho, Information Fusion, Elsevier, 2025
- Binoculars poor accuracy in MAGE&M4
- MAGE: Machine-generated Text Detection in the Wild, Yafu Li, Qintong Li, Leyang Cui, Wei Bi, Zhilin Wang, Longyue Wang, Linyi Yang, Shuming Shi, Yue Zhang, ACL, 2024
- old human text
- prompt 27 LLM to generate text: continue story; write on topic; write on topic w/ source
- paraphrase both human&machine text as machine text
- ❌ paraphrased human text should not be machine text
- Hugging Face dataset
- M4: Multi-generator, Multi-domain, and Multi-lingual Black-Box Machine-Generated Text Detection, Yuxia Wang, Jonibek Mansurov, Petar Ivanov, Jinyan Su, Artem Shelmanov, Akim Tsvigun, Chenxi Whitehouse, Osama Mohammed Afzal, Tarek Mahmoud, Toru Sasaki, Thomas Arnold, Alham Fikri Aji, Nizar Habash, Iryna Gurevych, Preslav Nakov, EACL, 2024
- Fighting Fire with Fire: Can ChatGPT Detect AI-generated Text?, Amrita Bhattacharjee, Huan Liu, SIGKDD, 2024
- ChatGPT as detector high FNR
- MOSAIC: Multiple Observers Spotting AI Content, a Robust Approach to Machine-Generated Text Detection, Matthieu Dubois, François Yvon, Pablo Piantanida, arXiv, 2025
- use multiple LLM perplexity to automatically choose best
- rejected by ICLR 2025 bc not consistently better empirically
- probably bc model need same tokenizer and are similar
- MLSDET: Multi-LLM Statistical Deep Ensemble for Chinese AI-Generated Text Detection, Dianhui Mao, Denghui Zhang, Ao Zhang, Zhihua Zhao, ICASSP, 2025
- combine multiple statistical property from multiple LLM w/ ML classifier
- ❌ low quality: wrong use of word “MoE”; plagiarized Binoculars cross-perplexity as LLMs-crossEntropy
- 🖥️ Detecting AI-Generated Code Assignments Using Perplexity of Large Language Models, Zhenyu Xu, Victor S. Sheng, AAAI, 2024
- detect ChatGPT-generated code assignment; 👎 AUC 0.87
- Learning to Rewrite: Generalized LLM-Generated Text Detection, Wei Hao, Ran Li, Weiliang Zhao, Junfeng Yang, Chengzhi Mao, ACL, 2025
- finetune Llama to rewrite text, minimizing edit distance for AI text
- Levenshtein distance
- generalize better across domain than RAIDAR
- better 0.90 AUROC than Fast-DetectGPT, but not compared w/ Binoculars
- finetune Llama to rewrite text, minimizing edit distance for AI text
- Almost AI, Almost Human: The Challenge of Detecting AI-Polished Writing, Shoumik Saha, Soheil Feizi, ACL Findings, 2025
- AI-polished text in various degree tend to be classified as AI text
- small sample size: 15k polished from 300 human text
- ✅ Binoculars <10% FPR on GPT-4o/DeepSeek-V3 polished text
- Fast-DetectGPT <20%
- higher FPR on Llama, but such smaller model unlikely used IRL
- 😕 poor figure, wrong label: not (%) but ratio
- GitHub
- related news: A New Headache for Honest Students: Proving They Didn’t Use A.I.
- AI-polished text in various degree tend to be classified as AI text
- Detecting Machine-Generated Texts: Not Just “AI vs Humans” and Explainability is Complicated, Jiazhou Ji, Ruizhe Li, Shujun Li, Jie Guo, Weidong Qiu, Zheng Huang, Chiyu Chen, Xiaoyu Jiang, Xinru Lu, arXiv, 2024
- there should be an “undecided” category
- Glimpse: Enabling White-Box Methods to Use Proprietary Models for Zero-Shot LLM-Generated Text Detection, Guangsheng Bao, Yanbin Zhao, Juncai He, Yue Zhang, ICLR, 2025
- use Fast-DetectGPT w/ proprietary model logit
- much better performance on proprietary model outputs: 0.95 AUROC vs 0.79 on Mix3 dataset
- Enhancing LLM Text Detection with Retrieved Contexts and Logits Distribution Consistency, Zhaoheng Huang, Yutao Zhu, Ji-Rong Wen, Zhicheng Dou, EMNLP, 2025
pending review:
- MAGRET: Machine-generated Text Detection with Rewritten Texts, Yifei Huang, Jingxin Cao, Hanyu Luo, Xin Guan, Bo Liu, ACL, 2025
- Analyzing register variation in web texts through automatic segmentation, Erik Henriksson, Saara Hellström, Veronika Laippala, ICNLP, 2025
- Deciphering Textual Authenticity: A Generalized Strategy through the Lens of Large Language Semantics for Detecting Human vs. Machine-Generated Text, Mazal Bethany, Brandon Wherry, Emet Bethany, Nishant Vishwamitra, Anthony Rios, Peyman Najafirad, USENIX Security, 2024
- A Comprehensive Survey of Fake Text Detection on Misinformation and LM-Generated Texts, Soonchan Kwon, Beakcheol Jang, IEEE Access, 2025
testing:
- Binoculars & GPTZero work well on my text & short prompt generation
- ✅ classify paraphrase as human
- ❓ classify long prompt generation as human
- around 15GB × 2, 0.5s per context window (around 300 token) on A6000
Issues from AI-generated text
- bot account on social media
- fake product review
- academic plagiarism
- peer review validity
paper on AI-generated text:
- ❗️ Monitoring AI-Modified Content at Scale: A Case Study on the Impact of ChatGPT on AI Conference Peer Reviews, Weixin Liang, Zachary Izzo, Yaohui Zhang, Haley Lepp, Hancheng Cao, Xuandong Zhao, Lingjiao Chen, Haotian Ye, Sheng Liu, Zhi Huang, Daniel A. McFarland, James Y. Zou, ICML, 2024; Mapping the Increasing Use of LLMs in Scientific Papers, Weixin Liang, Yaohui Zhang, Zhengxuan Wu, Haley Lepp, Wenlong Ji, Xuandong Zhao, Hancheng Cao, Sheng Liu, Siyu He, Zhi Huang, Diyi Yang, Christopher Potts, Christopher D Manning, James Y. Zou, arXiv, 2024
- vastly efficient statistical batch detection via MLE of adjective appearance, i.e., word choice
- trained on human & ChatGPT-generated review from paper & prompt
- ❓ what prompt for us? generalize to other model?
- somewhat resistant to paraphrasing
- inference on 40k review from ICLR 2024, NeurIPS 2023, CoRL 2023, EMNLP 2023
- review w/ generation seem rushed, cite (use
et al.) less - ❗ what would set us apart from them?
- criticism
- validation unscientific: AI dataset generated same way as training data
- human may learn word from AI
- vastly efficient statistical batch detection via MLE of adjective appearance, i.e., word choice
- The Rise of AI-Generated Content in Wikipedia, Creston Brooks, Samuel Eggert, Denis Peskoff, EMNLP workshop, 2024
- use GPTZero & Binoculars w/ Falcon-7B
- Wikipedia article before & after GPT-3.5
- Reddit data from Kaggle
- get lower bound of generation by subtracting previous positive rate
- ❗ unscientific bc assume paper i.i.d.
- people likely believe repeated statement
- did not use Ghostbuster bc need training, Fast-DetectGPT bc lower accuracy
- The AI Review Lottery: Widespread AI-Assisted Peer Reviews Boost Paper Scores and Acceptance Rates, Giuseppe Russo Latona, Manoel Horta Ribeiro, Tim R. Davidson, Veniamin Veselovsky, Robert West, arXiv, 2024
- > 16% of 28,000 ICLR 2024 review used AI, w/ higher score
- threat to peer review process
- use GPTZero
- 30 word that predict generation by ~70% accuracy
- can such word use for screening
- > 16% of 28,000 ICLR 2024 review used AI, w/ higher score
- AI models collapse when trained on recursively generated data, Ilia Shumailov, Zakhar Shumaylov, Yiren Zhao, Nicolas Papernot, Ross Anderson, Yarin Gal, Nature, 2024
- fine tune Meta’s OPT-125m causal LM w/ generated text based on wikitext, recursively
- model collapse: generate gibberish
- DataComp-LM: In search of the next generation of training sets for language models, Jeffrey Li, Alex Fang, Georgios Smyrnis, Maor Ivgi, et al., Achal Dave, Ludwig Schmidt, Vaishaal Shankar, NeurIPS, 2024
- mentioning of synthetic data literature
- Prevalence, Sharing Patterns, and Spreaders of Multimodal AI-Generated Content on X during the 2024 U.S. Presidential Election, Zhiyi Chen, Jinyi Ye, Emilio Ferrara, Luca Luceri, arXiv, 2025
- ❌ lack literature review: claim there exist “scarce” studies on AI text
- 3 months of 24.7M tweet before election
- 12% AI image by GPT-4o
- 1.4% AI text by fine-tuned RoBERTa
- ❌ but only 0.96 F1 score in testing, so could just be error
- a few radical “superspreader” account for most AI content
- Extended: Navigating Today, Shaping Tomorrow: Studying the Role of LLMs on Wikipedia, Manoel Horta Ribeiro, Andrés Monroy-Hernandez, Wikimedia Research Fund Research Proposal, 2025
- propose to analyze use & user impact of LLM content on Wikipedia
- methods unclear
- has Binoculars in reference list w/o citing it
- ⭐️ Preprint: Do Spammers Dream of Electric Sheep? Characterizing the Prevalence of LLM-Generated Malicious Emails, Wei Hao, Van Tran, Vincent Rideout, Zixi Wang, AnMei Dasbach-Prisk, M. H. Afifi, Junfeng Yang, Ethan Katz-Bassett, Grant Ho, Asaf Cidon, IMC, 2025
- ~240k×2 Baracuda flagged spam/business email compromise (BEC)
- replace link w/
[link], filter <250 character
- replace link w/
- used RoBERTa, Fast-DetectGPT, DAIDAR, very different results
- train/test on pre-GPT + self-generated sample
- RoBERTa very low FPR/FNR on testing
- clear increase trend
- Latent Dirichlet Allocation (LDA) topic modeling; linguistic analysis
- case study: many similar email w/ different wording
- ~240k×2 Baracuda flagged spam/business email compromise (BEC)
news:
- Some of Substack’s Biggest Newsletters Rely On AI Writing Tools | WIRED
- 10% of 25 Substack sample seem generated, even by prominent author
- GPTZero paid to view article
- ❗ really small sample size
- some author claim to use LLM to polish not create
- predict that badge asserting human-made will be common
- 10% of 25 Substack sample seem generated, even by prominent author
- AI Slop Is Flooding Medium | WIRED
- 40% of post seem generated
- done by Pangram & Originality separately
- ❓ how do we compete w/ company
- ∃ misinformation tracking company, e.g. NewsGuard, that scan for generated text
- Medium CEO claim most generated post was hardly being read
- argue generated post are bad writing
- mention of YouTube get-rich-quick tutorial on generating post/book
- 40% of post seem generated
research ideas
- emphasize data in the wild different from benchmark
- noisy nature: non-prose
- low %LLM text cause pathetic theoretical max accuracy skill score (MASS) compared to trivial detector
- set-level detection applications: Reddit users, OpenReview, student cheating, Amazon reviewers
- collect advanced prompts from Reddit for adversarial benchmark dataset
- push-pull fine-tune LLM for logit-based detection
- manually check misclassified text to find patterns
- mash various metrics together randomly by brute force to see what work well
🤖 Agent-added generated web artifacts (2026-06-07)
- 🤖 Shift from text detection to artifact reliability: generated websites, widgets, plugins, and scripts are deployed executable artifacts, so the useful question is what obligations they satisfy, not whether a paragraph “sounds AI”.
- 🤖 Research angle: attach generation provenance, security claims, policy obligations, tests, scans, and deployment receipts to each generated artifact; then ask whether those receipts reduce insecure deployment and make repair more stable.
- 🤖 Transfer: software supply-chain provenance, C2PA-style authorship signals, static/dynamic application security testing, property-based tests, and runtime policy monitors.
- 🤖 Evaluation sketch: generate many small sites/components from realistic prompts, run scanners and hand-written exploit tests, patch with/without receipts, and measure exploitable vulnerabilities, review time, and regression rate.
- 🤖 Anchors:
LLMs in Web Development,Hidden Risks of LLM-Generated Web Application Code,Asleep at the Keyboard, SLSA/in-toto/Sigstore/Rekor, C2PA, Retrieval Collapse.
Human detection of AI-generated content
- A Representative Study on Human Detection of Artificially Generated Media Across Countries, Joel Frank, Franziska Herbert, Jonas Ricker, Lea Schönherr, Thorsten Eisenhofer, Asja Fischer, IEEE S&P, 2024
- human in USA&Germany&China cannot distinguish generated audio&image&text
- Blind and Low-Vision Individuals’ Detection of Audio Deepfakes, Filipo Sharevski, Aziz Zeidieh, Jennifer Vander Loop, Peter Jachim, ACM CCS, 2024
- low-vision/blind people cannot detect audio deepfake
- The Turing Test Is More Relevant Than Ever, Avraham Rahimov, Orel Zamler, Amos Azaria, arXiv, 2025
- TODO: not gone through this yet
- mention “Human or Not” website’s human 60% accuracy detecting AI in chat
- criticism: instruction unclear; interaction too short
Browser extension/add-on
display info on search result/ webpage itself
extension to automatically detect AI-generated text:
- Hive AI Detector: free
- Originality.ai
- Winston AI: need account
why extension for human to vote DNE:
- user privacy
- but can be solved like have I been pwned? using hash
- scale and cost
- peer-to-peer?
- adversarial attack like click farm
- can require voter to verify & pass CAPTCHA
- solution from crowdsourcing platform: moderator on Reddit, VIP on SponsorBlock
- voting is subjective
- specific tagging instead, e.g., “Ad”, “AI”, “Scam”
- (abandoned) similar project Dissenter browser let user comment on any webpage
Terms
- First Came ‘Spam.’ Now, With A.I., We’ve Got ‘Slop’, Benjamin Hoffman, The New York Times, 2024
- definition of “slop”
- claim unwanted AI spam frequently appear in search results
Benchmark paper
- MAVIS: Mathematical Visual Instruction Tuning with An Automatic Data Engine, Renrui Zhang, Xinyu Wei, Dongzhi Jiang, Ziyu Guo, Shicheng Li, Yichi Zhang, Chengzhuo Tong, Jiaming Liu, Aojun Zhou, Bin Wei, Shanghang Zhang, Peng Gao, Chunyuan Li, Hongsheng Li, ICLR, 2025
Last edited:
Sketch of JSphere the Project
Study why websites use JS. Specifically, what the JS is for: intention, use, application, etc. (spheres), that may or may not be replaceable by plain html/css or moving the functionality to the backend.
Spheres may overlap, producing a Venn diagram.
Problems
- Many websites ship way too much JS than needed.
- Running JS takes too many resources on the client side than needed.
Hypotheses
- Web developers are kind of stuck with the front-end situation due to the lack of alternatives.
- Web developers ship lots of dead JS code (problem 1).
- Shipping libraries without tree shaking.
- Shipping the whole app instead of only the necessary parts.
Preemptive loading.I don’t think so.
- Misalignment between developer intention and actual JS shipped.
- Large amounts of JS is used for bulk transformation of JSON data to DOM nodes, a common protocol in SPAs.
Deeper motivation
I believe front-end JS is overused. Many websites ship multiple MiB of JS to their clients (e.g. Facebook), but JS is designed for scripting, not systems. Current mitigations to this issue is to compile from TS, etc., but JS is not designed as a compilation target—we introduced WASM for this.
WASM cannot replace JS, but I hope it will in the future. WASM cannot replace JS because it lacks JS features:
- Browser APIs, including DOM manipulation. This renders WASM a mere “number cruncher”, and is hard to fix because most browser APIs are powerful and complex JS “string functions”.
- Be compiled from app languages and remain small (e.g. Elm, Clojure). This will be fixed now that we have WasmGC.
- Outstanding tooling. This comes gradually with a big ecosystem.
- Low learning curve and extreme dynamism. However, developers can be happy with static languages (e.g. Kotlin, Go), though humans have inertia.
To mitigate the first problem, we need to understand what front-end JS is used for. Why do websites need JS in the first place?
JS functionality spheres
- Frontend processing (essential)
- Form validation, sanitization, and submission
- UI dynamic interaction
- Domain-specific logic
- HTML generation (maybe replaceable by SSR)
- Dynamic content rendering
- Style application
- UX enhancements (maybe replaceable by CSS)
- Animations and effects
- Font loading
- Extensional features (bloated and hard to replace)
- Authentication and authorization (or SSO)
- Third-party integrations
- Social media sharing and embedding
- Payment gateways and APIs
- Analytics and tracking (Google Analytics/AdSense/tracking)
- Boilerplate (avoidable by writing vanilla compatible JS)
- Frontend frameworks (React)
- Browser compatibility workarounds (JQuery, PollyFill)
TODO:
- Manually check out the JS in a few websites.
- How to go from browser APIs to intent?
- Only need to check most used APIs, which contribute to most API calls.
Survey methods
- Scraping
- Open source codebases
- Public browser extension (but IRB :o)
- Web archives
Questionnaire for developers—social science :(
Implication: only open web, no login.
Analysis methods
- Static analysis. E.g., concolic execution.
- Pros: detects dead code.
- Cons: slow, cannot handle extreme JS dynamism, does not reflect real-world usage.
- Script injection. E.g., browser extension, proxy.
- Pros: easy, mostly compliant, reveals real-world usage, could scale.
- Cons: some scripts know (evasion), no idea which portions are useful, may need IRB.
- Browser modification
—too much work. Presumably VisibleV8.- Pros: most compliant, real-world usage.
- Cons: resource heavy?
- ML. Presumably by fine-tuning LLM.
- Pros: guesses intention. Reads comments, docs, commit messages.
- Cons: who labels? Where to get GPUs?
Anticipated implications
Towards better user experiences online.
- Developer: alert them of common tendencies to overuse JS → optimize website.
- Browser vendor: design & recommend to guide developer—teach them to utilize backend & HTML/CSS features.
- Perhaps add features that remove the need for common bloat patterns.
- People who block JS: more educated decisions when blocking.
Development
Track the evolution of JS usage in websites. Where are we going? Are we getting more JS unnecessary? Are we on a slope to JS hell?
Last edited:
Literature around JS Monitoring
A Symbolic Execution Framework for JavaScript, 2010 S&P
An empirical study of privacy-violating information flows in JavaScript web applications, 2010 CCS
Modeling the HTML DOM and browser API in static analysis of JavaScript web applications, 2011 ESEC/FSE
🤷 JSFlow: Tracking Information Flow in JavaScript and its APIs, 2014 SAC
run JS in JS. track user data flow, decide if sent
Online Tracking: A 1-million-site Measurement and Analysis, 2016 CCS
⭐ Browser Feature Usage on the Modern Web, 2016 IMC
browser add feature but not remove. browser feature: n:1 map to web standard; found in Firefox WebIDL file. browser extension for instrumentation and enough 5-round user interaction. HTML&DOM API most prominent; Beacon for tracking; hardware access, storage. dataset: Web API usage in the Alexa 10k
🙅 JSgraph: Enabling Reconstruction of Web Attacks via Efficient Tracking of Live In-Browser JavaScript Executions, 2018 NDSS
instrument Blink&V8 via hook. record DOM change+navigation. reconstruct web attack, flowchart viz
⭐ VisibleV8: In-browser Monitoring of JavaScript in the Wild, 2019 IMC
VisibleV8, maintained, instrument V8. Tracking JS w/ JS can be spotted.
Hiding in Plain Site: Detecting JavaScript Obfuscation through Concealed Browser API Usage, 2020 IMC
Jalangi: A Selective Record-Replay and Dynamic Analysis Framework for JavaScript, 2013 ESEC/FSE
👎 UXJs: Tracking and Analyzing Web Usage Information With a Javascript Oriented Approach, 2020 IEEE Access
track user to analyze UX. poorly written.
FV8: A Forced Execution JavaScript Engine for Detecting Evasive Techniques, 2024 USENIX Security
Last edited:
Execution
Crawling
- Test VV8.
- Docker just works.
- Log format in
tests/README.md. Need parser. They havepost-processor/but too specific.- Write log parser library in Rust.
- Does https://github.com/wspr-ncsu/visiblev8-crawler work?
- Over-engineered. Would prefer simpler single script than this monstrosity of SQLite, Celery, Mongo, and PostgreSQL.
- Runs Puppeteer eventually (
crawler.js). ⇒ Let’s just use Puppeteer’s successor, Playwright.- Figure out Playwright.
- Prevent being blocked by USC OIT: Ask John/ add link to research description page in
User-Agent.
- Make Playwright and monkey testing work.
- Mounting: write directly to
headless_browser/target/on host.- Need sysadmin capability & root in Docker to run Playwright & create directory, or else spurious error.
- Need
sudo setenforce 0for Fedora due to SELinux.
- File management: each site has own directory by
encodeURIComponent(url), under which;- share browser cache in
user_data/; - each (
Nout of 0~4) trial launch separate VV8 and write:$N/vv8-*.log$N.harreachable$N.json
- share browser cache in
- Disable content security policy (CSP) for
eval. -
Prevent navigation.Go back in browser history immediately when navigating.-
Browser bug: sometimes go back too much toDetect if page has horde onabout:blank.loadevent, and reload if not. [ ] Fewer navigation when headless??- Some sites (e.g., YouTube) change URL w/o navigation; cannot do anything about them.
-
- Visit 3 + 9 clicked pages like Snyder did.
- Some secondary URLs’ host name vary by
www.prefix, e.g., google.com. - Split out each visit to separate browser page, so that each VV8 log can be split by when gremlins is injected into “loading” vs “interacting”.
- Save space: remove
user_data/after all trials. - Crawl only 100 first
- Mounting: write directly to
Analyze API call traces
- Separate site load & interaction
- Make single gremlins injection split each VV8 log into a part w/o interaction and a part w/ interaction: separate browser page for each load.
- When aggregating record, split by gremlins injection in VV8 log.
- Find anchor APIs, the most popular APIs overall and per script.
- Filter out most internal, user-defined, and injected calls.
- Analysis of API popularity in
popular_api_calls_analysis.md.- Tail-heavy distribution: It takes 1.75% (318) APIs to cover 80% of all API calls, and 3.74% (678.0) APIs to cover 90%.
- Many calls before interaction begin.
- DOM & event APIs dominate absolute counts.
- Popularity per script is useless.
- APIs called out in the proposal are somewhat popular.
- Pick manually among 678 APIs that make up 90% of calls, details in
notable_apis.md.
- Figure out frontend interaction/ DOM element generation API classification
HTMLDocument.createElementbefore interaction is clearly DOM element generation.- Various
addEventListenercalls are frontend processing. - More potential heuristics in
notable_apis.md. - We only somewhat know what spheres a script belongs to, but how do we know it does not belong to another sphere?
- We can probably only claim we detect which sphere.
- Split script to fine-grained!!
-
evalperfunctionchunk of 1kB code. Details ineval_trick.md.
-
Log file interpretation
VV8 creates a log file per thread, roughly equivalent to a browser page we create plus some junk background workers. Each of $N/vv8-*.log contains:
- Before gremlins injection:
- JS contexts created & their source code.
- API calls in each context.
- Guaranteed not for interactions.
- After gremlins injection:
- All of the above, but may be for interactions.
Observations when manually inspecting aggregated logs for YouTube
Details in youtube_scripts_api_calls_overview.md.
- Strong indicators: popular APIs like
addEventListenerandappendChildstrongly indicate specific spheres. - API pollution:
getting and setting custom attributes onwindow, etc. are recorded, but they are not browser APIs.Functions generally seem more useful because we can and do filter out user-defined ones.- Largely dealt with by filtering by API names (alphanumeric or space, at least 3 characters for
this, 2 characters forattr, at most 3 consecutive number).
- Largely dealt with by filtering by API names (alphanumeric or space, at least 3 characters for
- Useless information:
getting and setting fromwindow, callingArray, etc. generally means nothing. API types (function, get, etc.) also seem useless once we considerthisandattr.- Just track anchor APIs and pick Function over Get for anchor APIs.
- Difficult scripts: some scripts only call a few APIs, so they are difficult to classify.
- Do we care about every script or just big ones or just ones that call many APIs?
- Many scripts are in the HTML, so how to aggregate their stats over the 5 trials?
- Aggregate multiple runs of same scripts.
Classification heuristics
By manually inspecting the 678 most popular APIs that make up 90% of all API calls in the top 100 sites, we spot “anchor” APIs (list in notable_apis.md). See the classification results in classification_results.md.
Certain indicators
- Frontend processing
- Get
.*Event,Location(some attributes),HTML(Input|TextArea)Element.(value|checked) - Function
addEventListener,getBoundingClientRect- These can also be used to trigger DOM element generation?
- Set
textContentand anything onURLSearchParams,DOMRect,DOMRectReadOnly
- Get
- DOM element generation, before interaction begins
- Function
createElement,createElementNS,createTextNode,appendChild,insertBefore,CSSStyleDeclaration.setProperty - Set
CSSStyleDeclaration,style
- Function
- UX enhancement
- Function
removeAttribute,matchMedia,removeChild,requestAnimationFrame,cancelAnimationFrame,FontFaceSet.load,MediaQueryList.matches - Set
hidden,disabled
- Function
- Extensional features
Performance,PerformanceTiming,PerformanceResourceTiming,Navigator.sendBeacon
Intermediate indicators
XMLHttpRequest(andWindow.fetch): send/fetch data from server, one of:- Form submission, CRUD → frontend processing.
- Auth, tracking, telemetry → extensional features.
- Load data onto page → DOM element generation (but will be detected through other API calls)?
SVGGraphicsElementsubclasses and canvas elements: graphics for UX enhancement, but you can render them and send SVG, so maybe DOM element generation?CSSStyleRule,CSSRuleList: UX enhancement or DOM element generation.Window.scrollY: UX enhancement or frontend processing.
Uncertain indicators
querySelector[All],getElement[s]By.*: get a node, but then what?.*Element’scontains,matches: search for a node or string, but then what?Storage,HTMLDocument.cookie: local storage, but then what?DOMTokenList: store/retrieve info on node, but then what?IntersectionObserverEntry: viewport and visibility, but then what?ShadowRoot: web components, but then what?Crypto.getRandomValuesframes: iframes
Deferred
- Would like
- Clean up the APIs better.
- Separate out the 5 trials.
- Save space: compress logs.
- Proper logging.
- Checkpointing and resuming.
- Concatenate
chrome.1,chrome.2and other such logs after their previous logs (chrome.0) when analyzing to avoid unknown execution context ID.
- Just thoughts
- If top 1000 sites yield poor results, try sampling other sites.
- Targeted event listener tests instead of chaos testing?
Last edited:
Notable APIs
Out of 678 most popular APIs, which takes up 90% of all API calls in the top 100 sites:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
16281 Function HTMLDivElement matches 843 835 1115182 1064906 4.807023 6.144259 2.282807 2.758132 95.491678
3621 Get TransitionEvent target 326 326 884580 883460 3.460662 5.166294 5.826075 6.594800 99.873386
9483 Function HTMLDivElement querySelector 1871 1647 847881 808260 1.416274 2.079385 2.040353 1.344933 95.327057
3378 Function CustomElementRegistry get 101 71 828723 806370 12.442614 13.151448 5.779473 2.220260 97.302718
14414 Get Event target 2002 1903 824110 783286 1.179062 1.482671 4.650736 5.382586 95.046292
16594 Function Performance now 2764 2340 624855 498159 0.960439 1.144829 3.490532 3.096365 79.723936
13516 Get Window location 9423 7181 579071 319716 0.664399 0.615618 6.606676 4.230041 55.211882
16209 Function HTMLDivElement querySelectorAll 2294 2227 574049 442116 0.767773 0.923417 1.696780 1.783361 77.017119
5904 Get HTMLDivElement classList 2137 1910 435096 351005 0.811707 0.916675 2.908658 2.905556 80.673001
17431 Get HTMLDocument nodeType 1153 969 419956 348949 0.773276 0.978419 1.682256 1.831237 83.091800
11333 Function HTMLDivElement closest 1111 1109 415799 62022 1.477813 0.420875 2.660322 3.038853 14.916342
5142 Get Event keyCode 1147 1147 376969 361243 0.682080 0.925483 2.624004 9.471046 95.828304
14908 Get Event key 790 786 344674 329328 0.900894 1.128496 2.078672 4.175591 95.547677
4078 Function HTMLDivElement contains 542 535 303535 254118 0.702358 0.960562 1.509068 3.241954 83.719505
5498 Get HTMLDivElement className 904 870 299901 263160 0.837205 1.027364 2.385866 2.627550 87.748957
2457 Get Window getComputedStyle 1535 1310 295456 159215 0.592931 0.438401 1.151197 0.846097 53.887889
2014 Function HTMLDocument createElement 9320 6330 286107 122524 0.296257 0.219127 2.612151 0.967649 42.824538
9545 Get Event which 455 454 263921 248376 0.621834 0.818845 1.011871 1.339680 94.109980
7048 Function HTMLDivElement addEventListener 2514 2184 252068 107180 0.391858 0.234839 2.477123 1.046851 42.520272
9862 Get HTMLAnchorElement nodeType 1250 1203 250886 102360 0.416466 0.238107 0.954481 0.410062 40.799407
7499 Get MouseEvent target 2602 2602 243446 243446 0.353644 0.459806 2.971607 4.680082 100.000000
3346 Get DOMRect top 1266 1213 227425 144601 0.468570 0.443659 1.414995 1.919121 63.581840
5732 Function HTMLDocument querySelectorAll 4647 3765 223991 187374 0.332157 0.412884 1.507670 0.883315 83.652468
8406 Get Window performance 3257 2539 223517 126555 0.347078 0.293616 2.802016 1.382159 56.619854
4999 Get ImageData data 22 12 218417 17777 14.651612 16.882722 6.550062 2.413431 8.139018
16481 Get DOMRect left 1177 1134 212885 126981 0.441333 0.387885 1.458221 1.986245 59.647697
11541 Function DOMTokenList contains 1919 1724 210971 141308 0.421512 0.391151 2.304020 2.127485 66.979822
3329 Get Event ctrlKey 543 533 209527 208734 0.494948 0.654059 1.262094 3.066172 99.621528
14621 Get Event timeStamp 1033 944 203949 199608 0.405411 0.522149 0.740702 0.852084 97.871527
4138 Get Event changedTouches 412 408 195658 195448 0.507606 0.648649 1.343745 1.961513 99.892670
10053 Get HTMLSpanElement tagName 702 663 193630 81431 0.472738 0.266883 1.569983 0.315915 42.054950
2996 Get HTMLDocument cookie 5578 4147 172695 110544 0.324422 0.336975 7.789128 2.641675 64.011118
7105 Get Event defaultPrevented 714 690 171461 167435 0.374097 0.499074 0.737214 0.976114 97.651944
6714 Get HTMLSpanElement style 548 504 167025 11671 0.517220 0.051895 3.090145 1.050911 6.987577
968 Get HTMLAnchorElement href 2456 2328 145107 135169 0.502295 0.942538 1.435041 1.251417 93.151261
4177 Get Performance timing 1679 1332 143633 127130 0.302955 0.382869 2.240215 0.829030 88.510301
14823 Function Window getComputedStyle 1697 1384 143326 75800 0.299979 0.220471 1.873741 2.419006 52.886427
7305 Get HTMLMetaElement dataset 335 295 142890 130639 0.982850 3.175198 1.974473 0.559279 91.426272
12098 Get PerformanceTiming navigationStart 1421 1228 136193 124766 0.302260 0.397229 1.608191 0.654052 91.609701
14284 Get MutationRecord target 114 109 136183 124456 2.137970 2.359855 2.534340 4.659148 91.388793
1861 Get HTMLAnchorElement addEventListener 1370 1178 131340 29593 0.307599 0.098327 7.717213 0.833458 22.531597
10400 Get Event metaKey 528 518 128645 128019 0.305513 0.402858 1.198076 3.016747 99.513390
4750 Get Event shiftKey 491 481 126416 125790 0.300380 0.396070 0.798485 1.127302 99.504810
15693 Get Window history 1452 1223 123512 37555 0.255723 0.114506 0.727469 0.699028 30.405952
5048 Get Event altKey 556 551 123345 122726 0.288138 0.378780 1.216686 2.985656 99.498156
2211 Get Window addEventListener 7893 6191 122537 31256 0.140030 0.056707 2.405811 0.710843 25.507398
13441 Get IntersectionObserverEntry boundingClientRect 135 118 121778 115749 2.683412 2.996992 0.959645 1.765307 95.049188
15065 Get Event relatedTarget 354 340 120531 119802 0.354351 0.449621 0.857684 1.087789 99.395176
595 Function HTMLAnchorElement isSameNode 30 30 117855 117855 8.029145 12.948267 7.101826 11.841353 100.000000
911 Function HTMLElement getAttribute 902 860 117772 31042 0.206437 0.074248 0.942646 0.938351 26.357708
12704 Function Storage setItem 2530 2151 117494 100433 0.229494 0.285617 1.399357 0.855013 85.479259
4182 Get Event touches 104 104 117488 117488 1.273323 1.823082 4.985049 5.382803 100.000000
3222 Get Event button 237 228 115014 114410 0.373357 0.467717 1.213677 1.483833 99.474847
8221 Get Event pointerType 215 211 113740 113504 0.392012 0.482340 1.327292 1.639816 99.792509
18 Get Event charCode 234 234 111544 110954 0.343765 0.432244 1.156061 1.442831 99.471061
3947 Function HTMLAnchorElement setAttribute 1354 1154 110406 80822 0.276005 0.419018 1.176040 0.787740 73.204355
15997 Get HTMLDivElement dataset 1019 941 110241 58327 0.305932 0.209428 2.886125 1.568396 52.908627
7327 Get HTMLDocument createElementNS 797 672 110043 29138 0.713621 0.383323 1.456620 0.289284 26.478740
15619 Function HTMLDocument querySelector 5256 3878 109894 70588 0.143162 0.159666 5.420111 2.722504 64.232806
14249 Get HTMLElement contains 156 155 109845 6882 0.529747 0.077596 1.327992 0.179596 6.265192
16323 Get CSSStyleDeclaration position 341 315 106935 93720 0.345195 0.415523 0.474251 0.340467 87.642026
4579 Get PerformanceResourceTiming name 459 421 104968 48263 0.501391 0.351048 7.462511 6.226703 45.978774
11476 Function DocumentFragment appendChild 555 540 103875 94235 0.567692 0.809485 2.425293 3.739579 90.719615
17561 Get HTMLDivElement removeEventListener 269 261 102308 93036 0.367874 0.461578 0.433881 0.630124 90.937170
14811 Function HTMLInputElement matches 120 120 101906 101899 0.937924 1.010790 1.194562 1.553083 99.993131
2818 Get IntersectionObserverEntry isIntersecting 835 815 100920 74725 0.674087 0.814893 5.613972 7.372370 74.043797
10958 Get MutationRecord attributeName 89 81 100443 98200 1.816932 1.910443 13.742685 17.799135 97.766893
15809 Function HTMLAnchorElement removeAttribute 373 347 99233 96946 1.153120 1.474503 0.726152 0.792383 97.695323
8141 Get Event pointerId 203 199 98769 98559 0.355878 0.442541 1.309350 1.638151 99.787383
9253 Get Event state 203 199 98769 98559 0.355878 0.442541 1.309350 1.638151 99.787383
15723 Get Event pageX 337 333 95672 95055 0.270339 0.381892 0.936991 1.368982 99.355088
17872 Get Event pageY 337 333 95672 95055 0.270339 0.381892 0.936991 1.368982 99.355088
1914 Function HTMLBodyElement appendChild 2017 1641 95122 87854 0.192521 0.238969 2.019357 1.951309 92.359286
66 Get DOMRect bottom 718 690 94763 38693 0.584749 0.580383 1.550073 2.244249 40.831337
1215 Get HTMLDivElement textContent 815 784 93982 72828 0.622264 0.822394 1.921985 1.384557 77.491435
15126 Get Window Reflect 815 650 93695 985 0.227729 0.003498 1.616386 0.718477 1.051283
6681 Get HTMLDocument getElementsByTagName 4894 3152 91115 76951 0.158297 0.196486 2.076936 0.360218 84.454810
6007 Function HTMLDivElement appendChild 2328 2052 87416 23624 0.157654 0.065366 2.490404 1.678324 27.024801
14338 Get Event clientY 227 223 86343 85736 0.274052 0.346012 1.155634 1.443879 99.296990
7370 Get Event clientX 223 219 86333 85726 0.274112 0.346119 1.174707 1.468122 99.296908
4883 Get HTMLAnchorElement classList 871 842 84332 70097 0.201348 0.278285 2.291487 2.019763 83.120286
16115 Get MouseEvent type 755 755 83349 83349 0.168377 0.221242 1.248696 1.422853 100.000000
6772 Get HTMLDocument hidden 1603 1537 82147 47474 0.200568 0.175928 1.534644 2.676095 57.791520
8011 Function EventTarget dispatchEvent 110 110 81800 63914 0.311552 0.299519 0.360584 0.373508 78.134474
12711 Function HTMLDocument getElementById 5559 3690 81282 42177 0.114240 0.095513 6.735331 2.271519 51.889717
11100 Function HTMLDivElement getBoundingClientRect 1295 1148 81101 61989 0.178199 0.207279 1.526008 1.561731 76.434323
2723 Function Storage getItem 4445 3465 80359 53636 0.111631 0.125812 2.384386 1.275023 66.745480
17488 Get HTMLAnchorElement disabled 42 42 79569 79569 2.102839 2.148920 1.905932 1.917607 100.000000
8714 Construction Event None 641 543 79374 63053 0.198452 0.214734 1.748308 0.696653 79.437851
5616 Function HTMLAnchorElement addEventListener 1346 1174 77789 18943 0.184291 0.063770 6.796528 0.760201 24.351772
611 Get HTMLElement addEventListener 755 743 77573 2900 0.456644 0.026392 1.805401 1.324329 3.738414
17667 Get Performance timeOrigin 638 498 77460 75360 0.467205 0.675298 0.726314 0.243126 97.288923
9166 Get Window requestAnimationFrame 1735 1609 77177 30706 0.153209 0.090460 2.655344 3.087896 39.786465
2338 Get Event screenY 208 204 76925 76328 0.269005 0.342615 1.238773 1.549703 99.223919
9977 Get Event screenX 208 204 76925 76328 0.269005 0.342615 1.238773 1.549703 99.223919
2418 Function HTMLBodyElement removeChild 667 517 76466 75216 0.460771 0.746417 1.423947 0.993174 98.365287
10247 Get HTMLBodyElement constructor 37 37 75365 32587 2.267393 2.680637 2.514466 2.597025 43.238904
14409 Function DOMTokenList add 2140 1859 75038 50171 0.119709 0.129215 2.026993 1.599572 66.860791
1353 Get DOMRect width 898 766 73558 50213 0.191047 0.175964 1.478908 1.038934 68.263139
8987 Get DOMRect right 721 696 72803 18396 0.448942 0.269434 0.867479 1.108576 25.268189
17217 Get Window matchMedia 1611 1379 72404 20964 0.157922 0.062416 2.640280 2.069632 28.954201
9493 Set Event flow 121 121 72147 57173 0.262724 0.259411 0.292955 0.308683 79.245152
3085 Get Event offsetX 155 155 70920 70340 0.249699 0.317938 0.758509 0.929270 99.182177
4424 Get Event offsetY 155 155 70920 70340 0.249699 0.317938 0.758509 0.929270 99.182177
14697 Get HTMLLIElement querySelector 324 316 68679 57442 0.438484 0.410091 1.165981 0.755493 83.638376
4801 Get HTMLAnchorElement textContent 834 818 68587 22234 0.426822 0.236131 1.026544 0.598604 32.417222
568 Get Window removeEventListener 2851 2478 67894 22285 0.106554 0.051886 0.643697 0.698827 32.823224
12336 Get HTMLElement id 396 376 66643 6243 0.211400 0.026531 0.862097 0.147936 9.367826
16137 Get Location search 5601 4460 65008 34421 0.089337 0.081936 2.977207 2.503777 52.948868
10354 Get Location hash 1782 1382 64491 49026 0.136625 0.146484 1.765293 0.619653 76.019910
9312 Get HTMLDocument removeEventListener 1123 1024 64243 25996 0.226914 0.159079 0.461634 0.592738 40.465109
7772 Function Storage removeItem 1630 1325 62618 55509 0.145805 0.179347 1.016465 0.985584 88.647034
12900 Get IntersectionObserverEntry target 515 496 62370 50038 0.595738 0.825574 6.585918 9.794942 80.227674
13380 Get HTMLImageElement src 324 278 61949 55192 0.248963 0.279343 1.549264 0.817876 89.092641
13971 Function CSSStyleDeclaration getPropertyValue 877 850 60107 18237 0.150438 0.063671 0.519474 0.272330 30.340892
12778 Function HTMLDocument getElementsByTagName 4775 3038 60070 46347 0.104988 0.118652 2.101945 0.346168 77.154986
5032 Get MouseEvent clientY 504 504 59862 59862 0.150060 0.198041 0.564462 0.695423 100.000000
15651 Get MouseEvent clientX 502 502 59859 59859 0.150075 0.198069 0.566498 0.697981 100.000000
16479 Get HTMLScriptElement contains 50 50 59428 4725 0.497370 0.195014 0.440591 0.120095 7.950798
5017 Get HTMLDocument createEvent 946 769 58567 20951 0.453316 0.292947 1.299261 0.678529 35.772705
12149 Get Window cancelAnimationFrame 753 709 57477 16721 0.369145 0.239573 0.606008 0.692131 29.091637
18119 Function Window addEventListener 7166 5668 56988 12036 0.087308 0.031169 1.998809 0.587056 21.120236
1619 Function DOMTokenList remove 1455 1297 56450 33813 0.093652 0.088424 1.097433 1.080078 59.899026
17146 Get MouseEvent ctrlKey 568 568 54139 54139 0.134587 0.176825 0.225626 0.324791 100.000000
12805 Get HTMLLIElement classList 432 379 54046 24570 0.364803 0.213858 1.165796 0.336717 45.461274
6363 Get HTMLInputElement value 959 918 53080 43990 0.116852 0.140776 3.371986 3.226430 82.874906
4864 Function CSSStyleDeclaration setProperty 844 733 52840 21599 0.344912 0.211022 3.304432 2.357075 40.876230
13983 Get XMLHttpRequest readyState 1799 1460 52660 41546 0.117972 0.138164 2.416760 1.615187 78.894797
11621 Get HTMLScriptElement querySelectorAll 255 254 52491 7958 0.222868 0.065104 0.889439 0.412583 15.160694
17248 Get AnimationEvent target 156 154 51350 26463 0.946958 0.695481 1.293656 2.294568 51.534567
7970 Get HTMLBodyElement querySelectorAll 899 887 49554 47400 0.104660 0.162933 0.451424 0.528431 95.653227
16722 Get DOMRect height 848 728 48913 33326 0.132691 0.115341 0.943817 0.621586 68.133216
1007 Function HTMLHtmlElement contains 239 227 48804 19490 0.149274 0.077270 0.346510 0.126978 39.935251
1586 Function HTMLElement contains 156 155 48695 5210 0.234840 0.058744 0.499611 0.158083 10.699250
10761 Get HTMLLIElement matches 194 194 48675 38829 0.448194 0.417750 0.121070 0.148470 79.771957
13396 Get MouseEvent timeStamp 743 743 48631 48631 0.109854 0.142058 0.730755 1.041972 100.000000
8125 Get MouseEvent defaultPrevented 717 717 48346 48346 0.113253 0.151701 0.240732 0.434295 100.000000
5205 Function HTMLDivElement removeEventListener 260 252 47554 43494 0.170548 0.215572 0.371203 0.479496 91.462338
6411 Function HTMLAnchorElement getBoundingClientRect 315 308 45499 18954 0.178495 0.126211 0.733821 0.767323 41.658058
9289 Function HTMLLIElement querySelector 324 316 44104 34549 0.281584 0.246653 1.151900 0.741847 78.335298
10020 Set HTMLAnchorElement href 2781 2633 43452 29806 0.078498 0.084109 0.583468 0.409084 68.595232
10485 Function Performance get timing 1518 1263 42977 34680 0.093326 0.108573 2.111314 0.486240 80.694325
8749 Function HTMLBodyElement querySelectorAll 909 897 42696 40672 0.086075 0.131413 0.442494 0.518009 95.259509
10978 Function HTMLDivElement removeAttribute 960 905 42597 28256 0.141140 0.149708 0.946574 0.483958 66.333310
9128 Function Window requestAnimationFrame 1655 1422 42244 28852 0.092087 0.097062 1.884883 3.626479 68.298457
8299 Get CSSStyleDeclaration display 737 706 39290 23448 0.106862 0.085491 0.902827 1.160609 59.679308
14494 Function HTMLDocument addEventListener 5870 5040 38962 10686 0.045599 0.019454 1.434622 0.627379 27.426723
9252 Get HTMLDocument createTextNode 1377 1101 38610 13895 0.081862 0.041612 0.448151 0.128047 35.988086
1971 Get HTMLDivElement insertBefore 605 435 38586 20373 0.186160 0.143721 2.028594 0.351760 52.798943
12639 Get Location pathname 3308 3049 38557 22143 0.073938 0.063340 5.189143 6.232416 57.429261
8396 Get HTMLLIElement style 560 405 37454 20411 0.592363 0.288392 5.040646 1.269598 27.796764
14663 Function HTMLImageElement getBoundingClientRect 471 462 37376 26681 0.304719 0.304806 0.494410 0.521456 71.385381
9416 Get MouseEvent button 651 651 37270 37270 0.081775 0.105410 0.203340 0.320155 100.000000
6941 Get Text querySelectorAll 109 109 37203 9394 1.316163 0.468775 2.026148 0.726001 25.250652
2968 Set Text textContent 42 41 37094 23641 1.142186 0.933173 0.917371 0.731892 63.732679
12725 Get SVGGElement setAttribute 181 94 36915 34399 1.276700 1.692134 0.734407 0.935771 93.184342
17687 Get HTMLHeadingElement textContent 515 491 36591 22860 0.363449 0.418207 1.356123 0.986070 62.474379
1907 Get MouseEvent relatedTarget 551 551 36528 36528 0.090811 0.121204 0.181478 0.322789 100.000000
10573 Get HTMLSpanElement querySelectorAll 294 290 36423 3483 0.141920 0.025951 0.638319 0.257111 9.562639
10180 Get SVGAnimatedString animVal 141 141 35733 0 1.063953 0.000000 1.073527 0.000000 0.000000
14038 Function HTMLLIElement matches 212 212 35613 27566 0.307302 0.276173 0.174845 0.209069 77.404319
9460 Function HTMLScriptElement contains 50 50 34822 2789 0.291435 0.115110 0.290610 0.102494 8.009304
1408 Function IntersectionObserver observe 1207 1148 34729 10292 0.115662 0.055461 1.237426 0.623971 29.635175
8866 Get Event preventDefault 152 146 33383 32313 0.361916 0.420887 1.060576 2.027285 96.794776
6798 Get Event currentTarget 245 228 32970 31656 0.213604 0.257495 0.752055 1.005232 96.014559
231 Get HTMLImageElement addEventListener 593 543 32948 13187 0.164906 0.109288 0.794287 0.199816 40.023674
16132 Get MouseEvent shiftKey 568 568 32948 32948 0.081890 0.107583 0.210033 0.304548 100.000000
3772 Function HTMLElement addEventListener 750 739 32724 2545 0.183205 0.022435 1.564308 1.332341 7.777167
16218 Get DOMRectReadOnly width 171 152 32313 29120 0.920164 1.404839 1.141764 1.228964 90.118528
11062 Get Event composedPath 113 108 32060 31658 0.506599 0.618031 0.903666 1.284913 98.746101
4198 Get HTMLButtonElement addEventListener 1479 1202 31731 4233 0.076390 0.014662 1.316896 0.835040 13.340267
1721 Get HTMLFormElement nodeName 211 209 31631 25358 0.086438 0.085160 0.221656 0.229548 80.168189
3350 Get HTMLInputElement checked 346 334 31629 30890 0.325307 0.469699 0.799651 0.794651 97.663537
9717 Function HTMLDocument createTextNode 1347 1071 31621 10393 0.067451 0.031229 0.436073 0.127475 32.867398
16017 Function HTMLScriptElement querySelectorAll 265 264 31596 3200 0.122425 0.022725 0.449440 0.213413 10.127864
15776 Get Event eventPhase 314 303 31579 29878 0.163133 0.214638 0.534467 0.701922 94.613509
17500 Get HTMLDivElement scrollLeft 179 173 31301 15018 0.176875 0.124601 1.615388 0.642169 47.979298
3282 Get DOMRectReadOnly height 171 151 30922 28292 0.907513 1.425795 0.429273 0.414457 91.494729
719 Get Crypto getRandomValues 1541 1225 30435 3165 0.170737 0.033795 1.865329 0.867292 10.399211
15518 Get HTMLElement style 549 489 30418 25567 0.105885 0.125329 1.493825 0.611387 84.052206
8459 Get HTMLAnchorElement removeEventListener 163 163 30074 26586 0.212811 0.252762 10.830490 33.543656 88.401942
5743 Get Event isTrusted 296 286 29859 28557 0.231935 0.348898 0.525885 0.706710 95.639506
13864 Get HTMLDocument getElementsByClassName 1339 1087 29724 9286 0.081348 0.035449 1.980805 0.892173 31.240748
553 Function HTMLDivElement insertBefore 590 435 29696 15125 0.137121 0.100618 1.936143 0.295648 50.932786
11456 Set CSSStyleDeclaration display 2158 1870 29629 20599 0.057507 0.064276 1.980954 1.334224 69.523102
11506 Get Event composed 198 193 29307 28905 0.412240 0.484833 1.555166 2.268116 98.628314
13010 Set CSSStyleDeclaration height 1003 833 29251 24464 0.069698 0.081981 0.304656 0.070588 83.634748
12834 Get MouseEvent metaKey 568 568 28631 28631 0.071161 0.093487 0.206934 0.300433 100.000000
4164 Function URLSearchParams get 1828 1560 28238 17025 0.108924 0.145465 2.392487 1.587353 60.291097
13685 Get MouseEvent which 422 422 27894 27894 0.078999 0.110417 0.613775 0.847804 100.000000
12006 Get HTMLAnchorElement contains 78 77 27892 6093 0.214739 0.199062 0.406560 0.474514 21.844973
8914 Get MouseEvent altKey 541 541 27876 27876 0.069528 0.091297 0.188469 0.273704 100.000000
15714 Get HTMLScriptElement matches 13 13 27112 8121 0.447334 0.144384 0.204745 0.068769 29.953526
6813 Get HTMLScriptElement querySelector 5 5 27016 8111 0.470368 0.146231 0.487683 0.159742 30.022949
10796 Get HTMLHtmlElement scrollLeft 686 674 26980 24978 0.066215 0.087673 0.352541 0.608070 92.579689
5832 Get HTMLAnchorElement querySelectorAll 182 181 26790 7994 0.182795 0.191212 0.719168 0.296390 29.839492
5335 Get ShadowRoot host 27 23 26450 18481 3.353093 3.789404 2.990668 2.523576 69.871456
8265 Get MouseEvent screenX 432 431 26156 26155 0.074340 0.100463 0.187035 0.281187 99.996177
2495 Get MouseEvent screenY 430 430 26154 26154 0.074335 0.100459 0.182993 0.279588 100.000000
11802 Function HTMLDocument createElementNS 870 748 25562 7929 0.173085 0.106273 1.088253 0.170741 31.018700
1271 Function HTMLImageElement addEventListener 585 539 25288 11160 0.128254 0.094256 0.826761 0.479900 44.131604
8172 Set HTMLDocument cookie 2810 2376 25002 15393 0.057419 0.058849 5.065215 0.855618 61.567075
1117 Get HTMLLIElement querySelectorAll 428 283 24763 6135 0.117284 0.058253 0.788971 0.077840 24.774866
10647 Get PerformanceResourceTiming responseEnd 271 247 23874 7791 0.312687 0.302471 1.978660 1.709044 32.633828
4216 Get MessageEvent data 908 677 23826 9579 0.240720 0.147865 5.398752 5.537861 40.203979
1279 Function HTMLAnchorElement contains 78 77 23764 5635 0.182958 0.184099 0.389154 0.470281 23.712338
2717 Get MouseEvent pointerType 210 210 23241 23241 0.082687 0.102711 0.464080 0.477471 100.000000
14151 Get HTMLDocument scrollingElement 594 582 23040 21476 0.072746 0.086050 0.213598 0.306672 93.211806
6381 Get MouseEvent offsetX 199 199 22993 22993 0.081879 0.104333 0.313116 0.427567 100.000000
10351 Get MouseEvent offsetY 199 199 22993 22993 0.081879 0.104333 0.313116 0.427567 100.000000
12434 Get HTMLTextAreaElement value 142 138 22946 22587 0.084866 0.104089 1.192374 1.197698 98.435457
16255 Function HTMLBodyElement contains 370 207 22532 16616 0.078523 0.077264 0.180246 0.080905 73.744009
1345 Get MouseEvent keyCode 238 238 22474 22474 0.080439 0.102588 0.282488 0.310556 100.000000
13718 Get MouseEvent charCode 193 193 22411 22411 0.080467 0.102558 0.311932 0.327368 100.000000
699 Get HTMLElement textContent 404 394 22233 3757 0.205046 0.063767 0.561368 0.158516 16.898304
1513 Get Window origin 1289 1101 22169 14509 0.202095 0.240889 1.286647 1.650455 65.447246
7132 Get HTMLStyleElement querySelectorAll 72 71 22038 1311 0.120812 0.015140 0.152180 0.047534 5.948816
7770 Get MouseEvent changedTouches 195 195 21964 21964 0.084084 0.106469 0.323369 0.343555 100.000000
7877 Get DOMRectReadOnly top 113 103 21890 20279 0.536787 0.543799 0.366536 0.480785 92.640475
6873 Get MouseEvent state 182 182 21823 21823 0.085844 0.109151 0.329381 0.344476 100.000000
15423 Get MouseEvent key 182 182 21823 21823 0.085844 0.109151 0.329381 0.344476 100.000000
16195 Get MouseEvent pointerId 182 182 21823 21823 0.085844 0.109151 0.329381 0.344476 100.000000
13022 Get Window frames 1252 1002 21647 5991 0.324448 0.207435 1.437239 0.732157 27.675890
6517 Get HTMLElement querySelectorAll 838 778 21615 8622 0.042891 0.026701 0.216786 0.176318 39.888966
4622 Get CustomEvent detail 525 494 21581 15168 0.351925 0.305029 1.007954 1.372400 70.284046
8544 Get HTMLButtonElement removeAttribute 415 345 21581 17502 0.153523 0.185642 0.739158 0.096874 81.099115
9282 Function HTMLButtonElement addEventListener 1475 1215 21572 3449 0.048451 0.011562 1.259833 0.811528 15.988318
10098 Get Event bubbles 311 300 21248 19547 0.155065 0.231605 0.484210 0.652921 91.994541
9949 Get Event cancelable 304 293 21215 19514 0.155911 0.233246 0.495045 0.667662 91.982088
258 Set CSSStyleDeclaration position 1192 969 21109 2744 0.052430 0.009619 0.507048 0.181102 12.999195
16455 Get Window scrollY 748 732 21054 20005 0.074004 0.097788 2.101091 4.300151 95.017574
3841 Function HTMLAnchorElement matches 428 421 20814 16177 0.090471 0.146241 0.495322 0.483386 77.721726
382 Get DOMRectReadOnly left 20 10 20755 19340 1.656417 1.796056 1.046280 1.309103 93.182366
14538 Function HTMLAnchorElement querySelectorAll 192 191 20666 5916 0.122200 0.097969 0.640198 0.272638 28.626730
1555 Get HTMLLIElement addEventListener 394 377 20635 1059 0.206049 0.015210 0.370146 0.058123 5.132057
15370 Function SVGPathElement setAttribute 472 368 20615 7684 0.211360 0.153777 1.324606 0.119985 37.273830
17625 Get DOMRectReadOnly bottom 10 9 20314 19277 1.565912 1.689944 1.043303 1.630184 94.895146
5853 Get DOMRectReadOnly right 8 7 20299 19263 1.694730 1.794396 1.301227 2.033126 94.896300
12959 Set CSSStyleDeclaration left 565 532 20098 2004 0.078073 0.011633 0.940909 0.591199 9.971141
4017 Function HTMLSpanElement querySelectorAll 304 300 20086 1848 0.071940 0.012095 0.336692 0.147938 9.200438
13605 Function HTMLDivElement removeChild 937 886 19958 6750 0.065481 0.035759 0.432451 0.263485 33.821024
4899 Get CSSStyleRule selectorText 98 95 19820 117 0.075323 0.000551 0.413574 0.001181 0.590313
14550 Set CSSStyleDeclaration width 1292 1097 19640 8521 0.065403 0.042337 1.446305 0.382616 43.385947
1409 Get HTMLSpanElement matches 119 118 19621 13586 0.095171 0.135756 0.060798 0.057475 69.242139
8499 Get SVGGElement appendChild 185 98 19413 392 0.550612 0.014762 2.657822 0.131523 2.019265
6959 Function HTMLElement querySelectorAll 844 784 19393 6851 0.036904 0.020121 0.208905 0.170334 35.327180
8445 Function HTMLLIElement querySelectorAll 429 284 19386 4685 0.090873 0.043728 0.770231 0.074259 24.166925
10151 Get HTMLSpanElement querySelector 195 150 19255 13171 0.165161 0.129837 1.334592 0.095666 68.403012
4938 Get PerformanceResourceTiming transferSize 251 243 19084 7794 0.217156 0.208775 1.392484 0.983322 40.840495
10597 Get HTMLAnchorElement appendChild 439 317 18979 6710 0.149446 0.082790 0.773147 0.377680 35.354866
13911 Function CSSRuleList item 5 5 18806 18806 1.929088 1.929088 1.933220 1.933220 100.000000
2730 Get MediaQueryList matches 1294 1115 18660 6449 0.108481 0.056959 2.218405 1.270101 34.560557
1674 Get DocumentFragment appendChild 565 548 18600 8016 0.093284 0.063870 0.311641 0.220411 43.096774
2046 Get HTMLTextAreaElement style 98 98 18491 18281 0.078172 0.098089 1.132860 1.119545 98.864312
2755 Get XMLHttpRequest responseText 1804 1432 18385 15141 0.042540 0.051085 0.746252 0.516296 82.355181
16467 Get PerformanceResourceTiming duration 263 238 18315 8300 0.179272 0.172481 0.596822 0.566587 45.318045
6253 Get SVGPathElement attributes 198 197 18189 5025 0.211708 0.111967 0.309853 0.057502 27.626587
10388 Get HTMLLIElement appendChild 171 164 18164 5593 0.272864 0.173562 0.932245 0.341723 30.791676
1263 Get HTMLParagraphElement textContent 525 510 18148 8969 0.170347 0.173469 0.685390 0.522630 49.421424
13664 Get XMLHttpRequest status 1784 1454 18146 14144 0.037343 0.044292 1.521811 1.169566 77.945553
13766 Function Storage key 140 133 18102 15314 0.069092 0.073161 1.802729 0.917468 84.598387
Last edited:
Analysis of popular API calls
We aggregated data for all API calls, filtering out user-defined functions and other irrelevant data as possible. Results are in data/api_calls.csv and analyzed in data/src/data/api_calls.py.
Columns
api_type: The type of API call—Get, Set, Function, or Construction.this: The object the API is called on, may be empty for static functions.attr: The attribute or method being called, may be empty.appear: How many scripts the API call appears in.appear_interact: How many scripts the API call appears in after interaction started.total: How many times the API call is made.interact: How many times the API call is made after interaction started.%total/total: The percentage out of all API calls in the scripts the API appear in.%interact/interact: The percentage out of all API calls after interaction in the scripts the API appear in.avg%total/script: The average percentage per script.avg%interact/script: The average percentage per script after interaction.%interact/total: The percentage of calls after interaction out of all calls.
Overall, data are tail-heavy, aligning with prior observations:
In [2]: df.describe()
Out[2]:
appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
count 18120.000000 18120.000000 1.812000e+04 1.812000e+04 18120.000000 15662.000000 18120.000000 18120.000000 18120.000000
mean 83.331733 71.206733 6.331973e+03 3.842462e+03 0.927087 0.530690 1.367818 0.515940 39.876583
std 348.429012 279.559604 8.239731e+04 5.046730e+04 6.230344 3.780852 6.853030 2.822503 40.950548
min 1.000000 0.000000 1.000000e+00 0.000000e+00 0.000087 0.000000 0.000088 0.000000 0.000000
25% 4.000000 2.000000 5.000000e+00 0.000000e+00 0.007226 0.000000 0.016281 0.000000 0.000000
50% 7.000000 5.000000 2.300000e+01 5.000000e+00 0.036847 0.008031 0.095799 0.005917 23.913043
75% 35.000000 30.000000 2.650000e+02 8.225000e+01 0.178863 0.092942 0.512494 0.167178 83.026494
max 9957.000000 7181.000000 6.542023e+06 3.267748e+06 100.000000 100.000000 100.000000 100.000000 100.000000
Call distribution
From the CCDF of number of calls per API, we can see that 0.1% of APIs (18) are called over 1,000,000 times, massively outnumbering other APIs. There is also a 2-4 time gap between total API calls and API calls after interaction began, signalling a large number of API calls before interaction (precisely, 45,109,934 before vs 69,625,413 after).
Note: this graph uses the total and interact columns.
To find how many APIs need to be investigated to cover 90% of all API calls, we plot the CDF of the fractions of API calls vs fractions of APIs:
It takes 1.75% (318) APIs to cover 80% of all API calls, and 3.74% (678.0) APIs to cover 90%.
Top 20 API calls overall
As a rough look, we sample the top 20 API calls based on various metrics.
The most called APIs are mainly DOM-related, including many “get” calls on on HTMLDocument or HTMLDivElement and a few functions. The results are similar for calls made after interaction began.
In [3]: df.nlargest(20, "appear")
Out[3]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
12035 Get HTMLDocument createElement 9957 6827 386183 160286 0.383050 0.272003 2.670769 0.975292 41.505193
13516 Get Window location 9423 7181 579071 319716 0.664399 0.615618 6.606676 4.230041 55.211882
2014 Function HTMLDocument createElement 9320 6330 286107 122524 0.296257 0.219127 2.612151 0.967649 42.824538
2211 Get Window addEventListener 7893 6191 122537 31256 0.140030 0.056707 2.405811 0.710843 25.507398
18119 Function Window addEventListener 7166 5668 56988 12036 0.087308 0.031169 1.998809 0.587056 21.120236
241 Get Navigator userAgent 6996 5088 142782 58271 0.173377 0.112728 5.145219 2.053937 40.811167
5125 Get Window document 6890 5156 280870 131302 0.349732 0.245301 2.341958 1.213727 46.748318
9201 Function Window setTimeout 6789 5622 774630 688808 0.847538 1.324614 3.571197 3.203018 88.920904
1990 Get HTMLDocument body 6479 5167 364548 234641 0.378641 0.399859 2.522424 1.552503 64.364912
2370 Get HTMLDocument addEventListener 6238 5288 106708 34235 0.119114 0.059167 1.832010 0.636335 32.082880
15595 Get Window navigator 6201 4558 268025 98575 0.384988 0.216489 4.785670 1.907738 36.778286
2129 Get HTMLDocument documentElement 6129 4566 348638 220531 0.365681 0.365297 3.225033 1.109748 63.255009
14494 Function HTMLDocument addEventListener 5870 5040 38962 10686 0.045599 0.019454 1.434622 0.627379 27.426723
7915 Get Location href 5824 4561 210402 135381 0.291802 0.297886 2.584136 2.093848 64.343970
16137 Get Location search 5601 4460 65008 34421 0.089337 0.081936 2.977207 2.503777 52.948868
14177 Get HTMLDocument getElementById 5600 3731 145667 67289 0.202675 0.151724 6.768832 2.289762 46.193716
2996 Get HTMLDocument cookie 5578 4147 172695 110544 0.324422 0.336975 7.789128 2.641675 64.011118
12711 Function HTMLDocument getElementById 5559 3690 81282 42177 0.114240 0.095513 6.735331 2.271519 51.889717
13966 Get HTMLDocument querySelector 5470 4069 214306 135242 0.261517 0.286668 5.343761 2.736037 63.106959
15619 Function HTMLDocument querySelector 5256 3878 109894 70588 0.143162 0.159666 5.420111 2.722504 64.232806
In [4]: df.nlargest(20, "appear_interact")
Out[4]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
13516 Get Window location 9423 7181 579071 319716 0.664399 0.615618 6.606676 4.230041 55.211882
12035 Get HTMLDocument createElement 9957 6827 386183 160286 0.383050 0.272003 2.670769 0.975292 41.505193
2014 Function HTMLDocument createElement 9320 6330 286107 122524 0.296257 0.219127 2.612151 0.967649 42.824538
2211 Get Window addEventListener 7893 6191 122537 31256 0.140030 0.056707 2.405811 0.710843 25.507398
18119 Function Window addEventListener 7166 5668 56988 12036 0.087308 0.031169 1.998809 0.587056 21.120236
9201 Function Window setTimeout 6789 5622 774630 688808 0.847538 1.324614 3.571197 3.203018 88.920904
2370 Get HTMLDocument addEventListener 6238 5288 106708 34235 0.119114 0.059167 1.832010 0.636335 32.082880
1990 Get HTMLDocument body 6479 5167 364548 234641 0.378641 0.399859 2.522424 1.552503 64.364912
5125 Get Window document 6890 5156 280870 131302 0.349732 0.245301 2.341958 1.213727 46.748318
241 Get Navigator userAgent 6996 5088 142782 58271 0.173377 0.112728 5.145219 2.053937 40.811167
14494 Function HTMLDocument addEventListener 5870 5040 38962 10686 0.045599 0.019454 1.434622 0.627379 27.426723
2129 Get HTMLDocument documentElement 6129 4566 348638 220531 0.365681 0.365297 3.225033 1.109748 63.255009
7915 Get Location href 5824 4561 210402 135381 0.291802 0.297886 2.584136 2.093848 64.343970
15595 Get Window navigator 6201 4558 268025 98575 0.384988 0.216489 4.785670 1.907738 36.778286
16137 Get Location search 5601 4460 65008 34421 0.089337 0.081936 2.977207 2.503777 52.948868
8169 Get Location hostname 4968 4176 136629 68568 0.429844 0.370961 4.515706 3.713880 50.185539
2996 Get HTMLDocument cookie 5578 4147 172695 110544 0.324422 0.336975 7.789128 2.641675 64.011118
13966 Get HTMLDocument querySelector 5470 4069 214306 135242 0.261517 0.286668 5.343761 2.736037 63.106959
7130 Get NodeList length 4664 4065 2382138 1072590 2.861152 1.943079 3.927897 1.756873 45.026359
15619 Function HTMLDocument querySelector 5256 3878 109894 70588 0.143162 0.159666 5.420111 2.722504 64.232806
In [5]: df.nlargest(20, "total")
Out[5]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
10159 Get HTMLDivElement parentNode 2965 2640 6542023 3267748 7.269719 6.034085 3.250519 3.723290 49.950115
10200 Get HTMLDivElement nodeType 2014 1800 4208131 3091512 5.603724 5.771592 3.311296 2.459127 73.465203
12998 Get HTMLBodyElement parentNode 1665 1501 3365475 1217366 4.883114 2.911233 1.474360 1.232955 36.172190
7130 Get NodeList length 4664 4065 2382138 1072590 2.861152 1.943079 3.927897 1.756873 45.026359
12987 Get HTMLDivElement getAttribute 2037 1865 2048964 771237 2.767731 1.546469 2.962922 2.441469 37.640339
17434 Get HTMLDivElement nodeName 1443 1384 1931993 1450429 2.994059 3.124005 4.088068 4.737432 75.074237
1340 Get HTMLDivElement hasAttribute 858 830 1766442 1005093 3.688406 2.609303 2.078833 1.705360 56.899292
14607 Get MutationRecord addedNodes 432 423 1509702 775421 5.358348 4.852424 7.431751 9.234233 51.362521
16368 Get HTMLDivElement contains 542 535 1143362 1053742 2.645657 3.983127 2.107908 6.223987 92.161713
14386 Get MutationRecord type 339 331 1130505 470080 4.330352 3.197764 2.887015 3.495311 41.581417
1488 Get HTMLDivElement parentElement 1652 1584 1119639 646139 1.859494 1.433435 3.000702 2.827354 57.709583
6767 Function HTMLDivElement getAttribute 2039 1867 1117674 508505 1.509619 1.019614 2.401499 2.032517 45.496719
16281 Function HTMLDivElement matches 843 835 1115182 1064906 4.807023 6.144259 2.282807 2.758132 95.491678
7543 Get Performance now 3207 2534 1071387 900360 1.621756 2.036715 4.229508 3.661958 84.036861
17164 Get HTMLDivElement tagName 2146 2058 1063408 740653 1.584709 1.610988 2.923359 2.710166 69.648996
9359 Get HTMLDivElement matches 715 707 1061215 1007261 5.876682 7.905329 2.152317 2.651707 94.915828
4046 Get CustomElementRegistry get 137 89 1051466 1011774 11.754951 12.657662 4.568745 1.805876 96.225080
9514 Get HTMLDivElement querySelector 1871 1647 1030328 988630 1.721028 2.543417 2.069165 1.374590 95.952939
16355 Get HTMLBodyElement nodeType 1094 926 969560 909957 1.680494 2.101329 0.870327 0.668667 93.852572
2513 Get MutationRecord removedNodes 108 107 947656 302503 5.658883 4.521003 5.596039 5.110085 31.921182
In [6]: df.nlargest(20, "interact")
Out[6]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
10159 Get HTMLDivElement parentNode 2965 2640 6542023 3267748 7.269719 6.034085 3.250519 3.723290 49.950115
10200 Get HTMLDivElement nodeType 2014 1800 4208131 3091512 5.603724 5.771592 3.311296 2.459127 73.465203
17434 Get HTMLDivElement nodeName 1443 1384 1931993 1450429 2.994059 3.124005 4.088068 4.737432 75.074237
12998 Get HTMLBodyElement parentNode 1665 1501 3365475 1217366 4.883114 2.911233 1.474360 1.232955 36.172190
7130 Get NodeList length 4664 4065 2382138 1072590 2.861152 1.943079 3.927897 1.756873 45.026359
16281 Function HTMLDivElement matches 843 835 1115182 1064906 4.807023 6.144259 2.282807 2.758132 95.491678
16368 Get HTMLDivElement contains 542 535 1143362 1053742 2.645657 3.983127 2.107908 6.223987 92.161713
4046 Get CustomElementRegistry get 137 89 1051466 1011774 11.754951 12.657662 4.568745 1.805876 96.225080
9359 Get HTMLDivElement matches 715 707 1061215 1007261 5.876682 7.905329 2.152317 2.651707 94.915828
1340 Get HTMLDivElement hasAttribute 858 830 1766442 1005093 3.688406 2.609303 2.078833 1.705360 56.899292
9514 Get HTMLDivElement querySelector 1871 1647 1030328 988630 1.721028 2.543417 2.069165 1.374590 95.952939
16355 Get HTMLBodyElement nodeType 1094 926 969560 909957 1.680494 2.101329 0.870327 0.668667 93.852572
7543 Get Performance now 3207 2534 1071387 900360 1.621756 2.036715 4.229508 3.661958 84.036861
3621 Get TransitionEvent target 326 326 884580 883460 3.460662 5.166294 5.826075 6.594800 99.873386
17442 Get HTMLBodyElement nodeName 1117 1092 905159 878087 1.588063 2.115985 0.662423 0.761367 97.009144
12774 Get HTMLHtmlElement nodeName 777 754 896397 854629 1.931199 2.493193 0.726602 0.848152 95.340457
9483 Function HTMLDivElement querySelector 1871 1647 847881 808260 1.416274 2.079385 2.040353 1.344933 95.327057
3378 Function CustomElementRegistry get 101 71 828723 806370 12.442614 13.151448 5.779473 2.220260 97.302718
14414 Get Event target 2002 1903 824110 783286 1.179062 1.482671 4.650736 5.382586 95.046292
14607 Get MutationRecord addedNodes 432 423 1509702 775421 5.358348 4.852424 7.431751 9.234233 51.362521
From the relatively low %interact/total of some most popular APIs (e.g., 43% for createElement), we can already see a large number of DOM manipulations being done before any interaction.
Unfortunately, the top 20s for %total/total, %interact/interact, avg%total/script and avg%interact/script are mostly user-defined junk. This only shows the custom attributes are highly popular within the scripts that use them.
Top 20 API function calls
Since “get” calls do not usually create side effects, we focus on function calls.
The most popular function calls overall matches our expectations, mainly focusing on querying and interacting with the DOM.
In [7]: df[df["api_type"] == "Function"].nlargest(20, "appear") # type: ignore[reportArgumentType]
Out[7]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
2014 Function HTMLDocument createElement 9320 6330 286107 122524 0.296257 0.219127 2.612151 0.967649 42.824538
18119 Function Window addEventListener 7166 5668 56988 12036 0.087308 0.031169 1.998809 0.587056 21.120236
9201 Function Window setTimeout 6789 5622 774630 688808 0.847538 1.324614 3.571197 3.203018 88.920904
14494 Function HTMLDocument addEventListener 5870 5040 38962 10686 0.045599 0.019454 1.434622 0.627379 27.426723
12711 Function HTMLDocument getElementById 5559 3690 81282 42177 0.114240 0.095513 6.735331 2.271519 51.889717
15619 Function HTMLDocument querySelector 5256 3878 109894 70588 0.143162 0.159666 5.420111 2.722504 64.232806
12778 Function HTMLDocument getElementsByTagName 4775 3038 60070 46347 0.104988 0.118652 2.101945 0.346168 77.154986
5732 Function HTMLDocument querySelectorAll 4647 3765 223991 187374 0.332157 0.412884 1.507670 0.883315 83.652468
2723 Function Storage getItem 4445 3465 80359 53636 0.111631 0.125812 2.384386 1.275023 66.745480
1029 Function Window clearTimeout 4064 3570 122973 97912 0.181246 0.218990 1.177498 2.771284 79.620730
16594 Function Performance now 2764 2340 624855 498159 0.960439 1.144829 3.490532 3.096365 79.723936
8423 Function Window removeEventListener 2715 2396 12394 7457 0.020448 0.018160 0.505042 0.459469 60.166209
16575 Function Navigator get userAgentData 2575 2003 8612 3716 0.019608 0.011080 0.995214 0.463714 43.149094
17624 Function HTMLHeadElement appendChild 2559 1888 17051 7303 0.040659 0.022542 1.667455 0.622105 42.830333
16461 Function HTMLHtmlElement getAttribute 2550 2173 54549 13001 0.088869 0.032554 0.661737 0.118803 23.833617
12704 Function Storage setItem 2530 2151 117494 100433 0.229494 0.285617 1.399357 0.855013 85.479259
7048 Function HTMLDivElement addEventListener 2514 2184 252068 107180 0.391858 0.234839 2.477123 1.046851 42.520272
6007 Function HTMLDivElement appendChild 2328 2052 87416 23624 0.157654 0.065366 2.490404 1.678324 27.024801
16209 Function HTMLDivElement querySelectorAll 2294 2227 574049 442116 0.767773 0.923417 1.696780 1.783361 77.017119
14409 Function DOMTokenList add 2140 1859 75038 50171 0.119709 0.129215 2.026993 1.599572 66.860791
In [8]: df[df["api_type"] == "Function"].nlargest(20, "appear_interact") # type: ignore[reportArgumentType]
Out[8]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
2014 Function HTMLDocument createElement 9320 6330 286107 122524 0.296257 0.219127 2.612151 0.967649 42.824538
18119 Function Window addEventListener 7166 5668 56988 12036 0.087308 0.031169 1.998809 0.587056 21.120236
9201 Function Window setTimeout 6789 5622 774630 688808 0.847538 1.324614 3.571197 3.203018 88.920904
14494 Function HTMLDocument addEventListener 5870 5040 38962 10686 0.045599 0.019454 1.434622 0.627379 27.426723
15619 Function HTMLDocument querySelector 5256 3878 109894 70588 0.143162 0.159666 5.420111 2.722504 64.232806
5732 Function HTMLDocument querySelectorAll 4647 3765 223991 187374 0.332157 0.412884 1.507670 0.883315 83.652468
12711 Function HTMLDocument getElementById 5559 3690 81282 42177 0.114240 0.095513 6.735331 2.271519 51.889717
1029 Function Window clearTimeout 4064 3570 122973 97912 0.181246 0.218990 1.177498 2.771284 79.620730
2723 Function Storage getItem 4445 3465 80359 53636 0.111631 0.125812 2.384386 1.275023 66.745480
12778 Function HTMLDocument getElementsByTagName 4775 3038 60070 46347 0.104988 0.118652 2.101945 0.346168 77.154986
8423 Function Window removeEventListener 2715 2396 12394 7457 0.020448 0.018160 0.505042 0.459469 60.166209
16594 Function Performance now 2764 2340 624855 498159 0.960439 1.144829 3.490532 3.096365 79.723936
16209 Function HTMLDivElement querySelectorAll 2294 2227 574049 442116 0.767773 0.923417 1.696780 1.783361 77.017119
7048 Function HTMLDivElement addEventListener 2514 2184 252068 107180 0.391858 0.234839 2.477123 1.046851 42.520272
16461 Function HTMLHtmlElement getAttribute 2550 2173 54549 13001 0.088869 0.032554 0.661737 0.118803 23.833617
12704 Function Storage setItem 2530 2151 117494 100433 0.229494 0.285617 1.399357 0.855013 85.479259
6007 Function HTMLDivElement appendChild 2328 2052 87416 23624 0.157654 0.065366 2.490404 1.678324 27.024801
16575 Function Navigator get userAgentData 2575 2003 8612 3716 0.019608 0.011080 0.995214 0.463714 43.149094
17624 Function HTMLHeadElement appendChild 2559 1888 17051 7303 0.040659 0.022542 1.667455 0.622105 42.830333
6767 Function HTMLDivElement getAttribute 2039 1867 1117674 508505 1.509619 1.019614 2.401499 2.032517 45.496719
In [9]: df[df["api_type"] == "Function"].nlargest(20, "total") # type: ignore[reportArgumentType]
Out[9]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
6767 Function HTMLDivElement getAttribute 2039 1867 1117674 508505 1.509619 1.019614 2.401499 2.032517 45.496719
16281 Function HTMLDivElement matches 843 835 1115182 1064906 4.807023 6.144259 2.282807 2.758132 95.491678
9483 Function HTMLDivElement querySelector 1871 1647 847881 808260 1.416274 2.079385 2.040353 1.344933 95.327057
3378 Function CustomElementRegistry get 101 71 828723 806370 12.442614 13.151448 5.779473 2.220260 97.302718
9201 Function Window setTimeout 6789 5622 774630 688808 0.847538 1.324614 3.571197 3.203018 88.920904
16594 Function Performance now 2764 2340 624855 498159 0.960439 1.144829 3.490532 3.096365 79.723936
2831 Function HTMLDivElement hasAttribute 858 830 596653 412168 1.246269 1.070484 2.153890 2.032827 69.080018
16209 Function HTMLDivElement querySelectorAll 2294 2227 574049 442116 0.767773 0.923417 1.696780 1.783361 77.017119
11333 Function HTMLDivElement closest 1111 1109 415799 62022 1.477813 0.420875 2.660322 3.038853 14.916342
15923 Function HTMLAnchorElement getAttribute 1630 1553 353941 184154 0.464089 0.381401 1.700309 2.157078 52.029576
4078 Function HTMLDivElement contains 542 535 303535 254118 0.702358 0.960562 1.509068 3.241954 83.719505
2014 Function HTMLDocument createElement 9320 6330 286107 122524 0.296257 0.219127 2.612151 0.967649 42.824538
7048 Function HTMLDivElement addEventListener 2514 2184 252068 107180 0.391858 0.234839 2.477123 1.046851 42.520272
5732 Function HTMLDocument querySelectorAll 4647 3765 223991 187374 0.332157 0.412884 1.507670 0.883315 83.652468
11541 Function DOMTokenList contains 1919 1724 210971 141308 0.421512 0.391151 2.304020 2.127485 66.979822
2490 Function Text contains 51 51 187765 5018 1.569764 0.206079 1.265214 0.071572 2.672490
16718 Function HTMLScriptElement getAttribute 2065 1544 151950 50237 0.378190 0.168485 6.170167 2.245830 33.061533
12692 Function TreeWalker nextNode 139 124 144231 71645 1.507849 0.865876 4.913585 3.978987 49.673787
14823 Function Window getComputedStyle 1697 1384 143326 75800 0.299979 0.220471 1.873741 2.419006 52.886427
4797 Function HTMLDivElement setAttribute 2075 1803 124080 65231 0.200152 0.153838 0.799871 0.543422 52.571728
In [10]: df[df["api_type"] == "Function"].nlargest(20, "interact") # type: ignore[reportArgumentType]
Out[10]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
16281 Function HTMLDivElement matches 843 835 1115182 1064906 4.807023 6.144259 2.282807 2.758132 95.491678
9483 Function HTMLDivElement querySelector 1871 1647 847881 808260 1.416274 2.079385 2.040353 1.344933 95.327057
3378 Function CustomElementRegistry get 101 71 828723 806370 12.442614 13.151448 5.779473 2.220260 97.302718
9201 Function Window setTimeout 6789 5622 774630 688808 0.847538 1.324614 3.571197 3.203018 88.920904
6767 Function HTMLDivElement getAttribute 2039 1867 1117674 508505 1.509619 1.019614 2.401499 2.032517 45.496719
16594 Function Performance now 2764 2340 624855 498159 0.960439 1.144829 3.490532 3.096365 79.723936
16209 Function HTMLDivElement querySelectorAll 2294 2227 574049 442116 0.767773 0.923417 1.696780 1.783361 77.017119
2831 Function HTMLDivElement hasAttribute 858 830 596653 412168 1.246269 1.070484 2.153890 2.032827 69.080018
4078 Function HTMLDivElement contains 542 535 303535 254118 0.702358 0.960562 1.509068 3.241954 83.719505
5732 Function HTMLDocument querySelectorAll 4647 3765 223991 187374 0.332157 0.412884 1.507670 0.883315 83.652468
15923 Function HTMLAnchorElement getAttribute 1630 1553 353941 184154 0.464089 0.381401 1.700309 2.157078 52.029576
11541 Function DOMTokenList contains 1919 1724 210971 141308 0.421512 0.391151 2.304020 2.127485 66.979822
2014 Function HTMLDocument createElement 9320 6330 286107 122524 0.296257 0.219127 2.612151 0.967649 42.824538
595 Function HTMLAnchorElement isSameNode 30 30 117855 117855 8.029145 12.948267 7.101826 11.841353 100.000000
7048 Function HTMLDivElement addEventListener 2514 2184 252068 107180 0.391858 0.234839 2.477123 1.046851 42.520272
14811 Function HTMLInputElement matches 120 120 101906 101899 0.937924 1.010790 1.194562 1.553083 99.993131
12704 Function Storage setItem 2530 2151 117494 100433 0.229494 0.285617 1.399357 0.855013 85.479259
1029 Function Window clearTimeout 4064 3570 122973 97912 0.181246 0.218990 1.177498 2.771284 79.620730
15809 Function HTMLAnchorElement removeAttribute 373 347 99233 96946 1.153120 1.474503 0.726152 0.792383 97.695323
11476 Function DocumentFragment appendChild 555 540 103875 94235 0.567692 0.809485 2.425293 3.739579 90.719615
The top 20 function calls on the other 4 metrics are also less intuitive. They are mostly internal, workers, canvas, etc., and they do not appear much.
In [12]: df[df["api_type"] == "Function"].nlargest(20, "%total/total") # type: ignore[reportArgumentType]
Out[12]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
4048 Function Object query 7 0 7 0 100.000000 NaN 100.000000 0.000000 0.000000
5873 Function DedicatedWorkerGlobalScope importScripts 15 0 15 0 100.000000 NaN 100.000000 0.000000 0.000000
10648 Function KeyboardLayoutMap Iterator next 1 0 50 0 94.339623 NaN 94.339623 0.000000 0.000000
8245 Function Navigator joinAdInterestGroup 22 0 80 0 25.559105 NaN 33.441558 0.000000 0.000000
978 Function HTMLDocument evaluate 5 2 790 0 17.665474 0.000000 17.901950 0.000000 0.000000
14861 Function FontFaceSet add 18 4 18 4 16.666667 16.666667 16.666667 3.703704 22.222222
15873 Function FontFace load 18 4 18 4 16.666667 16.666667 16.666667 3.703704 22.222222
16387 Function HTMLLinkElement insertAdjacentHTML 29 29 29 29 16.666667 16.666667 16.666667 16.666667 100.000000
2636 Function HTMLDivElement isEqualNode 4 4 350 245 14.583333 13.424658 10.373686 10.092331 70.000000
9888 Function HTMLBodyElement get dataset 11 0 11 0 14.285714 NaN 14.285714 0.000000 0.000000
11149 Function Window close 7 0 7 0 14.285714 NaN 14.285714 0.000000 0.000000
3378 Function CustomElementRegistry get 101 71 828723 806370 12.442614 13.151448 5.779473 2.220260 97.302718
6954 Function Window find 1 1 290 266 11.435331 10.901639 11.435331 10.901639 91.724138
7442 Function DedicatedWorkerGlobalScope btoa 5 0 5 0 10.000000 NaN 10.000000 0.000000 0.000000
13750 Function DOMException get name 4 4 5 5 9.433962 9.433962 9.318182 9.318182 100.000000
8856 Function DedicatedWorkerGlobalScope postMessage 53 0 998 0 9.239030 NaN 14.201290 0.000000 0.000000
595 Function HTMLAnchorElement isSameNode 30 30 117855 117855 8.029145 12.948267 7.101826 11.841353 100.000000
3325 Function CanvasRenderingContext2D save 5 5 4700 4252 7.365501 7.344330 8.110019 8.297614 90.468085
4235 Function CanvasRenderingContext2D restore 5 5 4700 4252 7.365501 7.344330 8.110019 8.297614 90.468085
2952 Function HTMLBodyElement getClientRects 12 0 12 0 6.666667 NaN 14.423077 0.000000 0.000000
In [13]: df[df["api_type"] == "Function"].nlargest(20, "%interact/interact") # type: ignore[reportArgumentType]
Out[13]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
4306 Function CanvasRenderingContext2D putImageData 7 7 1378 1146 0.600666 27.501800 7.636882 19.591959 83.164006
2788 Function BroadcastChannel removeEventListener 3 2 3 2 0.603622 25.000000 0.666398 16.666667 66.666667
5443 Function PerformanceObserverEntryList getEntriesByName 4 4 10 10 2.036660 23.255814 2.005391 28.875812 100.000000
14861 Function FontFaceSet add 18 4 18 4 16.666667 16.666667 16.666667 3.703704 22.222222
15873 Function FontFace load 18 4 18 4 16.666667 16.666667 16.666667 3.703704 22.222222
16387 Function HTMLLinkElement insertAdjacentHTML 29 29 29 29 16.666667 16.666667 16.666667 16.666667 100.000000
2636 Function HTMLDivElement isEqualNode 4 4 350 245 14.583333 13.424658 10.373686 10.092331 70.000000
3378 Function CustomElementRegistry get 101 71 828723 806370 12.442614 13.151448 5.779473 2.220260 97.302718
595 Function HTMLAnchorElement isSameNode 30 30 117855 117855 8.029145 12.948267 7.101826 11.841353 100.000000
6954 Function Window find 1 1 290 266 11.435331 10.901639 11.435331 10.901639 91.724138
4237 Function IDBTransaction removeEventListener 13 5 702 21 0.578583 9.589041 3.134371 3.592959 2.991453
1527 Function HTMLCanvasElement dispatchEvent 5 5 5 5 2.659574 9.433962 2.702381 10.952381 100.000000
13750 Function DOMException get name 4 4 5 5 9.433962 9.433962 9.318182 9.318182 100.000000
46 Function HTMLFormElement checkValidity 5 5 35 35 2.800000 9.333333 2.905555 13.967387 100.000000
3325 Function CanvasRenderingContext2D save 5 5 4700 4252 7.365501 7.344330 8.110019 8.297614 90.468085
4235 Function CanvasRenderingContext2D restore 5 5 4700 4252 7.365501 7.344330 8.110019 8.297614 90.468085
1661 Function URL get protocol 90 90 5352 1824 0.524881 6.625740 0.728693 0.645742 34.080717
16281 Function HTMLDivElement matches 843 835 1115182 1064906 4.807023 6.144259 2.282807 2.758132 95.491678
15075 Function MessageEvent stopImmediatePropagation 1 1 1 1 0.564972 5.882353 0.564972 5.882353 100.000000
7786 Function DialogHelperElement querySelector 5 5 540 495 4.846962 5.586277 4.874266 5.632438 91.666667
In [14]: df[df["api_type"] == "Function"].nlargest(20, "avg%total/script") # type: ignore[reportArgumentType]
Out[14]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
4048 Function Object query 7 0 7 0 100.000000 NaN 100.000000 0.000000 0.000000
5873 Function DedicatedWorkerGlobalScope importScripts 15 0 15 0 100.000000 NaN 100.000000 0.000000 0.000000
10648 Function KeyboardLayoutMap Iterator next 1 0 50 0 94.339623 NaN 94.339623 0.000000 0.000000
8245 Function Navigator joinAdInterestGroup 22 0 80 0 25.559105 NaN 33.441558 0.000000 0.000000
6982 Function FontFaceSet load 110 52 735 116 0.429920 2.183735 21.941940 5.717374 15.782313
13606 Function ServiceWorkerGlobalScope fetch 25 0 4307 0 3.182920 NaN 19.438611 0.000000 0.000000
12027 Function ServiceWorkerGlobalScope importScripts 11 0 36 0 0.944386 NaN 18.684029 0.000000 0.000000
978 Function HTMLDocument evaluate 5 2 790 0 17.665474 0.000000 17.901950 0.000000 0.000000
11792 Function Image setAttribute 175 85 628 204 0.101835 0.037405 17.618164 4.888760 32.484076
16387 Function HTMLLinkElement insertAdjacentHTML 29 29 29 29 16.666667 16.666667 16.666667 16.666667 100.000000
14861 Function FontFaceSet add 18 4 18 4 16.666667 16.666667 16.666667 3.703704 22.222222
15873 Function FontFace load 18 4 18 4 16.666667 16.666667 16.666667 3.703704 22.222222
17399 Function PerformanceObserverEntryList getEntriesByType 38 38 3650 3159 4.730062 5.344725 15.360827 19.455392 86.547945
2952 Function HTMLBodyElement getClientRects 12 0 12 0 6.666667 NaN 14.423077 0.000000 0.000000
11149 Function Window close 7 0 7 0 14.285714 NaN 14.285714 0.000000 0.000000
9888 Function HTMLBodyElement get dataset 11 0 11 0 14.285714 NaN 14.285714 0.000000 0.000000
8856 Function DedicatedWorkerGlobalScope postMessage 53 0 998 0 9.239030 NaN 14.201290 0.000000 0.000000
15223 Function TrustedTypePolicy createScript 225 166 5909 3701 0.046810 0.041957 12.566570 7.982096 62.633271
6954 Function Window find 1 1 290 266 11.435331 10.901639 11.435331 10.901639 91.724138
2636 Function HTMLDivElement isEqualNode 4 4 350 245 14.583333 13.424658 10.373686 10.092331 70.000000
In [15]: df[df["api_type"] == "Function"].nlargest(20, "avg%interact/script") # type: ignore[reportArgumentType]
Out[15]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
5443 Function PerformanceObserverEntryList getEntriesByName 4 4 10 10 2.036660 23.255814 2.005391 28.875812 100.000000
4306 Function CanvasRenderingContext2D putImageData 7 7 1378 1146 0.600666 27.501800 7.636882 19.591959 83.164006
17399 Function PerformanceObserverEntryList getEntriesByType 38 38 3650 3159 4.730062 5.344725 15.360827 19.455392 86.547945
3938 Function HTMLAnchorElement removeEventListener 163 163 13043 11362 0.092295 0.108022 5.412695 16.769294 87.111861
2788 Function BroadcastChannel removeEventListener 3 2 3 2 0.603622 25.000000 0.666398 16.666667 66.666667
16387 Function HTMLLinkElement insertAdjacentHTML 29 29 29 29 16.666667 16.666667 16.666667 16.666667 100.000000
46 Function HTMLFormElement checkValidity 5 5 35 35 2.800000 9.333333 2.905555 13.967387 100.000000
595 Function HTMLAnchorElement isSameNode 30 30 117855 117855 8.029145 12.948267 7.101826 11.841353 100.000000
1527 Function HTMLCanvasElement dispatchEvent 5 5 5 5 2.659574 9.433962 2.702381 10.952381 100.000000
6954 Function Window find 1 1 290 266 11.435331 10.901639 11.435331 10.901639 91.724138
1336 Function Window getSelection 103 103 8064 8064 0.517555 0.579214 9.106014 10.571244 100.000000
2636 Function HTMLDivElement isEqualNode 4 4 350 245 14.583333 13.424658 10.373686 10.092331 70.000000
2536 Function HTMLAnchorElement blur 16 16 17 17 0.001361 0.001822 9.398725 9.830911 100.000000
13871 Function Selection toString 95 95 4873 4873 0.350078 0.381274 8.209906 9.385576 100.000000
3469 Function DOMException get message 8 5 15 11 0.007231 0.020454 9.319476 9.318414 73.333333
13750 Function DOMException get name 4 4 5 5 9.433962 9.433962 9.318182 9.318182 100.000000
11893 Function BroadcastChannel close 6 4 8 2 0.045961 0.510204 0.348012 8.333333 25.000000
3325 Function CanvasRenderingContext2D save 5 5 4700 4252 7.365501 7.344330 8.110019 8.297614 90.468085
4235 Function CanvasRenderingContext2D restore 5 5 4700 4252 7.365501 7.344330 8.110019 8.297614 90.468085
15223 Function TrustedTypePolicy createScript 225 166 5909 3701 0.046810 0.041957 12.566570 7.982096 62.633271
Top 20 API Set calls
There are some interesting popular “set” calls as well, despite the many internal functions.
In [16]: df[df["api_type"] == "Set"].nlargest(20, "appear") # type: ignore[reportArgumentType]
Out[16]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
15422 Set HTMLScriptElement src 4145 2406 15143 6913 0.033048 0.019939 2.485560 0.417693 45.651456
11866 Set HTMLScriptElement async 3037 1612 8652 2926 0.023194 0.010426 2.714181 0.277729 33.818770
8172 Set HTMLDocument cookie 2810 2376 25002 15393 0.057419 0.058849 5.065215 0.855618 61.567075
10020 Set HTMLAnchorElement href 2781 2633 43452 29806 0.078498 0.084109 0.583468 0.409084 68.595232
15256 Set HTMLScriptElement onload 2311 1711 15091 7425 0.035689 0.023283 1.407092 0.675300 49.201511
11456 Set CSSStyleDeclaration display 2158 1870 29629 20599 0.057507 0.064276 1.980954 1.334224 69.523102
3257 Set HTMLScriptElement type 1977 1171 4850 2048 0.059195 0.034339 2.318651 0.435811 42.226804
11781 Set HTMLDivElement innerHTML 1938 1811 16250 5709 0.036140 0.021380 0.966634 0.606579 35.132308
299 Set Window dataLayer 1859 1061 1911 405 0.028186 0.011752 9.510403 0.102686 21.193093
7094 Set XMLHttpRequest onreadystatechange 1780 1455 15562 11971 0.039432 0.041042 0.740359 0.471672 76.924560
12681 Set Image src 1693 1131 6466 3467 0.016076 0.011726 4.572729 1.848441 53.618930
13778 Set HTMLScriptElement onerror 1586 1291 12757 5854 0.033671 0.019983 0.744364 0.615878 45.888532
2347 Set XMLHttpRequest withCredentials 1564 1254 8258 6551 0.019977 0.023260 0.648240 0.361858 79.329135
14550 Set CSSStyleDeclaration width 1292 1097 19640 8521 0.065403 0.042337 1.446305 0.382616 43.385947
17552 Set HTMLImageElement src 1202 837 15598 5529 0.059533 0.037416 3.087841 1.070676 35.446852
258 Set CSSStyleDeclaration position 1192 969 21109 2744 0.052430 0.009619 0.507048 0.181102 12.999195
2148 Set HTMLIFrameElement src 1106 838 1383 543 0.011561 0.008270 0.710719 0.609099 39.262473
8985 Set HTMLDivElement id 1084 916 4409 709 0.013589 0.003192 0.643126 0.349976 16.080744
17444 Set MessagePort onmessage 1043 886 1228 133 0.003000 0.000449 0.391508 0.161973 10.830619
13010 Set CSSStyleDeclaration height 1003 833 29251 24464 0.069698 0.081981 0.304656 0.070588 83.634748
In [17]: df[df["api_type"] == "Set"].nlargest(20, "appear_interact") # type: ignore[reportArgumentType]
Out[17]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
10020 Set HTMLAnchorElement href 2781 2633 43452 29806 0.078498 0.084109 0.583468 0.409084 68.595232
15422 Set HTMLScriptElement src 4145 2406 15143 6913 0.033048 0.019939 2.485560 0.417693 45.651456
8172 Set HTMLDocument cookie 2810 2376 25002 15393 0.057419 0.058849 5.065215 0.855618 61.567075
11456 Set CSSStyleDeclaration display 2158 1870 29629 20599 0.057507 0.064276 1.980954 1.334224 69.523102
11781 Set HTMLDivElement innerHTML 1938 1811 16250 5709 0.036140 0.021380 0.966634 0.606579 35.132308
15256 Set HTMLScriptElement onload 2311 1711 15091 7425 0.035689 0.023283 1.407092 0.675300 49.201511
11866 Set HTMLScriptElement async 3037 1612 8652 2926 0.023194 0.010426 2.714181 0.277729 33.818770
7094 Set XMLHttpRequest onreadystatechange 1780 1455 15562 11971 0.039432 0.041042 0.740359 0.471672 76.924560
13778 Set HTMLScriptElement onerror 1586 1291 12757 5854 0.033671 0.019983 0.744364 0.615878 45.888532
2347 Set XMLHttpRequest withCredentials 1564 1254 8258 6551 0.019977 0.023260 0.648240 0.361858 79.329135
3257 Set HTMLScriptElement type 1977 1171 4850 2048 0.059195 0.034339 2.318651 0.435811 42.226804
12681 Set Image src 1693 1131 6466 3467 0.016076 0.011726 4.572729 1.848441 53.618930
14550 Set CSSStyleDeclaration width 1292 1097 19640 8521 0.065403 0.042337 1.446305 0.382616 43.385947
299 Set Window dataLayer 1859 1061 1911 405 0.028186 0.011752 9.510403 0.102686 21.193093
258 Set CSSStyleDeclaration position 1192 969 21109 2744 0.052430 0.009619 0.507048 0.181102 12.999195
8985 Set HTMLDivElement id 1084 916 4409 709 0.013589 0.003192 0.643126 0.349976 16.080744
17444 Set MessagePort onmessage 1043 886 1228 133 0.003000 0.000449 0.391508 0.161973 10.830619
2148 Set HTMLIFrameElement src 1106 838 1383 543 0.011561 0.008270 0.710719 0.609099 39.262473
17552 Set HTMLImageElement src 1202 837 15598 5529 0.059533 0.037416 3.087841 1.070676 35.446852
13010 Set CSSStyleDeclaration height 1003 833 29251 24464 0.069698 0.081981 0.304656 0.070588 83.634748
In [18]: df[df["api_type"] == "Set"].nlargest(20, "total") # type: ignore[reportArgumentType]
Out[18]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
9493 Set Event flow 121 121 72147 57173 0.262724 0.259411 0.292955 0.308683 79.245152
10020 Set HTMLAnchorElement href 2781 2633 43452 29806 0.078498 0.084109 0.583468 0.409084 68.595232
2968 Set Text textContent 42 41 37094 23641 1.142186 0.933173 0.917371 0.731892 63.732679
11456 Set CSSStyleDeclaration display 2158 1870 29629 20599 0.057507 0.064276 1.980954 1.334224 69.523102
9902 Set HTMLSpanElement textContent 497 463 29552 8465 0.262036 0.134479 1.362292 0.089505 28.644423
13010 Set CSSStyleDeclaration height 1003 833 29251 24464 0.069698 0.081981 0.304656 0.070588 83.634748
8172 Set HTMLDocument cookie 2810 2376 25002 15393 0.057419 0.058849 5.065215 0.855618 61.567075
4044 Set HTMLImageElement onload 510 440 21372 11883 0.361391 0.249478 0.810341 0.577726 55.600786
258 Set CSSStyleDeclaration position 1192 969 21109 2744 0.052430 0.009619 0.507048 0.181102 12.999195
12959 Set CSSStyleDeclaration left 565 532 20098 2004 0.078073 0.011633 0.940909 0.591199 9.971141
14550 Set CSSStyleDeclaration width 1292 1097 19640 8521 0.065403 0.042337 1.446305 0.382616 43.385947
16491 Set CSSStyleDeclaration fontFamily 143 116 16992 591 0.161403 0.007508 4.393393 0.188850 3.478107
13647 Set CSSStyleDeclaration transform 704 696 16935 14308 0.090705 0.128078 0.874879 0.462369 84.487747
11781 Set HTMLDivElement innerHTML 1938 1811 16250 5709 0.036140 0.021380 0.966634 0.606579 35.132308
5856 Set HTMLDivElement className 881 726 15672 4497 0.087585 0.033973 1.528997 1.046062 28.694487
131 Set Event isDefaultPrevented 191 191 15620 15617 0.351237 2.103407 0.222507 7.115688 99.980794
17552 Set HTMLImageElement src 1202 837 15598 5529 0.059533 0.037416 3.087841 1.070676 35.446852
7094 Set XMLHttpRequest onreadystatechange 1780 1455 15562 11971 0.039432 0.041042 0.740359 0.471672 76.924560
15422 Set HTMLScriptElement src 4145 2406 15143 6913 0.033048 0.019939 2.485560 0.417693 45.651456
15256 Set HTMLScriptElement onload 2311 1711 15091 7425 0.035689 0.023283 1.407092 0.675300 49.201511
In [19]: df[df["api_type"] == "Set"].nlargest(20, "interact") # type: ignore[reportArgumentType]
Out[19]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
9493 Set Event flow 121 121 72147 57173 0.262724 0.259411 0.292955 0.308683 79.245152
10020 Set HTMLAnchorElement href 2781 2633 43452 29806 0.078498 0.084109 0.583468 0.409084 68.595232
13010 Set CSSStyleDeclaration height 1003 833 29251 24464 0.069698 0.081981 0.304656 0.070588 83.634748
2968 Set Text textContent 42 41 37094 23641 1.142186 0.933173 0.917371 0.731892 63.732679
11456 Set CSSStyleDeclaration display 2158 1870 29629 20599 0.057507 0.064276 1.980954 1.334224 69.523102
131 Set Event isDefaultPrevented 191 191 15620 15617 0.351237 2.103407 0.222507 7.115688 99.980794
8172 Set HTMLDocument cookie 2810 2376 25002 15393 0.057419 0.058849 5.065215 0.855618 61.567075
13647 Set CSSStyleDeclaration transform 704 696 16935 14308 0.090705 0.128078 0.874879 0.462369 84.487747
7094 Set XMLHttpRequest onreadystatechange 1780 1455 15562 11971 0.039432 0.041042 0.740359 0.471672 76.924560
4044 Set HTMLImageElement onload 510 440 21372 11883 0.361391 0.249478 0.810341 0.577726 55.600786
204 Set Event isPropagationStopped 50 50 11723 11723 1.076866 1.692896 0.501635 3.173913 100.000000
11747 Set Event nativeEvent 50 50 11723 11723 1.076866 1.692896 0.501635 3.173913 100.000000
15818 Set Event persist 50 50 11723 11723 1.076866 1.692896 0.501635 3.173913 100.000000
14550 Set CSSStyleDeclaration width 1292 1097 19640 8521 0.065403 0.042337 1.446305 0.382616 43.385947
9902 Set HTMLSpanElement textContent 497 463 29552 8465 0.262036 0.134479 1.362292 0.089505 28.644423
15256 Set HTMLScriptElement onload 2311 1711 15091 7425 0.035689 0.023283 1.407092 0.675300 49.201511
15422 Set HTMLScriptElement src 4145 2406 15143 6913 0.033048 0.019939 2.485560 0.417693 45.651456
5704 Set CSSStyleDeclaration opacity 212 192 7607 6789 0.047285 0.070397 0.306024 0.537926 89.246746
935 Set HTMLAnchorElement onclick 287 274 13304 6744 0.126817 0.105791 0.135959 0.098332 50.691521
2347 Set XMLHttpRequest withCredentials 1564 1254 8258 6551 0.019977 0.023260 0.648240 0.361858 79.329135
Specific API of interest
Some APIs clearly indicate developers’ intent. We look at them case by case.
addEventListener on various elements all clearly indicate frontend processing, regardless of whether they are called after interaction started.
In [22]: df[(df["attr"] == "addEventListener") & (df["appear"] > 100) & (df["api_type"] == "Function")]
Out[22]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
170 Function HTMLHtmlElement addEventListener 435 403 10386 2790 0.042678 0.015690 1.014821 0.156781 26.863085
482 Function HTMLLinkElement addEventListener 357 203 6291 1129 0.165954 0.097912 1.344452 0.234178 17.946272
926 Function HTMLUListElement addEventListener 318 302 1973 73 0.020669 0.000985 0.300937 0.006706 3.699949
1271 Function HTMLImageElement addEventListener 585 539 25288 11160 0.128254 0.094256 0.826761 0.479900 44.131604
1593 Function HTMLSpanElement addEventListener 346 333 7552 270 0.049295 0.002749 0.135847 0.027511 3.575212
3005 Function HTMLParagraphElement addEventListener 101 101 2233 2 0.130516 0.000176 0.138290 0.000166 0.089566
3031 Function HTMLSelectElement addEventListener 236 217 1468 21 0.046463 0.001421 0.465725 0.017949 1.430518
3308 Function NetworkInformation addEventListener 106 103 119 18 0.021710 0.008249 0.167541 0.024107 15.126050
3772 Function HTMLElement addEventListener 750 739 32724 2545 0.183205 0.022435 1.564308 1.332341 7.777167
5077 Function MediaQueryList addEventListener 708 671 5206 2308 0.014862 0.008460 0.791159 0.285986 44.333461
5616 Function HTMLAnchorElement addEventListener 1346 1174 77789 18943 0.184291 0.063770 6.796528 0.760201 24.351772
7048 Function HTMLDivElement addEventListener 2514 2184 252068 107180 0.391858 0.234839 2.477123 1.046851 42.520272
7638 Function HTMLVideoElement addEventListener 233 193 13401 2890 0.273275 0.080812 2.216936 0.073431 21.565555
8196 Function AbortSignal addEventListener 104 104 8336 8160 0.026733 0.031255 0.176075 0.404642 97.888676
9282 Function HTMLButtonElement addEventListener 1475 1215 21572 3449 0.048451 0.011562 1.259833 0.811528 15.988318
11331 Function HTMLFormElement addEventListener 384 302 1962 97 0.050651 0.005543 4.696687 0.949741 4.943935
13049 Function XMLHttpRequest addEventListener 113 97 1176 715 0.010391 0.019337 0.309974 0.138416 60.799320
13077 Function HTMLScriptElement addEventListener 523 481 2340 1130 0.010101 0.013179 1.327969 0.154031 48.290598
13558 Function HTMLLIElement addEventListener 390 376 9582 737 0.096313 0.010782 0.262191 0.054946 7.691505
14483 Function HTMLBodyElement addEventListener 1021 964 10257 4482 0.027587 0.016387 0.603541 0.057784 43.696987
14494 Function HTMLDocument addEventListener 5870 5040 38962 10686 0.045599 0.019454 1.434622 0.627379 27.426723
16637 Function HTMLInputElement addEventListener 623 585 4813 1395 0.014064 0.005429 0.332024 0.059557 28.984002
18119 Function Window addEventListener 7166 5668 56988 12036 0.087308 0.031169 1.998809 0.587056 21.120236
HTMLDocument.createElement indicates either UX enhancement or DOM element generation. Since only 43% are called after interaction started, more than half of them are clearly DOM element generation.
In [24]: df[(df["attr"] == "createElement") & (df["api_type"] == "Function")]
Out[24]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
2014 Function HTMLDocument createElement 9320 6330 286107 122524 0.296257 0.219127 2.612151 0.967649 42.824538
Window.requestAnimationFrame is a clear indication of UX enhancement because it is strictly for animation. Much more of it is called after interaction started. Though calling it before interaction might make sense because the page might be animating before the user interacts.
In [26]: df[(df["attr"] == "requestAnimationFrame") & (df["api_type"] == "Function")]
Out[26]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
9128 Function Window requestAnimationFrame 1655 1422 42244 28852 0.092087 0.097062 1.884883 3.626479 68.298457
Navigator.sendBeacon is a clear indication of extensional features (tracking). It seems to be called more after interaction started.
In [27]: df[(df["attr"] == "sendBeacon") & (df["api_type"] == "Function")]
Out[27]:
api_type this attr appear appear_interact total interact %total/total %interact/interact avg%total/script avg%interact/script %interact/total
1989 Function Navigator sendBeacon 1132 1085 4685 3613 0.011954 0.012742 0.395376 3.096326 77.118463
Last edited:
Analysis of selected YouTube scripts API calls
Overview
let mut logs = read_logs("headless_browser/target/youtube.com/0").unwrap();
let i_log = logs
.iter()
.enumerate()
.max_by_key(|(_, LogFile { records, .. })| records.len())
.map(|(i, _)| i)
.unwrap();
// Aggregate API calls.
let mut aggregate = RecordAggregate::default();
for entry in &logs[i_log].records {
let (line, record) = entry.clone();
if let Err(err) = aggregate.add(line as u32, record) {
println!("{line}: {err}");
}
}
let mut ids = aggregate.scripts.keys().copied().collect::<Vec<_>>();
ids.sort_unstable();
for id in &ids {
let script = &aggregate.scripts[id];
println!(
"{id} line#{} source~{}kB used {} APIs {:?} {:?}",
script.line,
script.source.len() / 1024,
script.api_calls.len(),
script.injection_type,
script.name,
);
}
6 line#348 source~0kB used 0 APIs Not Url("https://www.youtube.com/")
7 line#351 source~0kB used 2 APIs Not Url("https://www.youtube.com/")
8 line#355 source~3kB used 6 APIs Not Url("https://www.youtube.com/")
9 line#363 source~0kB used 5 APIs Not Url("https://www.youtube.com/")
10 line#372 source~0kB used 0 APIs Not Url("https://www.youtube.com/")
11 line#374 source~2kB used 14 APIs Not Url("https://www.youtube.com/")
12 line#831 source~37kB used 44 APIs Not Url("https://www.youtube.com/s/desktop/72b8c307/jsbin/spf.vflset/spf.js")
13 line#951 source~14kB used 19 APIs Not Url("https://www.youtube.com/s/desktop/72b8c307/jsbin/network.vflset/network.js")
14 line#1112 source~8466kB used 1147 APIs Not Url("https://www.youtube.com/s/desktop/72b8c307/jsbin/desktop_polymer.vflset/desktop_polymer.js")
15 line#413 source~50kB used 37 APIs Not Url("https://www.youtube.com/s/desktop/72b8c307/jsbin/web-animations-next-lite.min.vflset/web-animations-next-lite.min.js")
16 line#591 source~5kB used 1 APIs Not Url("https://www.youtube.com/s/desktop/72b8c307/jsbin/intersection-observer.min.vflset/intersection-observer.min.js")
17 line#782 source~5kB used 1 APIs Not Url("https://www.youtube.com/s/desktop/72b8c307/jsbin/www-i18n-constants-en_US.vflset/www-i18n-constants.js")
18 line#796 source~11kB used 17 APIs Not Url("https://www.youtube.com/s/desktop/72b8c307/jsbin/www-tampering.vflset/www-tampering.js")
19 line#717 source~9kB used 28 APIs Not Url("https://www.youtube.com/s/desktop/72b8c307/jsbin/scheduler.vflset/scheduler.js")
20 line#467 source~2kB used 8 APIs Not Url("https://www.youtube.com/s/desktop/72b8c307/jsbin/custom-elements-es5-adapter.vflset/custom-elements-es5-adapter.js")
21 line#482 source~77kB used 168 APIs Not Url("https://www.youtube.com/s/desktop/72b8c307/jsbin/webcomponents-sd.vflset/webcomponents-sd.js")
22 line#595 source~0kB used 1 APIs Not Url("https://www.youtube.com/")
23 line#607 source~445kB used 6 APIs Not Url("https://www.youtube.com/")
24 line#705 source~0kB used 1 APIs Not Url("https://www.youtube.com/")
25 line#947 source~0kB used 0 APIs Not Url("https://www.youtube.com/")
26 line#986 source~0kB used 1 APIs Not Url("https://www.youtube.com/")
27 line#998 source~0kB used 3 APIs Not Url("https://www.youtube.com/")
28 line#1009 source~0kB used 1 APIs Not Url("https://www.youtube.com/")
30 line#1021 source~0kB used 1 APIs Not Url("https://www.youtube.com/")
31 line#1036 source~0kB used 1 APIs Not Url("https://www.youtube.com/")
32 line#1048 source~0kB used 2 APIs Not Url("https://www.youtube.com/")
33 line#1054 source~0kB used 1 APIs Not Url("https://www.youtube.com/")
34 line#1066 source~0kB used 1 APIs Not Url("https://www.youtube.com/")
35 line#1078 source~0kB used 1 APIs Not Url("https://www.youtube.com/")
36 line#1090 source~0kB used 1 APIs Not Url("https://www.youtube.com/")
37 line#1101 source~0kB used 1 APIs Not Url("https://www.youtube.com/")
41 line#89054 source~0kB used 1 APIs Not Url("https://www.youtube.com/")
42 line#89187 source~0kB used 1 APIs Not Url("https://www.youtube.com/")
43 line#89498 source~0kB used 1 APIs Not Url("https://www.youtube.com/")
44 line#89581 source~0kB used 1 APIs Not Url("https://www.youtube.com/")
45 line#89653 source~0kB used 4 APIs Not Url("https://www.youtube.com/")
46 line#89728 source~0kB used 14 APIs Not Url("https://www.youtube.com/")
47 line#89775 source~0kB used 1 APIs Not Url("https://www.youtube.com/")
48 line#89858 source~0kB used 0 APIs Not Url("https://www.youtube.com/")
49 line#89863 source~0kB used 1 APIs Not Url("https://www.youtube.com/")
50 line#92474 source~11kB used 5 APIs Injected Empty
55 line#94972 source~0kB used 0 APIs Injected Empty
56 line#94977 source~0kB used 4 APIs Injected Eval { parent_script_id: 50 }
58 line#94996 source~0kB used 4 APIs Injected Eval { parent_script_id: 50 }
61 line#95117 source~227kB used 126 APIs Injected Eval { parent_script_id: 50 }
64 line#95189 source~0kB used 0 APIs Interaction Eval { parent_script_id: 50 }
65 line#260337 source~277kB used 202 APIs Not Url("https://www.youtube.com/s/desktop/72b8c307/jsbin/www-searchbox.vflset/www-searchbox.js")Selected scripts inspection
https://www.youtube.com/s/desktop/72b8c307/jsbin/www-tampering.vflset/www-tampering.js is part of the Closure Library to detect if the page is tempered. The API calls is clearly mainly for extensional features, gathering information from userAgent and doing math:
for (api_call, lines) in &aggregate.scripts[&18].api_calls {
println!(
"{}/{} times: {api_call:?}",
lines.n_may_interact(),
lines.len()
);
}
0/2 times: ApiCall { api_type: Get, this: "Window", attr: Some("Symbol") }
0/4 times: ApiCall { api_type: Get, this: "Window", attr: Some("yt") }
0/1 times: ApiCall { api_type: Get, this: "Navigator", attr: Some("userAgentData") }
0/1 times: ApiCall { api_type: Get, this: "Window", attr: Some("Object") }
0/6 times: ApiCall { api_type: Get, this: "Navigator", attr: Some("userAgent") }
0/1 times: ApiCall { api_type: Get, this: "Window", attr: Some("execScript") }
0/1 times: ApiCall { api_type: Get, this: "Window", attr: Some("String") }
0/1 times: ApiCall { api_type: Get, this: "Window", attr: Some("window") }
0/7 times: ApiCall { api_type: Get, this: "Window", attr: Some("navigator") }
0/1 times: ApiCall { api_type: Function, this: "Navigator", attr: Some("get userAgentData") }
0/1 times: ApiCall { api_type: Get, this: "Window", attr: Some("WeakMap") }
0/1 times: ApiCall { api_type: Get, this: "Window", attr: Some("Array") }
0/1 times: ApiCall { api_type: Get, this: "Window", attr: Some("Set") }
0/1 times: ApiCall { api_type: Get, this: "Window", attr: Some("Math") }
0/1 times: ApiCall { api_type: Get, this: "Window", attr: Some("ytbin") }
0/1 times: ApiCall { api_type: Set, this: "Window", attr: Some("ytbin") }
0/1 times: ApiCall { api_type: Get, this: "Window", attr: Some("Map") }https://www.youtube.com/s/desktop/72b8c307/jsbin/desktop_polymer.vflset/desktop_polymer.js contains the Polymer code that generates HTML. These are mainly event-related APIs for frontend processing and APIs for DOM element generation (perhaps a bit of UX enhancement as well):
for (api_call, lines) in &aggregate.scripts[&14].api_calls {
if lines.len() > 1000 {
println!(
"{}/{} times: {api_call:?}",
lines.n_may_interact(),
lines.len()
);
}
}
21747/22409 times: ApiCall { api_type: Get, this: "HTMLDivElement", attr: Some("usePatchedLifecycles") }
21740/21792 times: ApiCall { api_type: Function, this: "HTMLDivElement", attr: Some("querySelectorAll") }
10185/10187 times: ApiCall { api_type: Function, this: "DocumentFragment", attr: Some("appendChild") }
2433/2434 times: ApiCall { api_type: Get, this: "Event", attr: Some("type") }
43621/45032 times: ApiCall { api_type: Get, this: "HTMLDivElement", attr: Some("tagName") }
7139/7143 times: ApiCall { api_type: Function, this: "HTMLBodyElement", attr: Some("appendChild") }
10185/10226 times: ApiCall { api_type: Get, this: "DocumentFragment", attr: Some("isConnected") }
21754/21780 times: ApiCall { api_type: Get, this: "HTMLDivElement", attr: Some("isConnected") }
6303/6449 times: ApiCall { api_type: Get, this: "DocumentFragment", attr: Some("children") }
3786/3803 times: ApiCall { api_type: Function, this: "DocumentFragment", attr: Some("get children") }
2478/2480 times: ApiCall { api_type: Get, this: "Event", attr: Some("pageY") }
7139/7143 times: ApiCall { api_type: Get, this: "HTMLBodyElement", attr: Some("isConnected") }
0/8817 times: ApiCall { api_type: Get, this: "Window", attr: Some("Reflect") }
2478/2480 times: ApiCall { api_type: Get, this: "Event", attr: Some("target") }
2478/2480 times: ApiCall { api_type: Get, this: "Event", attr: Some("pageX") }
2064/2065 times: ApiCall { api_type: Get, this: "Event", attr: Some("keyCode") }
10717/10717 times: ApiCall { api_type: Function, this: "HTMLBodyElement", attr: Some("removeChild") }Interestingly, most of these calls are done after interaction began, probably during YouTube’s navigation-less page switching. I.e., YouTube does not load a new page when you click a link, but instead swaps out the content of the current page and changes the URL.
The script with context id 23 on line #607 embedded in the HTML only sets a large 440kB JSON for various string templates for the UI (e.g., Downloading 1 video...), thus kind of counts as DOM element generation:
for (api_call, lines) in &aggregate.scripts[&23].api_calls {
println!(
"{}/{} times: {api_call:?}",
lines.n_may_interact(),
lines.len()
);
}
0/1 times: ApiCall { api_type: Set, this: "Window", attr: Some("ytcfg") }
0/1 times: ApiCall { api_type: Get, this: "Window", attr: Some("innerWidth") }
0/1 times: ApiCall { api_type: Get, this: "Window", attr: Some("innerHeight") }
0/1 times: ApiCall { api_type: Set, this: "Window", attr: Some("ytplayer") }
0/2 times: ApiCall { api_type: Get, this: "Window", attr: Some("ytcfg") }
0/1 times: ApiCall { api_type: Get, this: "Window", attr: Some("yt") }https://www.youtube.com/s/desktop/72b8c307/jsbin/network.vflset/network.js only calls a few APIs, but hits the ones we are interested in for frontend processing, DOM element generation, and extensional features. It seems to contain a portion of the structured page fragments (SPF) library used for dynamic content fetching and rendering.
for (api_call, lines) in &aggregate.scripts[&13].api_calls {
println!(
"{}/{} times: {api_call:?}",
lines.n_may_interact(),
lines.len()
);
}
0/2 times: ApiCall { api_type: Function, this: "Window", attr: Some("addEventListener") }
0/2 times: ApiCall { api_type: Get, this: "Window", attr: Some("Symbol") }
0/1 times: ApiCall { api_type: Function, this: "Window", attr: Some("postMessage") }
0/4 times: ApiCall { api_type: Get, this: "Window", attr: Some("removeEventListener") }
0/2 times: ApiCall { api_type: Get, this: "Window", attr: Some("spf") }
0/1 times: ApiCall { api_type: Get, this: "Window", attr: Some("Array") }
0/2 times: ApiCall { api_type: Get, this: "Window", attr: Some("postMessage") }
0/1 times: ApiCall { api_type: Get, this: "HTMLDivElement", attr: Some("style") }
0/1 times: ApiCall { api_type: Get, this: "HTMLDocument", attr: Some("createElement") }
0/2 times: ApiCall { api_type: Function, this: "Window", attr: Some("removeEventListener") }
0/1 times: ApiCall { api_type: Function, this: "HTMLDocument", attr: Some("createElement") }
0/4 times: ApiCall { api_type: Get, this: "Window", attr: Some("addEventListener") }
0/1 times: ApiCall { api_type: Get, this: "Performance", attr: Some("timing") }
0/1 times: ApiCall { api_type: Function, this: "Performance", attr: Some("get timing") }
0/1 times: ApiCall { api_type: Get, this: "Window", attr: Some("Math") }
0/1 times: ApiCall { api_type: Set, this: "Window", attr: Some("spf") }
0/2 times: ApiCall { api_type: Get, this: "MessageEvent", attr: Some("data") }
0/1 times: ApiCall { api_type: Get, this: "Performance", attr: Some("now") }
0/3 times: ApiCall { api_type: Get, this: "Window", attr: Some("performance") }Script with ID 27 on line #998 only loads fonts (UX enhancements).
for (api_call, lines) in &aggregate.scripts[&27].api_calls {
println!(
"{}/{} times: {api_call:?}",
lines.n_may_interact(),
lines.len()
);
}
0/2 times: ApiCall { api_type: Function, this: "FontFaceSet", attr: Some("load") }
0/3 times: ApiCall { api_type: Get, this: "FontFaceSet", attr: Some("load") }
0/4 times: ApiCall { api_type: Get, this: "HTMLDocument", attr: Some("fonts") }
println!("{}", &aggregate.scripts[&27].source);
if (document.fonts && document.fonts.load) {document.fonts.load("400 10pt Roboto", ""); document.fonts.load("500 10pt Roboto", "");}Last edited:
The eval Trick
Each direct eval creates a separate browser execution context, so the idea is to use it to break down scripts without the need of including additional scripts. The high-level idea is to split each script and subsequently each block recursively into blocks of eval calls smaller than 1kB (an arbitrary number), and somehow have the whole script behave as before.
- Test run in the browser.
- Crawl top 1000 websites and analyze the logs.
Why it should work
Direct eval calls are executed in the same scope as the caller, with read-write access to all of the surrounding variables.
Challenges and workarounds
In reality, the eval trick is a giant hack due to the quirks of eval.
Hoisting: some constructs behave as if they are evaluated first before the script is run.
Top-level functions.
We simply
evalthem first.Variable declarations. Functions cannot capture variables declared in adjacent
evals, and would capture the variable in the outer scope with the same name instead, causing errors. Variables created inevaldo not leak out unless they are declared withvarin non-strict mode.We identify all variable declarations in the current scope, declare all of them first using
varorlet, then make sure they are not declared again in theevalcalls on the same level.(Deferred) Some assignments do not have a single variable identifier on their left-hand side (LHS), such as destructuring. The LHS can contain arbitrary expressions.
We currently stick
varto their beginning so most of them work, but the assigned variables do not leak out. This is usually fine because most such assignments are for local variables anyway.
returnstatements cannot return from insideeval.For each
evalblock that containsreturnstatements not in nested functions or classes, we wrap it in an immediately invoked function expression (IIFE) so that thereturns are valid. We call the IIFE with.call(this)to preservethis. We then check the return value ofevaland return early it if it is notundefined.Functions declared in IIFEs do not leak out.
We declare the function identifiers as variables first, then convert all function declarations to assignments of function expressions to those variables.
(Deferred) This seems to break a few scripts, especially when they call functions defined in other scripts.
No idea for solutions yet because the error messages did not reveal the cause.
importstatements are not allowed insideeval.We put them at the top of the script.
exportstatements are not allowed insideeval.We keep these scripts as is.
break,continueandyieldstatements may not be able to reach the correct outer scopes insideeval.We do not rewrite with
evalin loops or generators until we hit a function or class boundary.awaitdoes not work insideeval.We
awaiton theevaland use an async IIFE if an IIFE is used.Bloat: deeply nested
evals cause mountains of backslashes.We use
String.rawto avoid escaping backslashes and nest nestedevalcalls in functions to escape the backticks and${at runtime.Browser crash with stack size exceeded when nesting
evalto over depth 8.We limit the depth of
evalnesting to 8 and inline the deeper blocks.
Inherent limitations
- Performance:
evaldisables the JIT and forces slow variable lookups. - Integrity: e.g., if the website checks the checksum of the script, it will fail.
Last edited:
Classification results
Initial results on top 100 websites
Of the 40116 scripts we analyzed (3192.7MB, details in script_features.py):
- Size: 9B~8.7MB, average 80kB, median 2.2kB.
- Many small scripts.
- No significant correlation between anything.
- Coverage: 67% classified by count, 93% by size.
- Coverage growth potential: 7% by count, 1% by size.
- Half (1296.1MB, 40.60%) scripts by size fall into all sure categories. Count 1473 (3.67%).
- Look for bloated sites.
- What next if we can split it up?
- What user impact from size? Aggregate per page?
- Chrome execution time of script.
| Feature | Count | Percentage (%) | Size (MB) | Size Percentage (%) |
|---|---|---|---|---|
| Total Scripts | 40116 | - | 3192.7 | - |
| Frontend Processing | 14129 | 35.22 | 2864.3 | 89.72 |
| DOM Element Generation | 8196 | 20.43 | 2248.9 | 70.44 |
| UX Enhancement | 4496 | 11.21 | 1840.7 | 57.65 |
| Extensional Features | 4915 | 12.25 | 1888.1 | 59.14 |
| Silent Scripts | 10260 | 25.58 | 28.1 | 0.88 |
| Has Request | 4205 | 10.48 | 1432.1 | 44.86 |
| Queries Element | 13640 | 34.00 | 2731.6 | 85.56 |
| Uses Storage | 4571 | 11.39 | 1641.0 | 51.40 |
| No Sure Category | 13148 | 32.77 | 221.1 | 6.93 |
| No Category | 10178 | 25.37 | 179.7 | 5.63 |
| Feature Combination | Frontend Processing | DOM Element Generation | UX Enhancement | Extensional Features | Has Request | Queries Element |
|---|---|---|---|---|---|---|
| DOM Element Generation | 6602 (16.46%), 2197.1MB (68.82%) | - | - | - | - | - |
| UX Enhancement | 3840 (9.57%), 1821.5MB (57.05%) | 3125 (7.79%), 1613.2MB (50.53%) | - | - | - | - |
| Extensional Features | 4229 (10.54%), 1841.1MB (57.67%) | 2703 (6.74%), 1562.9MB (48.95%) | 1844 (4.60%), 1440.5MB (45.12%) | - | - | - |
| Has Request | 3981 (9.92%), 1428.9MB (44.76%) | 2338 (5.83%), 1192.9MB (37.36%) | 1459 (3.64%), 1162.6MB (36.42%) | 1755 (4.37%), 1226.1MB (38.40%) | - | - |
| Queries Element | 9379 (23.38%), 2648.1MB (82.94%) | 6846 (17.07%), 2152.1MB (67.41%) | 3754 (9.36%), 1773.7MB (55.55%) | 3508 (8.74%), 1800.3MB (56.39%) | 3627 (9.04%), 1410.1MB (44.17%) | - |
| Uses Storage | 4335 (10.81%), 1633.2MB (51.15%) | 2728 (6.80%), 1362.7MB (42.68%) | 1669 (4.16%), 1278.9MB (40.06%) | 2093 (5.22%), 1372.2MB (42.98%) | 2424 (6.04%), 1106.1MB (34.64%) | 3722 (9.28%), 1596.9MB (50.02%) |
| Feature Combination | Scripts Count (%) | Size (MB) (%) |
|---|---|---|
| Frontend Processing & DOM Element Generation & UX Enhancement | 2813 (7.01%) | 1604.9MB (50.27%) |
| Frontend Processing & DOM Element Generation & Extensional Features | 2679 (6.68%) | 1533.0MB (48.02%) |
| Frontend Processing & UX Enhancement & Extensional Features | 1814 (4.52%) | 1439.2MB (45.08%) |
| DOM Element Generation & UX Enhancement & Extensional Features | 1482 (3.69%) | 1296.6MB (40.61%) |
Results with the eval trick on top 1000 websites
We crawled the top 1000 websites with the eval trick applied to scripts. The eval trick rewrites each script into smaller blocks of eval calls, creating V8 execution contexts that maps to smaller blocks of source code. The unit here is execution context, not script anymore.
- Size: 1B~6MB, average 1.2kB, median 48B, total 26.2GB.
- Most scripts broken down, but some persisted.
- Rewritten contexts cover 23.3GB (89.14%) of source code.
- Some rewritten contexts are still large, probably because of class,
elsebranch, etc.
- Some rewritten contexts are still large, probably because of class,
- Still no significant correlation between anything.
- Half of the contexts by size do not call any APIs, 84% by count.
- Coverage: 86% classified by count, 87% by size. By size, 49.12% silent + 38% classified + 12.87% no-sphere.
- By size, 98% (3.3GB) of no-sphere contexts make less than 100 API calls.
- By size, 80% (667MB) of no-sphere contexts are rewritten.
- One eighth of contexts by size fall into all sure categories (12.37%, 3235.2MB), which is 1/3 of all contexts belonging to some sphere.
- Much less than previous results, but still high.
| Feature | Count | Percentage (%) | Size (MB) | Size Percentage (%) |
|---|---|---|---|---|
| Total Contexts | 21027954 | - | 26163.2 | - |
| Silent Contexts | 17572814 | 83.57 | 12850.4 | 49.12 |
| Frontend Processing | 338273 | 1.61 | 9469.6 | 36.19 |
| DOM Element Generation | 72286 | 0.34 | 6250.1 | 23.89 |
| UX Enhancement | 26536 | 0.13 | 5392.0 | 20.61 |
| Extensional Features | 32647 | 0.16 | 5617.2 | 21.47 |
| Has Request | 16821 | 0.08 | 4318.8 | 16.51 |
| Queries Element | 120844 | 0.57 | 7719.9 | 29.51 |
| Uses Storage | 26081 | 0.12 | 5142.6 | 19.66 |
| Feature Combination | Frontend Processing | DOM Element Generation | UX Enhancement | Extensional Features | Has Request | Queries Element |
|---|---|---|---|---|---|---|
| DOM Element Generation | 20763 (0.10%), 5924.2MB (22.64%) | - | - | - | - | - |
| UX Enhancement | 15544 (0.07%), 5229.6MB (19.99%) | 12910 (0.06%), 4537.7MB (17.34%) | - | - | - | - |
| Extensional Features | 13557 (0.06%), 5540.2MB (21.18%) | 6207 (0.03%), 4006.9MB (15.31%) | 5369 (0.03%), 3667.5MB (14.02%) | - | - | - |
| Has Request | 10514 (0.05%), 4276.4MB (16.35%) | 5694 (0.03%), 3081.3MB (11.78%) | 4519 (0.02%), 3041.1MB (11.62%) | 4926 (0.02%), 3572.3MB (13.65%) | - | - |
| Queries Element | 33064 (0.16%), 7174.1MB (27.42%) | 29577 (0.14%), 5575.6MB (21.31%) | 15820 (0.08%), 4875.0MB (18.63%) | 7871 (0.04%), 4812.3MB (18.39%) | 7730 (0.04%), 3857.2MB (14.74%) | - |
| Uses Storage | 13332 (0.06%), 5067.7MB (19.37%) | 7018 (0.03%), 3569.3MB (13.64%) | 5109 (0.02%), 3400.2MB (13.00%) | 5215 (0.02%), 3815.2MB (14.58%) | 6573 (0.03%), 3583.0MB (13.69%) | 9930 (0.05%), 4640.1MB (17.74%) |
| Feature Combination | Scripts Count (%) | Size (MB) (%) |
|---|---|---|
| Frontend Processing & DOM Element Generation & UX Enhancement | 10291 (0.05%) | 4483.3MB (17.14%) |
| Frontend Processing & DOM Element Generation & Extensional Features | 6022 (0.03%) | 3975.0MB (15.19%) |
| Frontend Processing & UX Enhancement & Extensional Features | 5241 (0.02%) | 3664.5MB (14.01%) |
| DOM Element Generation & UX Enhancement & Extensional Features | 4078 (0.02%) | 3235.9MB (12.37%) |
Last edited:
Machine Learning Systems
- WaferLLM: Large Language Model Inference at Wafer Scale, Congjie He, Yeqi Huang, Pei Mu, Ziming Miao, Jilong Xue, Lingxiao Ma, Fan Yang, Luo Mai, OSDI, 2025
Last edited:
Photo Crypto Auth
- cameras will sign photo cryptographically
- influencer have posted genuine photo but for irrelevant event
- may build system to authenticate photo
problem:
what about photo without signature?don’t care
steps:
- What in photo from C2PA camera?
- Post-processing on social media site preserve signature?
- X remove C2PA
- Twitter joined C2PA in 2021 but X quit C2PA in 2024 after Elon Musk
- Facebook remove C2PA
- although Meta is in C2PA steering committee
- LinkedIn display C2PA info. probably the only platform, because of Microsoft
- X remove C2PA
- Extract info from posts’ text
literature
P3: Toward Privacy-Preserving Photo Sharing, Moo-Ryong Ra, Ramesh Govindan, Antonio Ortega, NSDI 13
split photo into public and private part, encrypt private part
Mitigating Image-based Misinformation Campaigns, Calvin Ardi, Harsha V. Madhyastha
proposal: compare photo crypto metadata time+location w/ social media post text before manipulative post go viral. good for news. need to balance privacy
C2PA
- nesting: manifest (metadata) > claim (wrapper) > assertion (statement)
- claim generator: create & sign claim
- manifest consumer, e.g., C2PA validator
- public key encryption (ECDSA/EdDSA/RSA) to sign claim; SHA-2 hash for hard binding of manifest & content
- modifying image invalidate previous signature, need new one: 10.3.3.2. Multiple Claims | Content Credentials : C2PA Technical Specification :: C2PA Specifications
- PhotoShop seem to keep private key on cloud, see Content credentials in Photoshop
- attack: see Threat | C2PA Security Considerations :: C2PA Specifications onward
- steal private key/ trick claim generator/ make key → penetrate
- security guidance: “best practice”
- hardware security module (HSM); revoke
- Canon signing key leak from 2010: Analyst Finds Flaws in Canon Image Verification System | PCWorld
- no transitive trust; probably whack-a-mole security patching
- could add any author name during editing: blog
- how actually done
- check out C2PA editing software
- few options.
- Adobe is biggest
- PixelStream seems vaporware. blog from CAI: Community story: Pixelstream. but dead GitHub and website; cannot register
- Photo Mechanic is for camera
- Cloudinary is for content delivery
- Try after sign up: only preserve existing, do not add new; need to join beta program
- Microsoft Designer is not advertised; MS Paint
- check out C2PA image
- Check out C2PA SDK
- check out C2PA editing software
- Note down potential issues
- Removing metadata rids hard binding. Soft binding improvements?
- Camera private key leak
- Editing software lose track
- Taking photo of photo
- ❗Literatures? Difference between photo of photo and photo
- Bad search term. Only found paper on distinguishing manipulated photo.
- ❗Literatures? Difference between photo of photo and photo
- PKI: long term verification support?
- ❗Literatures? Trusting signed document long term
- Check out signed digest standard
- ❗Literatures? Trusting signed document long term
- Vilesov arXiv paper
- use case: prove my photo is real
- news, social media
- legal, forensic
- artwork
- research proof
- figure out concrete use case
- vision: want C2PA be like TLS
- “three-legged approach”: C2PA, watermark, fingerprint
- need phone to do C2PA; doable similarly to Apple Pay
- provider companies charging high margin hinder adoption
- build open-source solution for mobile?
- enhancement
- privacy by choosing metadata to include
- prove one image is manipulation of another
- surrounding
- blockchain
- opting out of ML training
PKI & blockchain
- cannot scale to 1 certificate per user per period?
- share pubkey, sign on server
- blockchain reference instead of certificate, but not same level of trust
- current pubkey may eventually be cracked
- quantum algorithm crack RSA & ECC in quadratic time; quantum-safe crypto not adopted
- 💡 need time interval for key validity → content/hash on blockchain
- but current blockchain may be cracked too
idea
- get something then reach out to C2PA people
- RGBD camera to combat taking photo of photo
difficulties implementing C2PA on mobile
- performance: slow to sign?
- PKI: get certificate? scaling? revocation?
Last edited:
C2PA-Related Papers
Introduce C2PA
- This Election Year, Look for Content Credentials: Media organizations combat deepfakes and disinformation with digital manifests, Eliza Strickland, IEE Spectrum, 2024
- talking about what C2PA is and how the adoption may work
- Understanding the Impact of AI-Generated Deepfakes on Public Opinion, Political Discourse, and Personal Security in Social Media, Prakash L. Kharvi, IEEE SP, 2024
- why policies & companies should adopt C2PA
- Defining best practices for opting out of ML training, Paul Keller, Zuzanna Warso, Open Future policy brief, 2023
- C2PA has entry to opt out of ML training
- AI-Generated Images as an Emergent Record Format, Jessica Bushey, IEEE BigData, 2023
- literature review by computational archival science (CAS) people, ITrustAI
- GenAI literature in medicine & law enforcement & journalism
- copyright attribution; public trust in democracy
- Confidence-Building Measures for Artificial Intelligence: Workshop Proceedings, Sarah Shoker, Andrew Reddie, et al., arXiv, 2023
- foundational models can be used for insecure things
- watermarking has tempering and adoption problems
- ⭐ Solutions to Deepfakes: Can Camera Hardware, Cryptography, and Deep Learning Verify Real Images?, Alexander Vilesov, Yuan Tian, Nader Sehatbakhsh, Achuta Kadambi, arXiv, 2024
- ways to verify images, including C2PA
- need every camera to support C2PA
- can spoof by taking photo of a photo
- prevent by various ways to distinguish 2D from 3D: camera structure from motion, hand jitter, stereo-based depth triangulation, lidar sensing, polarization-based sensing, time-of-flight sensing, spatially altered Bayer pattern, sparse polarization-sensitive pixel sampling
- useless if object is already flat
- new file format for “real” images
- Global content revocation on the internet: a case study in technology ecosystem transformation, Narek Galstyan, James McCauley, Hany Farid, Sylvia Ratnasamy, Scott Shenker, HotNets, 2022
- wild new idea to rethink content revocation
- Deepfake Fraud Detection: Safeguarding Trust in Generative Ai, Felipe Romero-Moreno, SSRN Preprint, 2024
- from law person perspective, C2PA and other tools to combat deepfake
Enhance or extend C2PA
- Ensuring privacy in provenance information for images, Nikolaos Fotos, Jaime Delgado, IEEE DSP, 2023; Towards Privacy-Enhancing Provenance Annotations for Images, Nikolaos Fotos, Jaime Delgado, IEEE ICIP, 2024
- add privacy-preserving features
- A Blockchain based Framework for Content Provenance and Authenticity, Emil Bureacă, Iulian Aciobăniței, IEEE ECAI, 2024
- blockchain on top of C2PA
- Integrating Content Authenticity with DASH Video Streaming, Stefano Petrangeli, Haoliang Wang, Maurice Fisher, Dave Kozma, Massy Mahamli, Pia Blumenthal, Andy Parsons, ACM MMSys, 2024
- C2PA in video stream
- Trust Nobody: Privacy-Preserving Proofs for Edited Photos with Your Laptop, Pierpaolo Della Monica, Ivan Visconti, Andrea Vitaletti, Marco Zecchini, IEEE SP, 2025; Trust Nobody: Privacy-Preserving Proofs for Edited Photos with Your Laptop, Pierpaolo Della Monica, Ivan Visconti, Andrea Vitaletti, Marco Zecchini, Cryptology ePrint Archive, 2024
- privacy-preserving proofs that an image is manipulation of another
- VerITAS: Verifying Image Transformations at Scale, Trisha Datta, Binyi Chen, Dan Boneh, Cryptology ePrint Archive, 2024; VIMz: Verifiable Image Manipulation using Folding-based zkSNARKs, Stefan Dziembowski, Shahriar Ebrahimi, Parisa Hassanizadeh, Cryptology ePrint Archive, 2024
- zero-knowledge proof that an image is transformation of another
- To Authenticity, and Beyond! Building Safe and Fair Generative AI Upon the Three Pillars of Provenance, John Collomosse, Andy Parsons, IEEE CGA, 2024
- three pillars: metadata, fingerprint, watermark
- Pseudorandom Error-Correcting Codes, Miranda Christ, Sam Gunn, IACR, 2024
- robust codeword appear random w/o decoding key
- -hardness from learning parity with noise (LPN) problem (NP-hard)
- undetectable watermark & tolerate alternation
- steganography
- robust codeword appear random w/o decoding key
Applying C2PA
- EKILA: Synthetic Media Provenance and Attribution for Generative Art, Kar Balan, Shruti Agarwal, Simon Jenni, Andy Parsons, Andrew Gilbert, John Collomosse, IEEE CVPR, 2023; DECORAIT - DECentralized Opt-in/out Registry for AI Training, Kar Balan, Andrew Gilbert, Alexander Black, Simon Jenni, Andy Parsons, John Collomosse, ACM CVMP, 2023
- blockchain to index & attribute GenAI contribution by fingerprinting
- C2PA to express consent & payment preference
- Interoperable Provenance Authentication of Broadcast Media using Open Standards-based Metadata, Watermarking and Cryptography, John C. Simmons, Joseph M. Winograd, IBC 2024
- C2PA & Advanced Television Systems Committee (ATSC) for broadcast provenance
- ATSC: transfer metadata over broadcast
Alternatives or complements to C2PA
- Towards Trustworthy Digital Media In The Aigc Era: An Introduction To The Upcoming IsoJpegTrust Standard, Jiayun Mo, Xin Kang, Ziyuan Hu, Haibo Zhou, Tieyan Li, Xiaojun Gu, IEEE COMSTD, 2023; An International Standard For Assessing Trustworthiness In Media, Deepayan Bhowmik, Sabrina Caldwell, Jaime Delgado, Touradj Ebrahimi, Nikolaos Fotos, Xiaojun Gu, IEEE ICIP, 2024
- ISO JPEG Trust: “trust profile” vs “trust credential” question-answer validation
- emphasis on trustworthiness
- TRAIT: A Trusted Media Distribution Framework, James Rainey, Mohamed Elawady, Charith Abhayartne, Deepayan Bhowmik, IEEE DSP, 2023
- blockchain to detect media manipulation
Scaling PKI
- A Blockchain-Based PKI Management Framework, Alexander Yakubov, Wazen M. Shbair, Anders Wallbom, David Sanda, Radu State, IEEE/IFIP Man2Block, 2018
- PKI insecure when CA compromised
- blockchain-based PKI
Fake image detection
- Can people identify original and manipulated photos of real-world scenes?, Sophie J Nightingale, Kimberley A Wade, Derrick G Watson, Springer Cognitive Research, 2017
- people can hardly tell if and how image manipulated
- Explaining Why Fake Photos are Fake: Does It Work?, Margie Ruffin, Gang Wang, Kirill Levchenko, ACM HCI, 2022
- people cannot tell if image manipulated
- explaining manipulation does not always help
- AI-synthesized faces are indistinguishable from real faces and more trustworthy, Sophie J. Nightingale, Hany Farid, PNAS, 2022
- people cannot tell if face is AI-generated
- Seeing is not always believing: Benchmarking Human and Model Perception of AI-Generated Images, Zeyu Lu, Di Huang, Lei Bai, Jingjing Qu, Chengyue Wu, Xihui Liu, Wanli Ouyang, NeurIPS, 2023
- accuracy detecting fake photorealistic image: human 60%, best open model 87%
- but model high false positive; best overall accuracy 83%
- 2 million fake image for model benchmark
- accuracy detecting fake photorealistic image: human 60%, best open model 87%
- Organic or Diffused: Can We Distinguish Human Art from AI-generated Images?, Anna Yoo Jeong Ha, Josephine Passananti, Ronik Bhaskar, Shawn Shan, Reid Southen, Haitao Zheng, Ben Y. Zhao, ACM CCS, 2024
- ML detector & human cannot tell if image is AI-generated
- ways to trick ML detector
- ML detector trained on specific generator not good at new generator
- human expert better than ordinary human
- Fake It Until You Break It: On the Adversarial Robustness of AI-generated Image Detectors, Sina Mavali, Jonas Ricker, David Pape, Yash Sharma, Asja Fischer, Lea Schönherr, arXiv, 2024
- perturbation can make forensic classifier useless
- best model DRCT-CLIP has 88% accuracy
- DRCT: Diffusion Reconstruction Contrastive Training towards Universal Detection of Diffusion Generated Images, Baoying Chen, Jishen Zeng, Jianquan Yang, Rui Yang, ICML, 2024
Anti-training
- GLAZE: Protecting Artists from Style Mimicry by Text-to-Image Models, Shawn Shan, Jenna Cryan, Emily Wenger, Haitao Zheng, Rana Hanocka, Ben Y. Zhao USENIX Security, 2023
- add noise to image to brick ML model from generating similar image
Adoption of C2PA-like standards
- Is The Web HTTP/2 Yet?, Matteo Varvello, Kyle Schomp, David Naylor, Jeremy Blackburn, Alessandro Finamore, Konstantina Papagiannaki, PAM, 2016
- crawl & track HTTP 2 usage
Last edited:
Peripheral Literature for C2PA
C2PA use case
- Community story: Pixelstream, CAI, 2022
- empower individual journalists to compete w/ established media by giving credibility
- version control: fork image, evolution tree
- How a voice cloning marketplace is using Content Credentials to fight misuse, CAI, 2024
- they use GlobalSign as certificate authority (CA)
- want everything to have C2PA just like HTTPS
- How we’re increasing transparency for gen AI content with the C2PA, Google, 2024
- show C2PA in image search result & ad
- Partnership on AI Unveils New Case Studies from Supporters of Synthetic Media Framework: Meta, Microsoft, Thorn, and Truepic
- How Truepic used disclosures to help authenticate cultural heritage imagery in conflict zones: Project Providence: gather evidence from image of attacks to Ukraine to prove war crime
- rotate certificate daily “for granular invalidation”
- hardware-backed keystore
- opt-in for various metadata for creator for privacy & safety
- importance to stay secure & credible
- future: election monitoring
- acknowledge C2PA need to be widely adopted & problem of metadata removal
- policies to come in place to mandate disclosure in AI output
- need to display info w/o clicking
- tiered AI content labeling, e.g., AI-generated vs AI-modified
- How Microsoft and LinkedIn gave users detailed context about media on the professional networking platform:
- LinkedIn shows “CR” watermark by images with C2PA
- use “synthetic media detectors” when C2PA is missing
- technically not verify, but know signer
- How Truepic used disclosures to help authenticate cultural heritage imagery in conflict zones: Project Providence: gather evidence from image of attacks to Ukraine to prove war crime
- Use of C2PA in real-world workflows, Brendan Quinn, Jay Li, David Beaulieu, Jonathan Dupras, Nigel Earnshaw, Charlie Halford, Gavin Peacock, Pia Blumenthal, IPTC Photo Metadata Conference 2022
- Azure Media Services use C2PA during video encoding (unclear what exactly)
- CBC/Radio-Canada use C2PA for news
- BBC JavaScript library to edit/show C2PA
- Ongoing by Tim Bray · C2PA
- public education of C2PA & attack & defense
- How Wrapt’s end-to-end platform protects creative workflows with Content Credentials
- platform to sign C2PA for content creator for intellectual right & charge them
C2PA implementation
- Truepic
- claims to do software-based on-device signing securely on smartphone
- secure boot & verify device integrity
- hardware-backed keystore on phone
- no implementation details
- need to sign up; ludicrous pricing ($499+/mon)
- claims to do software-based on-device signing securely on smartphone
- Panel 1: AI and Image Authenticity, Leonard Rosenthol, Dennis Walker, Neal Krawetz, Bofu Chen, Adobe, C2PA, Camera Bits, FotoForensics, Numbers Protocol, IPTC, 2024
- browser extension to find C2PA data from embedded watermark & fingerprint (photo search)
- disclosed watermark can be easily erased
- fingerprint can be forged
- metadata for “do not train”
- implementation bug: demo changing date w/o invalidating C2PA
- C2PA agnostic: work w/ cloud & blockchain
- trust list will include anyone w/ okay implementation
- browser extension to find C2PA data from embedded watermark & fingerprint (photo search)
- How Click Camera App Brings Content Credentials to Phones
- Click, 👍 free C2PA camera (photo + video) app on Android & iOS by Nodle
- proprietary app and ContentSign
- 👎 require Internet to sign, store on Ethereum blockchain
- 👎 no privacy: no way to choose what metadata to include; associate public key; everything on chain
- counter argument: no association between person & public key; can use approximate location
- no defense against photo of photo
- ❗ can post C2PA photo to public channel ⇒ reservoir of C2PA photo
- ❗ mention difficulty of scaling PKI & help w/ blockchain
- lie? blockchain reference does not imply same level of trust as certificate
- 👎 can verify by default, but cannot verify if using certificate trust list
- mention joining C2PA working group to integrate blockchain
- Three pillars of provenance that make up durable Content Credentials
- TrustMark: open-source watermark & removal (useless?)
- simple-c2pa
- SimpleC2PA Audio Credentials
- ProofMode app
- do not use hardware protection for private key
- self-signed certificate
- Capture Cam app by Numbers Protocol
- claim to preserve ownership by C2PA + blockchain + NFT
- company seems hacked up
- 👎 sign C2PA after capture after request
- 👎 no privacy: no way to choose what metadata to include; can see all photo of user if know one
- 👎 require Internet to sign; store on blockchain (their own)
- active open-source Capacitor app
- inactive open-source Android app repo
- Starling Lab Framework
- Stanford EE & USC Shoah Foundation
- blog from Filecoin Foundation for the Decentralized Web
- claim to use Numbers Protocol
- Inside Starling Lab, a moonshot project to preserve the world’s most important information - Fast Company
- claim blockchain is for preserving data
- 78 Days archive photo claim to use “Numbers Protocol” but show no C2PA in “verify”
- all verify link broken
Image metadata
- Secret message sharing using online social media, IEEE CNS, 2014
- hide message in pixels, survive image manipulation
Phone keystore security
- phones are claimed to have hardware-backed keystore considered secure for private key Android Keystore system | Security | Android Developers & Keychain data protection - Apple Support
Last edited:
C2PA Camera Apps Investigation
“Click”, “Capture Cam” and “ProofMode” in Peripheral Literature for C2PA. Photos taken:
| Click | Capture Cam | ProofMode |
|---|---|---|
| 1733499304 | bafybeiaq7b5fyime2l3lb6niajrmksfipe26r2rycxius3twog7vcarjma | IMG_4717 |
Signers and public key
Click issued a certificate through ContentSign for me, presumably by adding a reference on the blockchain.
$ c2patool --certs 1733499304.jpg | openssl x509 -text -noout
Certificate:
Data:
Version: 3 (0x2)
Serial Number: 7991087401548139538 (0x6ee60ba732604c12)
Signature Algorithm: ecdsa-with-SHA256
Issuer: CN=Click Camera, O=ContentSign by Nodle
Validity
Not Before: Dec 6 15:31:26 2024 GMT
Not After : Dec 6 15:31:26 2025 GMT
Subject: CN=0xF0Ed23507BC598b1eA0FdB7c31517B26538829F9, O=Click Camera
Subject Public Key Info:
Public Key Algorithm: id-ecPublicKey
Public-Key: (256 bit)
pub:
04:ad:da:20:bd:92:b7:95:e9:7c:82:0f:51:b6:79:
6b:35:4c:44:27:d1:04:83:f8:fa:10:84:40:8c:b1:
73:35:75:f8:59:1b:d9:f6:7a:ab:be:7d:90:21:4d:
c0:98:40:fd:5c:3a:ab:bf:48:5b:08:7d:2b:f7:3e:
87:3a:7b:f2:63
ASN1 OID: prime256v1
NIST CURVE: P-256
X509v3 extensions:
X509v3 Basic Constraints:
CA:FALSE
X509v3 Key Usage: critical
Digital Signature, Key Encipherment
X509v3 Extended Key Usage:
TLS Web Client Authentication, E-mail Protection
X509v3 Subject Key Identifier:
13:5D:2D:9D:71:F0:A5:D5:17:41:0E:79:29:C5:2C:35:13:1F:46:DC
X509v3 Authority Key Identifier:
keyid:4C:F9:B3:FD:D5:E6:6B:C3:0D:EB:2C:0E:53:AF:2B:22:30:B5:DA:0F
DirName:/O=Click App/CN=Click App ContentSign CA 1
serial:8C:DF:B9:CC:33:D1:F8:58:97:28:5C:95:14:C5:38:2D:CF:80:63
Signature Algorithm: ecdsa-with-SHA256
Signature Value:
30:46:02:21:00:8a:72:fe:22:a4:67:84:20:b8:90:e7:b9:2a:
36:b2:4a:bf:5d:f8:1a:56:f8:89:30:82:b8:0f:ab:6a:4a:ae:
c2:02:21:00:92:e4:ef:6f:2f:41:a0:54:81:19:f9:89:f1:3c:
ea:02:ef:11:4f:4b:0d:02:a6:68:6e:e3:72:14:63:fe:6e:81
- must have how changed C2PA verify works
Capture Cam seems to reuse its own pubkey w/ certificate issued by DigiCert.
$ c2patool --certs bafybeiaq7b5fyime2l3lb6niajrmksfipe26r2rycxius3twog7vcarjma.jpg | openssl x509 -text -noout
Certificate:
Data:
Version: 3 (0x2)
Serial Number:
0c:59:4a:96:f5:77:2e:e9:55:f3:02:4b:21:98:82:86
Signature Algorithm: sha256WithRSAEncryption
Issuer: C=US, O=DigiCert Inc, OU=www.digicert.com, CN=DigiCert Assured ID Client CA G2
Validity
Not Before: Feb 26 00:00:00 2024 GMT
Not After : Feb 26 23:59:59 2025 GMT
Subject: organizationIdentifier=NTRTW-82885990, C=TW, ST=Taipei City, O=Numbers Co., Ltd., SN=Chen, GN=Bofu, CN=Bofu Chen
Subject Public Key Info:
Public Key Algorithm: id-ecPublicKey
Public-Key: (384 bit)
pub:
04:c2:4e:fc:1a:84:99:0c:4e:43:03:40:87:ed:86:
96:a6:ed:14:22:99:dd:b6:86:e5:98:a1:30:6f:e0:
25:7d:71:08:78:86:ff:7e:68:d3:1d:a3:ac:43:67:
90:3e:dd:de:49:d1:5f:64:0e:92:7e:48:17:d2:ce:
cb:f2:a2:b1:e8:fd:08:81:78:6e:49:2c:b6:45:0b:
e5:a7:16:d4:87:ef:39:fd:e0:c3:1b:de:61:73:7b:
81:58:ec:bc:f5:d6:65
ASN1 OID: secp384r1
NIST CURVE: P-384
X509v3 extensions:
X509v3 Authority Key Identifier:
A5:62:20:50:DC:BB:5B:57:97:AD:23:8F:35:E2:54:6C:A9:7E:F9:4E
X509v3 Subject Key Identifier:
93:E5:50:21:D4:38:61:0C:C0:15:E3:17:BF:19:52:F6:96:FE:7F:D8
X509v3 Subject Alternative Name:
email:hi@numbersprotocol.io
X509v3 Certificate Policies:
Policy: 2.23.140.1.5.3.1
X509v3 Key Usage: critical
Digital Signature, Key Agreement
X509v3 Extended Key Usage:
E-mail Protection
X509v3 CRL Distribution Points:
Full Name:
URI:http://crl3.digicert.com/DigiCertAssuredIDClientCAG2.crl
Full Name:
URI:http://crl4.digicert.com/DigiCertAssuredIDClientCAG2.crl
Authority Information Access:
OCSP - URI:http://ocsp.digicert.com
CA Issuers - URI:http://cacerts.digicert.com/DigiCertAssuredIDClientCAG2.crt
Signature Algorithm: sha256WithRSAEncryption
Signature Value:
84:f6:67:53:cf:04:ee:05:8c:78:26:e1:2a:b4:66:39:e5:86:
60:0e:b8:dc:61:a3:83:86:2f:37:c1:39:26:df:3c:27:69:f0:
73:e2:0b:14:18:9c:16:78:58:75:10:c2:1e:71:2a:e1:41:73:
5c:04:2f:65:ec:a8:d7:d6:d5:7e:42:fa:9b:07:0a:5e:df:06:
14:50:52:8e:73:6f:12:58:ea:e9:10:2d:3c:93:ca:dd:2d:a7:
36:ff:1d:1a:4a:ab:01:98:97:de:37:a8:e4:58:78:d6:ea:77:
be:9f:00:92:1b:da:4d:e6:1e:c5:88:72:5e:9b:61:26:10:3f:
3d:67:26:35:4f:10:ef:e4:29:3d:5a:e2:72:d1:74:17:b3:a4:
21:b7:a9:87:79:1c:c8:cb:a2:7c:f4:2c:43:45:fe:67:f3:06:
a2:66:1d:c0:72:1f:2e:88:90:f2:5d:a8:29:73:9b:04:57:a4:
b3:5d:ba:da:f1:ea:5d:cb:99:28:8b:72:22:5c:93:8f:f3:18:
a5:09:5d:1a:06:2f:47:cb:c9:4d:b7:70:b2:98:6a:92:19:6c:
94:27:24:10:c7:1a:a1:ff:93:e8:f3:73:75:09:24:bc:98:41:
f7:c1:85:d1:76:45:fc:71:1e:bd:0e:3f:fa:32:0e:c6:b8:b5:
9e:fc:b2:cb
- probably sign after upload, same as Photoshop
- single point of failure
ProofMode issued a certificate for me.
$ c2patool --certs IMG_4717.JPG | openssl x509 -text -noout
Certificate:
Data:
Version: 3 (0x2)
Serial Number:
f7:13:e2:f6:79:17:45:63:f2:e5:ba:bd:75:b3:90:c8:37:9f:9e:cf
Signature Algorithm: ecdsa-with-SHA512
Issuer: CN=ProofMode-Root Offline Root CA, O=ProofMode-Root
Validity
Not Before: Dec 11 16:39:28 2024 GMT
Not After : Dec 11 16:39:28 2025 GMT
Subject: CN=ProofMode-User Content Credentials, O=ProofMode-User
Subject Public Key Info:
Public Key Algorithm: id-ecPublicKey
Public-Key: (256 bit)
pub:
04:ae:7a:c2:b2:1a:81:58:d6:d6:fd:30:32:56:d9:
5b:f1:69:ce:a9:48:c1:98:bf:99:78:97:00:ac:25:
3d:26:d4:fe:38:17:35:8a:98:38:f1:c2:f9:20:dc:
d3:b7:72:ca:a6:d4:dd:cd:b9:ce:46:c6:87:be:c1:
d1:a6:62:ef:4b
ASN1 OID: prime256v1
NIST CURVE: P-256
X509v3 extensions:
X509v3 Basic Constraints:
CA:FALSE
X509v3 Key Usage:
Digital Signature
X509v3 Subject Key Identifier:
8C:96:6B:28:0A:89:16:C1:2F:6C:32:98:12:23:99:3D:0C:8B:4E:42
X509v3 Authority Key Identifier:
8C:96:6B:28:0A:89:16:C1:2F:6C:32:98:12:23:99:3D:0C:8B:4E:42
X509v3 Extended Key Usage:
E-mail Protection
Signature Algorithm: ecdsa-with-SHA512
Signature Value:
30:45:02:21:00:99:cf:eb:9a:f1:76:c6:65:5c:44:b9:ae:e2:
a1:a0:69:d3:9d:57:d8:e8:7c:ef:e6:97:8e:be:dd:9d:5e:95:
57:02:20:54:10:b2:e7:9d:a1:f0:a4:43:a7:f1:5a:43:bd:9e:
3e:af:f2:85:cc:45:88:93:35:4d:28:80:3e:8a:b6:63:c0
- their own CA
Verify
“Verify” page is happy w/ Click & Capture Cam photo, but show The Content Credential issuer couldn’t be recognized. This file may not come from where it claims to. for ProofMode photo
c2patool by default is happy w/ all photo
c2patool not happy w/ Click & ProofMode photo after supplying Verify known certificate trust list, but happy w/ Capture Cam photoCommand output w/ my fork w/ select extra logging.
$ export C2PATOOL_TRUST_ANCHORS='https://contentcredentials.org/trust/anchors.pem'
$ export C2PATOOL_ALLOWED_LIST='https://contentcredentials.org/trust/allowed.sha256.txt'
$ export C2PATOOL_TRUST_CONFIG='https://contentcredentials.org/trust/store.cfg'
$ RUST_LOG=trace cargo r -- 1733499304.jpg trust
[2024-12-10T23:33:09Z DEBUG c2patool] Using trust anchors from Url(Url { scheme: "https", cannot_be_a_base: false, username: "", password: None, host: Some(Domain("contentcredentials.org")), port: None, path: "/trust/anchors.pem", query: None, fragment: None })
[2024-12-10T23:33:09Z DEBUG c2patool] Using allowed list from Url(Url { scheme: "https", cannot_be_a_base: false, username: "", password: None, host: Some(Domain("contentcredentials.org")), port: None, path: "/trust/allowed.sha256.txt", query: None, fragment: None })
[2024-12-10T23:33:09Z DEBUG c2patool] Using trust config from Url(Url { scheme: "https", cannot_be_a_base: false, username: "", password: None, host: Some(Domain("contentcredentials.org")), port: None, path: "/trust/store.cfg", query: None, fragment: None })
[2024-12-10T23:33:09Z TRACE c2pa::cose_validator] verify_cose: cert_check=true
[2024-12-10T23:33:09Z TRACE c2pa::cose_validator] check_cert: Extended key usage=ExtendedKeyUsage { any: false, server_auth: false, client_auth: true, code_signing: false, email_protection: true, time_stamping: false, ocsp_signing: false, other: [] }
[2024-12-10T23:33:09Z TRACE c2pa::cose_validator] check_trust: signing_time_epoc=Some(1733499285)
[2024-12-10T23:33:09Z TRACE c2pa::openssl::openssl_trust_handler] verify_trust: allowed_list={"igPZ4cQ+ElHb3Jagyp4o4LMVwkBicDWpm+oVuT9ctx0=", "QyrjnZlBhV+F2xAeNsb30KgVqD4QAQ+00rUtIfdXIzo=", "Z2O9JqjrmFVXI61XVcNlsodMzG1466HYQVyf+BkfWD8=", "5Obdx/KBgUxCpnrN1FVKm8TxKCGVUeJaFN7jh09SnOA=", "xXs/IWgBBAatf7AEbsXZNwgiV2zViVZFqbtqFgc0uXA=", "9heOFnvHjLz/iSNA37kqvnA40LDfSnr0UnyqZUECx7w=", "ad8hM2xz531vByVp8Hovpqv78qY0zV9zrLnRTYYdxB0=", "K9mtOEK4IaaomtzodP9jNUKxeWXb/VmZnYg7wCGG7r0=", "9qobPTVKRcOkldyUHSqN47xQN/V8tWrnW15DlUEco14=", "MFcAt2slSc/tA2sbjMNYRu26khsUmjqZ4xaQ+pfw4eI=", "SwJmKrvd0a561mMCdmrEhSGIj9tda8HjaTsTy8CCjRo=", "U2h3hfYy4GRIk7KCpu819C3nLko6A/NRn5xND2jYIng=", "vLyqdFQcIV1wOdjZvMD9rAQnvcrtOgjRRjxOF7HcyIw=", "fPAhO8QbeH8RUyk2673iIIoNFor6tZi8Fsshu07ieHI=", "AVVAhHuItD0yCby1WTAOFQOGPwiXwsgvTVbc/vlpSK0=", "rAnk74zT9+yxSkgHRFbaMC7mi/FprjBvnaeFGAroSac=", "o6uXNf1TKvSiNUL15CTvrGpfKEjCxpYrawNpYrfpkxc=", "J3TPotkZdPCd2iOdX4wmkudA821oz621eT/CAT2Zasc=", "UkQdwe7X8cO+Pj1Sb+VXxqkozHwXgC5YEqeiM42eA9w=", "czGRID6tAPpW8H+BtsxRZ38Y1cSRqebzg+MCjpBT1f4=", "OVkKb9nszYa6YpVdVfOEv481CrHaeaRnTbXM7zQC5KA=", "mfYmsZ1px3Bo+ZUvcttATyzVa9Pj8nNtHzsj99JgLwE=", "jko53/VSR3DMMb1nWmNx2+C+eh4U6CMV3BCw6tOgEVE=", "Jcv4yjJRVoH3zT76I7PzNY4cGDsT+jKNfRwu+mDLrpA=", "r8Ozpwn+U+j6fjWGiikhChvVXhGFZuMjyxgJq2S53EM=", "h72o9aSy/NjDN4dD8xdtlX28dm4c0ERupBgVuKCCltw=", "qskM23c5D9ZOelxRn8ZHfBPJVMPcpDmp53TAXUTGlVY=", "En07oVKGfm1psGJNDXqzHouLz3sjQ22uehYhHfLztQc=", "RYiv7AH1j4iSgkRM0m9CyFnvXPDZQbUTQW5C2RWlX7k=", "CaJnmoY4M0Rc4VO/v/v5diZCx/JlohwsDLm9RHOG6JI=", "28qM81MvRsS8Il4OhoYfzSQ1dnSIgepF9/553j2+MTc=", "eS7xBJoBUu4SJmCjg3gY4h1mlzwNGECqcBkaAMmlAGc=", "6wtSrm8Zm4xkIqkI9GB1lMhW90dzJVZPhOdSUL4lRTk=", "XCYKS7pr8jrDLX7NeUXrldi1pAsDm6aqovGCO4iPY0Q=", "opQNg+Qgg7MwDSY7PEcBCMpP5V9qJkF3BZp97MENFcQ=", "lVK0M1Sn1rq0KUvDqIo8/Py5MWBpb6t/T0SWgUWyWHE=", "xay/SRpiM24PoQ0V12PB8NmSdFt0X78ummtUmiUca7E=", "oAhDShFP/R0lcjRXxIaZLfLd9FrSLCmBe76XCbfssjE=", "9xnJg+oMcadqQCUtdEhBAt22rBInCbqyaaK3V3jaJmc=", "ONSIhEwHVB2K7a9RcPnBdcw2l+h4QHQLCA1OlSd7zFQ=", "QSa4RsH9d5KTNMx0WlXh+VHj5NAhcj6tHtluLmNySdM=", "I7jqB0noPFAMx3l69LFaThD+G2/WVivV8N4Z6EW/NFM="}
[2024-12-10T23:33:09Z TRACE c2pa::openssl::openssl_trust_handler] verify_trust: chain=[X509 { serial_number: "6EE60BA732604C12", signature_algorithm: ecdsa-with-SHA256, issuer: [commonName = "Click Camera", organizationName = "ContentSign by Nodle"], subject: [commonName = "0xF0Ed23507BC598b1eA0FdB7c31517B26538829F9", organizationName = "Click Camera"], not_before: Dec 6 15:31:26 2024 GMT, not_after: Dec 6 15:31:26 2025 GMT, public_key: PKey { algorithm: "EC" } }, X509 { serial_number: "8CDFB9CC33D1F85897285C9514C5382DCF8063", signature_algorithm: ecdsa-with-SHA256, issuer: [organizationName = "Click App", commonName = "Click App ContentSign CA 1"], subject: [countryName = "US", stateOrProvinceName = "California", organizationName = "ContentSign by Nodle"], not_before: Nov 7 19:26:02 2024 GMT, not_after: Nov 6 19:26:01 2029 GMT, public_key: PKey { algorithm: "EC" } }, X509 { serial_number: "A1B561309558D8ACD67233A634D6C610E18C4A", signature_algorithm: ecdsa-with-SHA384, issuer: [organizationName = "ContentSign by Nodle", commonName = "ContentSign Root CA"], subject: [organizationName = "Click App", commonName = "Click App ContentSign CA 1"], not_before: Mar 8 23:59:51 2024 GMT, not_after: Nov 17 23:23:31 2033 GMT, public_key: PKey { algorithm: "EC" } }, X509 { serial_number: "1241A148F08412DA61BDB3A67C94491AFFDFDD", signature_algorithm: ecdsa-with-SHA384, issuer: [organizationName = "ContentSign by Nodle", commonName = "ContentSign Root CA"], subject: [organizationName = "ContentSign by Nodle", commonName = "ContentSign Root CA"], not_before: Nov 20 23:23:32 2023 GMT, not_after: Nov 17 23:23:31 2033 GMT, public_key: PKey { algorithm: "EC" } }]
{
"active_manifest": "intergalactic network inc:urn:uuid:cc50e95f-5031-44b6-917b-7c51172e67e3",
"manifests": {
"intergalactic network inc:urn:uuid:cc50e95f-5031-44b6-917b-7c51172e67e3": {
"claim_generator": "Click App c2pa-rs/0.28.5",
"claim_generator_info": [
{
"name": "c2pa-mini-rs",
"version": "0.1.0"
}
],
"title": "Authentic Content",
"format": "image/jpeg",
"instance_id": "xmp:iid:62f2721e-af32-4b92-95e5-366032f779b3",
"ingredients": [],
"assertions": [
{
"label": "stds.schema-org.CreativeWork",
"data": {
"@context": "http://schema.org/",
"@type": "CreativeWork",
"author": [
{
"@type": "Person",
"name": "0xF0Ed23507BC598b1eA0FdB7c31517B26538829F9"
},
{
"@id": "https://clickapp.com/zk/account/0xF0Ed23507BC598b1eA0FdB7c31517B26538829F9",
"@type": "Person",
"name": "Click"
},
{
"@id": "https://era.zksync.network/address/0xF0Ed23507BC598b1eA0FdB7c31517B26538829F9",
"@type": "Person",
"name": "Blockchain Record"
}
]
},
"kind": "Json"
},
{
"label": "com.nodle.chain",
"data": {
"address": "0xF0Ed23507BC598b1eA0FdB7c31517B26538829F9",
"block_header": "0x7eff56d6f32e1dcb2e62702705e5f632fe37a2515d2265dcc80549b129796ac0"
}
},
{
"label": "stds.exif",
"data": {
"@context": {
"dc": "http://purl.org/dc/elements/1.1/",
"exif": "http://ns.adobe.com/exif/1.0/",
"exifEX": "http://cipa.jp/exif/2.32/",
"rdf": "http://www.w3.org/1999/02/22-rdf-syntax-ns#",
"tiff": "http://ns.adobe.com/tiff/1.0/",
"xmp": "http://ns.adobe.com/xap/1.0/"
},
"exif:GPSLatitude": "33 deg 59' 21.47 N",
"exif:ApertureValue": "1.6",
"exif:GPSLongitude": "118 deg 21' 16.58 W",
"tiff:Make": "Apple",
"exif:GPSAltitude": "0.00",
"exif:GPSRadius": "approximate",
"exif:FileType": "JPEG",
"exif:DateTimeOriginal": "2024-12-06T07:34:45.0-08:00",
"exif:FocalLength": "5.1",
"exifEX:LensMake": "Apple",
"exif:FileSize": "1.31 MB",
"exif:ImageSize": "4032 x 3024",
"exif:ExposureTime": "1/60",
"exif:Megapixels": 12.2,
"exif:ExposureBiasValue": "0",
"exifEX:LensModel": "iPhone 13 mini back camera 5.1mm f/1.6",
"tiff:Model": "iPhone 13 mini",
"exif:ExposureProgram": 2.0
},
"kind": "Json"
}
],
"signature_info": {
"alg": "Es256",
"issuer": "Click Camera",
"cert_serial_number": "7991087401548139538",
"time": "2024-12-06T15:34:45+00:00"
},
"label": "intergalactic network inc:urn:uuid:cc50e95f-5031-44b6-917b-7c51172e67e3"
}
},
"validation_status": [
{
"code": "signingCredential.untrusted",
"url": "Cose_Sign1",
"explanation": "signing certificate untrusted"
},
{
"code": "general.error",
"url": "self#jumbf=/c2pa/intergalactic network inc:urn:uuid:cc50e95f-5031-44b6-917b-7c51172e67e3/c2pa.signature",
"explanation": "claim signature is not valid"
}
]
}
$ RUST_LOG=trace cargo r -- bafybeiaq7b5fyime2l3lb6niajrmksfipe26r2rycxius3twog7vcarjma.jpg trust
[2024-12-10T23:33:26Z DEBUG c2patool] Using trust anchors from Url(Url { scheme: "https", cannot_be_a_base: false, username: "", password: None, host: Some(Domain("contentcredentials.org")), port: None, path: "/trust/anchors.pem", query: None, fragment: None })
[2024-12-10T23:33:26Z DEBUG c2patool] Using allowed list from Url(Url { scheme: "https", cannot_be_a_base: false, username: "", password: None, host: Some(Domain("contentcredentials.org")), port: None, path: "/trust/allowed.sha256.txt", query: None, fragment: None })
[2024-12-10T23:33:26Z DEBUG c2patool] Using trust config from Url(Url { scheme: "https", cannot_be_a_base: false, username: "", password: None, host: Some(Domain("contentcredentials.org")), port: None, path: "/trust/store.cfg", query: None, fragment: None })
[2024-12-10T23:33:26Z TRACE c2pa::cose_validator] verify_cose: cert_check=true
[2024-12-10T23:33:26Z TRACE c2pa::cose_validator] check_cert: Extended key usage=ExtendedKeyUsage { any: false, server_auth: false, client_auth: false, code_signing: false, email_protection: true, time_stamping: false, ocsp_signing: false, other: [] }
[2024-12-10T23:33:26Z TRACE c2pa::cose_validator] check_trust: signing_time_epoc=Some(1733680070)
[2024-12-10T23:33:26Z TRACE c2pa::openssl::openssl_trust_handler] verify_trust: allowed_list={"RYiv7AH1j4iSgkRM0m9CyFnvXPDZQbUTQW5C2RWlX7k=", "h72o9aSy/NjDN4dD8xdtlX28dm4c0ERupBgVuKCCltw=", "AVVAhHuItD0yCby1WTAOFQOGPwiXwsgvTVbc/vlpSK0=", "En07oVKGfm1psGJNDXqzHouLz3sjQ22uehYhHfLztQc=", "K9mtOEK4IaaomtzodP9jNUKxeWXb/VmZnYg7wCGG7r0=", "igPZ4cQ+ElHb3Jagyp4o4LMVwkBicDWpm+oVuT9ctx0=", "jko53/VSR3DMMb1nWmNx2+C+eh4U6CMV3BCw6tOgEVE=", "I7jqB0noPFAMx3l69LFaThD+G2/WVivV8N4Z6EW/NFM=", "MFcAt2slSc/tA2sbjMNYRu26khsUmjqZ4xaQ+pfw4eI=", "r8Ozpwn+U+j6fjWGiikhChvVXhGFZuMjyxgJq2S53EM=", "o6uXNf1TKvSiNUL15CTvrGpfKEjCxpYrawNpYrfpkxc=", "9qobPTVKRcOkldyUHSqN47xQN/V8tWrnW15DlUEco14=", "5Obdx/KBgUxCpnrN1FVKm8TxKCGVUeJaFN7jh09SnOA=", "ONSIhEwHVB2K7a9RcPnBdcw2l+h4QHQLCA1OlSd7zFQ=", "6wtSrm8Zm4xkIqkI9GB1lMhW90dzJVZPhOdSUL4lRTk=", "OVkKb9nszYa6YpVdVfOEv481CrHaeaRnTbXM7zQC5KA=", "QyrjnZlBhV+F2xAeNsb30KgVqD4QAQ+00rUtIfdXIzo=", "xay/SRpiM24PoQ0V12PB8NmSdFt0X78ummtUmiUca7E=", "U2h3hfYy4GRIk7KCpu819C3nLko6A/NRn5xND2jYIng=", "QSa4RsH9d5KTNMx0WlXh+VHj5NAhcj6tHtluLmNySdM=", "9xnJg+oMcadqQCUtdEhBAt22rBInCbqyaaK3V3jaJmc=", "eS7xBJoBUu4SJmCjg3gY4h1mlzwNGECqcBkaAMmlAGc=", "Z2O9JqjrmFVXI61XVcNlsodMzG1466HYQVyf+BkfWD8=", "xXs/IWgBBAatf7AEbsXZNwgiV2zViVZFqbtqFgc0uXA=", "9heOFnvHjLz/iSNA37kqvnA40LDfSnr0UnyqZUECx7w=", "Jcv4yjJRVoH3zT76I7PzNY4cGDsT+jKNfRwu+mDLrpA=", "rAnk74zT9+yxSkgHRFbaMC7mi/FprjBvnaeFGAroSac=", "CaJnmoY4M0Rc4VO/v/v5diZCx/JlohwsDLm9RHOG6JI=", "28qM81MvRsS8Il4OhoYfzSQ1dnSIgepF9/553j2+MTc=", "lVK0M1Sn1rq0KUvDqIo8/Py5MWBpb6t/T0SWgUWyWHE=", "fPAhO8QbeH8RUyk2673iIIoNFor6tZi8Fsshu07ieHI=", "vLyqdFQcIV1wOdjZvMD9rAQnvcrtOgjRRjxOF7HcyIw=", "UkQdwe7X8cO+Pj1Sb+VXxqkozHwXgC5YEqeiM42eA9w=", "XCYKS7pr8jrDLX7NeUXrldi1pAsDm6aqovGCO4iPY0Q=", "opQNg+Qgg7MwDSY7PEcBCMpP5V9qJkF3BZp97MENFcQ=", "J3TPotkZdPCd2iOdX4wmkudA821oz621eT/CAT2Zasc=", "ad8hM2xz531vByVp8Hovpqv78qY0zV9zrLnRTYYdxB0=", "SwJmKrvd0a561mMCdmrEhSGIj9tda8HjaTsTy8CCjRo=", "czGRID6tAPpW8H+BtsxRZ38Y1cSRqebzg+MCjpBT1f4=", "oAhDShFP/R0lcjRXxIaZLfLd9FrSLCmBe76XCbfssjE=", "mfYmsZ1px3Bo+ZUvcttATyzVa9Pj8nNtHzsj99JgLwE=", "qskM23c5D9ZOelxRn8ZHfBPJVMPcpDmp53TAXUTGlVY="}
[2024-12-10T23:33:26Z TRACE c2pa::openssl::openssl_trust_handler] verify_trust: allowed_list contains cert RYiv7AH1j4iSgkRM0m9CyFnvXPDZQbUTQW5C2RWlX7k=
{
"active_manifest": "numbersprotocol:urn:uuid:92583583-b457-4c09-bb89-756ee7951cc8",
"manifests": {
"numbersprotocol:urn:uuid:92583583-b457-4c09-bb89-756ee7951cc8": {
"claim_generator": "Numbers_Protocol c2patool/0.9.9 c2pa-rs/0.35.1",
"title": "bafybeicbxmbnzynhvoxr3x5mfly4ptc3rpeqbm7qokm4s3rbjpq6cmijsm",
"format": "image/jpeg",
"instance_id": "xmp:iid:bca14d74-857d-45f0-9c64-a01996492e43",
"thumbnail": {
"format": "image/jpeg",
"identifier": "self#jumbf=/c2pa/numbersprotocol:urn:uuid:92583583-b457-4c09-bb89-756ee7951cc8/c2pa.assertions/c2pa.thumbnail.claim.jpeg"
},
"ingredients": [],
"assertions": [
{
"label": "stds.schema-org.CreativeWork",
"data": {
"@context": "https://schema.org",
"@type": "CreativeWork",
"author": [
{
"@type": "Person",
"name": "ra25"
}
],
"identifier": "bafybeicbxmbnzynhvoxr3x5mfly4ptc3rpeqbm7qokm4s3rbjpq6cmijsm",
"url": "https://verify.numbersprotocol.io/asset-profile/bafybeicbxmbnzynhvoxr3x5mfly4ptc3rpeqbm7qokm4s3rbjpq6cmijsm",
"locationCreated": "34.021771068073, -118.290588268337",
"dateCreated": "2024-12-08T17:46:21Z"
},
"kind": "Json"
},
{
"label": "c2pa.actions",
"data": {
"actions": [
{
"action": "c2pa.opened",
"digitalSourceType": "http://cv.iptc.org/newscodes/digitalsourcetype/digitalCapture"
}
]
}
},
{
"label": "numbers.assetTree",
"data": {
"assetTreeCid": "bafkreifitnkbzucemuguagkc4zxg3ywvenaqbheqo4joepwxonc35ckphe",
"assetTreeSha256": "a89b541cd044650d401942e66e6de2d52341009c907712e23ed77345be894f39",
"assetTreeSignature": "0xb95262c7947c87b5de6b26d4233eb66ca325634dec7df4729e758172231ad21b303c64c2d9073fbc1b4960a23dda9f7600ecab7b66d91548a99622e3c631c6331b",
"committer": "0x51130dB91B91377A24d6Ebeb2a5fC02748b53ce1"
}
},
{
"label": "numbers.integrity.json",
"data": {
"nid": "bafybeicbxmbnzynhvoxr3x5mfly4ptc3rpeqbm7qokm4s3rbjpq6cmijsm",
"publicKey": "ra25",
"mediaHash": "f05977bbc4454dc596d9a1bb6b83261992fa545e26dde1716ccbcae39c85c007",
"captureTimestamp": 1733679964
}
},
{
"label": "stds.exif",
"data": {
"@context": {
"EXIF": "http://ns.adobe.com/EXIF/1.0/",
"EXIFEX": "http://cipa.jp/EXIF/2.32/",
"dc": "http://purl.org/dc/elements/1.1/",
"rdf": "http://www.w3.org/1999/02/22-rdf-syntax-ns#",
"tiff": "http://ns.adobe.com/tiff/1.0/",
"xmp": "http://ns.adobe.com/xap/1.0/"
},
"EXIF:DateTimeOriginal": "2024-12-08T17:46:04Z",
"EXIF:GPSTimeStamp": "2024-12-08T17:46:04Z",
"EXIF:GPSLongitude": "-118.290588268337",
"EXIF:GPSLatitude": "34.021771068073"
},
"kind": "Json"
}
],
"signature_info": {
"alg": "Es384",
"issuer": "Numbers Co., Ltd.",
"cert_serial_number": "16414363228331548608953470346493198982",
"time": "2024-12-08T17:47:50+00:00"
},
"label": "numbersprotocol:urn:uuid:92583583-b457-4c09-bb89-756ee7951cc8"
}
}
}
$ RUST_LOG=trace cargo r -- IMG_4717.JPG trust
[2024-12-11T18:10:15Z DEBUG c2patool] Using trust anchors from Url(Url { scheme: "https", cannot_be_a_base: false, username: "", password: None, host: Some(Domain("contentcredentials.org")), port: None, path: "/trust/anchors.pem", query: None, fragment: None })
[2024-12-11T18:10:16Z DEBUG c2patool] Using allowed list from Url(Url { scheme: "https", cannot_be_a_base: false, username: "", password: None, host: Some(Domain("contentcredentials.org")), port: None, path: "/trust/allowed.sha256.txt", query: None, fragment: None })
[2024-12-11T18:10:16Z TRACE c2pa::cose_validator] verify_cose: cert_check=true
[2024-12-11T18:10:16Z TRACE c2pa::cose_validator] check_cert: Extended key usage=ExtendedKeyUsage { any: false, server_auth: false, client_auth: false, code_signing: false, email_protection: true, time_stamping: false, ocsp_signing: false, other: [] }
[2024-12-11T18:10:16Z TRACE c2pa::cose_validator] check_trust: signing_time_epoc=Some(1733935458)
[2024-12-11T18:10:16Z TRACE c2pa::openssl::openssl_trust_handler] verify_trust: allowed_list={"eS7xBJoBUu4SJmCjg3gY4h1mlzwNGECqcBkaAMmlAGc=", "RYiv7AH1j4iSgkRM0m9CyFnvXPDZQbUTQW5C2RWlX7k=", "czGRID6tAPpW8H+BtsxRZ38Y1cSRqebzg+MCjpBT1f4=", "MFcAt2slSc/tA2sbjMNYRu26khsUmjqZ4xaQ+pfw4eI=", "igPZ4cQ+ElHb3Jagyp4o4LMVwkBicDWpm+oVuT9ctx0=", "U2h3hfYy4GRIk7KCpu819C3nLko6A/NRn5xND2jYIng=", "5Obdx/KBgUxCpnrN1FVKm8TxKCGVUeJaFN7jh09SnOA=", "SwJmKrvd0a561mMCdmrEhSGIj9tda8HjaTsTy8CCjRo=", "J3TPotkZdPCd2iOdX4wmkudA821oz621eT/CAT2Zasc=", "qskM23c5D9ZOelxRn8ZHfBPJVMPcpDmp53TAXUTGlVY=", "Z2O9JqjrmFVXI61XVcNlsodMzG1466HYQVyf+BkfWD8=", "28qM81MvRsS8Il4OhoYfzSQ1dnSIgepF9/553j2+MTc=", "oAhDShFP/R0lcjRXxIaZLfLd9FrSLCmBe76XCbfssjE=", "lVK0M1Sn1rq0KUvDqIo8/Py5MWBpb6t/T0SWgUWyWHE=", "ad8hM2xz531vByVp8Hovpqv78qY0zV9zrLnRTYYdxB0=", "r8Ozpwn+U+j6fjWGiikhChvVXhGFZuMjyxgJq2S53EM=", "h72o9aSy/NjDN4dD8xdtlX28dm4c0ERupBgVuKCCltw=", "vLyqdFQcIV1wOdjZvMD9rAQnvcrtOgjRRjxOF7HcyIw=", "XCYKS7pr8jrDLX7NeUXrldi1pAsDm6aqovGCO4iPY0Q=", "fPAhO8QbeH8RUyk2673iIIoNFor6tZi8Fsshu07ieHI=", "xXs/IWgBBAatf7AEbsXZNwgiV2zViVZFqbtqFgc0uXA=", "9qobPTVKRcOkldyUHSqN47xQN/V8tWrnW15DlUEco14=", "En07oVKGfm1psGJNDXqzHouLz3sjQ22uehYhHfLztQc=", "QSa4RsH9d5KTNMx0WlXh+VHj5NAhcj6tHtluLmNySdM=", "I7jqB0noPFAMx3l69LFaThD+G2/WVivV8N4Z6EW/NFM=", "UkQdwe7X8cO+Pj1Sb+VXxqkozHwXgC5YEqeiM42eA9w=", "OVkKb9nszYa6YpVdVfOEv481CrHaeaRnTbXM7zQC5KA=", "CaJnmoY4M0Rc4VO/v/v5diZCx/JlohwsDLm9RHOG6JI=", "K9mtOEK4IaaomtzodP9jNUKxeWXb/VmZnYg7wCGG7r0=", "Jcv4yjJRVoH3zT76I7PzNY4cGDsT+jKNfRwu+mDLrpA=", "xay/SRpiM24PoQ0V12PB8NmSdFt0X78ummtUmiUca7E=", "AVVAhHuItD0yCby1WTAOFQOGPwiXwsgvTVbc/vlpSK0=", "rAnk74zT9+yxSkgHRFbaMC7mi/FprjBvnaeFGAroSac=", "6wtSrm8Zm4xkIqkI9GB1lMhW90dzJVZPhOdSUL4lRTk=", "jko53/VSR3DMMb1nWmNx2+C+eh4U6CMV3BCw6tOgEVE=", "9xnJg+oMcadqQCUtdEhBAt22rBInCbqyaaK3V3jaJmc=", "o6uXNf1TKvSiNUL15CTvrGpfKEjCxpYrawNpYrfpkxc=", "ONSIhEwHVB2K7a9RcPnBdcw2l+h4QHQLCA1OlSd7zFQ=", "mfYmsZ1px3Bo+ZUvcttATyzVa9Pj8nNtHzsj99JgLwE=", "9heOFnvHjLz/iSNA37kqvnA40LDfSnr0UnyqZUECx7w=", "opQNg+Qgg7MwDSY7PEcBCMpP5V9qJkF3BZp97MENFcQ=", "QyrjnZlBhV+F2xAeNsb30KgVqD4QAQ+00rUtIfdXIzo="}
[2024-12-11T18:10:16Z TRACE c2pa::openssl::openssl_trust_handler] verify_trust: chain=[]
{
"active_manifest": "urn:uuid:c24dd69c-8c9b-4a0e-8469-b93ceb93543f",
"manifests": {
"urn:uuid:c24dd69c-8c9b-4a0e-8469-b93ceb93543f": {
"claim_generator": "ProofMode/43 c2pa-rs/0.28.4",
"title": "1733935453751_c2pa.jpg",
"format": "image/jpeg",
"instance_id": "xmp:iid:00fd7d9d-77d5-4180-88eb-2077b985d477",
"thumbnail": {
"format": "image/jpeg",
"identifier": "self#jumbf=/c2pa/urn:uuid:c24dd69c-8c9b-4a0e-8469-b93ceb93543f/c2pa.assertions/c2pa.thumbnail.claim.jpeg"
},
"ingredients": [
{
"title": "1733935453751.jpg",
"format": "image/jpeg",
"instance_id": "xmp:iid:c5ed606e-8b9f-4bd0-8eff-46a201f5d68f",
"thumbnail": {
"format": "image/jpeg",
"identifier": "self#jumbf=c2pa.assertions/c2pa.thumbnail.ingredient.jpeg"
},
"relationship": "parentOf"
}
],
"assertions": [
{
"label": "c2pa.actions",
"data": {
"actions": [
{
"action": "c2pa.created"
}
]
}
},
{
"label": "c2pa.ai_training",
"data": {
"constraintInfo": null,
"use": "notAllowed"
}
},
{
"label": "c2pa.ai_generative_training",
"data": {
"constraintInfo": null,
"use": "notAllowed"
}
},
{
"label": "c2pa.data_mining",
"data": {
"constraintInfo": null,
"use": "notAllowed"
}
},
{
"label": "c2pa.inference",
"data": {
"constraintInfo": null,
"use": "notAllowed"
}
},
{
"label": "stds.schema-org.CreativeWork",
"data": {
"@context": "https://schema.org",
"@type": "CreativeWork",
"author": [
{
"@context": "https://schema.org",
"@id": "https://keys.openpgp.org",
"@type": "Person",
"identifier": "ae1a4c380d43bfb2",
"name": "ae1a4c380d43bfb2"
}
]
},
"kind": "Json"
}
],
"signature_info": {
"alg": "Es256",
"issuer": "ProofMode-User",
"cert_serial_number": "1410564205799300702414624826233507026152462458575",
"time": "2024-12-11T16:44:18+00:00"
},
"label": "urn:uuid:c24dd69c-8c9b-4a0e-8469-b93ceb93543f"
}
},
"validation_status": [
{
"code": "signingCredential.untrusted",
"url": "Cose_Sign1",
"explanation": "signing certificate untrusted"
},
{
"code": "general.error",
"url": "self#jumbf=/c2pa/urn:uuid:c24dd69c-8c9b-4a0e-8469-b93ceb93543f/c2pa.signature",
"explanation": "claim signature is not valid"
}
]
}
Last edited:
GenAI: Problems Introduced and Countermeasures
Deepfake
Accessible, scalable and performant
Disinformation
- Influence democratic process [4, 8, 11]
- Mislead public perception and belief through social media [4, 6, 8]
- Erode trust in media, democracy, authority, artwork, archival and legal evidence; “truth decay” [3, 9–11]
Countermeasures
- C2PA to attest content is real [1, 4, 11]
- 👍 Source and history [3, 6, 7, 10]
- Traceability and trust for not being tempered [5]
- 👎 Can be spoofed by taking photo with photo [12]
- 👎 Privacy: disclose sensitive information, but mechanisms exist [5]
- 👎 Can be stripped, is usually stripped [4]
- 👎 Need wide adoption [1, 4]
- 👎 Provenance does not imply trust [7]
- 👍 Source and history [3, 6, 7, 10]
- Preserve content on searchable blockchain [1, 2, 6, 8, 9]
- 👎 complex to implement; need wide adoption
- Watermarking by content creator [6]
- 👍 detect tempering, protect copyright
- JPEG Trust: “trust report” for user to evaluate trust [7]
- 👍 Directly address trust
- 👎 Implementation details unclear; privacy
Cybercrime
- Video conference scam targeting business [6, 9]
- Video promotion scam targeting individual [6, 9]
- Video romance scam [9]
- Personal attack: porn, fake speech, cyberbullying [6, 7]
- Identity theft [3, 7, 9]
Countermeasures
- Cloud provider limit bad actor [6]
Generation not for faking
- Bias in generation [3, 7]
- Intellectual property laundry [1, 3, 4]
- Not transparent or explainable, thus problem for regulation [3]
- Privacy and consent of training data [1, 3, 4]
Countermeasures
- Explainable AI (XAI) [3, 9]
- Bias mitigation and de-identification of training data [3]
- NFT of generation with authenticity metadata, ORA (Ownership, Rights, Attribution) [1, 4]
- Visual matching for generation [1]
General countermeasures
- Public awareness and education [6, 12]
- Detection
- Human technique [3]
- ML detection model, e.g., GAN
- 👍 Much more accurate than human [3]
- 👍 Can be improved constantly [12]
- 👎 Cannot outcompete generator [6, 9]
- Physiological signal analysis for video, e.g., blood flow [9]
- Multi-modal detection [9]
- Detection (cont.)
- Watermarking training data [3, 4]
- Watermarking generated content [9, 10]
- 👎 Can be stripped, tempered or faked [4, 10]
- Fingerprinting: search by perceived hash [1, 4]
- 👍 Recover stripped metadata; some resilience to tempering [4]
- 👎 Sensitive to editing [4]
- 👎 Need access to content database [4]
- 👎 Scalability and privacy concern [4]
- Similarity search (correlation) [4]
- 👎 May not reflect causality [4]
- Organizational effort: partnership [6]
- Legal framework and global standard [6, 9]
References
[1] Balan, K., Agarwal, S., Jenni, S., Parsons, A., Gilbert, A. and Collomosse, J. 2023. EKILA: Synthetic media provenance and attribution for generative art. Proceedings of the IEEE/CVF conference on computer vision and pattern recognition (2023), 913–922.
[2] Bureacă, E. and Aciobăniței, I. 2024. A blockchain blockchain-based framework for content provenance and authenticity. 2024 16th international conference on electronics, computers and artificial intelligence (ECAI) (2024), 1–5.
[3] Bushey, J. 2023. AI-generated images as an emergent record format. 2023 IEEE international conference on big data (BigData) (2023), 2020–2031.
[4] Collomosse, J. and Parsons, A. 2024. To authenticity, and beyond! Building safe and fair generative AI upon the three pillars of provenance. IEEE Computer Graphics and Applications. 44, 3 (2024), 82–90.
[5] Fotos, N. and Delgado, J. 2023. Ensuring privacy in provenance information for images. 2023 24th international conference on digital signal processing (DSP) (2023), 1–5.
[6] Kharvi, P.L. 2024. Understanding the impact of AI-generated deepfakes on public opinion, political discourse, and personal security in social media. IEEE Security & Privacy. (2024).
[7] Mo, J., Kang, X., Hu, Z., ZHou, H., Li, T. and Gu, X. 2023. Towards trustworthy digital media in the aigc era: An introduction to the upcoming IsoJpegTrust standard. IEEE Communications Standards Magazine. 7, 4 (2023), 2–5.
[8] Rainey, J., Elawady, M., Abhayartne, C. and Bhowmik, D. 2023. TRAIT: A trusted media distribution framework. 2023 24th international conference on digital signal processing (DSP) (2023), 1–5.
[9] Romero-Moreno, F. Deepfake fraud detection: Safeguarding trust in generative ai. Available at SSRN 5031627.
[10] Shoker, S., Reddie, A., Barrington, S., Booth, R., Brundage, M., Chahal, H., Depp, M., Drexel, B., Gupta, R., Favaro, M., et al. 2023. Confidence-building measures for artificial intelligence: Workshop proceedings. arXiv preprint arXiv:2308.00862. (2023).
[11] Strickland, E. 2024. This election year, look for content credentials: Media organizations combat deepfakes and disinformation with digital manifests. IEEE Spectrum. 61, 01 (2024), 24–27.
[12] Vilesov, A., Tian, Y., Sehatbakhsh, N. and Kadambi, A. 2024. Solutions to deepfakes: Can camera hardware, cryptography, and deep learning verify real images? arXiv preprint arXiv:2407.04169. (2024).
Last edited:
Removal Services
right to be forgotten: EU & California law
- find out if exercised when data breach occur
people search site
Data Defense: Evaluating People-Search Site Removal Services, Yael Grauer, Victoria Kauffman, Leigh Honeywell, Consumer Reports, 2024
- data removal services largely ineffective
- 35% removed after 4 month
- manual removal more effective
- 32 volunteer from New York & California
- data removal services largely ineffective
Last edited:
Static Analysis
Verus
- Verus: Verifying Rust Programs using Linear Ghost Types, Andrea Lattuada, Travis Hance, Chanhee Cho, Matthias Brun, Isitha Subasinghe, Yi Zhou, Jon Howell, Bryan Parno, Chris Hawblitzel, OOPSLA, 2023
- Rust type / borrow system already does part of verification work
- key idea: linear ghost types / permissions for low-level & concurrent code
- lets Verus verify tricky pointer / aliasing-heavy Rust more naturally
- proof / spec / exec all written in Rust-like syntax
- Verus: A Practical Foundation for Systems Verification, Andrea Lattuada, Travis Hance, Jay Bosamiya, Matthias Brun, Chanhee Cho, Hayley LeBlanc, Pranav Srinivasan, Reto Achermann, Tej Chajed, Chris Hawblitzel, Jon Howell, Jacob R. Lorch, Oded Padon, Bryan Parno, SOSP, 2024
- push Verus toward practical systems verification: concurrency, bit-level reasoning, unsafe Rust
- 6.1K LoC impl + 31K LoC proof across case studies
- faster / more automated than prior verifiers on their “millibenchmarks”
LLM + Verus
- AlphaVerus: Bootstrapping Formally Verified Code Generation through Self-Improving Translation and Treefinement, Pranjal Aggarwal, Bryan Parno, Sean Welleck, ICML, 2025
- translate Dafny → Verus to bootstrap training data / exemplars
- pipeline: exploration + treefinement + critique
- reward hacking a big issue; critique phase blocks things like
assume(false) - around 45% of DafnyBench translated to verified/aligned Verus programs
- Goedel-Architect: Streamlining Formal Theorem Proving with Blueprint Generation and Refinement, Jui-Hui Chung, Ziyang Cai, Zihao Li, Qishuo Yin, Rohit Agarwal, Simon Park, Rodrigo Porto, Narutatsu Ri, Ziran Yang, Shange Tang, Xingyu Dang, Hongzhou Lin, Mengdi Wang, Danqi Chen, Chi Jin, Liam H Fowl, Sanjeev Arora, arXiv, 2026
- 🤖 architecture signal, not a Verus systems result
- Lean 4 theorem proving on competition-math style benchmarks, not Rust / Verus systems verification
- core object is global blueprint graph: definitions / lemmas / declared deps → target theorem
- generator emits typed Lean skeleton and checks parse / type / acyclic / reachable graph through LeanArchitect
- graph validation should also require declared deps resolve and target theorem signature stays fixed
- prover closes lemma nodes in parallel using only declared parents, Lean compiler feedback, and Mathlib retrieval
- refinement rewrites whole blueprint from failed nodes
- false helper lemma: formal negation / counterexample diagnostic, then strengthen hypotheses, weaken conclusion, fix representation, drop node, or rewire dependents
- too-hard helper lemma: emit structured forfeit with attempts, stall point, and smaller helper-lemma decomposition
- solved nodes are reused only while signature and parent deps stay same
- result with open DeepSeek-V4-Flash: 99.2% pass@1 MiniF2F-test, 75.6% pass@1 PutnamBench
- with natural-language proof seed: 100% MiniF2F-test, 88.8% PutnamBench, 4/6 IMO 2025, 11/12 Putnam 2025, 3/6 USAMO 2026
- cost claim: PutnamBench pass@1 $294 total / $0.44 per problem, vs Hilbert ~$163k / ~$244
- 🤖 architecture signal, not a Verus systems result
- AutoVerus: Automated Proof Generation for Rust Code, Chenyuan Yang, Xuheng Li, Md Rakib Hossain Misu, Jianan Yao, Weidong Cui, Yeyun Gong, Chris Hawblitzel, Shuvendu Lahiri, Jacob R. Lorch, Shuai Lu, Fan Yang, Ziqiao Zhou, Shan Lu, OOPSLA, 2025
- agent pipeline mirrors human proof process: initial proof, refinement, verifier-error-guided debugging
- multiple agents, high temperature, multi-shot
- ~10 debugging agents for different errors
- using GPT-4o
- Lynette: AST analysis on Verus parser to provide fine-grained feedback
- checks; merge semi-correct generations; precise error
- focus mainly on handling loops (add invariants)
- interviewed multiple co-authors of Verus
- built VerusBench: 150 non-trivial proof tasks
- 137 / 150 solved; baseline only 67 / 150
- agent pipeline mirrors human proof process: initial proof, refinement, verifier-error-guided debugging
- ⭐️ VeruSAGE: A Study of Agent-Based Verification for Rust Systems, Chenyuan Yang, Natalie Neamtu, Chris Hawblitzel, Jacob R. Lorch, Shan Lu, arXiv, 2026
- continuation of AutoVerus
- transfer from toy tasks to real systems
- VeruSAGE-Bench: 849 tasks from 8 Verus-verified systems
- exclude VeriSMo bc it use fork of old Verus
- claim Anvil is largest Verus project
- system proof very different from VerusBench
- much more context, specs, helper lemmas; few loop
- spec almost as long as implementation and hard to read
- “cheat checker” built on Lynette
- to avoid
assume/admit/external_body/axiom
- to avoid
- provide
vstd - the longer the proof, the lower the success rate
- best model+agent combo solves >80%; Sonnet 4.5 can also help finish some human-incomplete proofs
- complicated agent orchestration + debug loop did worse than direct simple prompt for smarter LLMs
- 🤔 provide helper function signature for the most part
- agent should figure them out itself
- 🤔 extract all problems into 1 small file w/o codebase
- can agent do well directly on codebase just by better prompt?
- agent write useless proof code, as expected
- suck at certain pattern bc not trained on them
- VeriStruct: AI-assisted Automated Verification of Data-Structure Modules in Verus, Chuyue Sun, Yican Sun, Daneshvar Amrollahi, Ethan Zhang, Shuvendu Lahiri, Shan Lu, David Dill, Clark Barrett, arXiv, 2026
- goes beyond single fn proof to whole data-structure module
- need shared abstraction (
View) + type invariant + specs + proof code - planner decides which components to generate; repair stage fixes Verus syntax / semantic mistakes
- 10 / 11 benchmarks solved, 128 / 129 fn verified
- Reducing the Costs of Proof Synthesis on Rust Systems by Scaling Up a Seed Training Set, Nongyu Di, Tianyu Chen, Shan Lu, Shuai Lu, Yeyun Gong, Peng Cheng, Jacob R. Lorch, Yuan Yao, Xiaoxing Ma, arXiv, 2026
- goal: make Verus proof synthesis much cheaper than frontier model usage
- VeruSyn synthesizes 6.9M verified Rust+Verus programs + 4.5K CoT trajectories
- combine self-synthesis + tutorial-based synthesis + agent trajectories
- fine-tuned Qwen gets close to Sonnet 4.5 on VeruSAGE-Bench at a tiny fraction of the cost
- Automated Proof Generation for Rust Code via Self-Evolution, Tianyu Chen, Shuai Lu, Shan Lu, Yeyun Gong, Chenyuan Yang, Xuheng Li, Md Rakib Hossain Misu, Hao Yu, Nan Duan, Peng Cheng, Fan Yang, Shuvendu K Lahiri, Tao Xie, Lidong Zhou, ICLR, 2025
- SAFE: self-evolving loop for spec synthesis + proof synthesis + self-debugging on Verus errors
- built 19,017 specs + 9,706 verified Rust functions from 45,395 proof-friendly programs
- 52.52% accuracy on expert benchmark vs GPT-4o 14.39%
- self-debugging matters a lot; best setting gets 70.50% Accuracy@10
- KVerus: Scalable and Resilient Formal Verification Proof Generation for Rust Code, Yuwei Liu, Xinyi Wan, Yanhao Wang, Minghua Wang, Lin Huang, Tao Wei, arXiv, 2026
- says main issue is semantic-structural gap: proofs depend on module deps, lemmas, and changing Verus syntax
- retrieval-heavy system: dependency graph + lemma index + error-driven refinement
- 80.2% single-file success vs AutoVerus 56.9%; 51.0% on repo-level benchmarks vs 4.5% baseline
- on Asterinas, got upstream-accepted proofs for 23 previously unverified funcs
- Towards Repository-Level Program Verification with Large Language Models, Si Cheng Zhong, Xujie Si, LMPL workshop, 2025
- nice reminder that function-level VerusBench is too small / local
- introduces RVBench: 755 proof-completion tasks, 337 modules, 3,464 functions from 4 open-source Verus projects
- RAGVERUS uses retrieval over repo context / deps / examples
- reports large gains on old benchmarks and 27% relative gain on RVBench
🤖 LLM + system modeling
- 🤖 SysMoBench: Evaluating AI on Formally Modeling Complex Real-World Systems, Qian Cheng, Ruize Tang, Emilie Ma, Finn Hackett, Peiyang He, Yiming Su, Ivan Beschastnikh, Yu Huang, Xiaoxing Ma, Tianyin Xu, arXiv, 2026
- 🤖 benchmark for LLMs writing TLA+ system models from real code
- 🤖 11 concurrent / distributed artifacts: Asterinas locks, Etcd / Redis Raft, ZooKeeper FLE, Xline CURP, PGo systems
- 🤖 metrics: syntax, runtime, trace conformance, invariant correctness
- 🤖 conformance is the important bridge from generated spec to code
- 🤖 result: small lock specs mostly work, but real distributed systems break current LLMs
- 🤖 Etcd Raft basic modeling: only Claude-Sonnet-4 produced valid TLA+ and reached only 7.69% conformance
- 🤖 liveness is much harder than safety
- 🤖 paper reports 8.2% safety vs 41.9% liveness property violations
- 🤖 benchmark for LLMs writing TLA+ system models from real code
- 🤖 A. Jesse Jiryu Davis review of SysMoBench
- 🤖 useful reading: the benchmark is a spec-writing harness, not proof that agents can replace formal-methods engineers
- 🤖 critique: task definitions already encode much expert work
- 🤖 defining actions and scope may be most of the human intellectual job
- 🤖 open question: trace conformance plus model checking proves only subset relations among tested code behavior, spec behavior, and invariants
- 🤖 Multi-Grained Specifications for Distributed System Model Checking and Verification, Lingzhi Ouyang, Xudong Sun, Ruize Tang, Yu Huang, Madhav Jivrajani, Xiaoxing Ma, Tianyin Xu, EuroSys, 2025
- 🤖 source evidence: PDF, local extraction, source record
- 🤖 human takeaway 1 — TLA+ may be too slow when the specification covers everything
- 🤖 the concern does not transfer unchanged to verified Rust: TLC explicitly explores a model state space, whereas a Verus-like verified-Rust workflow generates verification conditions discharged by SMT
- 🤖 SMT is not free: contracts, invariants, ghost state, lemmas, solver timeouts, and proof maintenance can dominate; this paper does not measure Verus or SMT
- 🤖 paper evidence: the ZooKeeper TLA+ model could not finish in ten days (§1, p. 1); Table 5 reports a baseline with 2.27 billion states and no violation in 24 hours, versus 77,179 states and 11 seconds for a mixed-grained model (§5.2, p. 11)
- 🤖 human takeaway 2 — can a complete or near-complete distributed-system TLA+ project be converted wholesale into verified Rust
- 🤖 generally not as a mechanical or short-term migration: the authors say rewriting existing Java ZooKeeper with machine-checked proofs was “not realistic in the short term” (§1, p. 1), and say deductive verification cannot be directly applied to existing distributed systems (§7, pp. 13–14)
- 🤖 a clean-slate rewrite may be possible, but it is a new implementation and proof effort, not conversion; inference for VL: a credible path is hybrid and incremental—retain high-level TLA+ exploration, verify selected Rust components, and maintain an explicit correspondence layer
- 🤖 the paper’s own incremental work reused a baseline, added under-500-line specification deltas, and took under 40 person-hours for one expert (§4.3, p. 10); that evidence supports selective deepening, not wholesale porting
- 🤖 human takeaway 3 — TLA+-assisted projects often have specification/code mismatch because there is no programmatic binding
- 🤖 this supports the verified-Rust case: executable code, contracts, and proofs live in one Rust-like artifact, so code changes can invalidate the checked obligations instead of silently drifting from a separate model
- 🤖 the paper demonstrates the missing bridge directly: Remix needs developer-supplied mappings from model actions to code events, instruments those events, replays model traces, and compares model/code execution (§3.4–§3.5.3, pp. 7–9)
- 🤖 this is a strong argument for binding, not a claim that embedded contracts prove intent: the paper calls its conformance checking unsound and random, and a verified-Rust proof still establishes code against the supplied specification, not that the specification is adequate
- 🤖 synthesis: TLA+ and verified Rust are complementary cost and assurance points—TLA+ is useful for global protocol/state-space exploration, while verified Rust makes implementation-level contracts and code-to-proof binding harder to separate; a practical architecture can use both
Verus applications
- Vest: Verified, Secure, High-Performance Parsing and Serialization for Rust, Yi Cai, Pratap Singh, Zhengyao Lin, Jay Bosamiya, Joshua Gancher, Milijana Surbatovich, Bryan Parno, USENIX Security, 2026
- DSL + combinator library that generates verified Rust parsers / serializers on top of Verus
- notable extra guarantee: basic digital side-channel resistance
- verification in seconds, meant to be CI-friendly
- big compression of format specs: Bitcoin ~67 LoC vs ~2,000 baseline, TLS 500 vs ~7,000, Wasm 600 vs ~30,000
- 🤖 Rust TLS scope map
- 🤖 Vest is the recalled Verus work
- 🤖 verified TLS 1.3 handshake-message parser / serializer
- 🤖 not a complete verified TLS stack
- 🤖 Rustls is the deployed stack
- 🤖 testing, fuzzing, and a prior audit
- 🤖 no mechanical proof binding found for current production code
- 🤖 conditional reserve, not a current fast experiment
- 🤖 Bertie / Bert13 is the broader verified Rust TLS research stack
- 🤖 hax extraction to F*, ProVerif, and SSProve, not Verus
- 🤖 property-specific proof boundaries and application-owned certificate authentication
- 🤖 pre-release and explicitly not for production
- 🤖 direction: keep all three as prior art for the current launch
- 🤖 Vest already covers the narrow Verus format story
- 🤖 Rustls production binding is wider than a one-day arm
- 🤖 Bertie proof / production gaps are not a fast closure
- 🤖 Vest is the recalled Verus work
- Atmosphere: Towards Practical Verified Kernels in Rust, Xiangdong Chen, Zhaofeng Li, Lukas Mesicek, Vikram Narayanan, Anton Burtsev, KISV, 2023
- early “can Verus handle a real kernel?” paper
- minimal but practical microkernel; all code in Rust, prove refinement to high-level spec
- headline number: proof-to-code ratio 7.5:1, much lower than old kernel verification efforts
- Atmosphere: Practical Verified Kernels with Rust and Verus, Xiangdong Chen, Zhaofeng Li, Jerry Zhang, Vikram Narayanan, Anton Burtsev, SOSP, 2025
- follow-up makes Atmosphere look much more practical / mature
- 6K LoC exec + 20.1K proof, <2.5 person-years total effort
- proof-to-code ratio drops to 3.32:1; full verification in <20s
- IPC and ixgbe driver eval suggest verification did not destroy practicality
- VeriSMo: A Verified Security Module for Confidential VMs, Ziqiao Zhou, Anjali (single-name author), Weiteng Chen, Sishuai Gong, Chris Hawblitzel, Weidong Cui, OSDI, 2024
- first verified security module for confidential VMs (AMD SEV-SNP)
- verified for functional correctness + secure information flow + VM confidentiality / integrity
- key trick: 2-layer proof, one for malicious hypervisor interference, one for VeriSMo’s own concurrency
- similar performance to C impl; proofs exposed an overlooked AMD SVSM confidentiality requirement
Hybrid Rust verification
- A Hybrid Approach to Semi-automated Rust Verification, Sacha-Élie Ayoun, Xavier Denis, Petar Maksimović, Philippa Gardner, PLDI, 2025
- split the job: Creusot for safe Rust, Gillian-Rust for unsafe Rust
- main pitch is “real unsafe stdlib Rust” rather than proof-oriented reimplementation
- verifies LinkedList / Vec code from Rust stdlib with minor mods, often orders of magnitude faster than prior unsafe-Rust tools
- still proof-of-concept: gaps around closures, shared refs, concurrency, some Vec caveats
- Verifying the Rust Standard Library, Byron Cook, Remi Delmas, Zyad Hassan, Bart Jacobs, Ranjit Jhala, Rahul Kumar, Felipe R. Monteiro, Thanh Nguyen, Rebecca Rumbul, Michael Tautschnig, Celina Val, Carolyn Zech, NFM, 2026
- fact: largest Rust-stdlib verification campaign, not full std correctness
- paper says it is an open crowdsourced effort on a maintained fork, integrated into CI
- scope is absence of selected undefined-behavior classes, not functional correctness / liveness / security
- target surface: real
core,alloc, andstdcrates- snapshot has 33,955 functions
- paper says std has about 7,500 unsafe functions and 3,000 more safe functions that internally use unsafe code
- tools: Kani, ESBMC, VeriFast, Flux in CI
- Verus, Creusot, KRust, RAPx under review
- lesson: no single Rust verifier covers the whole std shape
- automatic harness result
- Autoharness generated 16,748 Kani harnesses
- 11,970 verified against Kani-supported UB classes
- 989 functions had formal function-contract proofs
- 295 automatic + 694 manual
- stronger but narrower result: VeriFast LinkedList proof
- directly verifies 19 pointer-heavy functions and implies 5 more
- establishes no UB for well-typed callers under its model
- also proves functional / semantic postconditions for covered linked-list operations
- has known aliasing limitations around mutable refs / boxes and reference validity
- limits
- Kani misses pointer-aliasing model violations, data races, invalid inline assembly, and some provenance-related UB
- generic functions are the largest skipped category: 9,635 skipped by Autoharness
- concurrency / relaxed memory, compiler intrinsics, and proof synchronization with six-week upstream Rust releases remain open
- 🤖 relevance to VL / VeruLaw
- this is evidence that real std-library proof work is moving from isolated papers to CI-backed engineering campaigns
- it is not evidence that “the entire Rust standard library is verified”
- it reinforces an assumption-carrying architecture: concrete implementation proofs should state which UB / functional properties they prove and which std / compiler / tool assumptions they spend
- abstract/spec proofs and concrete Rust proofs are different layers: std verification needs contracts, harnesses, models, and tool-specific annotations at the implementation boundary
- fact: largest Rust-stdlib verification campaign, not full std correctness
Testing + verification
- Property-Based Testing: Climbing the Stairway to Verification, Zilin Chen, Christine Rizkallah, Liam O’Connor, Partha Susarla, Gerwin Klein, Gernot Heiser, Gabriele Keller, SLE, 2022
- instead of ad-hoc QuickCheck properties, test refinement relation against executable spec
- 🤖 core property shape: if abstract input
iarelates to concrete inputic, then concrete output must relate to some allowed abstract output- deterministic spec:
R_X ia ic => R_Y (abs ia) (conc ic) - nondet spec:
R_X ia ic => exists oa in abs ia. R_Y oa (conc ic) - their
correshelper is basically this existential over spec results
- deterministic spec:
- 🤖 architecture mirrors proof stack
- hand-written Haskell executable spec plays the role of Isabelle/HOL functional spec
- Cogent compiler emits Haskell shallow embedding of implementation
- C ADTs are tested through Haskell FFI or replaced by mocks
- full binary-vs-spec testing is possible but usually too much state-space mismatch for their file-system setting
- 🤖 important trick: generate one middle-ground test value and project it to abstract + concrete representations
- avoids two independent generators where most pairs fail the input-refinement precondition
- domain-specific generators matter bc refinement properties have strong premises
- 🤖 nondeterminism is handled by finite executable nondeterminism or by explicit oracle inputs
- example: media / allocator failures become either small
NonDetresult sets or an oracle threaded into mocks - can test oracle-style spec and nondet spec against each other by enumerating finite oracles and comparing result sets
- example: media / allocator failures become either small
- 🤖 mocks are deliberately partial but observationally sufficient
- e.g. replace
ostore_readwith a map lookup + error oracle becausefsop_readpageonly observes returned object or error code - functional specs of lower modules become mocks for higher modules
- e.g. replace
- 🤖 modular testing caught bugs whole-system tests missed
- WordArray C code had invalid-input / corner-case bugs hidden by current callers
- specs had overly specific assumptions that were valid only for verified clients, not for the reusable library
fsop_readpagetesting exposed missing error cases in Haskell spec, which reflected a bug in the Isabelle/HOL spec
- 🤖 sells PBT as a continuum toward full proof, not all-or-nothing
- WordArray went from axiomatized → PBT-tested → formally verified
- tests survive code evolution better than proofs when spec stays same
- 🤖 design lesson: verification-friendly and PBT-friendly design coincide
- keep state explicit, small, and relevant
- avoid huge global states where random variation is mostly ignored
- executable specs are a communication interface between systems devs and proof engineers
- 🤖 for Verus + assumptions: direct analogue is assumption-backed boundary laws
- executable model / Rust reference impl / proptest generator tests the law before Verus proof spends it
assumeshould be represented as a named law with evidence, not hidden in proof code- useful for std / OS / hardware / crate boundaries Verus cannot or should not fully verify
- proof receipt should link each proved claim to the laws it spent and each law to PBT/fuzz/differential/runtime evidence
- generators should be law-aware, not pure type-aware, or most cases will miss the preconditions where the law is meaningful
- oracle/nondet split maps nicely to assumptions about alloc failure, clocks, scheduling, I/O, caches, retries, DB races
- if a bug falsifies a claim, walk claim → receipt → spent laws → weakest evidence / broadest scope / recent boundary change
Aeneas
mainly focus on Rust’s own soundness, rather than model checking
- Charon: An Analysis Framework for Rust, Son Ho, Guillaume Boisseau, Lucas Franceschino, Yoann Prak, Aymeric Fromherz, Jonathan Protzenko, CAV, 2025
- shared frontend / IR layer for Rust analysis tools
- gives analysis-friendly AST / CFG over rustc internals: ULLBC + LLBC
- used by Aeneas, Eurydice, a taint checker; can also reimplement Rudra
- Sound Borrow-Checking for Rust via Symbolic Semantics, Son Ho, Aymeric Fromherz, Jonathan Protzenko, ICFP, 2024
- formal semantics foundation for Aeneas / LLBC
- prove symbolic semantics really act like a borrow checker
- join op enables loops, so Aeneas can handle more realistic control flow
- Aeneas: Rust verification by functional translation, Son Ho, Jonathan Protzenko, ICFP, 2022
- lightweight Rust verification via functional translation instead of heavy memory reasoning
- focus on safe Rust subset: no unsafe / interior mutability
- std / external defs often need extra models
- translate LLBC to pure functional code; use “backward functions” to end borrows across calls
- case study: verified resizing hash table; claim productivity gains
Other
- How We Built Cedar: A Verification-Guided Approach, Craig Disselkoen, Aaron Eline, Shaobo He, Kyle Headley, Michael Hicks, Kesha Hietala, John Kastner, Anwar Mamat, Matt McCutchen, Neha Rungta, Bhakti Shah, Emina Torlak, Andrew Wells, FSE Companion, AWS, 2024
- verification-guided development
- executable Lean model + proofs
- check Rust impl against Lean with differential random testing
- also use property-based testing for unmodeled Rust parts
- direct verification of Rust not mature enough
- grouped critique only: lack std lib support, idiom limits, scaling, limited spec / property support
- see tool notes below for rough breakdown
- found 4 policy-validator bugs during proofs, plus 21 more bugs via DRT/PBT
- verification-guided development
Rust verification tools
- Aeneas
- active; translate safe Rust to Lean / Coq / HOL4 / F* via Charon
- nice if you want readable proof-assistant output instead of opaque IR
- limits: safe subset only; no unsafe / concurrency yet; std / external defs often need handwritten models
- Lean page says used in Microsoft’s SymCrypt → verified Rust effort
- Kani
- active AWS-backed bounded model checker; good for unsafe code / UB / panic / overflow checks
- proof-harness style w/
kani::any(); nice fit for CI-like checking - limits: bounded, may run out of resources; no concurrency support yet
- Creusot
- active deductive verifier; Rust → Coma / Why3
- limits: contracts / extern specs still needed; not full Rust yet
- used to verify CreuSAT SAT solver
- Verus
- active SMT-based verifier for low-level / systems Rust
- bigger recent ecosystem here for deeper systems verification; can reason about some unsafe patterns like raw ptrs
- limits: only subset of Rust + libs; proof / ghost style less idiomatic than normal Rust
- used in research + industry projects
- (likely dead) Prusti
- Viper-based prototype verifier for safe Rust w/ contracts
- limits: std / external lib specs often manual; prototype / subset of Rust
- ETH still lists it as under development, but latest GitHub release is 2023 AWS verify-rust-std effort
Idea: assumption-carrying verification
🧑 high-level:
- cannot prove everything, especially dependencies
- need to mark assumptions and verify base on them
- be like “law” in science
- use fuzzing/ simulation tests for confidence
- opposite to AutoVerus’ claim that
assumeshould not be in final proof
- integrate assumption correctness testing into proof
- when bug occur, need to backtrack to find which assumption is wrong
- DAG walk?
generated expansion:
- goal: regular development w/ coding agents, but new code comes w/ statically checked claims
- not “verify the whole codebase first”
- assume existing code + deps are correct at start, then make that assumption explicit at the boundary
- build on VeruSAGE result as proof-synthesis inner loop
- but optimize for normal repo development, not extracted proof task
- minimal specs: only write laws the new code actually spends
- avoid annotating entire dependency surface
- key object: assumption / law
- like scientific law: useful, scoped, test-backed, falsifiable
- fields: id, statement, scope, version, evidence, known falsifiers, dependent proofs
- examples: clock monotonicity, parser normalization, db uniqueness, retry idempotence, cache freshness window
- opposite to “no
assumein final proof” only at the wrong layer- should not hide
assumeinside proof code - but boundary models need explicit law-backed assumptions; otherwise assumptions still exist, just invisible
- should not hide
- agent workflow
- start w/ ordinary code, w/ verification in mind/docs
- proof agent / VeruSAGE-style loop proves local claims
- law agent extracts only missing assumptions needed by proof
- test agent turns each law into experiments: unit, property, fuzz, simulation, differential, runtime monitor
- proof receipt for every change
- claims proved
- laws spent
- new law: tests / monitors backing it
- document assumption debt: broad law, weak evidence, high fan-out, stale version, untested weird case
- tests become evidence, not proof
- confidence score, not soundness
- coverage should be law coverage: which tests exercise which law
- mutation / “mutant world” tests are especially valuable: non-monotonic clock, stale cache, reordered events, duplicate ids, dependency returns valid but adversarial values
- when bug occurs: assumption debugger
- bug falsifies claim
- claim points to proof receipt
- receipt points to laws
- laws point to evidence + code/dependency boundary
- rank suspects by static slice, dynamic trace, recent change, law fan-out, weak evidence
- use minimal hitting set / unsat-core-ish idea to find smallest wrong-law set explaining failure
- research demo
- pick 1 subsystem + 5-10 laws
- let coding agent make ordinary changes
- require proof receipts + law-linked tests
- inject bugs / mutants
- measure if system finds wrong assumption faster than grep / git bisect
🤖 Agent-added related work deepening (2026-05-24): repository-native Verus agents
Fact: the strongest recent evidence says verified-Rust proof generation is now mostly a repository-context problem, not a loop-invariant problem. VeruSAGE-Bench explicitly says its 849 tasks are extracted from “8 real-world Verus projects” and that tasks need “understanding dependencies originally defined across a large codebase” (https://github.com/microsoft/verus-proof-synthesis/blob/main/benchmarks/VeruSAGE-Bench/README.md). Its own comparison is the useful research signal: Verus-Bench tasks average ~30 LoC and 1.6 loops; VeruSAGE-Bench tasks average ~950 LoC, ~500 spec LoC, <0.1 loops, and 2.4 helper lemmas. This makes helper-lemma discovery, spec/interface recovery, and dependency retrieval more central than invariant templates.
Concrete systems/projects to anchor a paper:
microsoft/verus-proof-synthesis: the implementation/artifact for AutoVerus and VeruSAGE. It includesautoverus/,verusage/, Lynette utilities, and both Verus-Bench and VeruSAGE-Bench. Useful baseline because it exposes the agent/verifier loop and benchmark format rather than only paper numbers.verus-lang/verus: the verifier and standard library target. The README says Verus “statically checks that the executable Rust code will always satisfy the specifications” and can go beyond Rust’s type system for code that “manipulates raw pointers” (https://github.com/verus-lang/verus). This is the practical substrate, not just a proof language.- RVBench / RagVerus: repository-level retrieval baseline. The arXiv page says RepoVBench has 2,073 functions over 52 modules and 383 proof-completion tasks, while another RVBench version reports 755 tasks over 337 modules. Treat exact naming/versioning carefully; the stable takeaway is that repository indexing and dependency retrieval give measurable gains but still leave large gaps.
- KVerus: a retrieval-heavy proof-generation system. Its paper reports 80.2% single-file success and 51.0% repository-level success, and says the hard case is the “semantic-structural gap”: proofs depend on module dependencies, lemmas, and toolchain syntax drift (https://arxiv.org/html/2605.03822).
Inference: a good systems paper should not be “LLM writes Verus proofs”. That is already crowded. A stronger paper is a repository-native verification agent that keeps a live dependency/lemma/spec index, proposes missing helper signatures, uses Verus feedback as a typed environment signal, and evaluates proof maintainability under realistic code churn.
Concrete evaluation plan:
- Use VeruSAGE-Bench and RVBench/RepoVBench for comparability, but add at least one live-repository case where the agent runs in the original project instead of a single extracted file.
- Measure solved tasks, verifier calls, token cost, retrieved-context precision, helper-lemma discovery accuracy, and proof reviewability.
- Include an anti-cheating pass like VeruSAGE’s Lynette-based checker for
assume,admit,external_body, and axioms. - Compare against direct prompting, AutoVerus-style repair, RAG-only retrieval, and a smart coding-agent baseline with the same Verus wrapper.
Paper repository status: root PDFs for VeruSAGE and KVerus already exist in /hdd1/sichanghe/paper_collection. This agent could not add missing PDFs because that repository is readable but not writable by the agent account; ACL test failed with Permission denied at both the collection root and an existing per-paper directory. The available OCR convention is ocr_all.py, which runs marker_single over root PDFs not listed in done_ocr.txt; it was not practical or safe to run because the repository already has unrelated uncommitted OCR outputs and the agent cannot write new root PDFs.
🤖 Agent-added verification transfer (2026-06-07): web/L7 trusted boundary
- 🤖 Best transfer: verify small boundary components that decide what a web agent observed or was authorized to do: URL/header parsers, request/response normalizers, policy monitors, receipt validators, and transaction state machines.
- 🤖 Why this is research: the verified code becomes the trust base for agent evidence and action closure, so the contribution is not “use Verus”, but defining which boundary claims must be sound before receipts, taint, or L7 contracts mean anything.
- 🤖 Practical shape: combine Verus claims with named laws for unverified environment behavior, then back each law with fuzzing, property tests, differential tests, or runtime monitors. Bugs should trace from failed claim to spent laws and weakest evidence.
- 🤖 Anchors: VeruSAGE and KVerus for repo-level proof-agent state of the art; Vest for verified parsers/serializers; Atmosphere/VeriSMo for practical systems verification; PBT-as-verification-continuum for law evidence.
🤖 2026-07 follow-up: specification validity, grounded feedback, and joint search
🤖 delta from the existing notes
- the existing notes already establish that repository context, helper lemmas, and proof maintenance matter more than toy loop invariants
- the new evidence moves the bottleneck one layer earlier
- an accepted proof says the implementation refines a specification
- it does not show that the specification captures human intent
- the new systems pattern is a three-oracle loop
- verifier for proof validity
- tests, traces, mutants, or developer examples for specification intent
- performance and operational measurements for system utility
🤖 high-level implications for VL
- treat the specification as a fallible artifact with its own receipt
- record intent examples, rejected mutants, assumptions, version, and which claims depend on it
- invalidate dependent proofs when the specification or its evidence changes
- search jointly over code, proof, and representation
- IDS shows that changing data layout can make a stalled proof tractable
- a VL agent should backtrack across implementation boundaries instead of repeatedly repairing a fixed proof state
- ground repair in concrete behavior
- ExVerus turns verifier failures into validated counterexamples and then generalizes them into invariants
- this is stronger feedback than error text alone, but its validation is currently strongest for loop invariants
- use LLMs at semantic translation boundaries, not as final judges
- SymGPT and Trace let LLMs recover intent or compilable structure, then use symbolic or static analysis for the decision
- Scope’s direct-LLM comparison shows why a generated warning still needs an independently checkable witness
- retrieve proof context at multiple granularities
- VerusSeek reports gains from retrieving typed proof constructs rather than whole files or functions
- its 150-task VerusBench evaluation does not establish repository-scale retrieval, so VL should combine construct retrieval with the existing repository dependency index and evaluate both
- optimize synthetic proof data for diversity as well as validity
- a verifier filters invalid programs but does not prevent distribution collapse
- Formal Disco explicitly optimizes feature entropy and still finds that human code is more diverse on unoptimized proof-annotation structure
- separate evaluation gates
- specification quality, code behavior, proof validity, end-to-end alignment, repository integration, and maintenance under change are different outcomes
- VeriContest’s 5.29% best end-to-end result is not a systems result because its tasks are competitive-programming functions, not repositories
- keep system modeling separate from function contracts
- SysMoBench shows trace conformance and liveness fail even when small function-like models parse and run
- VL likely needs both a system model for global behavior and Verus claims for implementation-level obligations
- treat the specification as a fallible artifact with its own receipt
🤖 evidence tiers
- accepted top-conference papers
- SymGPT at OOPSLA 2026
- Expecto at PLDI 2026
- SysMoBench at ICLR 2026
- Scope at ASPLOS 2026
- related anchor IronSpec at OSDI 2024
- peer-reviewed but not a top-conference anchor
- VerusSeek at TASE 2026
- Trace in IEEE Transactions on Software Engineering 2026
- preprints as of 2026-07-19
- IDS, ExVerus, FM-Agent, the VeriFast study, VeriAct, Formal Disco, and VeriContest
- their numbers are useful hypotheses and baselines, not accepted results
- accepted top-conference papers
🤖 source-by-source evidence
- SymGPT, OOPSLA 2026
- short quote: “combining symbolic execution with the LLM significantly enhances the accuracy”
- method: GPT-5 translates ERC prose into a small rule DSL; generated constraints drive interprocedural symbolic execution
- scope: 132 rules from three ERC standards and 4,000 compilable contracts
- reported result: 5,783 violations and 122 false positives; direct GPT-5 found 152/159 curated ground-truth violations but produced 266 false positives
- uncertainty: analysis is unsound, return-value rules are unsupported, and false-negative review covered only 50 high-report contracts
- VL delta: an LLM-produced rule needs a typed intermediate form and a mechanically checkable witness before it enters a proof receipt
- Inductive Deductive Synthesis, preprint
- short quote: “writing the formal specification itself remains the largest open problem”
- method: alternating implementation synthesis and deductive proof with backtracking, audit, verifier feedback, and performance feedback
- scope: seven Rocq specifications for distributed key-value-store consistency
- reported result: verified implementations for 7/7 specifications versus 2/7 for each coding-agent baseline; average 6.8 hours and 0.04 per task for DeepSeek
- uncertainty: counterexample validation principally targets invariants; assertion and trigger failures can lack a well-defined behavioral witness
- VL delta: attach counterexamples and blocked-behavior summaries to proof receipts so future repairs can reuse failure knowledge
- VerusSeek, TASE 2026
- short quote: “retrieving coarse-grained entire files or functions introduces noise”
- method: split verified Verus into contracts, invariants, lemmas, proof blocks, and assertions; retrieve by type and expand context hierarchically
- reported result from the publisher abstract: 76.7% improvement over AutoVerus and 43.4% over RagVerus on 150 VerusBench tasks
- uncertainty: the full chapter was unavailable, so denominator, absolute success, ablations, and threats could not be independently checked
- VL delta: retain both a typed proof-construct index and repository-level dependency graph; evaluate retrieval precision rather than context size alone
- FM-Agent, preprint
- short quote: “Although FM-Agent cannot ensure soundness”
- method: infer a function’s expected behavior top-down from callers, reason compositionally against natural-language contracts, then generate tests
- scope: four agent-generated systems from 11K to 143K lines of code
- reported result: 522 newly reported bugs in about two days using 3.4 billion tokens
- uncertainty: there is no sound verifier or comparable formal-method baseline; current reasoning is sequential and the specifications remain natural language
- VL delta: caller-derived obligations are valuable candidates, but they should become typed, falsifiable laws before proofs spend them
- LLM-generated specifications for VeriFast, preprint
- short quote: “most errors (94%) come from LLMs’ mistakes in the domain-specific knowledge”
- method: eight prompt strategies, ten models, and three input forms over 303 C functions with separation-logic specifications
- reported result: 31.4% verification success overall; 51.2% on normal separation logic but about 12% on concurrency and loops
- uncertainty: one output per configuration, public source leakage, C and VeriFast only, and a benchmark derived mostly from already verified programs
- VL delta: expose symbolic heap state and tool-native repair actions instead of expecting a general model to reconstruct ownership bookkeeping from prose
- VeriAct, preprint
- short quote: “VR consistently overstates specification quality”
- method: Spec-Harness checks valid input-output pairs and rejects output mutants; an agent refines JML after both OpenJML and harness feedback
- reported result: verifier-accepted specifications often collapse under meaningful verification; VeriAct improves the meaningful rate by 5 and 12 percentage points on its two benchmarks
- uncertainty: the meaningful threshold is 0.5, evaluation uses at most five test pairs, and complex quantifiers and helper lemmas remain hard
- VL delta: never use verifier acceptance as the only specification-quality metric
- Expecto, PLDI 2026
- short quote: “starts from a maximally permissive specification”
- method: top-down DSL synthesis with informal typed helper definitions, tree search, SMT consistency checks, and, in the main experiment, three input-output examples
- reported result: 103/164 sound-and-complete HumanEval+ specifications and 59/127 on APPS; 42/501 useful Defects4J method specifications
- uncertainty: soundness is probabilistic over generated invalid outputs, and the DSL cannot directly express Java objects and methods
- VL delta: refine intent monotonically from permissive to discriminating, checking every partial specification against examples and non-vacuity
- SysMoBench, ICLR 2026 poster
- short quote: “software system intelligence, rather than code intelligence”
- method: grade generated TLA+ models on syntax, runtime coverage, trace conformance, and invariant correctness across 11 real systems
- reported result: small locks can score well, while Etcd Raft’s best basic model reached 7.69% conformance; 41.9% of liveness properties were violated
- new accepted-version detail: preliminary PAT and Alloy generation failed before behavioral evaluation, while simpler repair benchmarks scored well
- uncertainty: benchmark authors supply task scope and action hints; models reproduced known bugs in five systems but do not replace human models
- VL delta: require trace conformance and liveness checks above local Verus proofs
- Formal Disco, preprint
- short quote: “verifiers provide exactly the scalable quality signal that synthetic data generation needs”
- method: initiator, fixer, and extender workers share verified programs; iterative fine-tuning maximizes selected feature entropies
- reported result: fine-tuned Qwen 2.5-Coder reaches 43.0% VerusBench pass@1 versus 8.7% base and matches the reported Claude Opus 4.5 result
- uncertainty: entropy targets are hand chosen, external READMEs and docs are required to avoid collapse, and human annotation structures remain more diverse
- VL delta: measure diversity of lemmas, invariants, repository contexts, assumptions, and failure traces before training on verifier-filtered data
- Trace, IEEE TSE 2026
- short quote: “we do not directly employ LLMs for vulnerability detection”
- method: use an LLM to locate sensitive functions and complete unchanged snippets, then run AST, call-graph, CFG, and access-control analysis
- reported result: 14/15 CVEs, 89.2% precision on on-chain contracts, and 87.0% precision across 83 mostly non-compilable repositories
- uncertainty: Solidity access control only; 4/6 repository false positives came from LLM code modification and analysis truncates calls at depth three
- VL delta: a model may repair the analysis surface, but validation must prove that the original semantic slice stayed unchanged
- Scope, ASPLOS 2026
- short quote: “35 were confirmed as valid by Arm”
- method: parse the Arm RMM PDF, translate dependency-table conditions to Verus, and combine formal queries with rule-based consistency checks
- reported result: 35 confirmed specification bugs across evolving versions; 61.90% precision versus 1.52-8.00% for direct LLM review
- uncertainty: formal parsing covered 31/36 dependency-table cells and about 73% of commands; unsupported prose and syntax remain outside the model
- VL delta: make specification versions and coverage explicit in receipts; proof success outside the modeled slice must not imply whole-document validity
- VeriContest, preprint
- short quote: “end-to-end verifiable code generation is far from solved”
- method: 946 expert-reviewed Rust/Verus competitive-programming tasks with separate specification, code, proof, and end-to-end gates
- reported best pass@1: 92.18% code, 48.31% specification, 13.95% proof, and 5.29% end-to-end
- uncertainty: public contest contamination, function-level scope, excluded unsupported Rust and proofs, and no repository or systems behavior
- VL delta: use the task decomposition as a diagnostic baseline, then add live-repository, assumption, maintainability, and system-property gates
- related IronSpec, OSDI 2024
- short quote: “only as strong as their trusted specifications”
- method: automatic sanity checks, concrete SpecTesting Proofs, and mutation testing for Dafny specifications
- reported result: ten specification bugs across six real verified systems; 61 alive mutations included 13 quickly diagnosed intended behaviors
- uncertainty: final intent judgment remains human and large end-to-end proofs make mutation testing expensive
- VL delta: use spec mutants to focus human review and record the surviving behavior difference as evidence, not as an automatic verdict
- SymGPT, OOPSLA 2026
🤖 exact collection paths
- collection root:
/hdd1/sichanghe/paper_collection - unless labeled otherwise, each PDF below is at
<collection root>/<name>.pdf - each Markdown extraction or metadata directory is at
<collection root>/<name>/ SymGPT- Auditing Smart Contracts via Combining Symbolic Execution with Large Language Models, Shihao Xia, Mengting He, Shuai Shao, et al., OOPSLA, 2026Inductive Deductive Synthesis- Enabling AI to Generate Formally Verified Systems, Shubham Agarwal, Alexander Krentsel, Shu Liu, et al., arXiv, 2026ExVerus- Verus Proof Repair via Counterexample Reasoning, Jun Yang, Yuechun Sun, Yi Wu, et al., arXiv, 2026FM-Agent- Scaling Formal Methods to Large Systems via LLM-Based Hoare-Style Reasoning, Haoran Ding, Zhaoguo Wang, Haibo Chen, arXiv, 2026- publisher-abstract record only:
VerusSeek- Enhancing LLM-Based Proof Synthesis for Rust Programs via Semantic Chunking and Hierarchical Context Expansion, Yuchen Zhang, Cheng Wen, Zhiwu Xu, et al., TASE, 2026 An Empirical Study of LLM-Generated Specifications for VeriFast, Wen Fan, Minh Tran, Sanya Dod, et al., arXiv, 2026VeriAct- Beyond Verifiability -- Agentic Synthesis of Correct and Complete Formal Specifications, Md Rakib Hossain Misu, Iris Ma, Cristina V. Lopes, arXiv, 2026Expecto- Extracting Formal Specifications from Natural Language Description for Trustworthy Oracles, Dongjae Lee, Kihong Heo, PLDI, 2026SysMoBench- Evaluating AI on Formally Specifying Complex Real-World Systems, Qian Cheng, Ruize Tang, Emilie Ma, et al., ICLR, 2026Formal Disco- Scalable Open-Ended Generation of Formally Verified Programs, Gabriel Poesia, Simon Henniger, Tzu-Han Hsu, et al., arXiv, 2026Trace- Securing Smart Contract Repository Against Access Control Vulnerability, Chong Chen, Jiachi Chen, Lingfeng Bao, et al., IEEE TSE, 2026Scope- Detecting Inconsistencies in Arm CCA's Formally Verified Specification, Changho Choi, Xiang Cheng, Bokdeuk Jeong, Taesoo Kim, ASPLOS, 2026VeriContest- A Competitive-Programming Benchmark for Verifiable Code Generation, Zichen Xie, Mrigank Pawagi, Yuxin Liu, et al., arXiv, 2026- related
IronSpec- Increasing the Reliability of Formal Specifications, Eli Goldweber, Weixin Yu, Seyed Armin Vakil Ghahani, Manos Kapritsos, OSDI, 2024 - unavailable binary
Enhancing LLM-Based Proof Synthesis for Rust Programs via Semantic Chunking and Hierarchical Context Expansion- Springer redirected the PDF endpoint to the chapter page
- the public proceedings preview contains only front matter and the table of contents
- no preview was filed as the paper; the collection directory contains a clearly labeled publisher-abstract record instead
- collection root:
Last edited:
Web Atoms
web atom: group of URL that change together with high probability
- no need to probe every URL, just probe every member of the group when one change
🤖 Agent-added research direction (2026-06-07)
- 🤖 Insight: web atoms are useful for agents because they define evidence invalidation units. If one member changes, linked claims, crawls, generated scripts, UI/API equivalence tests, and receipts may need revalidation.
- 🤖 Why not merely engineering: the paper question is causal validity: can atom graphs predict which web evidence and automation artifacts are stale?
- 🤖 Transfer: dependency graphs, incremental computation, active automata learning, model-based testing, and dynamic web exploration.
- 🤖 Evaluation sketch: build atom graphs from CDP resource traces, crawl diffs, link/resource structure, and deployment metadata; compare atom-based invalidation with fixed recrawl schedules on stale-claim prevention, cost, and repair precision.
- 🤖 Anchors: Web Dependency Analyzer, WebREC, Browsertrix, Fable, dynamic web exploration state-flow graphs.
Last edited:
Web Crawling
- The Prevalence of Single Sign-On on the Web: Towards the Next Generation of Web Content Measurement, Calvin Ardi, Matt Calder, IMC, 2023
- automate SSO login w/ Google/Facebook, etc. to access gated content
- 58% of top 10K website can SSO
- On Landing and Internal Web Pages: The Strange Case of Jekyll and Hyde in Web Performance Measurement, Waqar Aqeel, Balakrishnan Chandrasekaran, Anja Feldmann, Bruce M. Maggs, IMC, 2020
- landing page different from internal page
- method to find representative internal page
- System to Identify and Elide Superfluous JavaScript Code for Faster Webpage Loads, Utkarsh Goel, Moritz Steiner, arXiv, 2020
- passive real user monitoring system (RUM) in CDN proxy
- on median page, 31% JS code superfluous, can rm for 5% speedup
- Browser-based Crawling of News Websites Behind Paywalls, IFLA News Media Section & IIPC Workshop on Archiving News Media, 2025
- Danish & Luxembourgish & Finnish using legal deposit law
- ask site owner to get login credential; legal deposit law enforce company to abide
- ask for IP-based paywall bypass; better than login
- cookie to bypass cache for IP-based paywall bypass
- Heritrix job queue for non-browser crawling
- Browsertrix browser automation
- show preview; designed for non-technical user
- pre-crawl validation of browser “profile” to ensure logged in
- Selenium + Sikuli + weekly manual profile check
- fork to crawl news frequently and dedup
- hash page after removing dynamic element w/ regex 🤣
- maintain shared document of paywall info
- “student helper” to check periodically & submit ticket
- https://github.com/iipc/awesome-web-archiving
- The Internet with Privacy Policies: Measuring The Web, Nikhil Jha, Martino Trevisan, Luca Vassio, Marco Mellia, ToW, 2022
- lose content if not clicked consent banner
🤖 Agent-added crawling direction (2026-06-07): archive-backed agent evidence
- 🤖 Insight: crawler/browser systems can make web-agent claims reproducible under live-web drift by pairing live observations with WACZ/Memento-style archived evidence and explicit freshness/source fields.
- 🤖 Why not merely engineering: the paper question is how much source correctness, temporal precision, and synthetic-content exposure change when agents reason over live-only vs archive-backed evidence.
- 🤖 Transfer: web-archiving formats, temporal IR, browser-based crawling behind consent/login/paywall state, and provenance graphs.
- 🤖 Sketch: crawl 20-50 volatile pages daily with Browsertrix/source-specific extractors; compare live-only, archive-only, and live+archive agents on claim support, time-of-claim accuracy, capture completeness, replay fidelity, and human review time.
- 🤖 Anchors: Browsertrix, WACZ, Memento/RFC 7089, Heritrix, Retrieval Collapse, PB stale/dedupe/news-quality work logs.
🤖 Agent-added crawling direction (2026-06-07): web atoms for invalidation
- 🤖 Insight: recrawl/retest decisions should follow dependency atoms: groups of URLs, scripts, APIs, archives, generated artifacts, and receipts that tend to become stale together.
- 🤖 Why not merely engineering: the research question is whether a causal dependency model predicts stale evidence and broken automation better than fixed crawl intervals or URL-level freshness checks.
- 🤖 Transfer: incremental computation, dynamic web dependency analysis, active automata learning, model-based testing, and crawl repair.
- 🤖 Sketch: learn atom graphs from CDP traces, crawl diffs, resource dependencies, and site maps; invalidate linked receipts/scripts/tests when an atom changes; measure stale-claim prevention, recrawl cost, and repair time.
- 🤖 Anchors:
web_atoms.md, Web Dependency Analyzer, WebREC, Browsertrix, Fable, dynamic web exploration state-flow graphs.
Last edited:
Web User-Facing
- Investigating influencer VPN ads on YouTube, Omer Akgul, Richard Roberts, Moses Namara, Dave Levin, Michelle L. Mazurek, IEEE SP, 2022
- scrape YouTube & analyze video
- Evolving Bots: The New Generation of Comment Bots and their Underlying Scam Campaigns in YouTube, Seung Ho Na, Sumin Cho, Seungwon Shin, IMC, 2023
- scrape YouTube comment & cluster to find user w/ URL in profile
- fine-tune BERT variant to generate embedding for DBSCAN clustering
- filter URL: discard most common domain (twitter) and very rare domain (personal website)
- match URL w/ blocklist to find social scam bot (SSB)
- most are “romance scam” or “game scam”
- SSB strategy: steal top comment, self-engagement
- scrape YouTube comment & cluster to find user w/ URL in profile
- As Advertised? Understanding the Impact of Influencer VPN Ads, Omer Akgul, Richard Roberts, Emma Shroyer, Dave Levin, Michelle L. Mazurek, USENIX Security, 2025
- Reviving Dead Links on the Web with Fable, Jingyuan Zhu, Anish Nyayachavadi, Jiangchen Zhu, Vaspol Ruamviboonsuk, Harsha V. Madhyastha, IMC, 2023
- heuristic to find mapping between dead link and new link after page moved
Search Engine Optimization (SEO)
- ❓ The influence of search engine optimization on Google’s results: A multi-dimensional approach for detecting SEO, Dirk Lewandowski, Sebastian Sünkler, Nurce Yagci, ACM WebSci, 2021
- insight from interview w/ “SEO expert”
- questionable heuristics (e.g., HTTPS, manual website classification)
- dataset: Google Trends, radical right, coronavirus
- most search result likely have SEO
- ⭐ Is Google Getting Worse? A Longitudinal Investigation of SEO Spam in Search Engines, Janek Bevendorff, Matti Wiegmann, Martin Potthast, Benno Stein, Springer ECIR, 2024
- search result on product review & spot affiliate link
- query:
best <category>where<category>is in GS1 Global Product Classification/ Google Product Taxonomy - filter review based on keyword regex, but 80% accuracy in test
- manual classification of top 30 domain: authentic review/ magazine&news/ content farm/ spam/ shop/ social media/ other
- query:
- top SEO content: repetitive, less readable, shallower URL, longer content, more heading, less heading-content overlap
- lots of SEO metric based on HTML
They are also indicators of lower-quality, possibly mass-produced, or even AI-generated content.
- comparison w/ BM25 search engine ChatNoir: much more affiliate link
- search result on product review & spot affiliate link
- Adversarial Search Engine Optimization for Large Language Models, Fredrik Nestaas, Edoardo Debenedetti, Florian Tramèr, arXiv, 2024
- embed instruction/defamation in web content to manipulate RAG LLM search engine (answer engine)
- can imply other content is bad
- test by searching w/
site:for owned domain
- embed instruction/defamation in web content to manipulate RAG LLM search engine (answer engine)
examples:
- AI SEO spam content when searching for “AI SEO” in Google Scholar: AI Revolutionizes Seo: How Chatgpt & Gemini Can Supercharge Your Rankings
- leading SEO company is huge: ahrefs
ideas:
- ranking based on user feedback
- measuring retrieval of Perplexity, ChatGPT, etc. in search mode
🤖 Agent-added generated/synthetic web directions (2026-06-07)
- 🤖 Source-critical agents: search and answer agents should model source ecology, not just rank pages. Live pages, archives, AI-generated pages, answer-engine summaries, consent-gated pages, and logged-in pages carry different evidence status.
- 🤖 Generated web artifacts: generated sites/components should be treated as executable supply-chain claims with provenance, security obligations, tests, and runtime monitors. This is more useful than another AI-text detector.
- 🤖 Why now:
Retrieval Collapsereports synthetic sources can dominate retrieval exposure; LLM-generated web-app studies report exploitable auth, session, validation, XSS, upload, and HTTP-header failures; AI SEO/content spam changes what web-grounded agents see. - 🤖 Evaluation sketch: crawl a volatile topic daily, classify source types, archive evidence, and test whether agent answers shift toward synthetic or stale evidence. For generated artifacts, generate sites, attach obligations, run security checks, and measure review/repair quality.
🤖 See literature_directions.md candidate 4 and candidate 5 for the question-first versions of these ideas.
Web Dependency
- Poster: Web Dependency Analyzer to Identify Resource Dependencies and their Impact on Rendering, Yasin Alhamwy, Paul Mertens, Oliver Hohlfeld, IMC, 2024
- which domain provide which assets, contribute how much to rendered content
- ablation: what happens to rendering when block some domains (or down)
Phishing
- Phishing in the Free Waters: A Study of Phishing Attacks Created using Free Website Building Services, Sayak Saha Roy, Unique Karanjit, Shirin Nilizadeh, IMC, 2023
- description of free website building service
- much pressure on detecting phishing domain ⇒ costly to buy frequently
Spam
- Click Trajectories: End-to-End Analysis of the Spam Value Chain, S&P, 2011
- SybilGuard: defending against sybil attacks via social networks, Haifeng Yu, Michael Kaminsky, Phillip B. Gibbons, Abraham Flaxman, SIGCOMM, 2006
Last edited:
Server
Google Chrome Remote Desktop
set up server through SSH: https://remotedesktop.google.com/headless (need sudo access)
Last edited:
NFS
enable nfs
systemctl enable nfs-server
add directory to export: edit etc/exports
directory_to_export ip_to_allow(rw,insecure)
export all specified directory
sudo exportfs -arv
mount on macOS
sudo mount -t nfs -v source target
automatically mount on macOS
open
/etc/fstabwithsudo vifsadd into the file:
source /System/Volumes/Data/../Data/Volumes/target_name nfs rw,nolockd,resvport,hard,bg,intr,tcp,nfc,rsize=65536,wsize=65536for pre-Catalina, it should be
source /../Volumes/target_name nfs rw,nolockd,resvport,hard,bg,intr,tcp,nfc,rsize=65536,wsize=65536
Last edited:
SSH
kitty ssh
kitty +kitten ssh …
port forwarding
ssh -L 8080:127.0.0.1:8080 username@host
ClashX Socks proxy (-C to compress and save bandwidth)
ssh -C -o "ProxyCommand nc -X 5 -x 127.0.0.1:7890 %h %p" username@host
rsync
general usage-P give a progress bar
rsync -P source destination
copy file from ssh server to client
rsync -P username@host:dir local_dir
copy file from client to ssh server
rsync -P local_dir username@host:dir
mosh
faster bc use UDP, but no port forwarding
official version buggy for TUI app; need to compile <git@github.com:jdrouhard/mosh.git> from scratch on both client and server:
sudo apt install autoconf automake libprotobuf-dev pkg-config # for Debian
brew install autoconf automake protobuf pkg-config # for Mac
git clone git@github.com:jdrouhard/mosh.git && cd mosh
./autogen.sh
./configure
make
make install # May need sudo.
another newer fork may be better, but haven’t tried: <git@github.com:alphallc/mosh.git>
Last edited:
Soft Skill
Last edited:
Art and Business
UCCA talk
fund from UCCA Lab w/ corporate client
give artist full control of space
hint what’s inside at the museum doorway
reuse old art
Last edited:
Management
basis & direction
aim → goal
SMART goal: specific, measurable, achievable, relevant, timely
meeting
- basics: goal, interest-related people
meeting procedure
doubly sand glass
- declare goal
- synchronize information
- brainstorm
- limit time
- no interruption
- conclude the problem
- summarize ideas from brainstorm
- no further brainstorm
- grade ideas for importance based on goal
- pick out most important problem
- repeat previous two step on most important problems
- grade potential solutions on 2-4 standards
meeting follow-up
urge timely report
Last edited:
Paper Presentation
- motivation + contribution
- too much time on motivation—people question the contribution
- too little time on motivation—people question the motivation
- look
- leave enough margin on slides for projector & heads in front of audience
- thing show up in liner direction
- use few colors and things
Last edited:
Storage
Last edited:
GitHub
GitHub linguist settings in .gitattributes (reference):
<directory to exclude from stats>/** linguist-vendored
<directory to exclude from stats and hide from diffs>/** linguist-generated
<directory to forcely include>/** linguist-detectable
Git large file system (Git LFS) settings in .gitattributes:
<directory to be included in Git LFS> filter=lfs diff=lfs merge=lfs -text
GitHub repository size: https://api.github.com/repos/git/git
Last edited:
University of Southern California Living
Library proxy redirect
location.href='https://libproxy.usc.edu/login?url='+location.href
Banking
| plan | regst. | mon. | US wire in | out | intl. in | out | ATM w/draw | Zelle |
|---|---|---|---|---|---|---|---|---|
| USCCU student | $9 | $0 | $5 | $20 | -2/yr, $10 | $40 | Citibank branch, -2non-shared/mon | ✅ |
| BoA student | $0 | $5- | $15 | $30 | $15 | $0 if not USD, $45 | BoA, $2.5 (5) if non-BoA (intl.) | ✅ |
| Chase college | $0 | $12- | $15 | $25 | $15 | $5 if not USD, $40 | Chase, $3 (5) if non-Chase (intl.) | ✅ |
- no international wire transfer: SoFi, Chime
- US-citizen-only: ally
Housing
(from Haodong)
places
- DPS
- downtown
- farther: Santa Monica and Culver City (closer to the beach and Hollywood); Monterey Park and San Gabriel (tons of Chinese food and markets); Koreatown (many Korean food, markets and great hair saloons); Pasadena (a bit far but peaceful and beautiful)
house vs apartment: house old, apartment expensive & small & have maintenance
website: Zillow
careful for: heat, floor noise
JavaScript highlight keyword on page
function highlight(regex, classes) {
let regExp = new RegExp(regex, "gi");
let openTag = `<span class="${classes.join(' ')}">`;
function processNode(node) {
if (node.nodeType === Node.TEXT_NODE) {
let parent = node.parentNode;
if (parent && parent.nodeName !== "SCRIPT" && parent.nodeName !== "STYLE") {
let html = node.nodeValue;
if (regExp.test(html)) {
let newHtml = html.replace(regExp, function(match) {
return `${openTag}${match}</span>`;
});
let span = document.createElement("span");
span.innerHTML = newHtml;
parent.replaceChild(span, node);
}
}
} else {
let childNodes = Array.from(node.childNodes);
childNodes.forEach(child => processNode(child));
}
}
processNode(document.body);
}
highlight(String.raw`\b(?:\$[\d,]+|(?:\d,?)?\d{3})\b`, ["highlight"]);
highlight(String.raw`\b(?:female|girls?|wom[ea]n)`, ["highlight-neg"]);
let style = document.createElement("style");
style.innerHTML = `
.highlight {
background-color: yellow;
}
.highlight-neg {
color: red;
}
`;
document.head.appendChild(style);
Health insurance
PhD student are automatically silently enrolled in USC Aetna Student Health Insurance Plan (SHIP)
- health portal for question/appointment https://www.usc.edu/myshr
- Delta Dental https://www.deltadentalins.com/usc (800-765-6003)
- policy/enrollee number is 10-digit USC ID number
- benefit list https://www1.deltadentalins.com/group-sites/usc/ppo.html
PEMS
(for automatically completing part of the “training”)
Staying safe:
function clickAll() {
const down = document.getElementsByClassName("lesson-nav-link__link")[1];
if (down) {
console.log(down);
down.click();
}
const cont = document.getElementsByClassName("continue-btn")[0];
if (cont) {
console.log(cont);
cont.click();
}
for (const expand of document.getElementsByClassName("blocks-accordion__header")) {
if (expand.ariaExpanded === "false") {
expand.click();
}
}
for (const select of document.getElementsByClassName("blocks-tabs__header-item--after-active")) {
if (select.ariaSelected === "false") {
select.click();
}
}
setTimeout(clickAll, 200);
}
clickAll();
Diversity, Equity and Inclusion for Students:
function clickAll() {
const next = document.getElementById("next");
if (next) {
console.log(next);
next.click();
}
const cont = document.getElementsByClassName("ng-binding")[0];
if (cont) {
console.log(cont);
cont.click();
}
for (const expand of document.getElementsByClassName("accordian-btn")) {
if (expand.ariaExpanded === "false") {
expand.click();
}
}
setTimeout(clickAll, 200);
}
clickAll();
Agent prompt:
Continue until you finish all course. Sometimes you need to click through a bunch of "cards" to be able to click "Next". Never ever fucking click exit or any elements outside the middle scrollable box
Anonymization
student directory obfuscated URL:
uscdirectory.usc.edu/web/directory/student/#first=ic&last=e&email=gh&major=csci
Last edited:
Text Editor
Last edited:
Vim
movement
arrow equivalent
↑
← h j k l →
↓
by word
to start of word
<–b– ○ –w–>
word word word
to end of word
ㅤㅤ<–ge–○ –e–>
word word word
by WORD
same as by word but capitalize the last letter
a WORD contains any consecutive non-whitespace character
search
search character
type a character in replace of w below
move to result
○–fw–>
word word
move to left of result
○–tw–>
word sword
backward
capitalize the letter
search expression
/…+entersearch forward?…+entersearch backward
repeat
nnext matchNlast match
expression
- exact
- regex
end of line
the end character
<–0– ○ –$–>
ㅤㅤlineㅤㅤ
the end non-whitespace character
ㅤㅤ<–^–– ○ ––g_–>
ㅤㅤnot whitespaceㅤㅤ
by chunk
by paragraph
paragraph 1
stuff
<–––– { ––––-+
paragraph 2 ○
more stuff |
<–––– } ––––-+
paragraph 3
by page
half page
- up
^u - down
^d
whole page
- up
^b - down
^f
to some position in this page
- Move to top of screen
H - Move to middle of screen
M - Move to bottom of screen
L - Top current line
zt - Center current line
zz - Bottom current line
zb
to past position
- go back to the previous jump position
`` - go back to the previous jump lien
'' - go to mark
letter:`+letter - go to top of last visual selection
`< - go to bottom of last visual selection
`> - go to top of last yanked
`[ - go to bottom of last yanked
`] - go to last change
g; - go to previous change in change history
g,
change
- delete current character and switch to insert mode
s - delete current line and switch to insert mode
S - delete current word and switch to insert mode
ciw - increase (decrease) line indent
>(<) - automatically indent line
= - change to uppercase/ lowercase
gU(gu) - toggle case
~
count
number + keys is the same as pressing keys for number times
go to line
number + G
or
number + gg
: + number
visual mode
- move the other border of selection instead
o
visual mode navigation
- select whole paragraph
vip - select all inside quotes
vi"(not only quotes, others are similar) - select all inside tags
vit - select all and including quotes
va"(not only quotes, others are similar)
undo and redo
- undo
u - redo
^r - undo a line
U
fold
- toggle all fold
zi - toggle current fold
za
spelling
- spelling suggestions for current word
z= - add spelling of current word to dictionary
zg - remove spelling of current word to dictionary
zw
buffer
- next buffer
:bn, previous buffer:bp - previous buffer
<C-o>
quit
- save all and quit
ZZ
write as root
:w !sudo tee %
regex replace
()[]are escaped by\if used as regex\{-}is*?\<…\>is\b…\b- capture groups are
\1, etc.
capitalize first letter
s/\<./\u&/g
simple camelCase to snake_case
s/\l\zs\u/_\l&/g
\( … \) to $…$
s/\\( \(.\{-}\) \\)/$\1$/g
Last edited:
Visual Studio Code (VSCode)
note: replace variable starting with $ with actual value
running Live Share on server for collaboration
SSH into server with port forwarding, then run Tmux:
ssh -L $FORWARD_PORT:localhost:$FORWARD_PORT $USER@$SERVER tmux new -s $SESSION_NAMEalternatives to
screenwould workrun Code Tunnels in Tmux on server. needed to get headless VSCode running on server
download vscode cli and install on server: Download Visual Studio Code - Mac, Linux, Windows
start code tunnel on server, log in, etc.
code tunnelfollow instruction, get
$URLof tunnel
connect to this code tunnel from headless Chrome in Tmux on server, and start Live Share. needed to get persistent session
download chrome and install on server: Google Chrome Web Browser. to do this w/o sudo on debian, only extract the
.debto somewhere you own and symlink into local bin onPATH, something like:mkdir $LOCAL_BIN/chrome dkpg -x $CHROME_DEB $LOCAL_BIN/chrome cd $LOCAL_BIN ln -s chrome/opt/google/chrome/google-chrome google-chromestart headless Chrome on server:
google-chrome --headless=new --remote-debugging-port=$FORWARD_PORT $URLconnect headless Chrome from local machine with Chrome DevTools remote debugging. open
chrome://inspect/#devicesin local Chromium-based browser, click Configure…, put inlocalhost:$FORWARD_PORT. wait a bit. tab of$URLshould appear on this page, click inspect below it to directly interact with web VSCode UI tabopen up chrome console and overwrite clipboard. needed to see Live Share link later because DevTools remote clipboard is fake:
_writeText = navigator.clipboard.writeText; navigator.clipboard.writeText = console.log;start Live Share from UI. open directory in UI, click Live Share button at the bottom to start it, choose log in.
complete login from remote popup tab by going back to
chrome://inspect/#devices. (wait a bit). find login tab, complete loginget Live Share link. return to UI tab, Live Share should be on, it should say link copied to clipboard (if not, click bottom Live Share button again to copy again). get link in console as printed out
(optional) to manage
Shared Terminals, in the UI, open theLive Sharepanel in the sidebar. needed for participants to use terminaluse the Live Share link yourself and send it to others. you can close your local browser and SSH connection now. the session remains up as long as your Tmux session on the server is up
Enabling discussion for feedback from people trying this out:
Last edited:
Xcode
Shortcuts
⌘ + ⇧ + O- Open Quickly
Format
https://medium.com/@jozott/format-on-save-xcode-swift-8133d049b3ac
brew install --cask swiftformat-for-xcode
launch SwiftFormat for Xcode.app
check Extensions -> Xcode Source Editor -> SwiftFormat
restart Xcode
Last edited:
Unstructured Bug Notes
when running GCC, if as is llvm-as, error is below. solution: align CC w/ as
as: Unknown command line argument '-I'. Try: 'as --help'
as: Did you mean '-h'?
as: Unknown command line argument '--64'. Try: 'as --help'
as: Did you mean '-h'?
as: Too many positional arguments specified!
Can specify at most 1 positional arguments: See: as --help
Last edited:
Unstructured Class Notes
some of these are generated from old docx file using Pandoc
Last edited:
Advanced Analysis of Algorithms
theory overview
NP&P → decision problem on &[u1] (language)
⇒ search problem (harder, but may reduce to decision problem)
⇒ optimization
desicion problem → board game
P space: where is polynomial
- P time P space (equal?)
- PPAD
#P: account #solution to NP problem
- each NP problem has #P problem
- #P-complete P space
linear programming: proved P
learning problem
- binary classification:
- learnable: train on unknown distribution , prediction correction increase
binary search to graph search
binary search (go to middle)
⇒ quick selection (broader notion of middle; randomize):
- input:
- want: -th smallest
- algorithm:
- pick with random
- split by to , , throw away impossible list and shrink
power of randomization: but wrt randomness:
of the time we pick element ranked , can throw away of the list
⇒ distance graph
binary search is graph w/ , each number node has edge w/ next number
- local info, e.g., is closer
generalized undirected graph “binary search” for target from
-
- on shortest path if:
- condition: will give set of vertex on shortest path
- iteration: or give closer to
- theorem: ∃ algorithm to find in question
- want: shrink possible answer set , set of node on shortest path from to
- ⇒ medium: lowest potential function
- update w/ hint :
-
claim:
proof:
interactive learning
A General Framework for Robust Interactive Learning, Ehsan Emamjomeh-Zadeh, David Kempe
given hypercube , search space , find s.t.
- VC dimention
- hyperplane in -dimensional space can split cell
greedy algorithm
- can deal with NP-hard problem
- optimality:
- argument of staying ahead
- exchange argument
- proving optimality
- optimum must exist for finite problem
- compare to imaginary optimum
- focus on simple local consistency that eliminate bad possibility
Huffman Codes
- prefix code: no code is prefix of another,
- ⇒ binary tree w/ leaf, each leaf’s parents not usable
- optimum is trivial when tree is given
- tree w/ same number of leaf of each length are equivalent
- has to be proper: each node is either leaf or parent of 2
- substructure optimality: bottom 2 children must map to 2 least frequency
- induction: merge 2 least frequency, treat it as one letter to find mapping for the rest
minimum spanning tree (MST)
cut: split graph to and
affinity: inverse distance, closeness
Kruskal’s algorithm
traditional Kruskal
- sort ascending
- from no node, add edge from small, w/o cycle
reversed Kruskal
- sort ascending
- from , remove edge from big, w/o disconnecting
Prim’s algorithm
- choose arbitrary node “home town” .
- repeat: find closest node w/ edge form .
- why: cut property: shortest cut edge is in MST
- reverse cut property: longest edge in cycle is not in MST
clustering
given w/ metric , , want s.t.
- maximize shortest inter-cluster edge
- idea: for tree , just need to cut longest edge
- ⇒ algorithm: for graph , cut longest edge in MST for optimal clustering
- proof: denote greedy solution cluster , optimum cluster
- if , ∃ node s.t.
- in MST on path from to , within s.t. cross boundary
- by reverse Kruskal, in MST, longest edge that do not disconnect graph are gone
by greedy algorithm, the th longest edge in MST - optimum solution has shortest inter-cluster edge , same or smaller than greedy solution ⇒ contradiction
approximation algorithm
set cover
given: input ground set , w/
want: s.t. and minimized
idea: minimize average cost
algorithm:
- while , pick , set
not optimal when many large also cover small
claim: greedy is within of optimum, where
doing consistently better than of optimum is NP-hard
greedy cost
- harmonic series
- when th (starting from 0) element in is covered, because at most element is covered in
set function
- salary for group in society
- hypergraph: indicator set function determine if each subset is hyperedge
property:
- grounded:
- monotone:
- submodular
submodular function
- diminishing return: less happier when having more and more chocolate
- discrete derivative:
- how much value can add to
- complementarity:
- submodular submodular
- “or” is fundamentally submodular
problem
input: submodular ,
output: , s.t. ,
oracle model: can get
example: max cover: for mapping choose element from to maximize
greedy algorithm : at time , add that maximize
theorem: monotone & submodular, ,
proof:
alternative definition for submodular function (equivalent):
reachability
submodular:
network influence
input
- dynamic & complex compared to traditional static graph
- network influence maximization: often submodular
independent cascade (IC)
each node has probability to influence
- stochastic network influence; e.g., pandemic
- influence spread
- generally #P-complete
- roughly stochastic “or” process; distribution of reachability model
threshold model
each node has threshold to be influenced by neighbor
- deterministic/ stochastic by , e.g., idea spreading
iterative algorithm
polynomial local search (PLS)
- e.g., simplex algorithm, bubble sort
- polynomial number of viable option at each step
- always improve because know potential function
- will stop because define direct acyclic graph (DAG)
Lloyd’s algorithm (K-means clustering)
input:
want: cluster into
- representation (center) of
- mean of cluster minimize variance of distance
- algorithm:
- randomly initialize
- calculate
- regroup by
- Voronoi diagram: zip code
- exponential time to converge, but polynomial time to get close
divide and conquer in geometric space
1-dimensional space
- nice because: can sort, minimal neighborhood, point = hyperplane
- mean: not statistically robust; median: robust
approximate median
-median
algorithm, use 2-way tree of height :
- uniformly sample point
- find median of every 3 point
- find median of every 3 median on the last level, recursively
proof:
- define probability that median algorithm w/ height yield result
- because only 1 point
- at least 2 point among 3 need to be to get median:
- by induction, if
median in 2-dimensional space
- -centerpoint: for any projection, at approximate median
- theorem: , -centerpoint
- intuition: need point to trap 1 point
- VC dimension theory: need sample to estimate well
- -good sample : half space ,
nearest neighbor
- ball: smallest ball that contain neighbor define “nearest”
- ball shape depend on metric (no necessary round)
- locality: a point is not covered by many ball
- k-NN graph (k-NNG): edge from and if is in
- point location, e.g., cell phone connect to tower
- nearest-pair problem: find nearest pair of point among set of point
- algorithm for 2D:
- divide by median on one axis to , find nearest pair in each half
- take minimum distance for
- find nearest pair within around the boundary () - only need to check a series of -hypercube
- take the minimum, recurs
- Bentley: in d-dimension
- algorithm for 2D:
construct k-NNG: divide and conquer ()
- split into by median from (could also split arbitrary)
- build k-NNG for each half ()
- point location problem: ball too big iff point from other half in ball
- need binary search tree for query
- max overlapping ball
- shrink all ball in w/ point in
- recurs
disk packing
non-overlapping 2D ball set
- problem: given point, find ball containing it
- planar graph: node for each ball, edge for intersection
- Koebe embedding: reverse is true
- e.g., prof Teng saw 100 lake in Minnesota (which has 10000) when driving across
condition: if can dig round lake on the spherical, then charge $1 for each lake on tour though great circle
- maximum expected charge:
- in -dimension
proof:
assume the globe has radius 1
each lake define a belt of width perpendicular to great circle passing through it ⇒ expectation of charge:
lake area cannot exceed globe area:
clearly want equal by convexity
kissing number
max number of non-overlapping ball to touch one ball
- in 1D, in 2D, in 3D
3-dimensional binary search via disk
a great circle divide disk into
can have conformal map s.t. median of all disk center is center of globe
- dilate point by projecting globe to plane via tangent, scaling up on plane, then projecting back
can build binary search tree by successive random split through median
-dimensional convex geometry
Helly’s theorem (projection lemma)
in -dimension, with ∞ convex point set, if convex set , all them intersect, then all ∞ of these set intersect
- in 1D, 3 interval intersect pairwise ⇒ ∃1 point in all 3 interval
- -centerpoint exist
Radon theorem: median in convex geometry definition
in -dimension
point ,
can be divided into 2 set s.t convex hull of and intersect
- i.e. s.t.
proof:
has linear equation ⇒ has non-trivial solution, i.e.,
is both in convex hull of and
- intersection point as median
- can get -median WHP, time via -tree
Lipton-Tarjan separator theorem for planar graph
Alan George nested dissection
- numerical system beat Gaussian elimination
- in Gaussian elimination, removing 1 node connect all its neighbor
- remove separator node to separate graph into 2 (or 3)
- eliminate think separator last, so eliminating each node incur small cost
fast Fourier transform (FFT)
integer multiplication
classic algorithm: —not scalable
- output size
can divide each number into high and low half
can save one smaller multiplication by:
FFT make multiplication , nearly as easy as addition
polynomial multiplication
- number are special case of polynomial
- better than number because continuous
- convolution: is sequence of diagonal sum in
- polynomial can be recovered by any distinct data point
realizable data
recover from by solving
easy to multiple and :
need data point to recover
active learning: can pick nice data point as wished
- unit root in complex space:
divide unit circle evenly ⇒ all in form
⇒ sample for
can save computation by , etc.
divide recursively:
⇒ calculate all in
linear programming (LP)
- maximization standard form: maximize, ≤ constraint, non-negative entry
- e.g., use limited material to make product for profit
- minimization standard form: opposite
- polyhedron
- polytope (bounded)
- vertex: ∃ vector, stay in if added, not in if subtracted
- face
- optimal solution: convex (a face), tight (constraint reach equality)
- feasible solution
- DNE when unbounded/ infeasible
- fundamental theorem of linear programming: optimal solution, if exist, contain vertex
- ⇒ if optimal solution exist, exist optimal solution w/ at most non-zero variable
- complementary slackness: , only a few constraint active
- dual LP
- variable become constraint, each row of constraint become 1 dual variable
- persuade not to make product by offering to buy raw material at higher price
- essentially finding upper bound for value
- finding the force on a ball in force field in a cage when it is stable against corner, then try to find path to origin w/ least work
- involution
- lenient primal form ⇒ tight dual form, vice versa
- weak duality theorem: primal value ≤ dual value
- looking for optimum from opposite direction
- one is unbounded the other is infeasible
- optimal if
- strong duality theorem: if either feasible and bounded, then the other is feasible and bounded and optimal value equal
- hold for LP, not for general convex optimization
- method
- simplex method (George Dantzig): polynomial in practice
- duality (John von Neumann)
- engineering method (polynomial): ellipsoid method, interior point method
network flow
- designed to attack USSR supply chain
- Ford-Fulkerson max flow: send most from source to sink
- simple greedy not optimal: find path w/ max min flow recursively
- optimal: include reverse flow from chosen flow in residual graph
- proof by duality
- min cut: sum of weight of edge that separate source and sink
- max flow ≤ min cut
- for each forward cut, ∃ flow that saturate it
- each backward cut is empty
randomization
- Andy Yao’s theorem: random data + deterministic algorithm (algorithm min) is the same as deterministic data + random algorithm (data min)
- min of max = max of min
- convert worst case analysis to average case analysis
Markov chain
- Markovian matrix : stochastic matrix
- doubly-stochastic matrix: both row & column sum to one
- spectral radius: largest dilation by vector
PageRank
- network centrality
approximation:
: start random and walk round
- significant PageRank problem: want all page w/ PageRank
- approximately find page w/ PageRank
spectral graph theory
- simplest: undirected graph
- spectral graph partitioning/ clustering: heuristics
- reduce search space from w/ Laplacian matrix
Laplacian matrix
- : degree matrix, diagonal, is degree of node
- : adjacency matrix
- additive decomposition: can add edge one at a time and sum the ,
-
- ⇒ is positive semi-definite
- eigenvalue
- Fiedler: graph disconnected
min cut
- convention:
- quality of cut: conductance
- want min conductance → NP-hard
- Cheeger’s inequality:
- algorithm
- find Fiedler vector (eigenvector corresponding to )
- sort entries ascending
-
- only need to check cut between and
- dimensionality reduction
- find Fiedler vector (eigenvector corresponding to )
Last edited:
Advanced Computer Networking
Misc
flow: same source&destination (IP&port) & protocol
- important: most traffic point-to-point
- concrete & fine-grained
NABC for research: (hook), need, approach, benefit, competition
dynamic host configuration protocol (DHCP): automatic IP address assignment
multiprotocol label switching (MPLS): show up on BGP
Some Reflections on Innovation and Invention, George H. Heilmeier
- think about where field is going, not where it is
- involve researcher throughout deployment & business
- technology transfer: focus on what people “care about”, what help people, not mathematical beauty
- overcome existing benefit haver; marketing
- everything need to work, or else fail
- catechism for DARPA funding/ startup: goal, existing solution, improvement & novelty, expected outcome, cost estimate
The design philosophy of the DARPA Internet protocols, David D. Clark
- Internet: multiplexed utilization of existing interconnected networks
- Internet was for military
- anticipate failure
- fate-sharing: endpoint deal with failure. guarantee and easy but inefficient
- protocol do not tell participant what fail
- accountability, host attachment, cost efficiency are lowest priority
- anticipate failure
- to connect existing network, bar is low
- adopt packet switching; gateway: packet switch
- distributed management was lower goal → the BGP mess
- UDP/TCP/IP was split from network control protocol (NCP)—NCP was too specific and bad for latency
- goal to support different application
- when designing, did not anticipate actual challenge
- protocol loose → realization determine what goes
- datagram is the basis of Internet flexibility
- high utilization: statistical multiplexing
- drawback: no guarantee, header overhead, difficult to manage & troubleshoot
On the Naming and Binding of Network Destinations, Jerome H. Saltzer
- type of name
- name: the thing
- address: where
- binding: mapping name to address
- route/path: how to get there
- movable; mnemonic; identity
End-to-end arguments in system design, J. H. Saltzer, D. P. Reed, D. D. Clark
- handling failure in middle do not void need to do so at end—no fundamental effect
- cost of duplication
- low level check help performance, but need not be perfect
- example: checksum, encryption, dedup, FIFO, transaction, RISC
- what end mean depend on application
Tussle in Cyberspace: Defining Tomorrow’s Internet, David D. Clark, John Wroclawski, Karen R. Sollins, Robert Braden
- tussle: conflict of interest among party
- need to allow various outcome for place w/ tussle
- should modularize design to separate tussle
- design for choice
Congestion Avoidance and Control, Van Jacobson, Michael J. Karels, SIGCOMM 1988
- obvious window-based transport protocol implementation cause 100x slowdown
- need to get to connection equilibrium → slow start
- preserve equilibrium → round trip timing consider variance
- goal: keep bottleneck full
- self-clocking: packet spacing follow ACK → follow bottleneck
- avoid retransmission too soon
- resource limit: congestion avoidance w/ additive increase (AI)
- congestion detection: packet loss,
delay - congestion recovery: multiplicative decrease (MD)
- congestion detection: packet loss,
- measure RTT: exponential weighted moving average (EWMA)—ACK time - sent time
- retransmission timeout (RTO)
- TCP fast retransmit: retransmit when 3 duplicate ACK (TCP Reno)
- TCP fast recovery: half
cwndinstead of slow start - selective ACK (SACK): for missing packet
A Binary Feedback Scheme for Congestion Avoidance in Computer Networks, Kadangode K. Ramakrishnan, Raj Jain, SIGCOMM 1988
- explicit congestion notification (ECN) router add congestion bit to packet, returned later in ACK
- DEC bit/congestion indication (CI)
- router: use average queue length over regeneration cycle (turns out not good)
- power: throughput / delay
- efficiency: not retransmit unnecessarily
- (throughput / knee throughput) / (delay / knee delay)
- fair share per flow
- Jain fairness where is allocation (bit rate) by demand per flow
- can cheat by opening many flow
- avoid oscillation & congestion collapse
- performance knee vs cliff, hysteresis
- change slowly: per RTT
- feedback filter & averaging: more consistent
- no choke/ source quench: avoid more work
- math model & simulation for policy
- congestion control challenge: hard to predict, changing, delay in control
BBR: Congestion-Based Congestion Control, Neal Cardwell, Yuchung Cheng, C. Stephen Gunn, Soheil Hassas Yeganeh, Van Jacobson
- better for WAN, cellular, large bandwidth+delay link
- adapt to larger queue routers have now
- avoid timeout & retransmission
- CUBIC struggle to keep many packet in flight because of long feedback loop
- BBR try to run at performance knee not cliff
- model ideal window size: bandwidth-delay product (BDP) = bottleneck bandwidth (BtlBw) × RTprop
- BtlBw = delivered / time taken
- assume RTT = RTprop + queuing delay
- measure bandwidth periodically: window size & packet loss & ACK rate
- pacing: additional to ACK self-clocking
- try-faster (ProbeBW state, 98%): send 5/4 pace to probe bandwidth (multiplicative increase), then send 3/4 to drain queue
- CUBIC keep probing at equilibrium → oscillation
- BBR more aggressive ⇒ dominate bandwidth when sharing
- try-slower (ProbeRTT state): send few packet to clear queue; probe RTprop by taking minimum
- startup state (slow start)
- exit startup when BtlBw stay same for 3 RTT
- drain mode to clear queue
- converge to fair share
BGP Routing Policies in ISP Networks, Matthew Caesar, Jennifer Rexford
- BGP not designed to do business policy
- many hack for business relationship & traffic engineering: Pref, MED, community
- BGP not designed to do real-time load balancing
- manual & unscalable configuration
- trick to enhance security, no systematic solution
- when can avoid BGP: connect to single network, default routing
- BGP multihoming goal: reachability, cost, performance, latency, reliability, load balancing
- interior gateway protocol (IGP, e.g., OSPF) vs external gateway protocol (EGP)
- internal BGP (iBGP): share BGP policy among an AS’s router
- peering: link between router in 2 AS (any relationship)/ exchange traffic w/o money (peer-to-peer)
- no-valley rule (valley-free routing)
- internet exchange point (IXP): physical place where ISP swap traffic
- e.g., AMS-IX (Amsterdam), One Wilshire (LA), LINX (London), DE-IX (Frankfurt)
- network access point (NAP)
- point of presence (POP)
- private network interconnect (PNI): 2 AS connect directly
- may be fast/cheap/secure
- routing information base (RIB): BGP routing table
- BGP UPDATE message: announce/withdraw route
- route = address prefix + next-hop router IP + AS path + policy
- BGP attribute: LocalPref, multi-exit discriminator (MED), community string
- selection: filter → highest LocalPref → shortest AS path → lowest origin ID → lowest MED → lowest IGP ID → lowest ID
- AS path purpose: avoid loop (originally); assume fewer AS hop faster
- AS path prepending (duplicate AS) → traffic engineering
- equal cost multi-path (ECMP): load balancing
- primitive alternative: manually split prefix
How the Great Firewall of China detects and blocks fully encrypted traffic, Wu, Mingshi, Jackson Sippe, Danesh Sivakumar, Jack Burg, Peter Anderson, Xiaokang Wang, Kevin Bock, Amir Houmansadr, Dave Levin, Eric Wustrow
- censorship circumvention traffic type
- steganograpic: look like allowed → mimicking: flawed
- polymorphic: not look like forbidden → tunneling: need to align fingerprint w/ popular implementation
- GFW active probing: send carefully-crafted packet to server & see if it let me use as proxy → block residually for 180s. solved
- fully encrypted traffic look like random
- research method: send random packet to detect censorship
- GFW passive detection
- allow if average #set bit in each byte (popcount) is at least 0.6 (30% of 8) from 4: random enough
- allow if enough printable ASCII (
[0x20,0x7e]): in first 6 byte of packet, or > 50%, or > 20 - allow if match fingerprint of TLS/HTTP
- GFW blocking characteristics
- limit #residual block: more blocked connection → shorter blocking
- only block client immediately, ignore server
- only examine first packet in TCP connection
- only check packet to specific PI range (popular VPS provider AS, but not CDN)
- only check packet w/ probability ~26%. know because #successful successive sending fit geometric distribution. → reduce false positive
- 0.6% false positive rate from empirical real traffic
- circumvention:
- trivial: prepend exempt start byte
- sophisticated and extensible: pad popcount & shuffle
Routing Stability in Congested Networks: Experimentation and Analysis, Aman Shaikh, Anujan Varma, Lampros Kalampoukas, Rohit Dube
- simulate & Markov model OSPF & BGP up-to-down (U2D) & down-to-up (D2U) timing when overload
- OSPF: only overload factor matter, not packet size
- BGP: helped&screwed by TCP reliability (slower U2D & D2U)
- routing can fail because, in IP, they go through same link as data
- queuing theory & Markov chain
- both detect failure by periodically sending hello (OSPF)/ keepalive (BGP)
Why Is It Taking So Long to Secure Internet Routing?, Sharon Goldberg
- BGP is easy to attack
- prefix hijack: bogus BGP announcement; subprefix hijack: announce more specific prefix
- route leak: announce route to too many
- blackhole: route to nowhere
- interception: route through eavesdropper
- defense
- prefix filtering
- problem: no incentive P2P or P2C or Tier-1
- Resource Public Key Infrastructure (RPKI): sign prefix ownership
- sign route origin authorization (ROA); put in regional internet registry (RIR)
- prevent hijack → incentive, but not leak
- PKI can be attacked; failing check break routing
- Border Gateway Protocol Security (BGPsec): sign BGP announcement
- need online crypto → need new router
- little useful unless all adopt
- prefix filtering
In Search of the Elusive Ground Truth: The Internet’s AS-level Connectivity Structure, Ricardo Oliveira, Dan Pei, Walter Willinger, Beichuan Zhang, Lixia Zhang
- AS topology graph: node = AS, edge = BGP session
- essential for understanding connectivity/routing for, e.g., simulation
- reveal business dispute, policy/sanction (de-peering)
- business relationship: customer-provider (C2P), peer-to-peer (P2P), sibling (same organization)
- invisible link: never show up
- P2P link never show up unless either peer has vantage point
- Internet flattening: eyeball ISP & hypergiant & content provider peer everywhere via IXP
- hidden link: show up gradually
- backup link only show up when primary fail (~100 day)
- C2P link show up eventually in routing table
- hard to see on lower hierarchy; good measurement on Tier-1 after a while
- measure routing ground truth
- BGP table & BGP update from RouteViews, RIPE RIS → reliable
- topology from R&E network (research & education)
- private router config & syslog from Tier-1
- traceroute problematic: map IP to AS
- AS topology is never complete
Trinocular: Understanding Internet Reliability Through Adaptive Probing, Lin Quan, John Heidemann, Yuri Pradkin
- detect Internet outage: reachability to /24 block
- parsimonious: adaptive probing by Bayesian inference
- minimize unsolicited traffic (background radiation) to < 1% by sending only when necessary
- use block history to bootstrap
- belief: increase a lot when probe success, decrease a bit when fail
- go outside threshold → conclude
- availability (priori of #IP that always replied):
- need to probe more to be confident if low availability
- send at regular interval (11min) for freshness
- predictable: probability for correct conclusion for outage is proportional outage duration when shorter than interval
- internet control message protocol (ICMP) echo request (ping)
- positive reply
- error reply: unreachable
- no reply: firewall, routing/transmission failure (outage), IP not used any more, computer sleep
- probe whole block to distinguish outage
- combine multiple vantage point (VP) → avoid interference from failure near VP
- parsimonious: adaptive probing by Bayesian inference
- internet outage
- cause: cable cut (shark/backhoe), routing/DDoS attack, configuration error, power outage
How the Internet reacted to Covid-19 – A perspective from Facebook’s Edge Network, Timm Böttger, Ghida Ibrahim, Ben Vallis
- when lockdown hit, Internet usage grew a lot but did well
- broadband traffic increased much more than mobile
- massive effort to get capacity, i.e., build more broadband
- bad session rate: indicate congestion
- India more affected: less infrastructure, more population
- traffic overflow: go through transit provider instead of peer (PNI, IXP)
Analysis and Simulation of a Fair Queueing Algorithm, Alan Demers, Srinivasan Keshavt, Scott Shenker
- queueing algorithm do not control congestion, but fairness
- allocating bandwidth & promptness & buffer space separately
- need to work w/ different source flow control & routing
- difficulty: distributed, different RTT, per-flow state
- first-come-first-serve (FCFS): source determine bandwidth
- why not: cannot assume everyone cooperate
- round-robin (Nagle): fair, but not efficient
- source over-sending cause long queue for them
- ignore packet size
- prerequisite for fair queueing
- protection against ill-behaved source
- continuous wrt packet arrival time, on average
- fair queueing (FQ): max-min fairness
- per source-destination pair (conversation)
- emulate bit-by-bit round-robin (surely fair)
- bit-by-bit impossible: packet size differ
- bidding: lower delay for link using less bandwidth
- preempt: stop sending current packet to send newly arrived short packet
Controlling Queue Delay, Kathleen Nichols, Van Jacobson
- problem: competition among user of network; router want high bandwidth but user want low delay
- bufferbloat: large standing queue → high delay
- e.g., in router before bottleneck, when sending rate match bottleneck rate, may have a standing queue
- cause: lots of cheap memory, sustained & large traffic
- active queue management (AQM) in router
- random early detection (RED)
- impossibly hard to configure
- low utilization when high delay
- cannot adapt different bit rate
- CoDel: new AQM to succeed RED
- easy to deploy
- track minimum queue size over 1 RTT
- to see if queue drain (queue size < maximum transmission unit (MTU))
- MTU: determined by hardware
- RTT: just use maximum RTT on Earth (300ms)
- packet-sojourn time: how long packet stay
- drop packet/ set ECN early to slow sender down
- good queue: at least 1 packet sojourn time on target in 1 RTT
Congestion Control for High Bandwidth-Delay Product Networks, Dina Katabi, Mark Handley, Charlie Rohrsy
- design transport protocol & router from scratch
- explicit feedback: router tell transport layer what to do
- router give positive/negative feedback () when sender want to send more than router can handle
- receiver copy congestion header and send to sender
- necessary: future link will have high BDP
- separate efficiency controller (EC) & fairness controller (FC)
- do not want per-flow state in router
- packet tell router sender’s
cwnd& RTT - , etc.
- packet tell router sender’s
- add EC and FC result together for feedback
- do not want per-flow state in router
- FC: AIMD for fairness
- shuffle to avoid stuck in unfair steady state
- very good performance in simulation
- few drop
- high throughput, fast convergence
- TCP probe slowly, expensive drop
- low delay
- cannot deploy: firewall, modify router & kernel
- use case: (between) data center, satellite, CDN/WAN
- doable in software-defined network (SDN)
Directed Diffusion: A Scalable and Robust Communication Paradigm for Sensor Networks, Chalermek Intanagonwiwat, Ramesh Govindan, Deborah Estrin
- wireless/mobile network tricky
- device move
- bit rate & bandwidth change
- less capacity
- difficult security, jamming
- different MAC protocol
- power constraint
- sensor network: cheap & numerous—how to communicate
- protocol for sensor network
- peer-to-peer: no IP address, use attribute/ named data
- where to send: interest, gradient → flood/multicast
- respond w/ data if we have
- reinforcement: become faster by sending via low-delay path
- negative reinforcement: shut down slow path if have multiple path
- process in the network to reduce traffic
- constrain flooding (expensive) by location
- reinforce single path
- duplicate suppression respond w/ cache
- → save energy (battery)
- do better than omniscient multicast (idealized)
- lose advantage if listening is more expensive than sending (802.11 radio vs TDMA-MAC)
- need scheduled listen MAC, e.g., S-MAC
- compared to in-network processing in Internet
- different from BGP: smaller scale, more dynamic, on-demand (not ahead of time)
- firewall
- 5G edge computing
- not much, bc not collaborative
- naming in sensor net: attribute-based, key-value pair
- not IP bc dynamic—do not know who to talk to
- application level info (location, sensor type) in network to optimize
- not end-to-end bc trust participant, care only about data
An In-depth Study of LTE: Effect of Network Protocol and Application Behavior on Performance, Junxian Huang, Feng Qian, Yihua Guo, Yuanyuan Zhou, Subhabrata Sen, Qiang Xu, Z. Morley Mao, Oliver Spatscheck
- inefficient 4G application
- video streaming: periodic short request burst, lose throughput
- battery inefficient: turn off and on radio
- video streaming: periodic short request burst, lose throughput
- protocol inefficiency
- high BDP: TCP receive window too small
- low bandwidth utilization
- HTTP keep TCP connection alive: waste battery
- need to wake up radio when closing connection
- high BDP: TCP receive window too small
- LTE different from wired: radio sleep, battery
- 400ms delay when radio wake up
- performance enhancing proxy (PEP): compression, caching, split TCP connection into 2
- long lingering flow: last payload byte to flow end similar to TCP flow duration
- many longer than LTE tail time (radio sleep timeout)
- main latency source: wired part of network
- cause: big queue (buffer bloat)
- passive bandwidth estimation in middle of network
A Variegated Look at 5G in the Wild: Performance, Power, and QoE Implications, Arvind Narayanan, Xumiao Zhang, Ruiyang Zhu, Ahmad Hassan, Shuowei Jin, Xiao Zhu, Xiaoxuan Zhang, Denis Rybkin, Zhengxuan Yang, Z. Morley Mao, Feng Qian, Zhi-Li Zhang
- 5G vs 4G
- millimeter wave (mmWave) frequency: many bandwidth, high throughput
- shorter range, more interference
- new radio transition state
- edge computing
- millimeter wave (mmWave) frequency: many bandwidth, high throughput
- deployment: stand alone (SA) vs non-stand alone (NSA)
- use 4G signaling & control plane vs use 5G
- challenges: interference from Internet measurement, difference in device
- complex & proprietary infrastructure
- latency: linear to device-server distance
- mmWave slightly better than low-band & 4G
- NSA worse than SA
- throughput: drop by distance if single connection bc CUBIC
- stay fast if multiple connection
- NSA worse than SA
- uplink much slower than downlink (2x or 10x)
- handoff: switch radio while driving
- vertical vs horizontal: different technology vs same
- many handoff, many vertical
- idle transition: latency spike when radio sleep
- mmWave high energy cost
- quality of experience (QoE)
- video streaming: more stall & less throughput on 5G
- web browsing: lower latency on 5G, but cost more energy
- not worth it for battery if not need higher speed
On the Self-Similar Nature of Ethernet Traffic, Will E. Leland, Murad S. Taqqu, Walter Willinger, Daniel V. Wilson
- network traffic self-similar (fractal) on different time scale
- bursty, packet dependent on each other
- time scale matter
- very different mean & variance on different time scale
- not smooth
- Poisson process model not fit, not bursty at large time scale
- memoryless → smooth when large scale
- better model
- only parameter: Hurst parameter
- measure self-similarity: evaluate R/S over different time scale
- R/S: range/standard deviation; is slope
- spectral density power law near origin
- generate from fractional Gaussian noise
- who care: understand real-world performance when designing network
- how big buffer: BDP
- macroscopic traffic analysis
- significance: people go at the same time, burst sometimes long
- need over-provision, will fail
- long-range dependence: current value matter long into future
- self-similar: variance decrease very slowly as time scale grow
- auto-correlation: how much I look like myself
- convolution of and
- large auto-correlation → self-similar
- show up on time-variance, range/std, periodigram
Self-Similarity in World Wide Web Traffic: Evidence and Possible Causes, Mark E. Crovella, Azer Bestavros
- why self-similar: heavy-tailed Pareto distribution
- superposition: many sending in this distribution
- web traffic heavy-tailed
- linear in log-log CCDF plot
- infinite variance when , infinite mean when
- transfer time
- distribution of file size
- few very large file
- superposition: many sending in this distribution
- web active/inactive regime (on/off): two separate power law
- disagreed and modeled w/ Poisson
Internet Inter-Domain Traffic, Craig Labovitz, Scott Iekel-Johnson, Danny McPherson, Jon Oberheide, Farnam Jahanian
- flattened Internet: more CDN, hypergiant, eyeball ISP, P2P reduce
- data centralization: cloud, big player dominate
- lots of content
- Google shifted to own data center & bought YouTube
- Comcast merged w/ other & started CDN
- P2P: direct downloading easier & got better at hiding bc legal
- data centralization: cloud, big player dominate
- consolidation to few AS
- big get bigger; migration to cloud
- data: security appliance in ISP
- many big ISP
- cannot share proprietary
MapReduce: Simplified Data Processing on Large Clusters, Jeffrey Dean, Sanjay Ghemawat
- fault tolerance: task as intermediate abstraction
- re-execute failed task; redundant task; straggler elimination
- Hadoop, Dryad, Spark, Zookeeper, Hive, Pig, HBase
The Tail at Scale, JeffRey Dean, Luiz André Barroso
- tail matter: worst get remembered; parallel computing
- countermeasure: micro-partitioning, partial result
- hedged queries: send task to multiple server, cancel slow
Rethinking Enterprise Network Control, Mart ́ın Casado, Michael J. Freedman, Justin Pettit, Jianying Luo, Natasha Gude, Nick McKeown, Scott Shenker
- Ethane: SDN to control switch centrally for enterprise
- evaluate flow → accept/drop/waypoint
- cheaper than layer 2 for security change
- goal: survivability, multiple link layer, multiple app, accountability, manageability
- support enterprise security, authentication, law enforcement, logging
- smart controller, dumb switch
- switch send first flow to controller, get policy
- centralize: easy to manage, but latency & single point of failure
- switch watch for per-package cost; controller per-flow
- flow security language (FSL): define name-based flow policy
- dynamic group
- compile to C++
- commercialized as OpenFlow & Nicira
P4: Programming Protocol-Independent Packet Processors, Pat Bosshart, Dan Daly, Glen Gibb, Martin Izzard, Nick McKeown, Jennifer Rexford, Cole Schlesinger, Dan Talayco, Amin Vahdat, George Varghese, David Walker
- protocol-independent language (P4): generalize forwarding plane policy
- OpenFlow getting more and more header field
- run on switch w/ ASIC/NPU at line rate
- header, parser, table, action
VL2: A Scalable and Flexible Data Center Network, Albert Greenberg, Srikanth Kandula, David A. Maltz, James R. Hamilton, Changhoon Kim, Parveen Patel, Navendu Jain, Parantap Lahiri, Sudipta Sengupta
- build data center for cloud provider
- goal for future
- agile: run any app on any server ⇒ high utilization
- performance isolation: no CPU/network interference between app (virtualization, VLAN); QoS ⇒ security, keep abstraction in service level agreement (SLA)
- flat addressing (LAN, layer-2 semantics): address isolation, migrate w/o changing IP, cheap switch w/ small table
- layer-2.5 shim
- hardware: cheap, commodity
- topology: valiant load balancing (VLB), equal cost multi-path (ECMP),
- high utilization in core network even when router fail
- Clos: full bisection bandwidth
- network switch: top-of-rack (ToR), aggregating switch (join different rack), core switch
- power, cooling
- provide abstraction: infinite compute capacity, isolated resource, flat network (LAN)
- traffic analysis
- most flow small; most byte in big flow
- somewhat random by design
Engineering Egress with Edge Fabric Steering Oceans of Content to the World, Brandon Schlinker, Hyojeong Kim, Timothy Cui, Ethan Katz-Bassett, Harsha V. Madhyastha, Italo Cunha, James Quinn, Saif Hasan, Petr Lapukhov, Hongyi Zeng
- BGP not ideal for large content provider: not capacity-aware/performance-aware
- Facebook want high QoE, low cost
- Edge Fabric solution: forecast how much traffic will go through each link
- look at latency
- run in each point of presence (PoP)
- components: aggregation switch (ASW), peer router (PR, core router)
- capacity-aware
- goal: shift traffic from overloaded peering
- algorithm: compute alternative path for overloaded
- output: override BGP route w/ LocalPref&MED to detour traffic
- performance-aware
- goal: shift traffic to low-latency path
- input: traffic w/ differentiated service code point (DSCP) to indicate QoS expectation
- algorithm: reroute if alternative path has lower latency
- split some traffic to A/B test
- use tunneling to reroute
- central load balancer: use DNS to map user to PoP
B4: Experience with a Globally-Deployed Software Defined WAN, Sushant Jain, Alok Kumar, Subhasree Mandal, Joon Ong, Leon Poutievski, Arjun Singh, Subbaiah Venkata, Jim Wanderer, Junlan Zhou, Min Zhu, Jonathan Zolla, Urs Hölzle, Stephen Stuart, Amin Vahdat
- goal: avoid over-provisioning WAN (30%), high utilization (90%)
- avoid loss/congestion; handle link failure
- high priority user traffic
- low cost: commodity switch & router
- support traffic growth
- solution: SDN (OpenFlow)
- traffic engineering (TE)
- replicated centralized controller: efficient, optimal
- per datacenter OpenFlow controller (OFC) & redundant routing (Quagga)
- fault tolerance
- app control
- why Google can do
- control everything: traffic generation, access router, backbone
- classify source: low priority for latency-insensitive large data transfer
- assumption:
- elastic bandwidth (different priority), app control
- few dozen data center: limited scale
- custom per-site software
- customer OFC: replicated, synchronized w/ Paxos
- custom routing w/ Quagga & BGP/ISIS
- group app into flow group (FG): better QoS
- TE map FG to tunnel group (TG): reduce #group for scalability
- max-min priority of FG into TG
- rate limit incoming traffic to router bandwidth: avoid drop in backbone; predictable traffic
- TE fail open: still can send traffic
- multiple path for each tunnel for link fault tolerance
- no drop for high priority traffic; drop low priority
- failure if many thing go wrong
Networking Named Content, Van Jacobson, Diana K. Smetters, James D. Thornton, Michael Plass, Nick Briggs, Rebecca Braynard
- content-centric network (CCN): content as primitive, not identity, host, etc.
- protocol: request w/ interest, respond w/ data
- support multicast by default
- hierarchical, variable-length name instead of IP address
- content-based security: SHA256 checksum on content, not host
- pertinence: answer to what question; in the name
- provenance: who say it; by public key signature
- efficiency: get from nearest router cache
- larger header for interest → 20% overhead; higher performance w/ more packet in flight
- fast handover
- reliability: multiple source; data provenance/origination/integrity from security
- receiver responsible to clarify
- stability: interest/data ACK-clock
- new waist in network stack above IP
- CCN naming: no location, say what content is
- hash, signed, maybe human-readable (meaningful)
- is routing protocol: send interest around; interest data 1:1
- window of interest; pipelining
- DDoS protection: caching; aggregation; block those w/ random interest
- policy & filtering (content firewall): signature-based
- low throughput & high latency bc large header ⇒ need pipelining
- automatic failover: fault tolerant
Fundamental Design Issues for the Future Internet, Scott Shenker
- revisit Internet architecture in 1995
- can we do QoS? yes
- app do not have real QoS
- QoS give guarantee of performance
- how to do QoS
- goal of Internet is user satisfaction: utility & efficacy
- utility: often step function: linear, fixed-rate, elastic, semi-adaptive
- best effort: maybe do not want guarantee; avoid high cost
- inelastic traffic, all or nothing: maybe QoS
- admission control: block some flow when congestion
- make sense if utility convex near origin
- admission control: block some flow when congestion
- solution choice; service model: what app ask from network
- overprovisioning: way enough bandwidth so no worry, but waste money
- integrated service (IntServ), QoS: reserve bandwidth, but expensive router
- differentiated service: prioritize
- user adapt
- parallel network (e.g., cellular + WiFi): fault tolerance, optimize each, but double cost
- service model may have QoE, but may be abused, depended; app need to know what it want
- network neutrality: should ISP have special deal w/ content provider to prioritize
- “zero rating”: content provider pay for user data
Click Trajectories: End-to-End Analysis of the Spam Value Chain, Kirill Levchenko, Andreas Pitsillidis, Neha Chachra, Brandon Enright, Mark Felegyhazi, Chris Grier, Tristan Halvorson, Chris Kanich, Christian Kreibich, He Liu, Damon McCoy, Nicholas Weaver, Vern Paxson, Geoffrey M. Voelker, Stefan Savage
- characterize spam
- domain: sell similar product
- ordering product, where from, how paid
- motivation: spam bad, shady product, high cost anti-spam
- bottleneck in spam
- observation: global, big business, speciality
- spam franchise:
- send many “attractive” message, (botnet)
- bulletproof hosting service
- payment
- deliver product
- data collection: parse spam, crawl website, cluster & tag content, buy product
- most spamming service use only a few DNS server/registrar/AS, but hard to take down all
- 95% service use a few bank: good target bc bank slow
Investigating Large Scale HTTPS Interception in Kazakhstan, Ram Sundara Raman, Leonid Evdokimov, Eric Wurstrow, J. Alex Halderman, Roya Ensafi
- nation-state man-in-the-middle intercept encrypted HTTPS
- can intercept TLS a.l.a. let people use your key by controlling certificate authority (CA)
- measure: visit sensitive website from VP within Kazakhstan
- probe from outside: visit forbidden website at HTTPS server in Kazakhstan; work bc Kazakhstan not care direction
- interception trigger: targeted domain in TLS Server Name Indication (SNI) header
- countermeasure: TLS 1.3 encrypt SNI, server or browser reject government certificate
The Menlo Report: Ethical Principles Guiding Information and Communication Technology Research, David Dittrich, Erin Kenneally
- information and communications technology research (ICTR)
- Belmont principles: respect for person (informed consent), beneficence (min harm max benefit), justice (unbiased subject)
- respect law & public interest
- current institutional review board (IRB) should apply to ICTR
- respect for person hard bc networking is indirect & large-scale
- beneficence hard bc hard to predict outcome
- justice hard bc lack control of demography
Tor: The Second-Generation Onion Router, Roger Dingledine, Nick Mathewson, Paul Syverson
- deployable low-latency anonymous web browsing
- circuit: amortize setup cost, reduce latency, avoid congestion
- easy to use
- relatively simple
- want anonymity among crowd
- TCP-only bc mainly for web browsing
- non-goal: peer-to-peer, end-to-end attack security, conceal user identity (steganographic)
- anonymity: receiver & proxy do not know who sender is
- proxy only know previous & next hop
- perfect forward secrecy: nested encryption so that each hop can only decode enough for next hop
- backward anonymity: remap IP
- threat: proxy compromised, traffic visible, timing (not addressed)
- onion proxy (OP): first hop, know sender & see content
- onion router (OR): middle hop
- exit node (EN): last hop, know sender & see content
- circuit: path through OR
- incremental circuit building: establish encrypted tunnel to next hop from public key encryption, one by one
- application-level anonymity: need separate proxy (e.g., Privoxy)
- rendezvous point of location-hidden service
- directory of server for Tor path to server
Last edited:
Advanced Natural Language Processing
natural language hard because ambiguity
breakdown of language: phonetics (sound) → phonology (meaningfully distinct sound)/ orthography (character)
- → morphology → lexeme (word)
- → syntax (grammar) → semantics (meaning) → pragmatics (context) → discourse (relation between sentences)
current model suck when samples are long and few
overwhelmingly obey Zipf’s law
Introduction to Natural Language Processing, Jacob Eisenstein, The MIT Press, 2018
Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition, with Language Models, Daniel Jurafsky, James H. Martin, 2025
GLU Variants Improve Transformer, Noam Shazeer, arXiv, 2020
- SwiGLU
GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints, Joshua Ainslie, James Lee-Thorp, Michiel de Jong, Yury Zemlyanskiy, Federico Lebrón, Sumit Sanghai, EMNLP, 2023
paper to present
- Learning to Rewrite: Generalized LLM-Generated Text Detection, Wei Hao, Ran Li, Weiliang Zhao, Junfeng Yang, Chengzhi Mao, ACL, 2025
- MultiSocial: Multilingual Benchmark of Machine-Generated Text Detection of Social-Media Texts, Dominik Macko, Jakub Kopál, Robert Moro, Ivan Srba, ACL, 2025
- MIND: A Multi-agent Framework for Zero-shot Harmful Meme Detection, Ziyan Liu, Chunxiao Fan, Haoran Lou, Yuexin Wu, Kaiwei Deng, ACL, 2025
- UTBoost: Rigorous Evaluation of Coding Agents on SWE-Bench, Boxi Yu, Yuxuan Zhu, Pinjia He, Daniel Kang, ACL, 2025
- CompileAgent: Automated Real-World Repo-Level Compilation with Tool-Integrated LLM-based Agent System, Li Hu, Guoqiang Chen, Xiuwei Shang, Shaoyin Cheng, Benlong Wu, LiGangyang LiGangyang, Xu Zhu, Weiming Zhang, Nenghai Yu, ACL, 2025
replication project
- Zero-Shot Detection of LLM-Generated Text using Token Cohesiveness, Shixuan Ma, Quan Wang, EMNLP, 2024
paper to question
- Self-Instructed Derived Prompt Generation Meets In-Context Learning: Unlocking New Potential of Black-Box LLMs, Zhuo Li, Yuhao Du, Jinpeng Hu, Xiang Wan, Anningzhe Gao, ACL, 2025
- impact on context window?
- what would long prompt do? like a revise request?
- what about multi-turn?
paper presentations
- What Happened in LLMs Layers when Trained for Fast vs. Slow Thinking: A Gradient Perspective
- presented by Jinyi
- fast&slow thinking: system 1&2, subconscious&conscious
- for LLM: no chain-of-thought (CoT) vs CoT; different level of detail
- probing & layer importance
- back propagation on different level of detail
- nuclear SVD of Q K V O of each layer’s gradient
- more detailed CoT ⇒ smoother gradient
- compare mean absolute difference (MAD) of each layer
- compare relative difference (RD)
- instruction tuning does not enable better nonsense detection
- byte latent transformer (BLT): patches scale better than tokens
- presented by Saba
- LLM training is end-to-end except for tokenization
- patching: dynamic group w/o fixed vocab
- entropy patching: start new patch when next byte hard to predict
- small byte-level autoregressive model to produce entropy
- small byte-level encoder&decoder surrounding 1 large latent transformer in middle
- use byte encoding plus hashed n-gram
- not learned!
- higher patch size ⇒ lower FLOP per accuracy gain
- minor accuracy degradation
- HumT DumT: Measuring and controlling human-like language in LLMs
- presented by Sadra
- human-like tone (HumT): ~anthropomorphization; users usually prefer against (bc wordy, not to-the-point)
- like flirty; overly descriptive?
- DPO + HumT (DUMT): RL to lower HumT
- little performance degradation
- Self-Instructed Derived Prompt Generation Meets In-Context Learning: Unlocking New Potential of Black-Box LLMs
- presented by Feiyu
- train rewriter (small model) to rewrite query, then feed new query to queried model (large), finally feed everything to query model again
- use judge model for reward in training
- higher token count & slower, in exchange for claimed performance
- LLMs know their vulnerabilities: Uncover Safety Gaps through Natural Distribution Shifts
- presented by Narges
- train attacker LLM to make victim LLM answer harmful question
- TreeRL: LLM Reinforcement Learning with On-Policy Tree Search
- presented by Saeed
- entropy tree (EPTree): RL w/ tree of action
- branch out from high-entropy (uncertain) token
- only fork once in the paper
- slightly higher #answers generated & pass rate per #tokens generated
- but unclear if better when allowing more #tokens
- forking appear relative location near uniform distro
- Mega: Moving Average Equipped Gated Attention, Xuezhe Ma, Chunting Zhou, Xiang Kong, Junxian He, Liangke Gui, Graham Neubig, Jonathan May, Luke Zettlemoyer, ICLR, 2023
- guest lecture by Xuezhe
- why: longer context practically mean smarter model
- challenge: transformer is quadratic compute&space in context length
- communication challenge; huge KV cache
- attention fail in large context
- chunk-wise attention: only attend to chunk instead of global
- damped exponential moving average (EMA): EMA w/ relaxed coupled weight
- learned parameter
- parallelize by precomputing flattened weight & FFT
- theoretically unbounded context
- practically, w/ chunking, perform worse than full attention
- apply on layer input for Q K but not V
- single-head gated attention: add reset gate to attention output
- gated attention: multiple attention output w/ output of another transform from input
- can reduce #heads e.g. from 32 to 4 ⇒ computational efficiency
- single Mega model perform well on various long-context task
- Megalodon: Efficient LLM Pretraining and Inference with Unlimited Context Length, Xuezhe Ma, Xiaomeng Yang, Wenhan Xiong, Beidi Chen, Lili Yu, Hao Zhang, Jonathan May, Luke Zettlemoyer, Omer Levy, Chunting Zhou, NeurIPS 2024
- better Mega
- complex EMA:
- reason: diagonal matrix much more expressive in complex space
- time-step normalization: auto-regressive group normalization
- cumulative mean&variance; no reset per document in training
- reduce communication bc only need last output instead of whole KV cache
- Gecko: ongoing improvements to Megalodon
- running mean&variance via constant decay
- sliding chunk attention: less wasted compute than flash attention
- adaptive working memory (online softmax)
- TokAlign: Efficient Vocabulary Adaptation via Token Alignment
- presented by Daniel
- problem: BPE & friends bias towards English, etc.
- replace vocabulary of LLM w/o full retraining
- injective map source tokenizer to target tokenizer via GloVe & alignment matrix
- evaluate by BLEU-1 score of embedding, then recover corpus & eval w/ BERTScore
- replace vocabulary, freeze LLM body, retrain embedding & LM head, then full fine-tune
- Turning Trash into Treasure: Accelerating Inference of Large Language Models with Token Recycling
- presented by Ardy
- token recycling for efficient decoding
- speculative decoding: small model speculate multiple token, then large model verify in parallel
- trash: non-verified speculative token, discarded
- prebuild static possible token tree (unclear how to generalize)
- concatenate all node in tree as LLM input, discard tokens in group
- double speed than autoregressive decoding in benchmark
- TokenFormer: Rethinking Transformer Scaling with Tokenized Model Parameters
- presented by Kiarash
- wasteful to not reuse smaller model when training larger
- pattention: cross attention w/ learnable parameter & modified softmax
- can concatenate parameter matrix to increase
- equivalent to 2-layer MLP w/ modified softmax as activation
- replace Q K V O (FFN) layer all w/ pattention
- much less computation power to train larger model w/ same performance
- better benchmark score w/ same parameter count
- Guest presentation: Path finding: how the search space for creative tasks is navigated
- presented by Tenghao
- for writing /info gathering/ brainstorming task, search&reward space large
- heuristic: constrained beam search: prefer more emotional intensive token
- reward design: emotional intensive + perplexity
- Large Language Models Are Biased Because They Are Large Language Models
- presented by Faith
- model learn from biased data
- RLHF does not fundamentally make LLM understand ethics
- need linguists/philosophers & collab btw researcher/corporation
- Toward Automatic Discovery of a Canine Phonetic Alphabet
- presented by Ruth-Ann
- clean&split&transcribe YouTube dog bark into cognitive vocal unit
- mutual filtering based on minimal pairs
- merge w/ JS divergence
- vision model to describe scene&movement & map to 10 category
- better scenario classifier thru phonetic unit than MFCC & audio model
- Improving Factuality with Explicit Working Memory
- presented by Tianwen
- working memory for RAG: KV cache for retrieved doc
- append memory after context in parallel w/ queue; weighted average of hidden vector ⇒ better retrieval
- recall vs precision tradeoff
- Reinforced IR: A Self-Boosting Framework For Domain-Adapted Information Retrieval
- presented by Nikunj
- retriever + generator reinforce in a loop
- SHuBERT: Self-Supervised Sign Language Representation Learning via Multi-Stream Cluster Prediction
- presented by Anzhe
- K-means → language model
- accuracy is SoTA but trash
- SpaRE: Enhancing Spatial Reasoning in Vision-Language Models with Synthetic Data
- presented by Gonglin
- little existing spatial reasoning data
- data collection by cleaning
- existing model cannot emulate others’ perspective
- match SoTA LLM w/ 2B model
- vision language model (VLM)
- guest lecture by Xuezhe
- non-generative
- CLIP: pair image w/ description
- VLM from pretrained LLM: LLaVA
- generative distribution-based: model data distribution
- closed-form analytic solution, but weak
- deep learning estimation, but no order & propagate error ⇒ bad
- exact density estimation: directly model joint distro
- generative normalizing flow
- but many layers bc invertible function weak
- determinant calculation expensive
- DL w/ approximate density estimation: variational auto-encoder (VAE)
- encode pixel to denser latent space
- try to recover pixel from latent space w/ evidence lower bound (ELBO)
- but face posterior collapse w/ high-dimensional latent space
- diffusion: add Gaussian noise step by step till get Gaussian (forward process), then (reserve process)
- training loss unstable; can only know by testing
- transfusion: try to unify diffusion transformer training
- 2-stage model bad at understanding task
- generative adversarial network (GAN)
- Improve Vision Language Model Chain-of-thought Reasoning
- presented by Wenbin
- get reasoning tokens from GPT-4o to train VLM
- filter disagreeing sample between annotation & GPT-4o
- Dehumanizing Machines: Mitigating Anthropomorphic Behaviors in Text Generation Systems
- presented by Lydia
- crowd source people on how/why “human-like” they find LLM output
- suggestions on how to reduce human-like tone
- cognitive ability, self-awareness, feeling
- Mind Reading: Decoding the internal representations of the human brain
- presented by Sam Nastase
- fMRI: plethysmography for skull defect
- 1st MRI machine in 1977 “Indomitable”, 0.05T
- MRI machine never shut down, always cooled, superconductive
- more oxygenated blood after second-scale delay of regional brain activity
- linear regression model to distinguish region w/ weight
- encoding/decoding: stimulus vs brain activity voxel
- singular area correlation vs aggregate correlation
- representational similarity analysis (RSA): only care about relationship
- work across subject, including monkey
- JailbreakRadar: Comprehensive Assessment of Jailbreak Attacks Against LLMs
- presented by Abhinav
- 16 violation category on 9 LLM
- LLaMa 3 secure, DeepSeek V3 easy to attack
- prompt guard mitigate most attacks
- A Troublemaker with Contagious Jailbreak Makes Chaos in Honest Towns
- presented by Yuxin
- single-agent attack work poorly
- ARCJ: retrieval + replication suffix to increase toxicity
- Geometric Signatures of Compositionality Across a Language Model’s Lifetime
- presented by Matthew
- compositionality of language: words etc. can recombine w/ other words
- manifold hypothesis: ANN compress representation to low-dimension nonlinear manifold
- idea: language restricted, cannot arbitrarily combine words
- measure: n-gram
- estimate dimensionality of manifold by whether TwoNN (2-nearest neighbor) ratio of distance to nearest by next-nearest neighbor approach 1
- plateau as model scale
- even drop at certain point
- performance jump
- later layer get higher intrinsic dimensionality than earlier layer, as opposed to the inverse w/ fewer parameters
- estimate linear dimension by PCA
- increase linearly as model scale
- LocAgent: Graph-Guided LLM Agents for Code Localization
- presented by Danny
- need to locate specific lines of code to modify
- code graph of files, PL construct
- sparse hierarchical entity indexing (BM25)
- dense embedding suck in practice
- just grep
- let agent filter for node type in code graph
- similar code localization performance to SoTA agent
- Reproduction: Prompts have evil twins
- presented by Kaicheng
- similar generation from weird prompt compared to sensible prompt
- brute-force search for “evil twin” prompt by token replacement
- make it more evil
- fluency penalty to the loss using log probability
- only pick token from limited weird set
linear model
inter-agreement rate: human annotator may disagree
- raw agreement rate
- need to subtract expected agreement (by chance) sum of products of raw rates
- good rate vary by opinion: 0.8 very good; 0.4 some consider good
perceptron: linear gradient lost
- loss only on argmax y
logistic regression: softmax on all y instead of just argmax y
- more stable than perceptron
naive Bayes
- assuming (wrongly)
non-linear model
- need: non-linearly-separable feature
- activation function
- old & bad: sigmoid, tanh
- contemporary: ReLU, GELU, Swish, SwiGLU (used in SoTA LLM)
Thumbs up? Sentiment Classification using Machine Learning Techniques, Bo Pang, Lillian Lee, Shivakumar Vaithyanathan, EMNLP, 2002
distributional feature representations
- embedding: arbitrary vector representation of word sequence
- distributional hypothesis: word meaning determined by where they are used
- pointwise mutual information (PMI) for words: p(word, context)
- positive PMI (PPMI): max(PMI, 0)
- very sparse matrix
- ⇒ singular value decomposition (SVD)
- word2vec
language model (LM)
- can generate: assume what came before determine what comes next
- n-gram: “windowed” Bayes
- backoff
- smoothing
- surprisingly good smallish model
- perplexity: how well LM predict real text by entropy
- feed forward neural network n-gram
tokenization
reuse frequent letter sequence
- byte pair encoding (BPE)
- start w/ character-level tokens
- count most frequent token pair & greedily replace w/ single token
- space sometimes part of token
- not semantically meaningful
- Reddit cause weird token e.g. user name
- small vocabulary cause long context
recurrent neural network (RNN)
- each layer: feed new embedding + old hidden state to get new hidden state
- strong emphasis on last token
- problem: vanishing gradient bc long chain of hidden state
- long short-term memory (LSTM)
- forget/input/output gate
- multiply cell state by forget gate, add input gate, finally multiply output gate
- Bidirectional LSTM (BiLSTM)
- go both backward & forward, then concatenate
- residual: directly add input to output
- attention: how much to attend to each hidden state
- minibatching: concatenate & broadcast multiple sequences for GPU efficiency
- major problem: cannot parallelize; inherently sequential
self-attention
- of each token to every token: parallelizable
- idea: soft weighted lookup (of “query”) in key-value store
step-by-step:
- for each token, compute query of this token, key for every token
- compute attention score using e.g. dot product
- softmax over all to get
- compute value for every token, multiply by and sum
problem & solution:
- no sequence order
- ⇒ position embedding: add a vector representing position e.g. Sinusoidal (OG)/ RoPE
- no element-wise nonlinearity
- ⇒ feed forward network (FFN) after attention layer
- not looking into future
- ⇒ attention mask: set attention score to for future token
transformer
- residual (add): smoothen loss landscape
- layer normalization (norm): speed up training by normalizing mean & variance
- multi-head attention: multiple attention & concatenation
- optimizer: basic SGD
- Adam: momentum, per-parameter normalize adjustment by std of output
- AdamW: de facto in 2025
- checkpoint/restart
pretrained language model
- ELMo (2016): word vector w/ context from BiLSTM
- fine-tuning: reuse model for other task for new task
- GPT (2018): decoder-only classifier-only transformer
- BERT (2018): convert piece of text to 512-dim vector w/ bidirectional transformer
- mask certain tokens w/ [MASK], random token, or actual token, then try to predict
- popular partially bc good marketing as a Muppet just like Elmo
- still fail Winograd challenge: figure out what ambiguous “it” refer to
- GPT-2 (2019): did well on task not trained on
- huge model: 1.5B parameters
- PR stunt bc uhallucinated nicorn story
- GPT-3 (2020): SoTA on many task
- 175B parameters
- few-shot; hardly affected by irrelevant/misleading context
- fixated on what it learned instead of adapting to flipped task
- T0: like T5 but only w/ task phrased in natural language
- LLaMA (2023): public architecture, weights, training data
- no training&preprocessing code
- hard to reproduce
- Gemini (2023): started trend of white paper w/o technical details w/ tons of safety check
modified pretrained language model
- T5: encoder-decoder transformer able to do multiple task
- cross-attention: query from decoder, key&value from encoder
- prefix tuning: prepend token to mark what the task is
- additional parameter alongside each layer
- do not fine-tune original parameter
- adapter: linear layer before&after transformer to adapt to new task
- LoRA: add parameter alongside each layer and add them
- work very well
- can add anywhere: Q, K, V, FFN
- Jon: a student claimed adding to FFN was best
- mixture of experts (MoE, from 1990s): send embedding to different channel for FFN
- learn the router
introspective model ourobouros
- scratchpad (2021): let model generate hidden token
- RNN and transformer are Turing complete if given infinite think time
- chain-of-thought (CoT, 2022): encourage model to include reasoning
- hand-written example for training
- ReAct: agentic + reasoning
human feedback
- problem
- some words matter more
- bad training data
- exposure bias
- evaluation is usually not differentiable ⇒ RL
- InstructGPT/ChatGPT
- supervised fine-tuning: got questions & answers & preference from human
- train reward mode: use human to rank answers from LLM
- PPO: initialize from supervised policy
reinforcement learning (RL)
- less desirable than supervised learning
- trick: start w/ MLE training before RL
- avoid moving away too much from existing model ⇒ KL divergence
- proximal policy optimization (PPO): avoid hard-to-compute KL divergence w/ CLIP
- cap model improvement by
- (DPO): no explicit reward model; only compare action
- minimum Bayes rick (MBR)
- generate many outputs & score against each other
- (GRPO): choose group w/ low variance
inference optimization
- KV cache
- LM-infinite: -shaped + capped attention for “infinite” context window
- attention instability beyond training context length
- speculative decoding: guess many upcoming tokens w/ smaller mode, check in parallel in large model
information retrieval (IR)
- multi-shot
- eval over k shots: mean average precision (MAP)/ normalized discounted cumulative gain (nDCG)/ mean reciprocal rank (MRR, +1/rank for each hit)
- limited ground truth ⇒ false negatives
- human review of ground truth
- user behavior telemetry
- token matching: surprisingly good
- need tokenization to account for word morphology
- TF-IDF/ BM25 (best match)
- cross-encoder: concatenate query & doc, classify
- bi-encoder: encode query & doc separately, find similarity, e.g. Faiss
- late-state interaction (e.g. ColBERT): bi-encoder except per query token
- hard negative training (difficult, e.g. from weaker model)
dialog model
frame-based agent
- frame w/ slots to fill needed info
- agent need to fill in all slots user answered and ask for missing slot
- IOB tagging: beginning (B), inside (I), outside (O) of slot
- fail when user change task, e.g. ask question
- ⇒ dialog state tracking (DST)
- figure out what user’s state is and act accordingly
- evaluation: slot error rate
aimless chatbot
- evaluation w/ BLEU—horrible
- still bad at multi-party, long-horizon
information extraction (IE)
- named entity recognition (NER)
- geopolitical entity (GPE)
- SoTA system still suck at pronoun & nominal
- LLM suck if asked directly; need to ask one by one
- BIOSE: + solo entity (S), end (E)
- coreference: merge node in knowledge graph
- Hearst Patterns
- come up w/ basic pattern
- find pairs w/ that pattern
- find same pairs w/ other pattern
- learn
- event-event relation: temporal, causal
- hard to agree on/ evaluate
- (PDTB)
- rhetorical structure theory (RST)
Last edited:
Advanced Operating Systems
- reliability
- things fail: storage, communication, bug in code, datacenter, CPU/other hardware
- dependency library
- security vuln.: spectre, meltdown, buffer overflow, attack (DDoS)
- incompatibility: version change
- things fail: storage, communication, bug in code, datacenter, CPU/other hardware
- performance
- non-scalable algo.
- congestion
- deadlock
- out of memory
- GC pause
- hypervisor pause
How to read a paper, Srinivasan Keshav, SIGCOMM CCR, 2007
- 3 pass: intro + heading, overall grasp, reproduce
- survey: start from reference section of recent searched paper; find prominent author/conference
An Evaluation of The Ninth SOSP Submissions or How (and How Not) to Write A Good Systems Paper, Roy Levin, David D. Redell
- paper category: implementation, theory, idea, measurement, survey, simulation
- know related work: old & new, peer-reviewed
- not readily solved by existing approach (or w/ tweak)
RAID: High-Performance, Reliable Secondary Storage, Peter M. Chen, Edward K. Lee, Garth A. Gibson, Randy H. Katz, David A. Patterson, ACM Computing Surveys, 1994
- disk array for performance&reliability&cost
- compare architecture: RAID level 0-6
- motivation: processor much faster but disk is bottleneck of overall perf
- large disk array exponentially likely to fail
- array of disk improve bandwidth for big I/O & latency for small I/O
- data striping: distribute data across multiple disk for parallel
- data interleaving granularity
- fine-grained: every I/O use all disk, but is blocking & cause seek for all disk
- coarse-grained: parallel request
- method to handle redundant info
- compute: parity, e.g., Hamming/Reed-Solomon code
- bottleneck on disk storing parity bit
- P+Q redundancy (Reed-Solomon): 2 parity disk to defend against ≥2 disk failure
- distribution: whether concentrate redundant info on few disk
- compute: parity, e.g., Hamming/Reed-Solomon code
- memory-style ECC not assume controller know which disk bad
- RAID 3&5&6 do inversely better on big I/O, poorer in small I/O (but, 5&6 are capped)
- can read fewer disk if write large
- improve small I/O perf by batching&caching
- can read fewer disk if write large
- block interleaving cannot handle some system crash unless w/ hardware like nonvolatile RAM
- system crash more frequent
- track if each parity block consistent for recovery perf
- bit rot hard to handle; solution: predict disk about to fail & replace
- correlated disk failure, system crash, bit rot greatly increase data loss probability in RAID 5
The Recovery Manager of the System R Database Manager, Jim Gray, Paul McJones, Mike Blasgen, Bruce Lindsay, Raymond Lorie, Tom Price, Franco Putzolu, Irving Traiger, ACM Computing Surveys, 1981
- concurrent SQL database failure recovery
- transaction: ACD (no I)
- only way to undo transaction is another
- shadowing: CoW, point to new copy at commit
- transaction log for recovery
- include update value to be idempotent
- checkpoint to avoid log big
- recovery: redo forward from checkpoint for committed (winner), undo backward for loser
Disconnected Operation in the Coda File System, James J. Kistler M. Satyanarayanan, ACM Transactions on Computer Systems, 1992
- offline access to remote file system
- shared file for collaboration & larger storage
- local caching for availability
- prioritize user-specified, recently used; fetch periodically
- cache entire file instead of block
- reconcile conflict thru replay of log of update
- aggregate log periodically, only save last update, rm inverse operation
- detect conflict by version number
- impossible to automatically resolve conflict
- evaluation: benchmark & user trace
- little conflict during in CMU usage bc not editing same file
Eraser: A Dynamic Data Race Detector for Multithreaded Programs, Stefan Savage, Michael Burrows, Greg Nelson, and Patrick Sobalvarro, Thomas Anderson, ACM Transactions on Computer Systems, 1997
- monitor: force all access to acquire lock, but cannot handle dynamic allocation
- happens-before problem: cannot catch when separate access by chance
- detect synchronization between variable access across thread by transitive happens-before
- lock set intersection to track all lock held when accessing each variable
- allow initialization w/o locking, RW lock, reuse allocation
- high overhead, but optimize by deduplicating lock set to track
- mechanism to opt out of checking bc false positive
- binary modification to track set of lock held when accessing each static/heap variable
Improving the reliability of commodity operating systems, Michael M. Swift, Brian N. Bershad, Henry M. Levy, SOSP, 2003
- device driver/ kernel module responsible for many OS crash
- need backward compatibility → cannot separate address space
- why possible: well-defined OS-driver interface
- extension procedure call (XPC): wrapper of kernel call that copy argument/ return value memory back and forth (interpose)
- separate address space/ page table for driver
- assume extension/driver not malicious; not defensive
- recovery: deallocate based on object tracking; restart driver
- page tracking to avoid double free
- reliable: avoid almost all crash
- overhead: higher CPU utilization/ lower performance
- packet sending higher overhead than receiving bc no batching
- XPC is main bottleneck bc page table switch cause TLB flush, close to page tracking & object tracking
- extensible: lots of shared code among different driver
Cores that don’t count, Peter H. Hochschild, Paul Turner, Jeffrey C. Mogul, Rama Govindaraju, Parthasarathy, Ranganathan, David E. Culler, Amin Vahdat, HotOS, 2021
- CPU certain (“mercurial”) core certain instruction silent failure
- e.g., faulty encryption cause data loss, mutex malfunction
- storage/network redundancy trick do not apply
- detection: proactive/ passive/ live with
- hard: intermittent, specific core, after aging, under specific frequency&voltage&temperature
- infeasible overhead: need triple computation to verify
- no known solution
The Design and Implementation of a Log-Structured File System, Mendel Rosenblum, John K. Ousterh, ACM Transactions on Computer Systems, 1992
- motivation: disk seek slow → slow read/write slow; RAM cheap; want to utilize write speed
- store all data in append-only log
- cache read & inode map in memory
- metric: write cost: disk access time per storage vs theoretical time
- superlinear: write cost vs fraction alive in segment cleaned
- segment & clean disk by group of block
- distinguish hot & cold data; prioritize cleaning cold segment bc they may squat segment for long
- assume temporal locality: factor youngest file age in segment
- evaluation: user trace & micro benchmark
Rethink the sync, Edmund B. Nightingale, Kaushik Veeraraghavan, Peter M. Chen, Jason Flinn, TOCS, 2008
- synchronous: guarantee durability, ordering; but unacceptably slow
- Ext3 only write to disk cache even in synchronous mode
- externally synchronous: appear to user & device to be synchronous
- user-centric: does not matter if user cannot see
- async inside app
- force commit on effect, e.g., pipe/device write
- low enough delay for user, hardly noticeable
- 10x faster than Ext3 sync mode in IO benchmark, but slightly slower in web server benchmark
Caching in the Sprite Network File System, Michael N. Nelson, Brent B. Welch, John K. Ousterho, ACM Transactions on Computer Systems, 1988
- client disk caching is slower than server memory caching
- predict (maybe incorrectly) that client won’t need disk
- write-back cache for lower write latency & less server/network load
- defer work: eliminate some overwrite of data
- handle concurrent write conflict: disable cache; versioning
- writer block other writer until write finish
- handle sequential write share: track last writer & force flush cache on new open
- versioning to avoid stale cache on reopen
- metric: performance, scalability (server&network utilization)
Outatime: Using Speculation to Enable Low-Latency Continuous Interaction for Mobile Cloud Gaming, Kyungmin Lee, David Chu, Eduardo Cuervo, Johannes Kopf, Yury Degtyarev, Sergey Grizan, Alec Wolman, Jason Flinn, MobiSys, 2015
- run game on server bc better hardware & compatibility & security update
- high delay bc edge computing expensive&less capable, high last mile latency
- target: 30 FPS, or 32ms to reflect user input
- approach: predict future frame for RTT
- navigation prediction
- Markov chain to predict next action → state → frame
- server send clipped cube of scene for possible future frame
- impulsive event (e.g., gun fire) speculation
- subsample all possible state on triggering
- time-shift trigger to nearby checkpoint tick
- checkpoint: save state object for rollback when prediction wrong
- evaluation
- user play game, opinion score, game performance
- frame time, frame rate, bitrate
A low-bandwidth network file system, Athicha Muthitacharoen, Benjie Chen, David Mazières, SOSP, 2001
- need: access file across slow link like WAN
- upload changed file on close; multi-edit last client to close file win
- inadequate option
- compression not exploit small diff
- log like Coda not handle conflict, not reduce download workload
- variable-size chunking w/ Rabin fingerprint to maximize chunk reuse
- declare end of chunk when least significant 13 bit of fingerprint is certain value
- 13 bit to aim for 8kB
- impose max&min chunk size to avoid edge case
- declare end of chunk when least significant 13 bit of fingerprint is certain value
- check hash-chunk database before reading/writing
- write tempfile when starting upload
- client specify tempfile descriptor for pipelining
- write tempfile when starting upload
- evaluation: run Emacs, Word, GCC, etc.
- network bandwidth usage
- app performance
- problem: side channel attack; cache miss if file encrypted
Coz: finding code that counts with causal profiling, Charlie Curtsinger, Emery D. Berger, SOSP, 2015
- profiling&speeding up multi-threaded program
- ↗️ longest-running function may not ↗️ program bc not on critical path
- causal profile: what overall impact if speed up certain function by certain amount
- virtual speedup, pause other thread
- track throughput&latency through progress point
- evaluation: profile different program & get speedup like predicted
Horcrux: Automatic JavaScript Parallelism for Resource-Efficient Web Computation, Shaghayegh Mardani, Ayush Goel, Ronny Ko, Harsha V. Madhyastha, Ravi Netravali, OSDI, 2021
- motivation: phone have many CPU core, but browser JS use 1 core & bottleneck page load
- concolic execution to find every possible control flow
- fall back to sequential if timeout
- automatically parallelize JS
- metric: total computation time (TCT), page load time (PLT), speed index (SI, integrate #pixel by time)
🤖 Serverless Runtime / Database Co-Design With Asynchronous I/O, Pekka Enberg, Sasu Tarkoma, Jon Crowcroft, Ashwin Rao, EdgeSys, 2024
- 🤖 problem: edge serverless wants local SQL state
- 🤖 cloud DB adds network RTT
- 🤖 SQLite removes RTT but sync I/O blocks the app thread
- 🤖 blocking hurts multitenancy when tenants exceed cores
- 🤖 idea: Limbo makes SQLite-style execution async
- 🤖 add Async/Await bytecode pairs for I/O opcodes
- 🤖 example:
NextbecomesNextAsync+NextAwait - 🤖
sqlite3_step()can returnSQLITE_IO- 🤖 runtime does other tenant work until I/O completes
- 🤖 architecture: query engine stays in-process, storage I/O is virtualized
- 🤖 runtime supplies an I/O module
- 🤖 prototype uses Linux
io_uring - 🤖 runtime event loop polls completions and resumes DB execution
- 🤖 result: microbenchmark reports up to 100x lower tail latency
- 🤖 workload: 1-100 tenants, each runs
SELECT * FROM users LIMIT 100- 🤖 1000 times per tenant
- 🤖 each tenant has a separate 1 MiB DB file
- 🤖 SQLite uses threads; Limbo uses Rust coroutines
- 🤖 workload: 1-100 tenants, each runs
- 🤖 caveat: current Limbo is preliminary
- 🤖 clean-slate Rust prototype
- 🤖 compatibility needs a shared SQLite/Limbo test suite
- 🤖 writes, shared DBs, scheduling, and security remain future work
Shielding Applications from an Untrusted Cloud with Haven, Andrew Baumann, Marcus Peinado, Galen Hunt, OSDI, 2014
Difference Engine: Harnessing Memory Redundancy in Virtual Machines, Diwaker Gupta, Sangmin Lee, Michael Vrable, Stefan Savage, Alex C. Snoeren, George Varghese, Geoffrey M. Voelker, Amin Vahdat, Communications of the ACM, 2010
- modify virtual machine monitor (VMM, or hypervisor) to share memory subpage
- page sharing: point identical memory page at same CoW physical page
- page patching: store a patch (diff) for another similar page, then point to it
- choose not-recently-written-to as reference page
- choose not-recently-accessed page to patch
- page compression of infrequently accessed page
- track page access+write w/ 2 bit
Deciding when to forget in the Elephant file system, Douglas S. Santry, Michael J. Feeley, Norman C. Hutchinson, Alistair C. Veitch, Ross W. Carton, Jacob Ofir, SOSP, 1999
- want to avoid accidental deletion/overwrite of important file
- trash/ recycle bin not good enough: inadequate checkpoint & less useful if soon cleared
- not checkpoint entire file system bc too much overhead & cannot roll back to between checkpoint
- feasible bc disk bigger & only some file need tracking
- minimize space overhead: CoW;
- landmark: user-specified/ heuristic-determined version to keep
- garbage collection: keep one/ keep all/ keep safe
Energy-aware adaptation for mobile applications, Jason Flinn, M. Satyanarayanan, SOSP, 1999
- need: more mobile device, not bigger battery
- more energy-saving technique bring lower energy consumption
- reducing fidelity hardly reduce energy consumption when “think time” high
- system to decrease fidelity as energy deplete
- exponential smoothing of power consumption expectation based on expected half life of battery
MAUI: Making Smartphones Last Longer with Code Offload, Eduardo Cuervo, Aruna Balasubramanian, Dae-ki Cho, Alec Wolman, Stefan Saroiu, Ranveer Chandra, Paramvir Bahl, MobiSys, 2010
- motivation: offload code to cloud to increase battery life
- developer partitioning is manual & static
- full VM migration transfer too much data especially if task small
- continuously profile & offload .NET function
- developer annotate pure function “remoteable”
- communication overhead increase dramatically w/ transfer size & RTT
- measure overhead&benefit: linear pre-built model to estimate energy cost
- send state diff to reduce bandwidth
Wide-area cooperative storage with CFS, Frank Dabek, M. Frans Kaashoek, David Karger, Robert Morris, Ion Stoica, SIGOPS OSR, 2001
- chord: circle to determine node responsible for data
Cluster-Based Scalable Network Services, Armando Fox, Steven D. Gribble, Yatin Chawathe, Eric A. Brewer, Paul Gauthier, SOSP, 1997
- replace ACID w/ BASE
Improving MapReduce Performance in Heterogeneous Environments, Matei Zaharia, Andy Konwinski, Anthony D. Joseph, Randy Katz, Ion Stoica, OSDI, 2008
- deal with straggler in MapReduce w/ heterogeneous machine
Efficient Memory Disaggregation with Infnswap, Juncheng Gu, Youngmoon Lee, Yiwen Zhang, Mosharaf Chowdhury, Kang G. Shin, NSDI, 2017
- tend on more blurry machine boundary: abstraction of shared CPU&memory
- possible bc RDMA fast
- motivation: huge performance impact if working set data not all in memory
- write swap memory to remote machine; async write to disk for backup
Hints for Computer System Design, Butler W. Lampson, SOSP, 1983
On system design, Jim Waldo, SIGPLAN Notices, 2006
external paper
Triangulating Python Performance Issues with Scalene, Emery D. Berger, Sam Stern, Juan Altmayer Pizzorno, OSDI, 2023
Last edited:
Algorithms and Databases
sort
insertion sort
loop invariant
the first j keys but sorted
heap sort
- make a max-heap
- throw the head out to the end of the array
- max-heapify the heap
- stop when the max-heap has 1 element
max-heap
- an array
A - heap size
size- array size
- element in the array out of the heap are ignored
- heap head
- first array element
A[0] - no parent
- first array element
- parent
A[(n - 1)//2]-
A[n]
- left
- exist if
2n + 1 < size - left child
A[2n + 1]
- exist if
- right
- exist if
2n + 2 < size - right child
A[2n + 2]
- exist if
build max-heap
convert a heap to a max-heap
- from
A[parent(size - 1)]toA[0], max-heapify the heap
max-heapify
convert a heap to a max-heap from A[i] provided that both left and right are max-heap
- find the maximum
A[l]amongA[i], left, right - if
A[i]is not the maximum, swap them and max-heapify fromA[l]
priority queue
a max-heap that act as a queue
max
return largest (A[0])
extract max
pop max
- swap
A[0]andA[size] - store
A[size] - kill
A[size]and decrementsize - max-heapify from
0
increase key
increase a key and keep the heap a max-heap
- swap
A[i]withA[parent(i)]whilei > 0andA[parent(i)] < A[i]
insert
- increment
size A[size - 1]- increase key on
A[size - 1]
quicksort
- partition the array so there is a point in the array, everything left to it is less than it and everything right to it is larger than it
- quicksort the left and the right
counting sort
sort integer know to be less than a constant
- initialize auxiliary array of 0 with length equal to the constant
- traverse the array and increment the index corresponding to the value in the auxiliary array
- traverse the auxiliary array and add the last element to this element, now the values represent the amount of elements less or equal to this element
- backwards traverse the array and fill in to index in the final array corresponding to the value in the auxiliary array, and decrement the value in the auxiliary array
radix sort
sort according to the last digit, then the previous, until the first
growth of function
asymptotic notation
notation
bounded above and below
notation
bounded above
notation
bounded below
notation
bounded above, not asymptotically tight
notation
bounded below, not asymptotically tight
median & order statistics
th order statistic
the th smallest element in the set
(lower) median
halfway point of the set
selection problem
find an element in the set larger than exactly element
Last edited:
Artificial Intelligence
most supervised learning when ppl talk about
ethics
Mill’s utilitarianism: maximize benefit for everyone, mostly equally
bane:
- conflict of interest
- personal benefit
Kant’s formalism/ duty ethics: unconditional command for every individual
bane: universal principle may harm specific people
Locke’s Right Ethics: individual has right simply by existence
bane: what to do when two people’s rights conflict
Aristotle’s virtue ethics: objective goodness from human qualities
bane: how to find the “golden mean”
the golden rule (all above agrees with)
Do unto others as you would have others do unto you
codes of ethics
statements of general principles, followed by instructions for specific conduct
defiens duties the professional owes to society/employers/clients/colleagues/subordinates/profession/self
engineering design process
- recognize problem/need, gather information
- define problem/goal
- generate/propose solution/method
- evaluate benefit&cost of alternatives
handling ethical issues
- correct the problem
- whistle blowing
- resign in protest
definition of artificial intelligence
- humanly → acting
- ration → math/theory
Turing test
- NLP
- knowledge representation
- automated reasoning
- ML
total Turing test
perceptional abilities
- computer vision
- robotics
thinking humanly
- get inside the working of human mind
- general problem solver
- cognitive science
thinking rationally
- correctness
- logic
- fact-check
knowledge-based system
- general-purpose search
- domain-specific knowledge
- knowledge bottleneck
intelligent agent
rational agent
- prior knowledge of environment
- performable action
- performance measurement
- perception
task environment
PEAS: performance measurement, environment, actuators, sensors
properties
- fully/partially observable
- single/multiple agent
- deterministic/stochastic
- episodic/sequential
- static/dynamic
- known/unknown
agent structure
- function: perception → action
- architecture: sensory → actuator
table-driven structure
- simplest
- e.g. industrial robot
- #cases explode
simple reflex agent
match input against rule, return action
- model-based: only work for fully observable
- goal-based
- utility-based: maximize gain expectation
search
- breadth/depth first
example application
collaborative perception
- share raw data → huge overhead
- extract feature
- share object position
anomaly detection
- bidirectional optimization
uninformed search
- backtracking search
breadth-first search
- complete: will find shallowest goal if graph has finite depth
- optimal if path cost is non-decreasing of depth
- where is branching factor
uniform-cost search
expand node with least path cost
- optimal
- where every action cost
informed search (heuristic search)
A* search (A-star search)
- cost
- cost to reach node
- estimated cost to goal, heuristic,
- optimal if is admissible in tree search
- admissibility: never overestimate
- optimal if is consistent in graph search
- consistency: triangle inequality
- optimally efficient if is consistent: expand fewest node among optimal algorithm
reinforcement learning
- control system
- model-based vs model-free
dynamic programming
- key: sub-problem
example
- Dijkstra’s algorithm: per node
- Bellman-Ford algorithm: per hop
discrete Markov decision process (discrete MDP)
finite tuple
space
action
state transition probabilities
discount factor
reward function : evaluation metric
total payoff. maximize this
policy . find this
find optimal policy
optimal policy
mapping state to expected total payoff
Bellman equation
value iteration
Bellman update:
- linear system
- Bellman back operator
- sync/async update
- force to converge exponentially
policy iteration
random
repeat:
- when converge, guarantee optimal policy
- high complexity: linear system very step
exploration and exploitation
-greedy
- is small and decrease
softmax
continuous Markov decision process (continuous MDP)
inverted pendulum
- kinematic model
discretization
- curse of dimensionality:
- bad for smooth function
4 ~ 8 dimension
value function approximation
approximate
trial
model/simulator:
- assume discrete
learn from data
- trial, each with time step
- supervised learning
- linear regression
- deterministic/stochastic model
- noise term
- model-based reinforcement learning
- fitted value iteration
fitted value iteration
approximate from
trial: ramdomly sample
initialization:
repeat for :
repeat for :
sample
is estimation of
any regression model, e.g.
- for deterministic model, can set
Mealy machine MDP
Bellman equation:
finite horizon MDP
finite tuple
time horizon
maximize
action based on time
time-dependent dynamic
- solution by dynamic programming: work way back from
linear quadratic regulation
linear transition with noise
negative quadratic reward to push system back
policy searching method
stochastic policy
: probability of taking action at state
direct policy search: find reasonable
- fixed initial state
- greedy stochastic gradient ascent
- learning rate
repeat:
sample
reinforce
reason it converge: product rule
partial observable MDP
reinforce with baseline
- arbitrary baseline
- independent of
Monte Carlo method
- trial:
- wait until end of episode return
- drawback: slow if episode long
time-difference learning (TD-learning)
at time , update
TD error
on-policy TD (SARSA)
- -greedy
- initialize arbitrary reward
- repeat for episode
initialize
behavior policy: select based on
repeat for each step
select potential for based on
update
until is terminal
off-policy TD: Q-learning
same as SARSA except
- greedy
Last edited:
Cloud Computing
operational expense (OPEX), capital expense (CAPEX) → centralize server
tenant isolation: challenge for cloud provider
cloud provider classification: infrastructure/ platform/ software as a service
data center hierarchy: rack, row & aisle, pod (building unit)
top-of-rack (ToR) switch: 2 per rack, high capacity
- north-south traffic: outside to inside—load balancing
- east-west traffic: within inside—high bandwidth
network topology
- fat tree. problem: require insane link capacity on top
- link aggregation: bond multiple link together
- leaf-spine topology (clos): layered multiple spine connected to multiple rack
Internet redundancy: multiple ISP
data storage
- classical approach: server with own HDD, data replication
- modern approach: separate compute/ storage unit, SSD, less data replication
Hadoop
- automatic MapReduce management
- HDFS: Hadoop distributed file system
- assume each server has own storage
- append-only, 128MB block
- NameNode index, DataNode store
- try to compute with local data
Spark
- multi-paradigm, high-performance
- building block: resilient distributed dataset (RDD)
- general, lazy, ephemeral, lineage, shareable
- aggressive caching with LRU
paravirtualization: modify guest OS to not use kernel space
- high performance
- hard to modify OS
full virtualization
- native performance
- need hardware support (e.g. ring -1 for hypervisor)
container
- isolate: network namespace, file system, process information, user
- Linux containers (LXC): more full system than Docker
automation level: deployment & configuration, → monitoring & measurement, → trends & prediction, → root cause analysis, → troubleshooting
- vendor-independent configuration: zero-touch provisioning & infrastructure as code
orchestration
- building blocks: ephemeral, can be replicated, replaced, composed → update, autoscaling, restore
- load balancing
- early error detection during rollout
Kubernetes
- pod: group of container, smallest unit to be managed
- init container: run before other
microservice: smaller scope & team, modularity, less complexity, language flexibility, test coverage, rapid deployment, fault isolation; cascading error, functionality & data duplication, attack surface
service mesh proxy: load balancing, convert conventional communication protocol
hysteresis: delay in response to change
- cause instability, oscillation
- event-based controller
- stabilization window
serverless/ FaaS: API redirection & runtime & DB by provider. event-driven, stateless, scale from zero to infinite
classic software development → agile → DevOps → site reliability engineering (SRE): merge development, quality assurance, operation
- version management
- extensive testing in continuous integration
- sandbox & canary deployment
- SRE: half time development, max half time operation, overflow redirect to development team
- on-call shift
- post-mortem report, pager fatigue
- error budget: target < 100% availability, adjust development accordingly
- playbook: automate away human
- on-call shift
networking safety and isolation: harden north-south traffic, assume cooperation & prevent traffic among tenant on east-west traffic
- same tenant: overlay topology (virtual) & underlay (physical)
- different tenant: traffic like north-south
- implementation: VLAN, packet carry tag
- VXLAN (extended): encapsulate, solve 4096 VLAN limit
remote storage interface: file/ block interface (NFS/ virtual disk)
object storage: key-bytes pair
Last edited:
Introduction to Databases
information: data with meaning
knowledge: actionable information
exploratory data analysis (EDA)
relation ≈ table
data definition language (DDL): for schema
data manipulation language (DML): for query and CRUD
DML & DDL both in SQL
data model (DM): entity, attribute, relationship, constraint
entity relationship diagram (E-R diagram) (ER diagram)
unified modeling language (UML): for OODM
relation schema
relation instance
- element
attribute usually atomic
superkey : subset of row tuple, bijection with row
- superset of is also superkey
candidate key = minimal superkey
union compatibility/ type compatibility
data control language (DCL) & transaction control language (TCL): management
like: any substring %, any char _
for where clause filter: like, between, some, all
for where clause standalone: exists, unique
union, intersect, except (all)
select x, fn(y) from _ group by x having …
boolean type: true, false, unknown
select _ from _ where x in y;
-- lateral clause:
select _ from x, lateral (/* access outside variables */) …;
-- with clause:
with alias_name as (…) select …;
delete from _ where _;
insert into table_name (attributes, …) values (…,), (…,), …
update table_name set attributes = value where …;
-- join using
select _ from relation1 join relation2 using (attr1, …);
-- view/ materialized view
create view view_name as select …;
create materialized view view_name as select …;
domain constraint on single relation: not null, unique, check (…)
referential integrity: foreign key (attr1) references table_name on delete …
named constraint: attr1 type, constraint constr_name check (…)
- drop named constraint:
alter table table_name drop constraint constr_name; - deferrable constraint: check at end of transaction
assertion
create assertion assert_name check (…);
function call
coalesce(attr1, default_value_in_place_of_null)cast(attr1 as type)data_format(value, 'format string')if(predicate, value_when_true, value_when_false)ordecodein Oracle
user-defined type (UDT): distinct type/ structured data type
create type type_name as …;
create domain domain_name as …;
create table extension
create table table2 like table1;
create table table1 as (select …) with data;
stored function/ stored procedure:
delimiter $$
create function fn_name(arg1 type1, …) returns type_out begin
-- declare local variable, set to NULL by default
declare local_var var_type default default_val;
-- mutate local variable
set local_var = …;
select _ into local_var from …;
return …;
end $$
-- `type_out` can be a `table (…)`—table function
create procedure proc_name(
in arg_input type1, out arg_output type2, inout arg_mutate type3, …
) begin
-- …
end $$
-- no returning for procedure
delimiter ;
-- call procedure
call proc_name(args…, @outside_var);
stored function: deterministic/ non-deterministic (default)
procedural SQL:
-- expression with pattern matching
case -- optionally with value here
when _ then _
…
else _
end;
-- loop
label1: loop
iterate; -- continue
leave; -- break
end loop;
while predicate1 do
-- …
end while;
repeat
-- …
until predicate1 end repeat;
for each_row as table_value1 do
-- …
end for;
trigger:
create trigger trigger_name after insert on table_name -- or `before`, `delete`
referencing new row as row_name for each row when ( -- or `old row`.
-- or without renaming `new` or `old`.
-- …
)
begin -- compound statement
rollback
end;
-- multiple trigger
create trigger trigger_name before update on table_name
for each row follows another_trigger_name begin
-- …
end, $$
error handling:
declare continue handle for sqlstate 'err_no' begin -- or for `not found`
-- …
end; -- or `set _ = …`
cursor:
declare cur_name for select _ from _;
open cur_name;
fetch cur_name into var1, …;
close cur_name;
entity-relationship model (E-R model): entity set, relationship set, attribute
- multi-valued attribute, composite attribute, derived attribute
- mapping cardinality, cardinality constraint (directed/undirected link)
- total participation (double line)/ partial participation
- weak entity set
- identifying entity set primary key → discriminator attribute
- descriptive attribute
lossy decomposition: (lossless: )
functional dependency (FD) : can uniquely identify by
- trivial FD:
- lossless decomposition (or swap 1&2)
Boyce-Codd Normal Form (BCNF): or superkey
mean time to failure MTTF
RAID: data striping vs mirror
fixed-length record: deletion: free list for deletion
variable-length record: offset + length, null bitmap
heap: free-space map (first/second-level)
sequential file: linked list of sorted search key
multi-table clustering file organization: faster some join & slower some other, cluster key
table partitioning
buffer manager: buffer replacement strategy (LRU/MRU), pin/unpin, shared/exclusive lock
column-oriented storage: less IO, better caching & compression
dense index: index for each search-key value
- dense clustering index: group by cluster key
sparse index: index for some search-key value
deadlock prevention:
- wait-die scheme, non-preemptive: older transaction wait for lock, younger transaction die
- wound-die scheme, preemptive: older transaction wound younger transaction when waiting for lock
- timeout-based scheme: hard to determine timeout, starvation
- wait-for graph: cycle → deadlock
recovery system:
- log-based recovery: redo/undo, immediate/deferred DB modification
Last edited:
Introduction to Programming and Data Structures
encryption
one-time pad
bitwise XOR: bitwise exclusive or
∧ caret (\wedge)
Boolean algebra
pseudo-random
pseudo random bits:
linear feedback shift register LFSR
bit, cell, register, seed, initial state
[N, k] LFSR: N-bit register with taps at N and k
seed cannot be 0, at most 2N − 1 fills in N-bit register
k counts from 1…
Java programming
virtual terminal vs integrated development environment IDE
Java program shell:
public class program_name {
public static void main(String[] args) {//begin
body
}//end
}
piping and redirecting—|, <, >
| is two directional
< and > take one’s output as the other one’s input, following the arrow
for multiple piping, “parenthesis” are added as if
convert to type: Type.parseType(String_needs_converting)
cast: (type) what_needs_converting
does not convert type when divide
convert to the more precise type when operate between two types
int
Integer.MAX_VALUE + 1 = Integer.MIN_VALUE =-Integer.MIN_VALUE
remainder %
char—uses ASCII, can be operated as if int, cast to int if not assigned to a char
a~z, A~Z, 0~9 are together in ASCII, this can give a range
char array converts to String when called String.valueOf()
StringBuilder—better way to concatenate strings
concatenate strings: .append
double
special values: Infinity, NaN
math library
type operation(type variable, …)
type: double, int, long, float
operation: abs, max, sin, asin, exp, log, pow, round, random, sqrt
variable: a, PI, E
boolean operation
and &&
or ||
not !
xor (!a && b) || (a && !b)
(a && b) == (!(!a || !b))
naming
camel case: moreThanOneWord
constant: MORE_THAN_ONE_WORD
loop
if if (boolean) {execution1;}
else {execution2;}
while while (boolean)
{
execution1
}
for for (initialization_statement1, …; boolean; increament_statement1, …)
{
execution
}
switch switch (variable) {
case literal -> operation;
…
}
do while do {execution1} while (boolean);
at least does once
array
type[] name;//declare array name of type type
new double[length];//an array of length length, all 0.0s
name[index] = literal//refer to array name by index index
{literal1,…}//an array
.length
copy: copy the length and every single value
assign: refer to the same array
two dimentional array
double[][] a
a[0].length decide all a[i].length
sorting: Arrays.sort()
output: System.out.println(output)//print output \n
System.out.print(output)//print output
System.out.printf(“string1%w1.p1c1… string2”,output1,…)//print string1 output1… string2 with field width w, precision .p, and conversion code c
negative w counts from the right. for c, d: decimal, f: floating, e: scientific, s: string, b: boolean
must have % and c
this is the standard string format in Java
https://docs.oracle.com/javase/tutorial/java/data/numberformat.html
DecimalFormat df = new DecimalFormat(“##.##”);
StdDraw line(,,,), point(,),
setCanvasSize(w,h), setXscale(x0,x1), setPenRadius(),
shape, filledShape
text(x,y,String)
enableDoubleBuffering, show, clear, pause,
System.exit(0); makes the program stop
input:
command-line argument: args[No.] //input in modyfy run configuration - program argument
StdIn: isEmpty, readType, readAllTypes, hasNextChar, hasNextLine*//Type = Int, Double, Boolean, String, or Line*
scanner:import java.util.Scanner; //import scanner
Scanner sc= new Scanner(System.in); //define a scanner
Type variable = sc.nextType();//let variable be input
make an explanation
/*
*
/
function
static void can change content of array as they are mutable, cannot change value of primitive type as they are immutable
import static imports the method so that its prefix can be ommited don’t use
applications programming interface API
private static long[] makes the array global
call: ClassName.method(object)
final makes the variable immutatble
recursion
recurrence relation
Gray codes: show all n-digit binary numbers by only changing 1 digit at a time
start from i = 0, change the ith digit from 0 to 1 and do everything done to the first i − 1 digits backwards
recursive graph
fractal
Brownian bridge: random path to bridge to points
midpoint displacement method: take the midpoint and Gaussianly-randomly move it, and set it as one of the end point
volatility: initial variance of the Gaussian dist
Hurst exponent H: divide the variance of the Gaussian dist by 22H H is ½ for Brownian bridge
fractal dimension: 2 − H
plasma clouds
exponential waste: calculate the same thing again
dynamic programming
store calculated results in array
top-down solution
make global array and recursion
bottom-up solution
make local array and loop
longest common subsequance LCS problem
for x[i…m) and y[j…n),
percolation
Monte Carlo simulation: apply randomness to estimate unknown qualities by simulation
2-dimentional n by n sites
blocked site, open site; full site, empty site
site vacancy probability p
vertical percolation: go straight down
object
reference type vs primitive type
create object: ClassName reference = new ClassName(argument1,argument2,…)
Color
import java.awt.Color;
Color(r,g,b)
col.getBlue()
Luminance Y = 0.299r + 0.587g + 0.114b
reference type
aliasing—pass by value
orphaned object: don’t have a reference
instance method: data-type operation for reference type
reference.method(argument)
create data-type
public class ClassName {
*// instance variable inside the reference type (not final if need to change value)
*private final type instanceVariable1;
…
*// constructor, with the same name as the class
*public ClassName(type parameterVariable1, …) {
type localVariable = value;
instanceVariable1 = parameterVariable1;
…
}
/*
- explanation of the method
*/
*public double methodName(type argument1, …) {
…
return something;
}
use short name for instance variables for convenience
use full name for parameter variables as the client can see them
immutability: final makes the value of primitive type and the identity of the object of reference type immutable
defensive copy: copy each of the values of the parameter variables to avoid aliasing
interface type
public interface interfaceName {
public abstract type methodName(type parameterVariable);
}
abstract methods: includes nothing
implements
public class ClassName implements interfaceName{
public int methodName(type parameterVariable) {
}
}
the class must have methods coresponding to all abstract methods in the interface
interface enables a method name to call different methods according to the object
functional interface: single method
lambda expression
(parameterVariable1,…) -> stuffToReturn;
implementation inheritance
subclass
general equals method
public boolean equals(Object x)
{
if (x == null) return false;
if (this.getClass() != x.getClass()) return false;
Class that = (Class) x;
return (this.instanceVariable1 == that.instanceVariable1) && …;
}
general hashcode method
public int hashCode() {
return Objects.hash(instanceVariable1,…);
}
wrapper type: built-in reference type corresponding to primitive type
autoboxing and unboxing
performance
running time: time when finish minus time when start (in millisecond)
System.currentTimeMillis()
System.nanoTime()
algorithm
tilde notation ∼ f(n)
order of growth
empirical analysis
doubling hypothesis: double the input size, study the running time
mathematical analysis
memory usage: bool—1; char—2; int, float, padding—4; long, double, object reference—8; object overhead—16; array overhead—24 (b)
big-O notation O(g(n)): running time |f(n)| < c|g(n)| ∀ n > n0
binary search
exception filter—determine whether a name is in a sorted array
collection
operations—create, insert, remove, test emptiness
item
(pushdown) stack
last-in-first-out (LIFO)
operations—push, pop, test emptiness
queue
first-in-first-out (FIFO)
linked-list
node—content + next node
iterator
resizing array—double the size if no enough space, halve it if less than ¼ used
avoid loitering—set the variable to null
generic type
generic class—a class that can be fed with different data types
public class GenericClass<typeParameter>
type parameter—a name for the data type to be used in this class by the client
constructor
public GenericClass(typeParameter parameter**)
{
para = parameter;
…
}
using the constructor
GenericClass<String> variableName = new GenericClass<String>(“blah”)**;
symbol table
key-value pairs—cannot be null
get(key)/ put(key,val)
contains(key)
hashing
binary search tree BST
put
get
regular expression
minimum RE
concatenate
union—| or {…,…}
closure—x*
grouping—()
java REs
String.matches(regex)
Pattern pattern = Pattern.compile(RE)
Matcher matcher = pattern.matcher(input)
matcher.find()
matcher.matches()
shorthands
wildcard—.
beginning of line—^
end of line—$
range—[char1-char2]
negation—^x
closure operator extension
one or more—x+
zero or one—x?
length—{num}
between—{low, high}
deterministic finite-state automata DFA
finite number of states
transitions
tape reader
universal virtual DFA
input format—number of states \s alphabet \s one line of each state
nondeterministic finite-state automata DFA
pushdown automaton PDA
Turing machine
universality
computability
David Hilbert’s questions: mathematics is consistent, complete, decidable?
Kurt Gödel: axiomatic system cannot be both consistent and complete
Alan Turing: mathematics is not complete
halting problem—reductio ab absurdum
totality problem, equivalence problem
Henry Rice: determining whether a program has any given functional property is unsolvable
intractability—no algorithm exists to efficently solve
polynomial-time algorithm—bounded above by a**nb—efficient
exponential-time algorithm—bounded below by 2a**nb
satisfiability problems
search problems—the problems with solutions that polynomial-times algorithms can check
NP—the set of all search problems
NP-complete—every search problems polynomial-time reduces to it
P—the set of all search problems that can be solved in poly-time
representation
binary—0b
convert to binary and print—System.out.print(String.format(“%16s”, Integer.toBinaryString(number)).replace(’ ’, ‘0’));
hexadecimal—0x
read hexadecimal—Integer.parseInt(input, 16)
twos-complement—−x = ∼ x + 1
∼ x—complement, flip all bits
arithmetic shift right—add 1 to begin if negative
logical shift right—always add 0
masking—get the bits wanted by bitwise or with a mask that only has 1s in the corresponding bits
TOY machine
16 bit
memory
memory location M[00] ∼ M[F**F]
memory dump M[F**F]—standard IO
arithmetic and logic unit ALU
computation engine
register
16 words R[0] ∼ R[F]
connect ALU & memory
R[0] is always 0
program counter PC
8 bit
memory address of next instruction
instruction register IR
current instruction
fetch-inctemenat-execute cycle
fetch from memory to IR
increment PC
execute as IR says and change memory or PC or calculate
instruction format (16 bit)
type RR—opcode + 3 registers (destination + 2 sources)
arithmetic instruction—1, 2 for addition, subtraction
logical instruction—3~6
type A—opcode + register (destination) + memory address (8 bits)
memory address instruction—7, A, B
memory instruction—8, 9
flow of control instruction—C~F
branching
halt—0
loop with branching
self-modifying code
TOY VM
booting—using a small program, load input into M[00] ∼ M[F**F] to start the machine
assembler—run assembly-language
assembly-language—use symbolic name for operation and addresses
interpreter—directly execute instruction written in a programming language
compiler—transform source code into another computer language
bootstrapping—use one virtual machine to create more powerful machine
Boolean logic
Boolean function and notation
NOT(x) ¬x x’
AND(x,y) x∧y xy
OR(x,y) x∨y x+y
XOR(x,y) x⊕y x⊕y
truth table
Boolean arithmic
absorption—x(x + y) = x + xy = x
DeMorgan’s laws—(xy)’ = x’ + y’ (x + y)’ = x’y’
Boolean function of more variables
majority—MAJ(…) = 1 iff more 1 than 0
odd-parity—ODD(…) = 1 iff number of 1 is odd
sum-of-products representation—OR(AND(each of the cases that contribute to 1)…)
circuit—interconnected network of wires, power connections, and control switchs that take value from input wire and output via output wire
control switch
relay—control line with electromagnet
vacuum tube
transistor
gates
recursive definition—a gate or a network of circuits that are connected with wires
combinational circuit—no loop
output depend only on input
decoder—tell which output wire to activate
n input, 2n output
demultiplexer (demux)—add another input to decoder
add AND gate to decoder output
act as 1-to-2n logical switch
multiplexer (mux)—AND all corresponding input and OR all of those
n + 2n input wires, 1 output wire
act as 2n-to-1 logical switch
sum-of-product circuit
ALU
module—parts of the computer
bus—group of wires to transmit data between modules
sequential circuit
buzzer
flip-flop
set
reset
register
memory
bit-slice design—same circuit for demux to write and mux to read
clock
tick-tock
clock speed
fetch and execute complementary
run and halt input
CPU
control
fetch
fetch write
execute
execute write
Last edited:
Networked Systems for Cloud Computing
- sovereignty: legislation cause data to stay within regions
motivation: cloud app
- merchant silicon switch: Broadcom; only provide chip (cheaper)
- as oppose to Cisco, which provide entire rack + software (expensive)
- previous network could not run new huge app
- four-post design: 4 router each connected to each of 512 racks via 1G port
- each ToR only 4G uplink despite 40x server w/ 1G link
- ⇒ NIC oversubscription
- four-post design: 4 router each connected to each of 512 racks via 1G port
- uniform bandwidth: pairwise same among server
- power domain: outlet w/ same power source
- source fail ⇒ all fail
- uniform bandwidth resilient to power domain fail
- power domain: outlet w/ same power source
Papers
Jupiter rising: a decade of clos topologies and centralized control in Google’s datacenter network
Arjun Singh, Joon Ong, Amit Agarwal, Glen Anderson, Ashby Armistead, Roy Bannon, Seb Boving, Gaurav Desai, Bob Felderman, Paulie Germano, Anand Kanagala, Hong Liu, Jeff Provost, Jason Simmons, Eiichi Tanda, Jim Wanderer, Urs Hölzle, Stephen Stuart, Amin Vahdat, CACM, 2016
- Clos topology: switch have same radix; core & aggregation layer
- assume switch has port ⇒ core + aggregation switch
- ⇒ get switch w/ port
- rearrangeable
- non-blocking: 1:1 subscription ratio (telecom terminology)
- mathematically proved: ALA where is downlink per middle layer, is uplink
- bisection bandwidth: as if cut network in half
- multi-stage Clos: more layer ⇒ exponential scaling
- 3-stage give port, -stage give
- Firehose: 32up, 32down aggregation block each made of Clos of 8-port switch
- each ToR connect to 2 aggregation block
- deployed side-by-side w/ legacy network; big red button (fallback)
- Watchtower: 128-port line card from 3 layer of 8x 16-port switch chip
- standardized design for economic of scale
- optical fiber
- Saturn: similar to Firehose but w/ 288-port line card from 12x 24-port chip
- ToR: 4up 20down (5:1 oversubscription) or 8up 16down (2:1 oversubscription)
- Jupiter: w/ 16x40G or 64x10G switch chip
- 128-port centauri chassis from 4 switch chip (not interconnected)
- 64up 256down blocking middle block from 4 centauri
- aggregation block from 8 middle block
- spine block from 6 centauri; 128down to 64x aggregation block (2x redundancy)
- incremental: build aggregation block first, spine later
- ⇒ ToR more burst bandwidth
- external connection: cluster block router (CBR), work like normal racks
- much larger internal traffic than external
- choose this bc any racks can have all external bandwidth
- Freedome block (FDB): Freedome border router (FBR) + Freedome edge router (FER)
- 2-stage fabric running BGP
- datacenter Freedome (DFD): 4x FDB to campus layer
- campus Freedome (CFD): 4x FDB to WAN
- in-place upgrade: reserve 25% capacity so can bring down 1 FDB w/o hitting app
- routing for full bisection bandwidth
- equal-cost multi-path (ECMP)
- same path per flow, e.g., hash flow 5-tuple
- centralized routing
- work bc topology very regular
- switch (client) tell Firepath master state w/ BGP update
- master provide 1 default route for outgoing traffic, aggregate incoming traffic into a single IP prefix
- ⇒ scalability
- equal-cost multi-path (ECMP)
Jupiter evolving: transforming google’s datacenter network via optical circuit switches and software-defined networking
Leon Poutievski, Omid Mashayekhi, Joon Ong, Arjun Singh, Mukarram Tariq, Rui Wang, Jianan Zhang, Virginia Beauregard, Patrick Conner, Steve Gribble, Rishi Kapoor, Stephen Kratzer, Nanfang Li, Hong Liu, Karthik Nagaraj, Jason Ornstein, Samir Sawhney, Ryohei Urata, Lorenzo Vicisano, Kevin Yasumura, Shidong Zhang, Junlan Zhou, Amin Vahdat, SIGCOMM, 2022
- wavelength division multiplexing (WDM): multiple stream on 1 optic fiber
- data rate can vary per stream
- optical circuit switch (OCS): programmable mirror
- make topology reconfigurable w/o manual operation
- support any speed bc based on WDM
- each block w/ 4 separate power domain (failure domain)
- ⇒ 1 power failure only reduce 25% capacity
- direct connect architecture: rid spine, OCS directly connect high-speed aggregation block
- bc spine & full bisection cost too much
- blocking ⇒ traffic engineering (TE) & topology engineering
- doable bc traffic mostly stable, topology more stable
- weighted cost multi-path (WCMP) for TE
- weights on aggregation blocks
- traffic matrix: directed demand between aggregation block
- Orion: software-defined networking (SDN) control plane for OCS
- aggregation block run Orion domain controller
- OCS group run Orion DCNI
- DCNI: optical switched datacenter network interconnection layer
- topology engineering controller change Orion DCNI
- use separate control plane network; but collocate w/ data plane
- fail static: continue w/ final config when fail
- traffic engineering
- indirect path: may hop over another aggregation block to satisfy demand
- hedging: reduce burst; use spare capacity
- minimize maximum link utilization (MLU)
- frequent: 15min at paper’s time; 2-5min now
- indirect path: may hop over another aggregation block to satisfy demand
- topology engineering
- only change topology when no feasible solution thru routing
- traffic-aware topology; help w/ heterogeneous link capacity
- manual rewiring + OCS reconfiguration
- gradual rewiring a few links
- capacity drop ≤25%
- may reduce “stretch” for some traffic: path length per shortest path
- infrequent: weeks at paper’s time
Alibaba HPN- A Data Center Network for Large Language Model Training
Kun Qian, Yongqing Xi, Jiamin Cao, Jiaqi Gao, Yichi Xu, Yu Guan, Binzhang Fu, Xuemei Shi, Fangbo Zhu, Rui Miao, Chao Wang, Peng Wang, Pengcheng Zhang, Xianlong Zeng, Eddie Ruan, Zhiping Yao, Ennan Zhai, Dennis Cai, SIGCOMM, 2024
- dense (not MoE) LLM training cause huge synchronized spike
- very few connection per network interface (~10)
- 2 network: frontend standard Clos, backend for LLM training only
- frontend has storage; handle inference
- backend:
- NIC per GPU + CPU; 8 CPU per host (server)
- intra-host network for each GPU e.g. NVLink (alongside NIC)
- only CPU’s NIC connect to frontend; GPU NIC connect to backend
- 136-host segment; +1/16 spare GPU in case of failure
- rail-optimized ToR: each GPU connected to alternating ToR other machines’ GPU connect to
- can go thru different ToR + NVLink for communication
- mitigate biggest impact: ToR failure
- every other backend ToR connect another plane’s aggregation block
- 2-plane pod
- avoid routing load imbalance from hash polarization
- multi-pod core layer: highly subscribed bc training fitted in 1 pod
NegotiaToR: Towards A Simple Yet Effective On-demand Reconfigurable Datacenter Network
Cong Liang, Xiangli Song, Jing Cheng, Mowei Wang, Yashe Liu, Zhenhua Liu, Shizhen Zhao, Yong Cui, SIGCOMM, 2024
- futuristic configurable ToR
- AWGR: dumb optical switch; smart ToR reconfigure path by sending different wavelength
- nanosecond reconfiguration time
- each epoch: 1-bit message to indicate whether want to send to reconfigure
- no centralized control
- REQUEST, GRANT, ACCEPT message to establish connection
Running BGP in Data Centers at Scale
Anubhavnidhi Abhashkumar, Kausik Subramanian, Alexey,reyev, Hyojeong Kim, Nanda Kishore Salem, Jingyi Yang, Petr Lapukhov, Aditya Akella, Hongyi Zeng, NSDI, 2021
- Facebook used BGP for DC network routing
- tussle in software development: BGP already exist & has software
- BGP rich policy; familiar operator
- ⇒ fast startup
- no IGP bc OSPF does not scale
- emulate external BGP: each switch is 1 AS
- peer group: switch w/ same role, connected to same group
- use very similar BGP policy
- use AS confederation for ASN assignment
- group all ASN within each pod into 1 when advertise externally
- uniform ASN assignment across DC, reuse if possible
- avoid devastating buggy config via simulation & staged rollout
- each spine plane has unique ASN
- spine/fabric/rack switch: SSW/FSW/RSW
- infrastructure IP for switch, vs production IP for server
- aggregate route per rack/pod to minimize routing table
- reliability: pre-define backup paths using communities
- backup path never leaves pod bc route aggregation
- maintainability: take switch offline w/ soft drain: LIVE → WARM → DRAINED
- WARM: lower BGP pref.
- service availability: virtual IP (VIP), VIP advertise to rack switch, BGP anycast
- move instance w/o changing routing config
- avoid BGP convergence time
- minimize exploration scope to pod unless entire pod fail
- fast custom BGP impl: only needed feature
- multi-threaded coroutine peer-thread
- batch same-attribute import policy
- policy cache for export
- multi-stage testing: unit, simulation, canary, phased deployment
- BGP graceful restart: keep forwarding table
- 2-3 weeks to change fleet
Orion: Google’s Software-Defined Networking Control Plane
Andrew D. Ferguson, Steve Gribble, Chi-Yao Hong, Charles Killian, Waqar Mohsin, Henrik Muehe, Joon Ong, Leon Poutievski, Arjun Singh, Lorenzo Vicisano, Richard Alimi, Shawn Shuoshuo Chen, Mike Conley, Subhasree Mandal, Karthik Nagaraj, Kondapa Naidu Bollineni, Amr Sabaa, Shidong Zhang, Min Zhu, Amin Vahdat, NSDI, 2021
- SDN: app write to state, controller read state & adjust
- generalized forwarding: forwarding table++; match any header field, do any action
- Orion: break up routing, network management, config management into microservices
- blast radius: #device when controller failure
- inter-block controller (IBC) control controller in spine/aggregation block
- no fate sharing in SDN: dunno what failed when controller cannot reach switch
- Orion identify switch state: (un)health/unknown
- for unknown, initially fail-closed; if below capacity, fail-static
- out-of-band control plane except for ToR (in-band)
- out-of-band break circular dependency, but expensive
- intent reconciliation from apps w/ state from switches
- believe top-level authority on conflict
- packet-in: switch “punt” packet to core to ask for app intent
- punt: redirect packet to slower path
- packet-out: controller instruction for switch
- architecture: core → network information base (NIB) → managers → OpenFlow front-end (OFE)
- NIB: in-memory database & pub-sub broker of network state; non-durable
- state, entity, relationship
- topology manager & flow manager & config manager: microservice
- weird bc microservice usually don’t share memory
- NIB: in-memory database & pub-sub broker of network state; non-durable
- eventual consistency; periodic reconciliation of state
- hand shake not scale & need memory
- routing engine (RE): compute path from route & install path
- topology abstraction: reduce part of topology to single node
- handle within supernode
- routing engine write flow → NIB pub → flow manager → OFE
- route sequencing to avoid dropping current packets
- reverse path order
- only doable bc SDN has global view
- topology abstraction: reduce part of topology to single node
- common library for app dev: NIB access, health monitoring, replication & leader election
- NIB failure: core start new instance, reconcile state from switch, get intent from config manager, reconcile intent w/ state
- capability readiness: abstraction of various NIB states to barrier apps
- ToR in-band control (→50%) bc cost, else out-of-band for reliability
- integrate BGP for 2 WAN: B4 (data center) & B2 (public)
- routing app abstract BGP into 1 node; switch dumb only run OpenFlow
- (control) domain decomposition
- physical domain vs virtual domain
- IBR-C virtual controller abstract spine/aggregation block as single node
- inter-block routing central (IBR-C)
- subscribe to NIB in spine&aggregation block
- switch/link failure: rm from forwarding table (fast), RE recompute path (slow)
- failure between blocks: IBR-C recompute WCMP path
Teal: Learning-Accelerated Optimization of WAN Traffic Engineering
Zhiying Xu, Francis Y. Yan, Rachee Singh, Justin T. Chiu, Alexander M. Rush, Minlan Yu, SIGCOMM, 2023
- want to distribute demand traffic among WAN optimally
- start w/ 4-8 path between each pair
- use GNN + RL to approximate bc inference fast
- FlowGNN: topology + demand
- GNN node per edge pair & full path
- GNN layer for capacity & demand constraint
- train embedding for demand regardless of network size
- multi-agent RL learn traffic split
- each demand as RL agent
- ADMM adjust infeasible solution from model
- fixed topology, learn using known traffic matrices
RedTE: Mitigating Subsecond Traffic Bursts with Real-time and Distributed Traffic Engineering
Fei Gui, Songtao Wang, Dan Li, Li Chen, Kaihui Gao, Congcong Min, Yi Wang, SIGCOMM, 2024
- centralized TE not handle burst within 5min
- put ML model on each router to respond to burst immediately
- model distinct for each router, trained in RL in same topology
- w/ real historical data
B4 and after: managing hierarchy, partitioning, and asymmetry for availability and scale in google’s software-defined WAN
Chi-Yao Hong, Subhasree Mandal, Mohammad Al-Fares, Min Zhu, Richard Alimi, Kondapa Naidu B., Chandan Bhagat, Sourabh Jain, Jay Kaimal, Shiyu Liang, Kirill Mendelev, Steve Padgett, Faro Rabe, Saikat Ray, Malveeka Tewari, Matt Tierney, Monika Zahn, Jonathan Zolla, Joon Ong, Amin Vahdat, SIGCOMM, 2018
- ISP performance & availability insufficient for cloud for WAN
- ISP WAN low utilization for failure headroom: 30-40%
- scale back high-volume but elastic traffic Google control
- WAN router: 2-stage Clos from 128x10G merchant silicon
- hierarchical SDN
- site: 4 OpenFlow Agent (OFA) switch, at campus edge, connect to cluster & other site
- OFCs run Paxos failover
- started WAN w/ BGP/IS-IS (Quagga/RAP); as fallback
- iBGP/IS-IS w/ other sites; eBGP w/ cluster
- SDN control BGP by taking BGP update into RIB & sending update to switch
- flow group for same-priority app between 2 site
- allocate much demand for each flow group as possible
- tunnel group to group flow group w/ predetermined path
- bandwidth enforcer (BwE) collect demand & enforce rate limit by flow group
- SDN gateway collect failure & build topology & send to TE
- bandwidth proportional to apps’ assigned
weight(fair share)- ⇒ bandwidth function (complex fairness)
- changes bc 100x growth & larger network
- added availability requirement: service-level objective (SLO)
- service class vary from search (highest) to bulk transfer (lowest)
- increase WAN bandwidth by adding B4 site make TE expensive
- slow TE cause lower availability bc longer time to address link failure
- change to Stargate Site design w/ up to 4 supernode
- by replacing switch w/ more links
- 2-stage Clos, 32x40G chip
- rid campus layer, direct site to clusters
- TE treat multiple links between site as single ⇒ cannot handle asymmetric link capacity
- use side link to allow links w/ different capacity
- still have incoming traffic evenly distributed to supernodes
- assume supernodes within site balance outgoing traffic
- incoming capacity need to be even split for TE
- hierarchical TE: site-level supernode-level
- non-hierarchical TE doesn’t scale, ~200x slower
- hash-based load balancing harder
- tunnel split group (TSG) at supernode to split traffic per TG
- generate TSG & prove is DAG; sequence to avoid drop
- switch split group (SSG) program switches within supernode
- ACL table use TCAM to match flow; expensive&small
- longest prefix match (LPM) table use SRAM; large
- exploit ECMP table for WCMP cause space explosion
- TG from QoS label + prefix
- save memory: first match QoS to VRF (LPM), then use different VRF for prefix
Achieving high utilization with software-driven WAN
Chi-Yao Hong, Srikanth Kandula, Ratul Mahajan, Ming Zhang, Vijay Gill, Mohan Nanduri, Roger Wattenhofer, SIGCOMM, 2013
- WAN utilization⤴ thru reducing peak demand by exploiting latency-tolerance
- label-switching: forward based on MPLS header between layer 2&3
- label-switching router (LSR); may rewrite label
- ISP did MPLS-TE, greedy label-switched path (LSP) assignment + capacity discovery ⇒ suboptimal&unfair
- SWAN want prioritization + fairness within class
- congestion-free ordering for route change
- need scratch capacity for gradually shifting traffic over
- host track demand between service & DC, do rate limiting
- broker receive&aggregate demand, tell controller → host rate limiting
- network agents: topology state → controller
- controller compute allocation to service & change forwarding table
- given pairwise demand, tunnel, link capacity, output fractions of flow over each tunnel
- max-min fairness priority by priority
- multi-commodity flow (MCF): maximize allocation subject to demand&capacity constraint
- leave scratch capacity for update
- approx. max-min fair for each bucket
- allocate rate within of fair; larger ⇒ less fair, faster
- try allocating in exponential sizes iteratively
- save table space: greedily select max-traffic tunnel till table full
- rerun optimization w/ fixed selected tunnel
- in-place traffic update: need congestion-free intermediate config
- use spare capacity , can do in step
- use scratch capacity to update tunnel set in step; tell service to send slow before start
EBB: Reliable and Evolvable Express Backbone Network in Meta
Marek Denis, Yuanjun Yao, Ashley Hatch, Qin Zhang, Chiun Lin Lim, Shuqiang Zhang, Kyle Sugrue, Henry Kwok, Mikel Jimenez Fernandez, Petr Lapukhov, Sandeep Hebbani, Gaya Nagarajan, Omar Baldonado, Lixin Gao, Ying Hang, SIGCOMM, 2023
OneWAN is better than two: Unifying a split WAN architecture
Umesh Krishnaswamy, Rachee Singh, Paul Mattes, Paul-Andre C Bissonnette, Nikolaj Bjørner, Zahira Nasrin, Sonal Kothari, Prabhakar Reddy, John Abeln, Srikanth Kandula, Himanshu Raj, Luis Irun-Briz, Jamie Gaudette, Erica Lan, NSDI, 2023
Data center TCP (DCTCP)
Mohammad Alizadeh, Albert Greenberg, David A. Maltz, Jitendra Padhye, Parveen Patel, Balaji Prabhakar, Sudipta Sengupta, Murari Sridharan, SIGCOMM, 2010
- problem: cloud service latency-sensitive partition-aggregate pattern incast burst
- switch are shallow-buffered & shared for all port bc cost
- large flow kick out small packet on switch
- retransmission timeout (RTO) default min 1s was huge
- old workaround: jitter: worker randomly delay before respond; insufficient, waste time
- reduce congestion window (cwnd) per extent of congestion: #packets w/ ECN bit
- hard to estimate queue size by bc RTT small
- mark CE bit when instantaneous queue size > some K
- much simpler than RED
- override delayed ACK w/ immediate ACK when CE go from 0 to 1 or CE switch to 1
- receiver echo CE bit till sender ack
- delay is usually
- “immediate” transmission have old ECN bit state bc receiver use ACK sequence to infer state transition
- reduce cwnd by where where is fraction of marked packet in window and g is “gain”
- DCTCP keep queue small so no lost response
- model to estimate and w/ synchronized sender w/ same cwnd thru shared bottleneck
- need
- DCTCP can maintain throughput compared to TCP w/ much smaller queue
- DCTCP prevent query delay increase & timeout on incast
Swift: Delay is Simple and Effective for Congestion Control in the Datacenter
Gautam Kumar, Nandita Dukkipati, Keon Jang, Hassan M. G. Wassel, Xian Wu, Behnam Montazeri, Yaogong Wang, Kevin Springborn, Christopher Alfeld, Michael Ryan, David Wetherall, Amin Vahdat
- aim: low tail latency
- disaggregation of disk etc. mandate network capability
- also handle endpoint congestion
- need low CPU usage
- Swift: different transport protocol than TCP
- async op stream e.g. read/write
- user level, not kernel
- kernel bypass: bake network stack into app, let it directly interface NIC
- delay-based congestion control: RTT increase signal more queuing; need to know accurate min RTT
- break RTT down to host + network
- AIMD to maintain E2E delay
- host congestion may be from receiver packet buffer
- delays: local NIC Tx, forward fabric, remote NIC Rx, remote NIC Tx, reverse fabric, local NIC Rx
- NIC timestamp packet w/ header at send/receive
- MD proportional to difference between delay and target delay at once per RTT
- AI by max(1,1/cwnd) if instantaneous RTT < target delay
- congestion windows: ecwnd for endpoint, fcwnd for fabric; take min
- endpoint delay is average, others are instantaneous
- router w/ little buffer can cause cwnd < 1
- handle cwnd < 1, send packet after RTT/cwnd delay
- almost every other protocol don’t handle cwnd < 1
- no pacing when cwnd > 1 to reduce CPU cost from timer
- target delay: propagation, transmission; depend on distance & #concurrent flow
- estimate fabric target delay by linear scaling per hop
- queue grow per sqrt of concurrent flows; scale target queue by
- selective ACK bc infrequent loss; per-packet coalesced non-delayed ACK
Demystifying NCCL: An In-depth Analysis of GPU Communication Protocols and Algorithms
Zhiyi Hu, Siyuan Shen, Tommaso Bonato, Sylvain Jeaugey, Cedell Alexander, Eric Spada, James Dinan, Jeff Hammond, Torsten Hoefler, arXiv, 2025
- collective communication, e.g. reliable broadcast
- scatter: shard data 1 to all other
- gather: collect shard from all to 1
- all reduce: reduce then broadcast; reduce scatter
- Nvidia Collective Communication Library (NCCL)
- NCl abstract communication into high-level API; auto choose transport protocol
- simple vs low latency vs low latency and high bandwidth transport protocol
- logical topology for transport e.g. ring/tree
Crux: GPU-Efficient Communication Scheduling for Deep Learning Training
Jiamin Cao, Yu Guan, Kun Qian, Jiaqi Gao, Wencong Xiao, Jianbo Dong, Binzhang Fu, Dennis Cai, Ennan Zhai, SIGCOMM, 2024
- consider either first party or third party GPU training job
- contention on either network or intra-host link
- GPU intensity, computation by max transmission time on any 1 link per job
- greedily assign high priority job first
- adjust priority based on communication-computation pattern of jobs
Network Virtualization in Multi-tenant Datacenters
Teemu Koponen, Keith Amidon, Peter Balland, Martin Casado, Anupam Chanda, Bryan Fulton, Igor Ganichev, Jesse Gross, Paul Ingram, Ethan Jackson, Andrew Lambeth, Romain Lenglet, Shih-Hao Li, Amar Padmanabhan, Justin Pettit, Ben Pfaff, Rajiv Ramanathan, Scott Shenker, Alan Shieh, Jeremy Stribling, Pankaj Thakkar, Dan Wendlandt, Alexander Yip, Ronghua Zhang, NSDI, 2014
- overlay virtual network can have link not physically existing
- end-host virtualization: use host to do it; physical network do not know
- overlay; more packet header
- in-network virtualization: switch know virtual network thru flow tables w/ tag in header
- usually do end-host virtualization
Andromeda: Performance, Isolation, and Velocity at Scale in Cloud Network Virtualization
Michael Dalton, David Schultz, Jacob Adriaens, Ahsan Arefin, Anshuman Gupta, Brian Fahs, Dima Rubinstein, Enrique Cauich Zermeno, Erik Rubow, James Alexander Docauer, Jesse Alpert, Jing Ai, Jon Olson, Kevin DeCabooter, Marc de Kruijf, Nan Hua, Nathan Lewis, Nikhil Kasinadhuni, Riccardo Crepaldi, Srinivas Krishnan, Subbaiah Venkata, Yossi Richter, Uday Naik, Amin Vahdat, NSDI, 2018
- on Google Cloud
- need to sclae to 100k VM per customer
- fabric manager API take customer config → Open vSwitch host management plane
- fast path vs co-processor which do additional processing
- hoverboard offload inactive flow
- entity-relationship model to store network config
- OFE program OVS, which change VM config
Achelous: Enabling Programmability, Elasticity, and Reliability in Hyperscale Cloud Networks
Chengkun Wei, Xing Li, Ye Yang, Xiaochong Jiang, Tianyu Xu, Bowen Yang, Taotao Wu, Chao Xu, Yilong Lv, Haifeng Gao, Zhentao Zhang, Zikang Chen, Zeke Wang, Zihui Zhang, Shunmin Zhu, Wenzhi Chen, SIGCOMM, 2023
(under here?)
- compute forward state from client config → nlog
- nlog based on Datalog logic programming language
- Datalog statement: head, clause, where head true if all clauses true
- allow incremental evaluation for e.g. VM migration only change specific tunnel
- hierarchical controller: AIP, logical, physical, OpenFlow & OVS
- parallel control w/ sharding
- master & standby controller per shard
Triton: A Flexible Hardware Offloading Architecture for Accelerating Apsara vSwitch in Alibaba Cloud
Xing Li, Xiaochong Jiang, Ye Yang, Lilong Chen, Yi Wang, Chao Wang, Chao Xu, Yilong Lv, Bowen Yang, Taotao Wu, Haifeng Gao, Zikang Chen, Yisong Qiao, Hongwei Ding, Yijian Dong, Hang Yang, Jianming Song, Jianyuan Lu, Pengyu Zhang, Chengkun Wei, Zihui Zhang, Wenzhi Chen, Qinming He, Shunmin Zhu, SIGCOMM, 2024
Azure Accelerated Networking: SmartNICs in the Public Cloud
Daniel Firestone, Andrew Putnam, Sambhrama Mundkur, Derek Chiou, Alireza Dabagh, Mike Andrewartha, Hari Angepat, Vivek Bhanu, Adrian Caulfield, Eric Chung, Harish Kumar Chandrappa, Somesh Chaturmohta, Matt Humphrey, Jack Lavier, Norman Lam, Fengfen Liu, Kalin Ovtcharov, Jitu Padhye, Gautham Popuri, Shachar Raindel, Tejas Sapre, Mark Shaw, Gabriel Silva, Madhan Sivakumar, Nisheeth Srivastava, Anshuman Verma, Qasim Zuhair, Deepak Bansal, Doug Burger, Kushagra Vaid, David A. Maltz, Albert Greenberg, NSDI, 2018
1RMA: Re-envisioning Remote Memory Access for Multi-tenant Datacenters
Arjun Singhvi, Aditya Akella, Dan Gibson, Thomas F. Wenisch, Monica Wong-Chan, Sean Clark, Milo M. K. Martin, Moray McLaren, Prashant Chandra, Rob Cauble, Hassan M. G. Wassel, Behnam Montazeri, Simon L. Sabato, Joel Scherpelz, Amin Vahdat, SIGCOMM, 2020
Empowering Azure Storage with RDMA
Wei Bai, Shanim Sainul Abdeen, Ankit Agrawal, Krishan Kumar Attre, Paramvir Bahl, Ameya Bhagat, Gowri Bhaskara, Tanya Brokhman, Lei Cao, Ahmad Cheema, Rebecca Chow, Jeff Cohen, Mahmoud Elhaddad, Vivek Ette, Igal Figlin, Daniel Firestone, Mathew George, Ilya German, Lakhmeet Ghai, Eric Green, Albert Greenberg, Manish Gupta, Randy Haagens, Matthew Hendel, Ridwan Howlader, Neetha John, Julia Johnstone, Tom Jolly, Greg Kramer, David Kruse, Ankit Kumar, Erica Lan, Ivan Lee, Avi Levy, Marina Lipshteyn, Xin Liu, Chen Liu, Guohan Lu, Yuemin Lu, Xiakun Lu, Vadim Makhervaks, Ulad Malashanka, David A. Maltz, Ilias Marinos, Rohan Mehta, Sharda Murthi, Anup Namdhari, Aaron Ogus, Jitendra Padhye, Madhav Pandya, Douglas Phillips, Adrian Power, Suraj Puri, Shachar Raindel, Jordan Rhee, Anthony Russo, Maneesh Sah, Ali Sheriff, Chris Sparacino, Ashutosh Srivastava, Weixiang Sun, Nick Swanson, Fuhou Tian, Lukasz Tomczyk, Vamsi Vadlamuri, Alec Wolman, Ying Xie, Joyce Yom, Lihua Yuan, Yanzhao Zhang, Brian Zill, NSDI, 2023
Harmonic: Hardware-assisted RDMA Performance Isolation for Public Clouds
Jiaqi Lou, Xinhao Kong, Jinghan Huang, Wei Bai, Nam Sung Kim, Danyang Zhuo, NSDI, 2024
Maglev: A Fast and Reliable Software Network Load Balancer
Danielle E. Eisenbud, Cheng Yi, Carlo Contavalli, Cody Smith, Roman Kononov, Eric Mann-Hielscher, Ardas Cilingiroglu, Bin Cheyney, Wentao Shang, Jinnah Dylan Hosein, NSDI, 2016
Ananta: cloud scale load balancing
Parveen Patel, Deepak Bansal, Lihua Yuan, Ashwin Murthy, Albert Greenberg, David A. Maltz, Randy Kern, Hemant Kumar, Marios Zikos, Hongyu Wu, Changhoon Kim, Naveen Karri, SIGCOMM, 2013
Network Load Balancing with In-network Reordering Support for RDMA
Cha Hwan Song, Xin Zhe Khooi, Raj Joshi, Inho Choi, Jialin Li, Mun Choon Chan, SIGCOMM, 2023
End-User Mapping: Next Generation Request Routing for Content Delivery
Fangfei Chen, Ramesh K. Sitaraman, Marcelo Torres, SIGCOMM, 2015
Analyzing the Performance of an Anycast CDN
Matt Calder, Ashley Flavel, Ethan Katz-Bassett, Ratul Mahajan, Jitendra Padhye, IMC, 2015
Taking the Edge off with Espresso: Scale, Reliability and Programmability for Global Internet Peering
Kok-Kiong Yap, Murtaza Motiwala, Jeremy Rahe, Steve Padgett, Matthew Holliman, Gary Baldus, Marcus Hines, Taeeun Kim, Ashok Narayanan, Ankur Jain, Victor Lin, Colin Rice, Brian Rogan, Arjun Singh, Bert Tanaka, Manish Verma, Puneet Sood, Mukarram Tariq, Matt Tierney, Dzevad Trumic, Vytautas Valancius, Calvin Ying, Mahesh Kallahalla, Bikash Koley, Amin Vahdat, SIGCOMM, 2017
Last edited:
Probability, Random Variables, and Stochastic Processes
joint distribution: discrete
uniform distribution
independent uniform variables
has uniform joint distribution use areas to find probability, always geometric method first
joint distribution: continuous
conditional probability: discrete
probability model
rule of average conditional probability
conditional expectation: discrete
for random variable and event
properties
- linearity property
- average conditional expectation
- rule of average conditional expectation
aka the formula for by conditioning on
- conditional expectation of given
is a function of
- to find a function, find its value first and replace the parameter with variable
conditioning: continuous case
if
probability over a region
infinitesimal conditioning formula
fall in small interval near
conditional density of given
joint density surface
marginal density of
multiplication rule for density
averaging conditional probability
integral conditioning formula
conditional expectation
conditional variance
! another way to calculate variance
! for i.i.d. with number independent to
Bayesian estimation
take the wanted parameter as a random variable with distribution prior distribution take a sample and use it to update the posterior distribution
general case
want in let with observations (measurements) know conditional distribution posterior distribution i.e. posterior = likelihood prior evidence
- it does not matter if the observation points are used one by one or all at once
conjugate prior
the posterior distribution is of the same type as the prior distribution
- normal + normal = normal
- binomial + Beta = Beta
indicator
maximum a posteriori probability (MAP) rule
select so that posterior probability is maximized maximize
point estimation
select point estimate to represent best guess of
estimator
- maximum a posteriori probability (MAP) estimator
- conditional expectation estimator a.k.a. least mean squares (LMS) estimator
least mean squares (LMS) estimation
select an estimator/function with least squared error
base case
for , want such that is minimized choose
general case
with observations , want to minimized choose
linear least mean squares estimation
the linear form of LMS
hypothesis testing
denote as event
MAP rule for hypothesis testing
choose iff it has a larger posterior or equivalently
general case—two coins
coin 1 gets head by , coin 2 by toss an unknown coin, coin , times and get heads choose iff
- critical choose iff
- probability of getting error
property
discrete Markov chain
- the Markov property the past does not matter for the future, only the present does
- discrete time
- state space finite or countably infinite
one-step probability
does not change
transition probability matrix
initial distribution
-step transition matrix
class structure
site leads to , i.e. and are in the same class
closed class
can not go to another class
class is closed,
absorbing state
transient & recurrent
hitting time
let , hitting time of , :
transient and recurrent state
site is recurrent if
- always can get from to in finite steps
transient if
number of times pass
- iff
theorem
- let be a transient state, then and which means
- let be a recurrent state, then and and
result
is finite at least recurrent state
is recurrent, recurrent, the same closed class
you always get absorbed in a closed class of recurrent states after moving around
starting from , the probability to go in class
- if , then
- if another closed class, then
- if is transient, then
starting from , the expected steps to be absorbed
stationary distribution
let be a Markov chain with state space a distribution on is said to be stationary if the distribution stay the same initial distribution , the distribution after infinite steps: the distribution will be independent on
find stationary distribution
build linear system with
null recurrent and positive recurrent
period of a state
GCD of all such that
states in the same class have the same period
a chain is irreducible if is a closed class
if every state of a Markov chain has period we say the chain is aperiodic
suppose a Markov chain is irreducible and aperiodic and has a stationary distribution
suppose a Markov chain is irreducible and all states are recurrent
- average number of visits to
- mean return time to
suppose a Markov chain is irreducible and has a stationary distribution
the stationary distribution is unique
and
Stochastic process
branching process
consider a population of individual:
- in every generation, , each individual produce a random number of offspring in the next generation , i.i.d. with the other individual. denote the number of individual in the -th generation
question of interest
generating function
fixed point of
- analysis: study
if , then if , then if , then
birth and death process
gambler’s ruin
with , find
- when
irreducible and stationary distribution
because is non-decreasing
a birth and death chain is recurrent iff
if transient if recurrent stationary distribution exists iff positive recurrent
else, null recurrent
random walk
random walk on finite graph
- number of vertex
- adjacent— is adjacent to iff there is one edge connecting them
- degree of a vertex —the number of edges incident to
- uniform—the distribution of where to go is uniform, meaning that the probability of going to any adjacent vertex is the same
- stationary distribution
where
random walk on positive integer
birth and death process
- reflective barrier
- recurrent iff
- stationary distribution iff recurrent
random walk on integer
consist of all points in with integer coordinate
Stirling’s formula
when is large
random walk on
- limit comparison test to check convergence
continuous Markov chain
- continuous time
- finite or countably infinite
time-homogenous— does nothing
Chapman–Kolmogorov Equations
holding time at state
the time staying at state before changing
- absorbing state , never move
- explosive , never stay
- general
proof
prove the holding time is memory-less
embedded discrete Markov chain
consisting of the state the continuous Markov chain visit
another representation of
before jumping from to , holding time go to the earliest state
- transition matrix for the embedded Markov chain
derivative at
- Kolmogorov backward equation
- Kolmogorov forward equation
- infinitesimal generator —transition matrix for the Markov chain itself
recover using
- system of differential equation using the Kolmogorov equation (either forward or backward)
matrix exponential
square matrix
- or differential equation of matrix
for the eigenvalues
long time behavior of continuous Markov chain
stationary distribution
- definition with
- finding the stationary distribution
- is a limiting distribution if recurrent and finite closed class
relationship with stationary distribution of embedded chain
let
irreducible
irreducible if , then
fundamental theorem
if the chain is finite or positive recurrent, if the chain is irreducible and is positive recurrent, then unique stationary distribution and limiting distribution
continuous birth and death process
pure birth
recurrence
Poisson process
continuous time Stochastic process with parameter (rate) , and
- has independent increment
where
inter arrival time
the time between the occurrence of the th event and the th
arrival time
the time of the occurrence of the th event
alternative definition using exponential distribution
sum of i.i.d.
combine independent Poisson process
is Poisson process with
splitting Poisson process
with every occurrence go to with probability and go to with probability , then is Poisson process with , is Poisson process with , the distribution between them is binomial
occurrence time spot
many occurrence time spot
let be i.i.d. let denote them in ascending order
proof
let be occurrence time for given
definition of
is if
alternative definition
- has independent increment
proof
- take the derivative of
- prove are exponential by induction
- prove are gamma using
property of Stochastic process
for Stochastic process
- mean function
- covariance function (auto-covariance function)
all the property of covariance apply to covariance function
second order stationary process
Gaussian process
Stochastic process
multivariate normal distribution
random variable
- joint density function is determined by
- covariance matrix
- covariance and independence normal random variable and independence
Brownian motion
standard Brownian motion
continuous time Stochastic process
- Stationary increment
- independent increment
- function is continuous
covariance function
connection between Brownian motion and discrete random walk
sum of random walk is discrete, but is continuous, can approximate Brownian motion after scaling and limiting using
relation between Gaussian process and Brownian motion
standard Brownian motion Gaussian process that
- continuous path function is continuous
transformation of Brownian motion
standard Brownian motion the following are standard Brownian motion
- reflection
- new start
- scaling
- Gaussian
hitting time
first time reaching
- usage
some distributions
Beta random variables
Beta function
exponential random variable
memory-less property
sum of i.i.d. exponential distribution is gamma distribution
proved by induction
comparison between and
comparison between with parameter
minimum of exponential distribution with ’s
Gamma distribution
Poisson distribution
bivariate normal distribution
joint density
marginals
conditionals
Last edited:
Probability and Statistics
⌊x⌋= the greatest integer smaller than x
sequence
index variable
explicit formulas
recurrence relation
arithmetic sequences
geometric sequences
bounded above/ below
(un)bounded
convergent ⇒ bounded
bounded, monotone ⇒ convergent
series
convergent vs divergent series
harmonic sum
p series:
convergent ⇒ limn → ∞an = 0
limn → ∞an ≠ 0⇒ divergent
tests
divergence test
partial sum
geometric: |q| < 1
integral: f, f(n) = an, continuous, ultimately decreasing 🡪 same
comparison:
scaling with or
alternating: |an + 1| − |an| < 0, ∀ n > n0, limn → ∞an = 0⇒ convergent
absolute convergence: convergent
conditional convergence: convergent, but divergent
convergent convergent
ratio:
root:
uniform convergence:
fn(x) converge to f(x): fn(x) → f(x) as n → ∞
∃N(ε) independent to x, ∀n > N, |fn(x) − f(x)| < ε⇔ uniform convergence: fn ⇉ f
dominated convergence: fi(x) → f(x) as x → ∞, ∃g, ∀x, i, fi(x) < g(x) ⇒ limi → ∞∫abfi(x)d**x = ∫abf(x)d**x
power series:
center a, coefficient cn
⇒ x = a⇔ convergent
or ∀x ∈ ℝ, convergent
or ∃R > 0, |x − a| < R⇒ convergent, |x − a| > R⇒ divergent
method: , radius of convergence
|x − a| < R⇒ absolutely convergent, |x − a| > R⇒ divergent from ratio test
Bessel function of the first kind:
basic formula:
plug out terms, create (x − a), see something as 1 − x, do it, range
Taylor and Maclaurin Series:
for |x| < 1
for |x| < 1
differentiation and integration: ,
may lose boundary of convergence
Cauchy product: ,
probability
sample space S: nonempty set
collection of events: subset of S: P(S)
probability measure P(A) ∈ [0, 1], P(⌀) = 0, P(S) = 1
if Ai… are mutually disjoint
symmetric difference: AΔB = (A ∖ B) ∪ (B ∖ A)
complement: Ac : = S ∖ A
disjoint: A ∩ B = ⌀ ⇔ A ⊆ Bc ⇒ A ∖ B = A ∩ Bc
De Morgan Laws: (A ∪ B)c = Ac ∩ Bc, (A ∩ B)c = Ac ∪ Bc
A = B ⇔ A ⊆ B, B ⊆ A
cardinality: |A|= # of elements in A
inclusion-exclusion principle: |A ∪ B| = |A| + |B| − |A ∩ B|, |A ∪ B ∪ C| = |A| + |B| + |C| − |A ∩ B| − |A ∩ C| − |B ∩ C| + |A ∩ B ∩ C|
partition of the sample: Bi, disjoint, S = B1 ∪ B2 ∪ …
P(A) = P(A ∩ B1) + P(A ∩ B2) + …
P(A ∖ B) = P(A ∩ Bc) = P(A) − P(B)
not necessarily disjoint: P(A1 ∩ A2 ∩ …) ≤ P(A1) + P(A2) + …
independent: P(A ∩ B) = P(A)P(B) for two events, and P(A1 ∩ … ∩ Ai) = P(A1)…P(Ai) for more events
uniform probability:
continuous uniform distribution: , [x, y] ⊂ [a, b]
combinatorics: length k, n symbols ⇒ nk
ordered subset
binomial:
generating function:
exponential generating function:
Bayes’ theorem:
random variable X(bla) = 2
discrete:
PDF probability mass/ density function: pX(x) = P(X = x)
law of total probability:
Bernoulli: pX(0) = q, pX(1) = p
Binomial:
rX(t) = (t**p + q)n
geometric: pX(k) = p**qk
negative-binomial:
Poisson:
E(X) = var(X) = λ
hypergeometric:
continuous distribution: pX(k) = 0 ∀ x ∈ ℝ,∫−∞∞f(x)d**x = 1
uniform:
exponential:
P(x ≥ t) = e−λ**t
normal:
gamma:
Γ(x + 1) = x**Γ(x)
chi-squared: Χ2(n) is the distribution of Z = X12 + … + Xn2 with Xi ∼ N(0, 1)
E(Z) = n
for z ≥ 0 if n = 1
t (or student): t(n) is the distribution of with Xi ∼ N(0, 1)
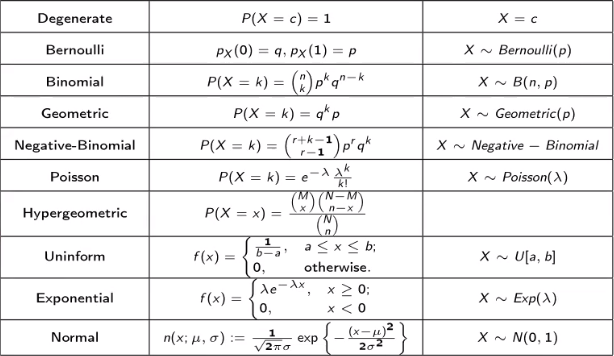
CDF cumulative distribution fun
joint distributions Y = h(X)
if X discrete, then
if X continuous, h(x) monotone where fX(x) > 0, then
marginal distribution: FX(x) = limy → ∞FX, Y(x, y)
joint probability fun
marginal PDF: table
joint density fun: f(x, y), ∫−∞∞∫−∞∞f(x, y)dxd**y = 1
marginal PDF fX(x) = ∫−∞∞fX, Y(x, y)d**y
independent
or f
continuous:
law of total prob: P((X, Y) ∈ B) = ∬BfX(x)fY|X(y|x)dxd**y
independent random variables: ∀B1, B2, P(X ∈ B1, Y ∈ B2) = P(X ∈ B1)P(Y ∈ B2)
expectation: E(X**Y) = E(X)E(Y) if X, Y independent
variance: var(X) = E((X − μx)2) = E(X2) − E2(X), var(X + Y) = var(X) + var(Y) + 2cov(X, Y)
covariance: cov(X, Y) = E((X − μX)(Y − μY)) = E(X**Y) − E(X)E(Y)
cov(a**X + b**Y, Z) = a cov(X, Z) + b cov(Y, Z)
correlation:
i.i.d. mutually independent and identically distributed
X1, …, Xn ∼ Bernoulli(p) i. i. d. ⇒ X1 + … + Xn ∼ B(n, p)
X1 ∼ B(n1, p), X2 ∼ B(n2, p) ⇒ X1 + X2 ∼ B(n1 + n2, p)
X1 ∼ Poisson(λ1), X2 ∼ Poisson(λ2) ⇒ X1 + X2 ∼ Poisson(λ1 + λ2)
generating fun: rX(t) = E(tX)
rX + Y(t) = rX(t)rY(t)
kth moment: E(Xk)
kth central moment: E((X − μx)k)
moment-generating fun:
MX(k)(0) = E(Xk)
MX + Y(s) = MX(s)MY(s) X, Y independent, work for rX(t)
uniqueness: if ∃s0 > 0, MX(s) < ∞ ∀s ∈ (−s0, s0), MX(s) = MY(s), then X, Y have the same distribution also work for r
characteristic fun: cX(s)= E(eiXs)
inequalities
Markov’s: X ≥ 0, a > 0
Chebychev’s: a > 0
Cauchy-Schwarz:
=, iff if var(Y) > 0
law of large number
sample sum: Sn = X1 + … + Xn for {Xi} i. i. d.
sample average:
WLLN weak: limn → ∞P(|Mn − μ| ≥ ε) = 0 for {Xi} same μ, var ≤ v, v < ∞, ε > 0 not necessarily i. i. d.
SLLN strong: P{limn → ∞Mn = μ} = 1 for {Xi} i. i. d.
x
central limit theorem: limn → ∞P(Zn ≤ x) = P(Z ≤ x) for {Xi} i. i. d, Z ∼ N(0, 1),
convolution: for X, Y independent, Z = X + Y
discrete:
continuous: fZ(z) = ∫−∞∞fX(z − w)fY(w)d**w
different convergence
: {Xn} converges in probability to Y, if limn → ∞P(|Xn − Y| ≥ ε) = 0
: {Xn} converges with probability 1 (almost surely) to Y, if limn → ∞P(Xn = Y) = 1
: {Xn} converges in distribution to Y, if limn → ∞P(Xn ≤ x) = P(Y ≤ x) ∀ x ∈ {x|P(Y = x) = 0}
sample
sample variance:
kth sample moment:
point estimation
the method of moments:
MLE maximum likelihood estimation: make L big as possible
maximum likelihood fun: L(θ; x1, …, xn) = p(X1 = x1, …Xn = xn|θ) or f
x1, …, xn independent:
good point estimator
unbiased: E(θ̂n) = θ
consistent:
mean squared error E((θ̂n − θ)2) is small
confidence interval: P(θ̂n− ≤ θ ≤ θ̂n+) ≥ 1 − α
⇐ P(a ≤ g(θ) ≤ b) ≥ 1 − α
N, t: let −b = a,
Χ2: let
deal with Xi ∼ N(μ, σ2)
μ = μ0:
hypothesis testing
null hypothesis H0
type I/ II error: H0 true/ false
level of significance α: probability for type I error
power of the test 1 − β, β: probability for type II error
p-value: probability that H0 is true
reject if p-value < α
for {Xi ∼ N(μ, σ02)} i.i.d., use
for two samples,
linear regression
linear least squares
correlation coefficient:
standard statistical model: Yj = β0 + β1xj + ej, j = 1, 2, …, n
E(ej) = 0, var(ej) = σ2
intercept β0, slope β1, residual ej
estimators
E(β̂0) = β0, E(β̂1) = β1
if ej ∼ N(0, σ2) i.i.d., then β̂0, β̂1 normal dist
sum of squared errors SSE:
independent of β̂0, β̂1
1 − α confidence interval for β̂0, β̂1
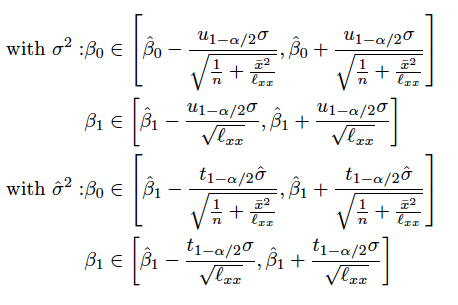
1 − α confidence interval for σ2
1 − α confidence interval for y0 = E(ŷ0):
Last edited:
Linear Algebra
linear system:
equivalent ∼—same solution set
consistent—have solution; inconsistent—no solutions
coefficient matrix:
augmented matrix:
row operation
replacement
interchange
scaling
row equivalent—same after proper row operation
⇒ equivalent matrix
entry—ai**j o**r ai, j o**r A[i, j]o**r Ai, j—the (i, j) entry of A
leading entry—leftmost entry of a nonzero row
(row) echelon form—step-like, leading entry going in to the right
echelon matrix
reduced echelon form—all leading entries are 1, entries below them are 0
an echelon form (REF) of…
the reduced echelon form (RREF) of…
only 1 for each matrix
pivot position—position corresponding to the leading entry of its reduced echelon form
pivot column—the column containing a pivot position
pivot—nonzero number in a pivot position
row reduction
forward phase—make pivots the leading entries
backward phase—eliminate non-pivots in pivot column
partial pivoting—use greatest entry in a column as the pivot for programming
solve linear system
basic variable—corresponding to pivot column
free variable—not so
solution set
element(s): 0—inconsisten**t o**r 1—consisten**t o**r ∞
parametric description—
back-substitution—solve for the basic variables one by one dealing with echelon form
existence and uniqueness theorem—consistent ⇔ no rightmost column as pivot column
vector equation— x1a1 + … + xnan = b
column vector
solution for vector equation x1a1 + … + xnan = b equivalent to solution of
Spa**n{v1,⋯, vp}—subset of ℝn spanned (/generated) by v1,⋯, vp—the set of all linear combinations of v1,⋯, vp
b ∈ spa**n{a1, ⋯, an} ⇔ A has a pivot in every row
matrix equation Ax = b:
Ax = b solution equivalent to x1a1 + … + xnan = b
existence of solutions—has solution iff b ∈ Spa**n{a1, ⋯, an}
{v1, ⋯, vp} spans (/ generates) ℝm if Spa**n{v1, ⋯, vp} = ℝm
identity matrix In,
Inx = x ∀ x ∈ ℝn
homogeneous linear system—can be writen as Ax = 0
opposite: heterogeneous
at least 1 solution x = 0, a.k.a. trivial solution
nontrivial solution iff ∃free variable
parametric vector form— x**=su** + tv (s, t ∈ ℝ) parametric vector equation of the plane
solution representation
vector
parameter vector form— x = p + tv (t ∈ ℝ) the equation of the line through p parallele to v
span
solution set of Ax = b— {w|w = p**+vh} i**f ∃solutio**n p ∀solutio**n o**f Ax** = 0 vh
linear dependency of matrix columns
a1⋯an of A are linearly independent ⇐ Ax = 0 has only the trivial solution
dependent ⇐ ∃ c1⋯cn, c1a1 + ⋯ + cnan = 0
more vectors than entries in each vector ⇒ linearly dependent
linearly dependent ⇔ at least one vector = linear combination of the others
⇒ ∃vj (j > i), vj is a linear combination of v1…vj − 1 if {v1…vp} is linearly dependent AND v1 ≠ 0
contains 0 ⇒ linearly dependent
linear transformation
transformation (/ function / mapping) T : ℝn → ℝm
domain ℝn
codomain ℝm
image T(x)
range: set of all images
matrix transformation x ↦ Ax
⇔ ∀ u**,** v, c, d, T(cu + dv) = c**T(u) + d**T(v)
kernal Nul A
range Col A
matrix operations
diagonal entry—ai**i
main diagonal
diagonal matrix—square matrix with all non-diagonal entries 0
zero metrix 0
vector multiplication
A(Bx)=(A**B)x
row-column rule—
*
A is right-multiplied by B, B is left-multiplied by A
A, B commute—A**B = B**A
power of matrix
A0 is the identity matrix
transpose matrix AT
(A**B)T = BTAT
matrix inversion
invertible—for n × n matrix A, ∃ n × n matrix C, C**A = In = A**C
C: an inverse of A
(non)singular matrix—(not) invertible
2 × 2 matrix iff det A = a**d − b**c ≠ 0
∀ invertible n × n matrix A, b ∈ ℝn, Ax = b ⇒ x**=**A−1b
(A**B)−1 = B−1A−1
(AT)−1 = (A−1)T
only product of invertible matrices is invertible
for n × n matrix: A is invertible
⇔ row equivalent to In
⇔ linear transformation x**↦Ax** is one-to-one
⇔ ∀ b**∈ℝn, Ax** = b has solution
⇔ linear transformation x**↦Ax** maps ℝn ***o***nto ℝn
⇔ ∃ n × n matrix C, C**A = I
⇔ ∃ n × n matri**x D, A**D = I
⇔ AT is invertible ⇔ det A ≠ 0
⇔ columns of A forms a basis of ℝn
⇔ Col A = ℝn
⇔ 0 is not an eigenvalue of A
⇔ det A ≠ 0
invertible linear transformation T : ℝn**↦ℝn—∃ S : ℝn↦**ℝn, ∀ x ∈ ℝn, S(T(x)) = x, T(S(x)) = x
S—the inverse T−1
elementary matrix—obtained by performing a single elementary row operation on identity matrix
roo**p A = E**A, where E = roo**p Im, roo**p is the single elementary row operation
elementary matrix E is invertible, E−1 is another elementary matrix obtained by reversed row operation
n × n matrix A is invertible iff row equivalent to In
A−1 = roo**p In if In = roo**p A
find A−1—row reduce and get
LU fractorization—A = L**U
A : m × n matrix
L : m × m unit lower triangular matrix
lower triangular matrix—entries above the main diagonal are 0s
U : m × n echelon matrix
implementation—
calculation: p. 145
determinant
A is quare matrix
usually use i = 1 the first row
origin—the last pivot in echelon form of the matrix obtained without division
Ai**j—obtained by deleting the ith row and jth column in A
(i, j)-cofactor Ci**j = (−1)i + jdet Ai**j
cofactor expansion across the ith row of A—
triangular matrix A— the entries on the main diagonal
row/ column operation
replacement—same
interchange—opposite
scaling—scales the same way
echelon form U by row replacements and r interchanges
det A = det AT
det A**B = (det A)(det B) proved using elementary matrices
if A is invertible
det k**A = kndet A if A has n rows
linearity property—linear transformation where only x is a variable
Cramer’s rule—the unique solution of Ax = b has entries
A is invertible n × n matrix, b ∈ ℝ
Laplace transfrom—converts system of linear differential equations to system of linear algebraic equations
a way to find A−1—A(A−1)j = (In)j
adjugate/ classical adjoint of A—
determinant as area or volume
area of parallelogram of 2 × 2 matrix A is |det A|
volume of parallelepiped of 3 × 3 matrix A is |det A|
linear transformation T : ℝ2 → ℝ2 (ℝ3 → ℝ3) determined by 2 × 2 (3 × 3) matrix A ⇒ {are**a (volum**e) o**f T(S)} = |det A| ⋅ {are**a (volum**e) o**f S}
vector space—10 axioms
subspace—3 axioms needed
0 ∈ H
H is closed under vector addition—u + v ∈ H
H is closed under multiplication by scalars—cu ∈ H
Spa**n{vi} is a subset of vector space V if vi ∈ V
null space of A, Nul A—solution set of Ax = 0
—is a subspace of ℝn
explicit discription—with the vectors that span Nul A
basis—solve and represent with free variables
dim Nul A= number of free variables
column space of A, Col A—Spa**n{a1, ⋯, an}
—is a subspace of ℝm
Col A = {b : b**=Ax**, x ∈ ℝn}
Col A = ℝm iff ∀b ∈ ℝm, ∃x, Ax = b
basis—pivot columns
dim Col A= number of pivot columns
row space of A,
—is a subspace of ℝn
= Col AT
basis—pivot rows
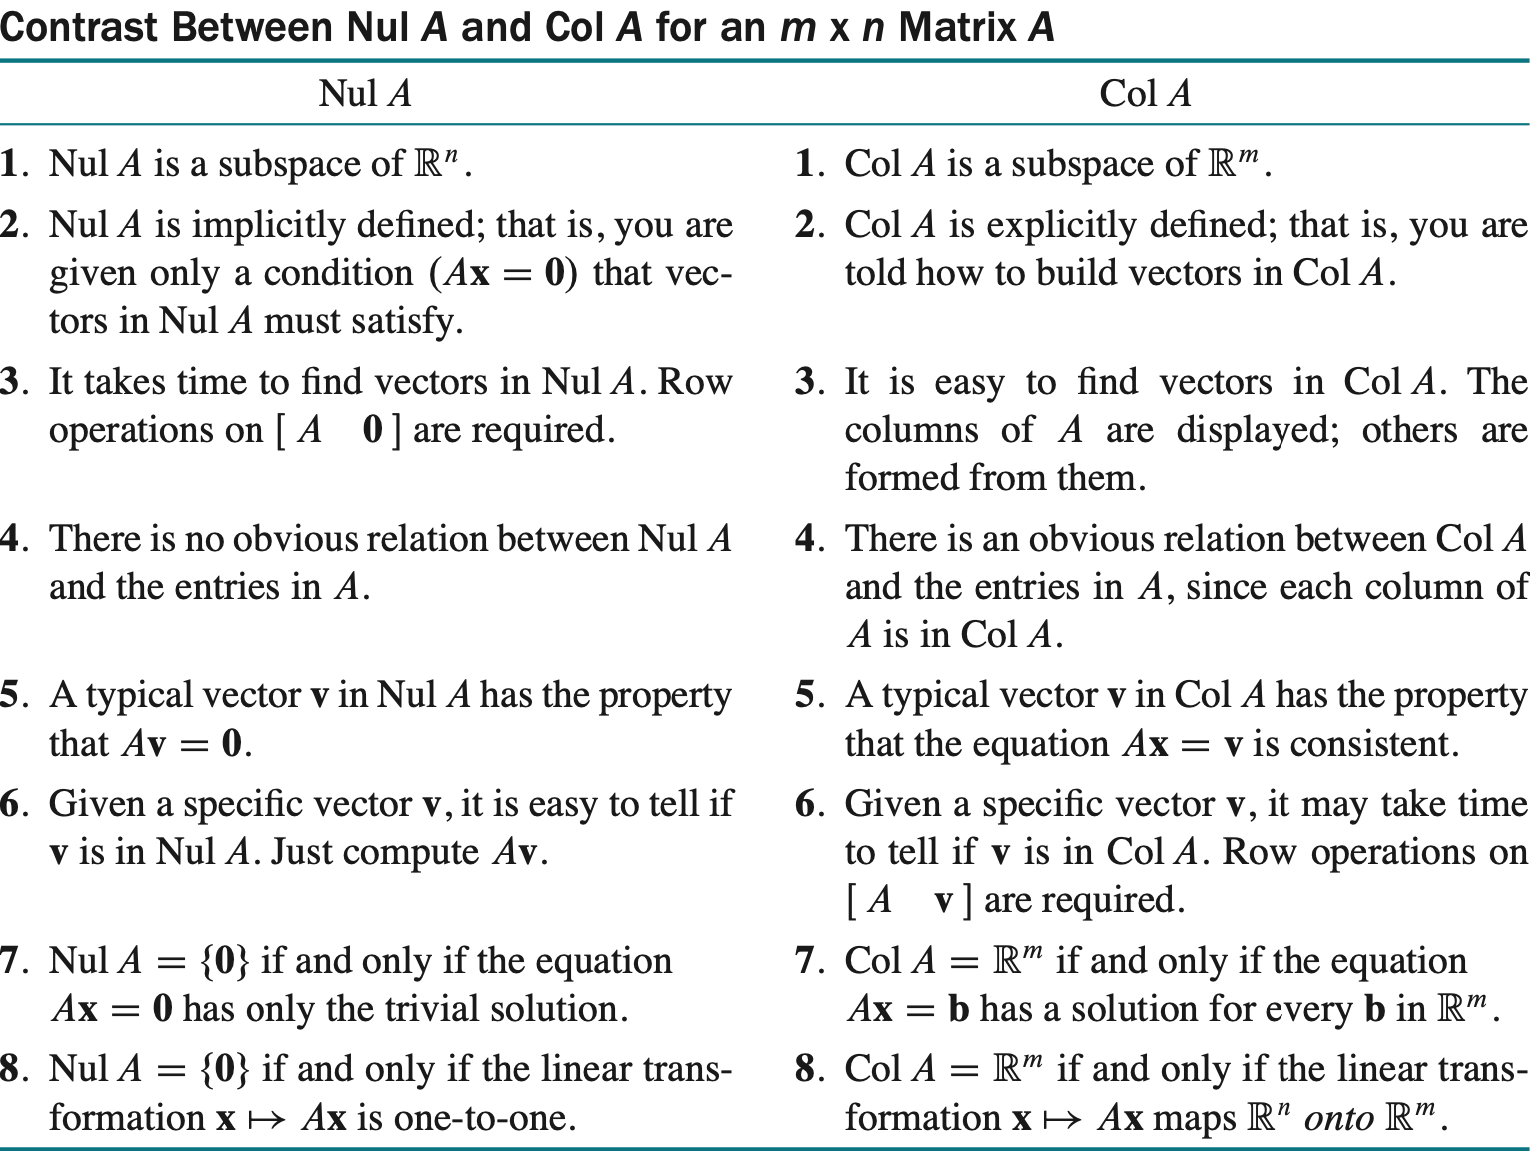
kernal/ null space of linear transformation T—T(u) = 0
basis Β of subset H—linearly independent, span H
standard basis for ℝn {e1, ⋯, en}
spanning set A small AP
linearly dependent set A big AP
coordinate system
the unique representation theorem
Β-coordinates of x—scalars that map them
Β-coordinate vector of x—
coordinate mapping x ↦ [x]Β
it is a one-to-one linear transformation—isomorphism
x = PΒ[x]Β, where change of coordinate matrix PΒ = [b1, ⋯, bn]
dimension
finite-dimensional vector space—spanned by finite set
0 dimension—{0}
infinite-dimensional
dim ℙn = n + 1
rank—dim Col A
rank thm—ran**k A + dim Nul A = n
an eigenvector corresponding to λ—x ≠ 0, Ax = λx, A i**s n × n
an eigenvalue of A—λ
main diagonal entries on triangular matrix
0 is an eigenvalue of A iff A is not invertible
find eigenvector x given eigenvalue λ: Ax = λx ⇒ (A − λ**I)x = 0
(A − λ**I)T = AT − λ**I
eigenspace of A—Nul (A − λ**I)
characteristic equation of A—det (A − λ**I) = 0
⇔ λ is an eigenvalue of A
characteristic polynomial of A (with degree n)
multiplicity of eigenvalue λ—the multiplicity as root
similarity—∃P invertible, P−1A**P = B
PBP−1 = A
A, B are similar
similarity transformation—A → P−1A**P
same characteristic polynomial and same eigenvalues
diagonalize—A = PDP−1 where D is diagonal
diagonalizable—∃P, D
⇔ A has n linearly independent eigenvectors
⇔ ∑dimensions of eigenspaces = n
⇔ characteristic polynomial factors completely into linear factors
⇔ dimension of eigenspace for each λ= multiplicity
⇔ basis of all eigenspaces form a basis of ℝn
⇐ A has n distinct eigenvalues
diagonizing—find eigenvalues ⇒ D; find eigenspace basis ⇒ P; check A**P = P**D
vector operation
inner product (dot product)—u ⋅ v**=**uTv
length—
normalizing—get unit vector in the same direction as nonzero vector
distance dis**t(u**,** v) = ∥u − v∥
orthogonal relationship
orthogonal—u ⋅ v**=**0
⇔ ∥u + v∥ = ∥u∥ + ∥v∥
orthogonal complement W⊥—the set of all vectors orthogonal to subspace W
is a subset of ℝn
interactive—A⊥ = B ⇔ B⊥ = A
(Row A)⊥ = Nul A
(Col A)⊥ = Nul AT
orthogonal set—ui**⋅**uj = 0 ∀ i ≠ j
⇒ linearly independent
is a basis for the subspace
orthogonal basis—basis that is orthogonal set
weight— for y ∈ Spa**n{uj}
orthogonal projection—
where z**⊥**u
subspace L spanned by u
orthonormal set—unit vector orthogonal set
orthonormal basis—basis that is orthonormal set
Gram-Schmidt process—calculate orthonormal basis by subtracting projection
QR factorization—orthonormal basis of linearly independent matrix Q, R = QTA
orthogonal matrix—square matrix with orthonormal columns
⇔ U−1 = UT
⇔ orthonormal rows
∥Ux∥ = ∥x∥
(Ux) ⋅ (Uy) = x ⋅ y
Ux⊥Uy ⇔ x**⊥**y
product of orthogonal matrix is orthogonal matrix
orthogonal projection—
for U of orthonormal basis ui
best approximation theorem— is the closest point in W to y
general least-square problem—find x for smallest least-square error ∥b − Ax∥
⇔ normal equation—ATAx = ATb
ran**k ATA = ran**k A
Ax = b has a unique least-square solution ∀ b ∈ ℝm
⇔ A is linearly independent
⇔ ATA is invertible
Χβ**=**y
design matrix—Χ
parameter vector—β
observation vector—y
least-square line (line of regression)—y = β0 + β1x
observed value—yi
predicted value—β0 + β1xi
residual—β0 + β1xi − yi
Χβ = y where
residual vector ϵ
diagonalization of symmetric matrix
symmetric matrix—AT = A
eigenvectors from different eigenspaces are orthogonal
orthogonally diagonalizable—could have orthogonal matrix P
A = PDP−1 = PDPT
⇔ A is symmetric
spectral decomposition—
where ui are the columns of P
uiuiT is a projection matrix—pro**j{ui}x**=**(uiuiT)x
single value decomposition SVD—A = UΣVT
left singular vectors form U is m × m orthogonal
is m × n
, σ1 ≥ ⋯ ≥ σr > 0
right singular vectors form V is n × n orthogonal
∀ m × n matrix A, ATA is symmetic
its eigenvalues λ1 ≥ ⋯ ≥ λi ≥ ⋯ ≥ 0
single values—
for {v1, ⋯****,vn} with eigenvectors of ATA correponding to λ1 ≥ ⋯ ≥ λi, and A has r nonzero singular values, {Av1, ⋯****,Avr} is an orthogonal basis for Col A, ran**k A = r
find single value decomposition
find orthogonal diagonalization of ATA—P, D′
V = P to orthonomal = {vi}
D and Σ
U—
Last edited:
Speech Recognition
broader speech processing
- wake-up word detection: binary classification
- small window → low latency
- multiple models, threshold & size
- echo cancellation: subtract (complex) echo of sound from speaker
- sound source localization: microphone array, delay
online/streaming mode: continuous conversion
omnidirectional/ cardioid/ hyper cardioid microphone
sound sample rate
- need at lease 2x of highest frequency wanted, else aliasing (Nyquist theorem)
- 44.1kHz for CD
- 16kHz good enough for speech
-curve
audio format: use PCM .wav
online endpointing format: push to talk, hit to talk, continuous listening
feature extraction
spectrogram: energy distribution over frequency vs time
preemphasize speech signal: boost high frequency
spectrogram: from time series to frequency domain
- discrete Fourier transform (DFT)
- symmetric, only first half + midpoint meaningful (by Nyquist theorem)
- magnitude: Hz, frequency at point
- : sample rate, : number of sample
- power: magnitude squared
- flat noise from jump in sample windowing
- solution: multiple input by bell-shape windowing function and half-overlap windows to avoid losing information
- before using fast Fourier transform (FFT): zero padding
- cause fake interpolated detail
auditory perception: from frequency to Bark
- mimic human ear, which distinguish low frequency better
- frequency warping with Mel curve
- filter bank: triangular filter on Mel curve to be multiplied
- evenly-spaced, half-overlap, 40 enough, 80 good
- translate back to equal-area triangles on frequency axis
- not directly on Mel curve for simplicity
log Mel spectrum: log of integration of each filter bank
Mel cepstrum discrete cosine transform (DCT) compression
- reduce redundancy from filter bank overlap
- subtract the mean to remove microphone/noise difference
- microphone response is speech with convolution
- convolution -DFT → multiplication -log → summation
longest common subsequence: dynamic programming, dummy char padding, streaming, search trellis, sub-trellis, lexical tree
- pruning: hard threshold vs beam search
DTW: dynamic time warping: disallow skipping (vertical on trellis), non-linear mapping (super diagonal)
- : best path cost from origin to
- : local node cost (vector distance)
- global beam across templates for beam search
- combine multiple template
- template averaging: first align templates by DTW
- template segmentation: compress chunks of same phoneme
- actual method: iterate from uniform segments to stabilize variance
Mahalanobis distance
- can be estimated with negative Gaussian log likelihood
covariance
- estimated with diagonal covariance matrix when elements largely uncorrelated
self-transition penalty: model phoneme duration
MFCC (Mel frequency cepstrum coefficient)
dynamic time warping (DTW)
- align multiple training sample
- segment all model sample uniformly by #phoneme, and average
- align each sample against model sample to get new segment and new average
- iterate until convergence
- transition probability: #segment switch over #frame in segment
hidden Markov model for DTW
- use log probability so total score is log total probability
- simulation by transition probability matrix (each row sum to 1)
- initial probability
expectation-maximization (EM) algorithm
initialize with k-means clustering
auxiliary function: conditional expectation of the complete data log likelihood
evaluate
iterate until convergence
forward algorithm
- initialize
- iterate
Baum Welch: soft state alignment
log-domain math
continuous text recognition: small-scale problem, e.g. voice command
- wrap back from end of template to start dummy variable
- high wrap back cost → discourage space
- lextree
- non-emitting state/ null state: only for connecting, no self-transition
- no transition time
- prior probability for word: add to the start of its HMM
- word transition probability for edge cost between word HMM
- approximate sentence probability with best path
grammar: only focus on syntax not semantics
- finite-state grammar (FSG)
- context-free grammar (CFG)
- backpointer: only word-level, additional script on word transition
training with continuous speech: bootstrap & iterate
- silence: silence model, bypass arc, self-loop non-emitting state
- loop need to go through emitting state, else infinite
N-gram
- N-gram assumption:
- start/end of sentence:
<s>,</s> - unigram, bigram. 5-gram good enough for commercial use
- N-gram with D words need transition node
- good Turing
- Zipf’s law
- backoff
state-of-the-art system
- unit of sound by clustering large unlabelled dataset
- transfer learning with small labeled dataset
phoneme: 39 English, Mandarin with tone
- few rare phoneme, much more common than rare word → beat Zipf’s law
- defined by linguistic, or learned by clustering
- mono-phone/tri-phone: context-independent/dependent (for neighbor)
- absorbing/generating state → non-emitting
- locus: stable centers in spectrum
multiple pronunciation: multiple internal model + probability
mono-phone/ context-independent (CI) model
di-phone: model previous and current phoneme. problem: cross-word effect
tri-phone: model multiple current phoneme based on previous and next phoneme
- many cases not seen, back off to mono-phone
- share Gaussian with mono-phone, different weight
- decision tree
inexact search: run n-gram on (n-1)-gram model by applying word-transition prob
Last edited:
Statistical Machine Learning
SGD > GD for online learning
SGD problem: mini batch too big
gated recurrent unit (GRU): a RNN
principal component analysis (PCA): autoencoder, dimensionality reduction
Bayesian decision theory
loss : take action when sample belong to
goal: minimize risk
for 0-1 loss,
reject class: a th class w/ fixed loss
- reject when
or, maximize discriminant function
maximum likelihood estimator (MLE)
parametric (distribution based on known parameters) vs non-parametric
linear regression
regularization in lasso
assuming
invertible, proof by positive definite
K-nearest neighbors (KNN)
need to try different
support vector machine (SVM)
hard-margin binary SVM
objective, maximize minimum margin:
by
apply Lagrange multiplier:
final objective:
solution: sequential minimal optimization (SMO)
- fix all but 2 , and iterate
- 2 variable because
soft-margin binary SVM
kernel SVM
solve non-linear problem w/ linear classifier
kernel, but w/o restriction
objective:
positive-definite kernel
positive-definite kernel output positive-definite matrix
- positive-definite matrix: pivots > 0 or eigenvalues or subdeterminant > 0
- Hilbert space: symmetric, positive-definite, linear
alternative definition of kernel:
- symmetric
- positive-definite: Gram matrix semi-positive definite
dimensionality reduction by principal component analysis (PCA)
lossy transformation from to dimension
- mean:
- covariance:
- centering matrix:
- proof:
- centering matrix:
maximize variance
minimize distance between full projection (-dimensional) and principal component analysis (PCA, -dimensional):
- centering:
- lossless transformation with :
- PCA transformation:
objective:
Monte Carlo sampling method
- sampling
- purpose: determine parameter when doing sum/integral
- good: from area of high probability & independent
- Monte Carlo drawback
- does not work in high dimension
- assume sample independence
transformation method
- assume
- get sample
- assume CDF
- solve
- get another sample and repeat
rejection sampling
- define distribution s.t.
- get sample
- rate
- select random variable
- if , accept sample ; else reject
- reject most sample when large
- hard to determine
- waste iteration
importance sampling
for value following distribution with PDF , do not know CDF, want expectation
define distribution with known CDF
weight (importance)
sampling-importance-resampling
- get sample from with known CDF
- normalize
- treat as probability for and resample
simulated annealing
- to avoid trapped in local minimum
- still need to try multiple time
when seeking minimum, accept increase in with probability
where temperature
Markov chain
- transition matrix
- stochastic matrix, because each row sum to 1
- converge, stationary
- all eigenvalue
- where is diagonal with entries
- converge, stationary
- stochastic matrix, because each row sum to 1
- probability be at state at time
- stationary distribution: when large
- sampling method: given PDF , set s.t.
detailed balance
Markov chain in stationary distribution if
Markov chain Monte Carlo (MCMC)
- work in high dimension
- honor probability dependency between sample
metropolis hasting algorithm (MH algorithm)
want to sample target distribution
design Markov chain w/ stationary distribution :
- get Markov chain w/ s.t. not necessarily
- acceptance rate
- use new Markov chain w/
- take the rest of probability s.t.
- drawback: do not know when stationary/converge. sample may be dependent
Gibbs sampling
want to sample variable following different distribution
fix to previous value when sampling :
a special case for metropolis hasting method
entropy
- randomness, impurity, how easy to determine
- equal to expected surprise
- cross entropy loss
surprise
decision tree based on entropy
- information gain
- maximize information gain on each split
statistical learning theory
- Bayes classifier : minimize expected risk
- empirical risk minimization (ERM): minimize loss on training data
- estimation error (training error): because finite, grow w/
- approximation error (model complexity): because finite
consistence wrt &
empirical risk close to true risk
- universally consistent wrt :
- Bayes-consistent wrt
- uniform convergence
- sufficiency
generalization bound
for finite class
- proposition: choose w/ at least probability
- by
for infinite class
proof: where is empirical risk of another sample (ghost sample)
class of for sample & ghost sample
problem: hard to compute shattering coefficient
shattering coefficient
maximum number of , function we can get by restricting to
(Vapnik-Chervonenkis dimension) VC dimension
maximum s.t. , classify completely correctly
- for function class w/ VC dimension
- for ,
- ERM is consistence VC dimension finite
Rademacher complexity
richness of function class in sample set
sample label
solution: for each possible set of , find the function to maximize the inner sum, then take weighted average
- generalization bound: with ≥ probability, ,
structural risk minimization (SRM)
to balance training error and model complexity
- e.g. regularization, linear SVM VC , RBF kernel
Last edited:
Unstructured Reading Notes
- JavaScript Dead-Code Elimination via HTTP Range Requests (ThorJS), Ayush Pandey, NSL meeting
- problem: lots of JS, bloat, screw developing regions
- mean page load time 18s for some countries
- dead code
- use in-browser proxy with precomputed JS file range
- on top of Muzeel, dead JS code elimination
- fork Thorium
- <10% top 1M sites don’t support range requests
- most servers can support tens to hundreds of ranges
- large savings for JS file loading & page load time
- problem: lots of JS, bloat, screw developing regions
- Collective Communication Algorithms, Arvin Ghavidel, NSL meeting
- collective communication (CC): any scheme where multiple nodes communicate
- collective algorithm: how node send/receive data
- collective schedule: chunk-level protocol of when, how much, etc.
- most people just use library
- prominent 4: AllGather, AllReduce, AllToAll, ReduceScatter
- AllReduce very core to ML training ⇒ now implemented in hardware
- default may not work well bc no knowledge of network topology
- NCCL uses ring AllGather for large message, tree for small
- backfire when e.g. each node has multiple GPUs + direct 1-to-1 connected NICs
- NCCL uses ring AllGather for large message, tree for small
- cannot escape contention w/ other process
- new inference paper get most gain from latency gaps
- latency larger than time to send some message
- no overlap in some link
- ⇒ do custom schedule
- most large companies forked NCCL
- MS-CCL, TE-CCL (SIGCOMM 2014)
- CC harder than TE bc can do streaming copy (dup)
- need many snapshots and take very long to run optimizer
- OptCCL basically solves this: s for 256 GPUs
- unlike TE, can reuse schedule bc problem unchanged
- except for MoE, unsolved
- does not handle failure
- can find waypoints where schedules would be optimal for a range of input
- need many snapshots and take very long to run optimizer
- installing updates hard bc usually no central control plane for GPUs
- direction: CC on OCS: need to decide topology + schedule
- DDB: Source-Level Interactive Debugging for Distributed Applications, Yibo Yan, NSL meeting
- too many too dynamic GDB sessions
- stack trace end at RPC boundary
- piggyback IP/PID/ thread context on RPC
- timeouts during interactive debugging
- shim above LibC to fake time
- Emergent Algorithms in Foundation Models, Deqing Fu, Theory Lunch
- motivation: what happens if AI become essentially oracle
- understand how transformer learn & behave
- in-context learning for linear regression
- doing better recently than fine-tuned
- experiment show layers converge like Newton’s method steps
- ~
- widely hypothesized (wrong): gradient descent
- train transformer to predict connectivity matrix from adjacency matrix
- unable to do distance for layers
- if replace residual by concatenation, can do more
- unable to generalize to OOD graphs
- disentangle transformer into algorithm + heuristic channel
- in 1-layer transformer, algorithm weights go up, heuristic up then down
- within-capacity graph promote algorithm channel
- out-of-capacity graph promote heuristic channel
- actually hurt accuracy
- if only train with within-capacity graph, better performance both ID and OOD
- Fourier spectrum for numbers 0~999 embedding for pretrained LM all seem similar
- many with frequency 2, 5, 10 due to base 10 representation
- number-text correspondence is important
- Fourier Number Encoding with (FoNE)
- make it take few examples to learn additions
- make high-precision float/ large number processing much better
- motivation: what happens if AI become essentially oracle
- StreamEP: Straggler-Tolerant MoE Decoding without Communication Barriers, Shaoyu Wang, NSL meeting
- motivation: expert parallelism (EP) straggler problem
- batch per each MoE expert w/ micro queue
- naive approach have scattered batches → low GPU utilization
- predict main batch
- analogy: making most people catching the shuttle bus
- each GPU schedule a few sets of weights to compute
- little throughput loss when small portion of network packets drop
- Wave: Leveraging Architecture Observation for Privacy-Preserving Model Oversight, Haoxuan Xu, NSL meeting
- measure what model is run only using microarchitectural side channel
- e.g. is Modal-aaS service using smaller model
- w/o knowing model structure/ user data
- e.g. export control
- use hardware counters (PMC)
- FLOPS/load/store scale w/ model size due to matrix math
- recover periodicity in kernel stats: per token (large), per layer (small)
- estimate kernel role & parameter size from theoretical size
- Discussion: User-study Design in DDB, Yibo Yan, NSL meeing
- show DDB is effective: usable, helpful in certain cases, complementary
- competition: tracing, record&replay
- 2 case per category: crash, deadlock, logical bug
- time-to-localize, time-to-fix, success rate
- questionnaire participant to rate metrics + objective comments
- Near-Optimal Online Traffic Engineering, Arvin Ghavidel, NSL meeting
- WAN TE 5min periodicity slow ⇒ need prediction
- sequencing programming switch very slow bc long RTT & waiting
- traditional TE fix several paths & only solve for splits
- easier to solve
- less memory on router
- topology engineering: edge-based instead of path-based
- decentralized SDN: each switch respond immediately & program itself
- becoming feasible bc switch becoming beefy
- want to be reactive, so maybe less need to predict
- ADMM: controller track mean, participants (switches) independently solve according to mean, in a loop
- switches iterate multiple steps per received mean
- multiple controller (coordinator) grouped by RTT
- MetaRL, Mahdi Alizadeh, NSL meeting
- traffic engineering: optimal solution very slow
- performance gap: difference for heuristics
- DL & RL solutions suck at corner case e.g. link failure
- challenge for MetaOps
- need to express problem as linear program—lot of code
- solver very slow
- new approach: use RL to learn to maximize performance gap
- off-policy RL thru soft actor-critic (SAC)
- can reuse past experience, unlike on-policy e.g. PPO
- max reward + policy entropy
- I/O Optimizations for Deep Learning on Distributed/Resource-Constrained Environments (Optimus-CC), Yaeyong Song, NSL meeting
- GPU utilization low in LLM training bc gap
- compress inter-stage gradient communication lossy
- compressing forward activation would diverge
- naive lossy compression cause higher perplexity
- save compression error & propagate next batch
- only compress critical path (ones that finish later)
- reduce wall clock time to convergence
- only advantageous if NIC slow & compute fast
- Defense: Incentivizing Efficient Delegation without Payments, Curtis Bechtel
- single-proposal mechanism can do as well as any multi-step method
- WLOG, only consider single-proposal delegation
- multi-agent delegation: strategic delegation gap = adversarial delegation gap
- delegation gap tend to 1 log inversely w/ more agent (assume symmetric contribution)
- combinatorial constraint: downward-closed solution constraint & probing constraint
- utility of solution is sum of component
- constant delegation gap from adaptivity gap
- Weitzman’s Pandora’s box: combinatorial + probe cost per element
- principle reimburse of probing cost
- agent probe too much but amortize for that
- shared-cost approximation: different reimbursement ratio per element
- reduce to online contention resolution scheme (OCRS)
- agent run either Pandora’s box or prophet inequality depending on whether probing too expensive
- delegation gap could be ≥1 if aligned enough
- principle reimburse of probing cost
- single-proposal mechanism can do as well as any multi-step method
- Async MoE, Coulson Liang, on behalf of Shaoyu Wang, NSL meeing
- MoE usually wait for all AllToAll before next layer
- async is sequential
- send metadata thru CPU
- allocate on GPU w/ NCCL
- NCCL CPU rendezvous: receiver tell sender target address
- proposal: NVSHMEM (shared memory)
- symmetric: receiving buffer (called PE) for each other GPU on each GPU
- send into communication buffer w/o CPU
- challenge:
- CPU needs to know transfer size to efficiently copy out arriving buffer
- ⇒ asyncly copy out in batches
- if multiple send from same sender to same receiver, need to tell sender when available
- ⇒ set bit w/ RDMA & busy wait
- CPU needs to know transfer size to efficiently copy out arriving buffer
- Steven idea: use NVSHMEM to mask old implementation latency
- Lunch in Theory: Near-Optimal Sparsifiers for Stochastic Knapsack and Assignment Problems, Xinyu Liu
- stoachastic knapsack: item may be unavailable (0 value)
- active probability (,equal in this study)
- don’t know which active; need to query to know
- only allowed to select queried active set
- sparsification: balance accuracy & query cost
- sparsification degree: #query / k
- want to hedge against active probability w/ few query
- insight: can substitute w/ value slightly lower if weight smaller
- bucket by multiple of value, query from lowest weight in each “large” bucket till weight exceed threshold
- set only “small” bucket to
- query “small” bucket naively
- for GAP: need redundant assignment & substitution when need to “steal” from another knapsack
- stoachastic knapsack: item may be unavailable (0 value)
- HTML5, Web Technology class, Marco Papa
- W3C failed to replace HTML4 w/ XML
- changes to web standard: https://spec.whatwg.org/
- goal: separate “presentation” into CSS
- successful bc has audio/video built in: no more Flash!
- WebM infringed MPEG-4 patent so Google had to pay Apple
- WebSQL dropped at version 5 bc nobody implemented it
- LiVo: Toward Bandwidth-adaptive Fully-Immersive Volumetric Video Conferencing, Rajrup Ghosh, NSL meeting
- volumetric video streaming need high bandwidth, no bandwidth adaptation
- use 2D video codex (H.265) for 3D
- WebRTC for streaming
- tile depth w/ color bc GPU only support 8 parallel encoders
- use luminance channel for depth to avoid geometry info loss
- dynamic bandwidth splitting between color vs depth to balance RMSE
- RMSE: root mean square error
- frustum culling: rid invisible pixel
- Lunch in Theory: How to Measure Differences in Rankings, Yeganeh Alimohammadi
- goal: individual ranking → global consensus
- explain observed variability
- ranking models
- Borda count: sum of score based on rank
- Plackett-Luce: probabilistic
- Mallow: central ranking , distance , dispersion
- usually norm where
- MCMC work in theory but not converge in practice
- MLE estimator strongly consistent
- set , optimize and fix it first
- optimize
- converge bc mean is stable w/ enough samples
- narrow sampling by only considering diagonal band
- dynamic programming to compute matching of spare matrix bipartite graph
- show how predictable games are, e.g. basketball > football
- goal: individual ranking → global consensus
- Granula Resource Demand Heterogeneity, Coulson Liang
- CPU pipeline complexity makes “bandwidth usage” imprecise
- resource usage fluctuates within 10us-level interval
- fine-grained scheduling possible now bc Quicksand & Granny
- profile w/ hardware performance counter (PMC)
- need “timeline”: call context of function
- Hiresperf w/ LDB & PMC polling & interrupt: 7% overhead at 10us interval
- read value from dedicated core
- future: self-report w/o interrupt
- Junzhou He, NSL meeting
- avoid WASM timing side-channel attack
- detect leakage from program dependence graph (PDG)
- repair by branch removal
- A Permissions Odyssey: A Systematic Study of Browser Permissions on Modern Websites, Alberto Fernandez-de-Retana
- website ask for permission in HTTP header
Permissions-Policy- many syntax error
- many permission delegate to iframe, many using wild card
- browser only display permission prompt on parent webpage, not iframe address
- website ask for permission in HTTP header
- Not All Visitors are Bilingual: A Measurement Study of the Multilingual Web from an Accessibility Perspective, Masudul Hasan Masud Bhuiyan
- many blind speak non-Latin-script language
- text-to-speech bad for many non-Latin
- alt text missing or in English
- Google Lighthouse test let empty alt text pass
- From WebGL to WebGPU: A Reality Check of Browser-Based GPU Acceleration, Sthitadhi Sengupta
- implement computation in WebGL, WebGPU, CPU on Chrome
- compile C++ to WASM/JS
- GPU slower for smaller size, faster for larger size
- WebGPU vs WebGL similar except for loop-driven function
- similar for GPU from WASM/JS
- implement computation in WebGL, WebGPU, CPU on Chrome
- Scrapers selectively respect robots.txt directives: evidence from a large-scale empirical study
- AI/search crawler ~30% endpoint access compliance
- AI data crawler more compliant
- On YouTube Search API Use in Research, Alexandros Efstratiou
- people split time period for search to circumvent 500-video result limit
- likely returned: more view, short, fewer channel vid, older channel
- result delta small ⇒ time period split work poorly
- A first look into long-lived BGP zombies, Iliana Maria Xygkou
- zombie: failure to withdraw route in downstream AS
- BGP beacon method
- long-lived zombie: ≥ 8.5 month
- router can propagate zombie route (resurrect)
- service: stuck routes observatory
- A Framework to Evaluate MPIC Security using Real-World BGP Announcements, Cyrill Krähenbühl
- multi-perspective issuance corroboration (MPIC) to avoid BGP attack on SSL
- deploy on cloud ⇒ lose resilience
- ru-RPKI-ready: the Road Left to Full ROA Adoption, Deepak Gouda
- ROAs cover more than half prefix
- not in AFRNIC & LACNIC
- ROA issuance planning complicated by subprefix & leasing
- most remaining prefix straightforward to ROA
- ROAs cover more than half prefix
- Replication: A Two Decade Review of Policy Atoms - Tracing the Evolution of AS Path Sharing Prefixes, Weili Wu
- important bc prefix in same atom stick together in BGP update
- still true; true for IPv6
- policy atom split farther away from origin
- TODO: this and web atom
- important bc prefix in same atom stick together in BGP update
- The Decentralization Dilemma: Performance Trade-Offs in IPFS and Breakpoints, Ruizhe Shi
- chunk & hash file for content ID (CID) into Merkle tree
- bitswap: ask for file, then download it
- make IPFS 8x slower than HTTP
- straggler bring down performance dramatically
- modify bitswap to improve performance for large file
- The Developer, the RFC, and the Middlebox: An HTTP/2 Compliance Story, Mahmoud Attia, Ilies Benhabbour
- server/proxy may ignore non-compliant part in request
- should reply 400
- asymmetric compliance between client & server
- server/proxy may ignore non-compliant part in request
- Protocol Compliance in Popular RTC Applications, Peiqing Chen
- different messaging app modify RTC protocol for own purpose
- ⇒ cannot interop
- How I learned to stop worrying and love IPv6: Measuring the Internet Readiness for DNS over IPv6, Anja Feldmann
- DNS marked IPv6 optional in 2004 bc cannot fragment
- need MTS, rely on more fallible ICMP ⇒ pain
- worse for longer DNSSEC
- ISP still dropped IPv6 fragment bc legacy security
- DNS over IPv6 is mostly working
- DNS marked IPv6 optional in 2004 bc cannot fragment
- Do Spammers Dream of Electric Sheep? Characterizing the Prevalence of LLM-Generated Malicious Emails, Wei Hao
- spike from GPT-4o release; ~50% spam email
- similar content from some spammer
- bypass word frequency template
- Somesite I Used To Crawl: Awareness, Agency and Efficacy in Protecting Content Creators From AI Crawlers, Elisa Luo
- most AI crawler respect robots.txt
- AI blocking services block crawler user-agent
- An In-Depth Investigation of Data Collection in LLM App Ecosystems, Yuhao Wu
- crawl “GPTs”
- analyze what they collect w/ LLM: include password
- embed advertising service: can see shared context window
- little privacy policy statement, but collect much in practice
- Tracking Internet Disruptions in Ukraine: Insights from Three Years of Active Full Block Scans, Florian Holzbauer
- periodic ICMP to all Ukraine /24 block every 2hr
- more fine-grained method than IODA
- ISP move address out from frontline, some to Amazon
- winter outage more in edge & frontline
- power outage overlap&correlate w/ network outage
- Russian army damage caused specific outage in Kherson
- Learning AS-to-Organization Mappings with Borges, Fabián E. Bustamante
- AS2Org rely on WHOIS/PeeringDB
org_id - use LLM to extract info from RIR text field
- AS2Org rely on WHOIS/PeeringDB
- Sibling Prefixes: Identifying Similarities in IPv4 and IPv6 Prefixes, Oliver Gasser
- dual-stack domain in OpenIntel DNS data
- find matching pair w/ highest Jaccard similarity
- tuning algorithm
- 76k sibling, over half have some organization name
- Have you SYN what I see? Analyzing TCP SYN Payloads in the Wild, Dario Ferrero
- reactive telescope: respond to packet
- 3/4 are HTTP GET
- Patchwork: A Traffic Capture and Analysis Platform for Network Experiments on a Federated Testbed, Nishanth Shyamkumar
- FABRIC network: testbed open for routing research
- Congestion Patterns in a Large-scale RDMA Datacenter, Soudeh Ghorbani
- congestion of AI training center moved from edge to core
- due to priority-based flow control (PFC) preventing last-hop drop
- unbalanced core from burst; revealed by PFC
- telemetry type (PFC) more important than frequency
- congestion of AI training center moved from edge to core
- The SAP Cloud Infrastructure Dataset: A Reality Check of Scheduling and Placement of VMs in Cloud Computing, Arno Uhlig
- public dataset of CPU, mem, network, storage of VM & long-running tasks
- resource allocation highly imbalanced
- CPU usually overprovised; memory closer to capacity
- FP-Inconsistent: Measurement and Analysis of Fingerprint Inconsistencies in Evasive Bot Traffic, Hari Venugopalan
- bot detection vs evasion
- pay bot traffic service to visit distinct obfuscated URL
- half not detected
- often evade if can support browser plugin/ from “iPhone”
- ⇒ forge browser attribute
- often inconsistent
- temporal e.g. changing attribute from same device
- spacial e.g. nonexistent iPhone screen size
- TODO: learn from these bots
- CookieGuard: Characterizing and Isolating the First-Party Cookie Jar, Zubair Shafiq
- make cookie “1st-party” w/
document.cookie, then 3rd-party read&write- not blocked bc 1st-party
- commonly in main frame
- exfiltration, overwrite, delete
- delete sometimes bc accidental name collision
- browser extensions: intercept & partition Cookie jar
- break SSO but not many sites
- for dev: running 3rd-party in main frame gives it full control
- make cookie “1st-party” w/
- Canvassing the Fingerprinters: Characterizing Canvas Fingerprinting Use Across the Web, Elisa Luo
- no need JS/consent
- fingerprint fingerprinting script the same way they fingerprint
- extract rendered canvas as base64 image ⇒ know emoji&font
- learn OS, browser, GPU, default font size, etc.
- some for CDN security
- adblocker list 45% of canvas fingerprinting, but only block 5% bc 1st-party exemption
- Where in the World Are My Trackers? Mapping Web Tracking Flow Across Diverse Geographic Regions, Robert Ricci
- important to know if tracker from another country bc jurisdiction
- visit regional popular websites w/ browser + DNS + traceroute
- geolocate w/ recent technique
- Europe largest hub for intercontinental tracker
- Fingerprinting QUIC clients, Seungju Lee
- Safari inconsistent QUIC support, other browsers good
- different connection ID (CID) across implementations
- Chunk-fu: Fingerprinting QUIC implementations using fragmented frames, Karthik Nishanth Sengottuvelavan
- QUIC TLS handshake frame could be chunked, method unspecified
- fingerprint how chunking done, runtime (big O)
- Passively Inferring Network Availability and Configuration from NTP Pool Clients, Paul Chung
- network time protocol for passive measurement
- use NTP pool bc anyone can reserve
- ground truth: US hospital ransomware report
- fingerprinting by hashing less-volatile NTP header
- network time protocol for passive measurement
- ASINT: Learning AS-to-Organization Mapping from Internet Metadata, Yongzhe Xu
- prune news w/ LLM → named entity recognition (NER) → RAG
- TODO: how prune?
- cluster AS of the same organization
- prune news w/ LLM → named entity recognition (NER) → RAG
- When Blocks Go Missing: The Timeliness and Trustworthiness of Blockchain RPC Providers, Ye Shu
- most user use remote block chain node thru RPC
- inconsistent states give opportunities for massive censorship & attack
- Binance smart chain (BSC) network: many have multi-second delay/ missing block
- How Do You Know My Name? Investigating The Role of Domain Names for Target Reconnaissance among Web and IPv6 Scanners, Sebastian Kappes
- network telescope (dark net) unused IP address waiting for scanner
- but IPv6 scanning focused so may have no traffic
- use honey domain name to attract scanner
- most scanner scan immediately after getting DNS response, but few wait weeks
- early scanner tend to TCP/UDP; late scanner ICMP
- network telescope (dark net) unused IP address waiting for scanner
- Towards a systematic benchmark framework for evaluating darknet-analysis methodologies, Max Gao
- use signature from historic outage
- DarkVec not much better than random; DarkSIM works somewhat
- The Potential of Erroneous Outbound Traffic Analysis to Unveil Silent Internal Anomalies, Andrea Sordello
- outbound traffic may be erroneous
- lack of response to ICMP error signal mistake
- capture from campus network w/ SDN monitor
- reveal malicious software & configuration mistake
- outbound traffic may be erroneous
- Identifying Disruptive Patterns in Internet Background Radiation, Xie Qiu
- https://ioda.live outage viz
- background radiation (telescope) to see traffic from /24
- problem: spoofing, burst
- hard to fingerprint scanner bc distributed
- low and slow “scanner” from china AS, w/ many source IP
- possibly from CGNAT
- IMC 2025 Student Workshop Keynote, Arpit Gupta
- digital inequity, vs secure & performant
- 100+billion spent, based on fake data from ISP oligopoly
- broadband querying tool (BQT): what user see from different IP
- ISP not executing after getting fund (CAF program)
- speed test data lack context of subscription tier
- collaborate w/ state government
- most ML for network don’t generalize
- mindset: make impact,
publish paper
- SplatPose: On-Device Outdoor AR Pose Estimation Using Gaussian Splatting, Rajrup Ghosh, NSL meeting
- perspective-n-point (PnP)
- image retrieval (slow) vs rendering-based (fast)
- appearance modeling to deal w/ different lighting
- hierarchical depth sorting for fast 3D Gaussian rendering
- Towards Microsecond-Scale vm Core Provisioning Agility on Serverless Platforms, Yibo Yan, NSL meeting
- data-driven workload demanding, unpredictable, bursty, but has deadline
- ⇒ over-provisioning (waste), autoscaling (too slow)
- horizontal scaling slow (10s, 10s of ms)
- ⇒ proposal: prioritize vertical scaling (add core to VM)
- microsecond core reallocation (redistribute)
- FlusOS: library OS, work-steal, scale up/down w/ host
- Hybrid Data-Driven and Simulation-Driven Prediction of mmWave Network Performance, Zihao Feng, NSL meeting
- mmWave high data rate ~40Gbps
- high center frequency ⇒ wider spectrum unoccupied (B) ⇒ higher bandwidth
- phased array cause side lobe ⇒ interference
- data-driven simulator: protocol-based simulator w/ RL
- per-beam received signal strength (RSS, physical layer) → RL → simulator
- KL divergence loss between simulator throughput and measured ground truth
- Steve Jobs President & CEO, NeXT Computer Corp and Apple. MIT Sloan Distinguished Speaker Series, 1992
- attack operational productivity w/ software, not management
- “object” reusability made NeXTSTEP attractive bc programmer could write 20% code to make the same “mission critical” application
- translate to “package” reuse today
- bright people produce stuff reused by others
- all decision maker should buy into the decision
- when hiring high-level people: expect them to tell you what to do, not the other way around
- take long term view on people: tolerate short-term mistakes to build team
- view manufacturing as competitive advantage
- view manufacturing as software engineering but w/ hardware
- start from the software to design hardware
- Defense: Automated Reproduction of Bug Reports for Mobile Applications, Zhaoxu Zhang
- bug report have missing/wrong step
- split & reorder actions in sentences for steps
- Markov decision process (MDP) + Q-learning for globally optimal steps
- ignore hidden state; only consider UI state
- optional: search w/ Markov chain from UI transition graph (UTG)
- intermediate representation to help validate non-crash bug reproduction
- WinCC: A step by step guide for a successful proposal, Tamim Ahmed
- find application of thing you worked a lot on
- can reuse stuff; do not reinvent the wheel
- proper timeline & cost (talk to financial expert)
- Theory Lunch: Towards Publicly Verifiable Cryptography: Obfuscation, Fully Homomorphic Encryption, and Proof Carrying State, Miryam Huang
- computationally impossible to obfuscate a circuit in plain setting s.t. new circuit reveal no information about ’s implementation
- even w/ quantum computing/state
- workaround: weaker as indistinguishable obfuscation; oracle model to help obfuscater; restrict circuit class
- in quantum setting, obfuscate w/ auxiliary state
- proof for fully homomorphic encryption (FHE)
- succinct non-interactive argument (SNARG)
- proof-carrying state (PCS): quantum proof-carrying data (PCD)
- useful bc quantum state not cloneable
- computationally impossible to obfuscate a circuit in plain setting s.t. new circuit reveal no information about ’s implementation
- Theory Lunch: Proper Learnability and the Role of Unlabeled Data, Julian Asilis
- proper learning: learned fn not in hypothesis class
- e.g., majority vote for binary classification, multiclass classification
- why limited hypothesis class: learnablility
- in PAC learning, having infinite unlabeled data does not change statistical difficulty of learning
- but make learnability always proper
- distributional SRM: regularize distribution of
- e.g., Bayesian learner
- proper learning: learned fn not in hypothesis class
- Theory Lunch: An Equivalence Between Fair Division and Wagering Mechanisms, Jens Witkowski
- divide multiple kind of goods among multiple agent vs. wagering
- one-to-one correspondence
- incentive compatibility: no more profit by lying about preference
- individual rationality: participant expect non-negative utility
- divide multiple kind of goods among multiple agent vs. wagering
- Job talk: Expectation vs Reality: How Network Abstractions Impact Internet Security, Paul Pearce
- routing is abstraction for Internet scanning
- e.g., different route when using HTTP vs HTTPS
- ECMP cause packet to go thru different AS → country → censorship
- ⇒ need to build exact packet for traceroute
- censorship/ no censorship due to routing bc source IP/port, etc.
- IPv6 impact overlooked in security community
- LSTM RL system to generate IPv6 address upper-64 bit
- domain knowledge for lower-64 bit
- IMCP6 port scan show many home router
- accidentally public IP due to no NAT; many CVE
- ⇒ abstraction change: default deny → default allow
- routing is abstraction for Internet scanning
- Theory Lunch: Vote Delegation through the Lens of Metric Distortion, Alan Grayson York
- delegating vote to informed voter reduce metric distortion from to
- assume 2 candidate for linear preference spectrum
- if informed voter among total is uniformly distributed among preference spectrum
- not if informedness is i.i.d.
- assume voter delegate vote to informed neighbor voter if expect them to vote better
- limitation: unrealistic assumption
- delegating vote to informed voter reduce metric distortion from to
- Guest Talk: Computational Homogenization for Inverse Design of Surface-based Inflatables, Yingying (Samara) Ren, ISTA
- goal: simple fabrication state, transform to complex&stable target state
- surface-based inflatable: flat to 3D
- analyze property of infinite sheet for periodic unit cell w/ different parameter using periodic homogenization w/ mesh
- use X/Y scale factor & bending stiffness to reverse engineer the pattern needed
- How to Enhance Your Immune System | Dr. Roger Seheult, Andrew Huberman
- long-wavelength light in sun benefit health
- they penetrate skin
- trigger mitochondria to produce melatonin, antioxidant
- mitochondria produce less ATP as we age
- long-wavelength light in sun benefit health
- The Science of Scientific Writing, George D. Gopen, Judith A. Swan, American Scientist, 1990
- writer responsible to make reader understand
- use structure reader expect
- verb immediately after subject
- each unit of discourse should serve single point
- put emphasized stuff at “stress position”, like end of sentence
- put context & known stuff at “topic position”, like beginning
- use strong action verb
- Thesis proposal: Incentivizing Efficient Delegation without Payments, Curtis Bechtel
- delegation motivation: outside contractor (agent) may not optimize for employer’s (principal) need
- probing constraint: cost, combination limit, etc.
- game: principal set constraint; agent probe, propose solution; principal accept one best proposal iff satisfy constraint or reject all
- delegate utility vs non-delegate utility: use agent vs as if principal doing task themselves
- -fraction delegation gap: fraction between utility
- goal: w/ more agent in competitive delegation w/ stochastic probing
- if probing has cost (Pandora’s Box problem), generally no constant bound
- strategic delegation reduce to adversarial delegation (agent want to minimize principal utility)
- Intelligent, Robust and Trustworthy AI: Managing GenAI Challenges, Next Phase of Hybrid AI Models and Enterprise AI for Mission-Critical Applications, Amit Sheth
- difficult to detect if text generated
- RLHF reduce hallucination
- tweak model to avoid hateful generation
- neurosymbolic: neural AI combined w/ symbolic cognition AI
- knowledge graph auxiliary to DL, bring explainability
- deep infusion
- what do you have what other do not
- Scalable -Means Clustering for Large via Seeded Approximate Nearest-Neighbor Search, Jack Spalding-Jamieson
- k-nearest neighbor w/ approximate radius
- metric: recall; impossible to guarantee
- ∃ sublinear heuristic
- search graph almost universally best
- other application: quantization, space partitioning
- initialization does not matter if and large, running Lloyds
- -means do nearest neighbor search each iteration
- hierarchical navigable small world (HNSW) perform well
- start w/ approximate nearest neighbor graph of centroid
- prune edge to sparsify; randomly sample centroid for higher layer
- start from highest layer, do greedy local beam search to find best centroid on each layer
- “seed point” to start search: choosing from previous assignment give big speedup
- k-nearest neighbor w/ approximate radius
- Full Proportional Justified Representation, Jiasen Liu
- representative selection: majority vs cohesion
- approval-based multi-winner election
- justified representation (JR): large cohesive group should have a winner
- large cohesive group: portion deserve a winner, has common approval
- but not fair; too weak
- strong cohesiveness (-cohesive): portion deserve winner, has common approval of candidate
- weak cohesiveness (weakly -cohesive), common approval of candidate; stronger guarantee
- non-transferable vs transferable (collective) utility: some voter in group satisfied (stronger) vs all
- 4 combination of (strong/weak cohesiveness) × (non-transferable/transferable utility)
- harder (coNP) to verify than finding one solution
- priceability: voter pay for candidate they approve under constant budget
- priceability imply FPJR (full proportional justified representation, weak cohesion + transferable utility) by bounding
- What uniform symmetric distro can a shallow circuit produce, Kewen Wu
- circuit: combination of logic gate mapping input bit to output bit
- symmetric: output w/ same Hamming weight are equally likely
- motivation: compute parity (or something else) of bit w/ shallow circuit → distro sample
- parity (xor): only e.g. where computation hard but sampling easy
- impossible to read 1 bit to decode compressed data
- only 6 case of shallow circuit (local function) mapping from uniform distro to uniform distro
- equal to at most 2-local
- cannot output 1 only on 1/3 majority bc deviation from 1/3
- cannot do majority bc lack of cutoff among either independent group (neighborhood) or independent bit
- Defense: Efficiency in Privacy-Preserving Computation via Domain Knowledge, Weizhao Jin (advisor: Srivatsan Ravi)
- homomorphic encryption on selective model parameters (vis mask) to reduce overhead
- filter by commonly-used formula for parameter sensitivity
- optimize privacy budget, computed via integration
- entity resolution: dedup point in 2 dataset
- simulate ReLU via polynomial function bc HE only support + ×
- balance degree (slow) and accuracy
- network path validation: avoid sending info on all node
- backward propagation to validate path for forward speed assuming few malicious
- XOR hash w/ zero-knowledge proof each pair
- homomorphic encryption on selective model parameters (vis mask) to reduce overhead
- I Slept With 100 Men in One Day | Documentary
- many man would do anything to have sex
- OnlyFans is a huge money printer but also a slippery slope
- The Creator Of Elixir - Top Shelf 7
- Go has huge foot gun in exchange for ability to write lower level code
- most problem are solved; should just use library
- Jose Valim see Rust as functional bc explicit mutability
- Jose think loop hard in immutable language
- Jose was bitten by PL paper w/ slow implementation, and still does not understand the math in his paper as a coauthor
- library that cannot evolve w/o breaking backward compatibility is either a lie or poorly designed
- Credit card interest and interchange fees
- credit card companies make most money from charging merchant percentage
- ordinary people pay for the benefit high-end card user get
- Saagar Enjeti: Trump, MAGA, DOGE, Obama, FDR, JFK, History & Politics | Lex Fridman Podcast #454
- America spirit highly influenced by Scottish-Irish about not trusting authority, fighting, freedom
- performance as politician is not very correlated with personal life
- Washington DC is itself a creature not caring about even the president
- personnel selection is key bc many decision are made by them
- lower down can brick president order by delaying
- US immigration is crowded by relative of citizen
- managerial revolution (virus): not known what is going on lower down
- true power show when ruling w/o having the position
- mainstream media ask dummy question at white house
- stealing election was common and unhinged in US in the last century
- Dario Amodei: Anthropic CEO on Claude, AGI & the Future of AI & Humanity | Lex Fridman Podcast #452
- scaling law: model do better w/ bigger network & training time & data; not seem to stop
- model learn local pattern, larger scale pattern, then long range correlation, etc. as they grow
- model feeling dumber likely bc different system prompt, user prompt, luck, or perception
- hard to make model both helpful/polite and concise/safe
- targeted regulation is needed to not have people radically against regulation
- mechanistic interpretability is a green field in AI
- constitutional AI for RL: AI to rate AI response based on prompt about principle
- important thing is what ultra good AI can do
- Amanda Askell is likely the human who talked most to Claude
- goal is for Claude to be helpful in front of million of people
- model try to please as many people by default, instead to get best result, encourage it to not care
- clear prompting: explain concept to model when talking about what you want, w/ example
- anthropomorphize w/ model: can ask why model refuse to answer
- use strong word to make model do something, e.g., never ever vs do not
- not failing signal failure bc not trying hard enough, but need to understand high-risk failure
- interesting idea: model refuse to talk if boring and just quit
- best way to measure model ability is bleeding edge research you do
- Defense: Real-time Multi-Resolution Neural Networks for Hand Simulation, Mianlun Zheng (Advisor: Jernej Barbič)
- from joint angle, simulate bone, tendon, muscle, vein, nerve, fascia, …
- application: medical education, robotics, Metaverse, physical therapy (committee)
- average (interpolate) 6 MRI scan of hand pose by calculating plastic strain & min energy function for equilibrium
- pattern matching bad: need huge data; no anatomy (dumb)
- tendon simulation: rod model; attach bone; emulate force from forearm; hook → tunnel to slide through
- fascia: triangle mesh + cloth solver; fat: FEM simulation; nail: rigid point cloud in skin
- high accuracy: < 1mm error against MRI
- real-time neural net challenge: nets in graphics slow; real-world usage need < 1ms; existing libraries overlook small model
- need: change level of detail (LOD) for Metaverse
- animation: deform character to vertices
- joint angle → linear blend skinning → net to reduce residue → real-time output
- LOD support: more vertex each level; restriction vs prolongation to downsample & upsample
- go up & down by level
- each level each region (by unity construction) separate net → small net → efficient
- further performance: reduce joint by perturbation simulation; PCA reduction for each region
- hot cache performance: lower output dimension & faster than prior work; much faster on high level
- Measuring context switching and memory overheads for Linux threads
- Native POSIX Thread Library (NPTL) & futex several times faster than old Linux thread
- bearable latency: on his i7-4771 in 2018, multicore context switching took ~1.5µs, same core switching ~2.5µs, launching thread ~5µs, launching process ~22.5µs
comparison: memcpy 64 KiB took 3µs, Goroutine switching took 170ns - lazy memory: 8 MiB virtual via
ulimit(VM), ~8 KiB resident (RSS) without touching stack
- Optimal Protocols for Studying & Learning, Andrew Huberman
- neuroplasticity apply during fast eye movement sleep
- focus & alertness is how remember; sleep is prerequisite; meditation, NSDR are tool
- testing help remember; test ASAP after exposure
- best be open-ended, short answer, minimal prompt, require critical thinking
- do not matter for memory if wrong
- perceived familiarity hinder memory
- gap effect: pause in talk greatly reinforce memory
- ChatGPT from Scratch: How to Train an Enterprise AI Assistant • Phil Winder • GOTO 2023
- post-GPT are decoder-only
- logistic regression is often superb for domain-specific task
- RLHF degrade performance
- parameter-efficient fine-tuning (PEFT): use adapter alongside frozen model
- quantization massively reduce RAM usage
- Falcon-7B LLM: used in demo, said to have cleaned training data, open-source
- fine tuning demo done on V100 in Colab
- How Smartphones Shrink Our Brains
- anticipation trump focus
- habit to rely on tool kill memory
- trying to split attention make though shallow
- paper is better for thinking (I think large screen help)
Last edited:
Steven Hé (Sīchàng)’s Blog
Segmentation fault (brain dumped).
Last edited:
Replacing an AirTag Battery was Frustrating
My AirTag showed low battery, so I had to replace it, and it was the most frustrating experience I’ve had for while, even more frustrating than dealing with AWS’s garbage web interface. So here I am, recording the actual tricks that helped me, in the hope that it might help in the future.
First I tried rubbing the new battery with alcohol solution after Gemini told me it could have a coating. This did nothing and I suspect the cheap battery I bought on Walmart from China does not have any coating. I’m including this because other batteries could be in this league.
After some fruitless attempt, my first consequential attempt was to try to fix the AirTag’s pins. Specifically, the AirTag side pins were pressed down and bent slightly inward, and it became hard to touch the top of the battery (+). I don’t have a toothpick—so I took a paper clip and bent it to separate out a pin. For clarity of orientation, let’s assume the AirTag, not its lid, is open and its inside facing upwards. After some practice, the trick turns out to be to push the paper clip pin into the little gap between each AirTag side pin and the side of the AirTag, and lift the AirTag side pin up. Use the AirTag’s side as a fulcrum and rotate the paper clip outwards s.t. the paper clip pin pulls the AirTag side pin upward. Since each battery side pins is in the shape of a spoon, if I pushed the paper clip into the “bottom of the spoon”, the paper clip pin could essentially grab it and pull it up. Do this gently until the AirTag side pin is fully extended, and the side pins will be lifted high up so it would be easy to contact the top of the battery.
But then the major problem was the cheap battery I bought tended to bounce out of the AirTag as soon as I stop pressing it down, probably a bit too wide, and the solutions turned out to be brute force. I tried many things, including pressing the battery down with a key while trying to put on the lid, but that was very fragile. By pure luck, one time I pulled the AirTag side pin super high up, and then slid the battery in from the opposite side to press the side pins tightly against the AirTag side wall, and the battery stuck inside the AirTag after I pressed it down! I suppose this was because the high side pin positions made the inside of the AirTag tight enough that it provided enough friction to hold the battery in place. So, I guess this’s the way to go: pull the side pins all the way up, and push the battery from the opposite side to get it stuck in.
At this point, I was pretty sure the battery was in place, but the stupid iPhone still could not detect it, neither in “Find My” nor in Bluetooth settings, even after I turned the Bluetooth off and on. I eventually remembered to reboot the iPhone, and it immediately started the AirTag pairing process! I suspect Apple was just constantly lying in my face: when I turn the Bluetooth off it was probably still on or had a cache that prevented it from detecting the AirTag, and the reboot cleared the cache or something. So, after this many years, rebooting still seems to be the Swiss army knife for technical problems.
Reflecting back, the most frustrating aspect was I had no idea whether the AirTag was powered or not after I close the lid—it only chirped when the battery first contacted the pins, and remains silent afterwards. Apple should really make the thing chirp when it’s not connected and you shake it, or something like that. But of course, they wouldn’t, and drive frustrated people to the “genius bar” or to just buy a new AirTag.
2026-02-16
Last edited:
My Programming Language Journey: How I Ended Up Using Rust and Python Most After Trying A Dozen Languages
And really, what’s with the love for all those programming languages? Trying to set a record for indecisiveness?
According to GitHub, I used over 30 computer languages, making a primary target for GitHub Roaster. Unfortunately, my lasting addiction in exploring different programming languages has not found me a perfect match. I have been tolerating Python and Rust for most of my projects, with Python for scripting and Rust for when the Python code becomes too complex or slow.
Sometimes, I wonder how my language learning journey influenced my current choices and liking. Would I have ended up choosing Go if I did not start with Java? Maybe I would have been a Kotlin boy if I did not learn Rust? In this memo, I would like to recall my journey, including the dark history I do not bring up, and look at how I ended up stuck with the snake and the crab languages and said no to the rat and the girl languages.
Before the beginning
I said I started with Java, but that is technically not true.
When I was in my 6th grade, I was left at a friend’s house for a few days. During the day, I was alone, and looked around their house for books to read—one of them being a C introductory book. I remember reading a few chapters about control flows, thinking that was nothing nerdy and high-profile. In retrospect, those few hours probably had a significant impact later.
In the IT course in my middle school, we were taught a CAPITALIZED LANGUAGE for programming graphical interfaces. This was probably Visual BASIC. I remember the absolute chaos in the computer labs with everyone trying to get online and play video games and the teacher hardly having patient to teach. Despite how bad I was at typing tests, I aced the programming exam, probably because of the C book I read a year ago.
I would move on to write automation scripts to play video games in high school. Those programs are much more sophisticated than the BASIC ones because some of them were to automate finishing game levels. That was probably when I learned to debug by running the program again and again, but I apparently did not gain a deep understanding—sometimes things just did not work without apparent reasons.
Going into university, I swore I would not become a programmer because computers are so unreliable and annoying. Boy, was I wrong. I now blame that feeling on Microsoft Windows.
My first programming languages
The experience learning my first programming language fundamentally set my expectations for any programming languages and influenced my taste to this day.
Entering university, my perception of programming was completely changed. I was shocked in Physics and Chemistry classes seeing people programming Python in the labs to run experiments. There were master’s students persuading me to learn computer science, saying that a computer science major can move to most other fields easily, but not the other way around. Suddenly, I wanted to try programming again and started watching Python video tutorials online.
Unfortunately, I did not learn Python by watching videos, and computer science at my university sucked. My peers told me that the entry level computer science course on Python was a waste of time, and advised me to straight-up take the higher-level course on Java. I took their advice and started learning Java instead of Python. I should thank these people for changing my life if I remember who they were.
Java, despite being the meme boilerplate-driven instant-legacy language, was a good first language, in retrospect. Unlike Python, which gives its learners false confidence about their abilities to program (despite often not being able to type out correct syntax), Java causes pain in all areas of its learners’ brains, greatly helping them remember the syntax. Although instructors like to teach programming like a philosophy, it is not. Getting started at programming is more like learning to play a musical instrument or sport—you need to build muscle memory so you can play at all! Then, you can learn to appreciate the philosophy. This is why I programmed more smoothly with languages with more syntax and later felt at home with Rust.
Another huge influence Java had on me was the development environment. I followed video instructions to learn IntelliJ IDEA. To this day, I still see JetBrains IDEs as absolute models in terms of auto-completion, refactoring, and code suggestions, despite how bloated and non-customizable they are. This is why I find VSCode lacking for Java and Kotlin, and why I did not like Python, Julia, or Ruby when I tried them—I got no method autocompletion or type hints in the editor. Python has since caught up with various language servers, but the lacking editor experience is still holding me back from Julia the girl language.
Liked it or not, I was forced to learn Python again and use it for my first collaborative project. Another student was scraping our university websites and making a custom search engine. I did not grasp Python concurrency and had speed problems crawling the websites. I blamed this on Python being slow.
Falling into the crab hole 🦀🕳️
Since Python was so slow, my logical choice was to speed it up, but I ended up in a completely different rabbit—or rather “crab” hole. The seemingly lazy methods like Cython and PyPy all showed major pitfalls quickly, so I started watching videos on how to write Python packages in C and C++ and disliked how they awfully incremented and decremented the reference pointers manually. By pure chance, I heard one of the videos mention “you might as well use Rust”. “There is another language that is not C or C++ that you can write Python packages in??” I was in surprise.
As I dug deeper into what Rust was, it sounded too good. It was fast as C++; but unlike C++, it had Python-like syntax I could understand, straightforward high-level abstractions like Java, error messages that says what is wrong, and a package manager; and it did not Segmentation Fault. Core dumped. It was 2022, the peak of the Rust hype; there were lots of conference talks introducing Rust. From these talks, I started getting a feel of the basic syntax and concepts. Ownership, the Result enumeration type, lifetime somehow all made perfect sense to me, perhaps because I was already used to analytical thinking from learning too much math. So, I read the first half of the book The Rust Programming Language and translated some Python programs to Rust. Everything made sense and the programs got 40x faster with basically the same structures. I was sold.
That was when I deviated from trying to write Python packages in Rust to directly writing Rust programs. I found Rust libraries for HTTP requests, and how to do basically the same things I did with the Python crawler in async Rust. Oh boy, was async Rust a bait! I shot myself in the foot so many times: mutex guards across .await causing errors, async timeouts not timing out, and deadlocks. Rust is definitely not a language you can hack around; you need to understand the concepts behind what you are doing.
The instructor advising the search engine project, however, found Rust too complicated. “I think it is beyond you,” he even suggested. I was pissed. That drove me to finish the Tokio book and later learn more advanced topics in Rust. One thing he said was true, though: having to wait for the code to compile sucks. However, these problems are tiny compared to the lack of an established ecosystem, which I gradually realized when trying to replace all the Python packages we used.
All in all, Rust was and has been a great experience for me. It requires thinking thoroughly about the task at hand and being explicit about all the types and sometimes the lifetimes; in exchange, it offers a rich development environment, robust compile-time checks, and top-tier speed. Rust also introduced me to pattern matching, algebraic data types, and the iterator pattern, which are the main reasons I say no to other imperative languages.
What about…
As I mentioned, I have never been fully satisfied with Python and Rust and peeked at a dozen other languages. I have wanted something that helps out with extensive compile-time checks like Rust but without the type gymnastics, and taps into a vast ecosystem like Python but without the atrocious performance and multicore solutions.
The languages that stand out are the ones I tried for the ecosystem argument: they have packages or frameworks for specific tasks like Ruby on Rails. I still place these languages as my go-to for specific tasks.
- Python for scripting, as a better Bash, and anything related to data science.
- Elixir for web backend (and perhaps frontend) and any complicated distributed systems.
- JavaScript for web frontend.
- Dart for mobile development.
Unfortunately, since I was spoiled by some of Rust’s outstanding benefits, other languages I tried did not stick:
- Julia and Ruby had too much implicit magic and poor editing environments.
- Go lacked basic abstractions like string methods, and its error checking is long-winded.
- Kotlin is nice but its abstractions like
Array.mapcost performance and it only really works well in heavy JetBrains IDEs. - Scheme hurts the eyes when doing simple math.
- Swift, Nim, Gleam had almost no ecosystems.
- Ocaml and F#, I had no idea what their package managers were doing that took tens of minutes when I first tried them. I still want to try F# again.
- Zig and Mojo sounded nice, but neither of them had pattern matching and neither are stabilized (1.0) yet.
I realize it has become very difficult for me to adopt another language for general purposes. For any language, I would want a supportive development environment, “functional programming features” like pattern matching, potential for high performance, and a large ecosystem. I have been vendor-locked in…
Started 2024-12-27, finished 2025-01-03
Last edited:
~300× Speed Up in Rust: Finding Inexact Matches in Nested Sets
I optimized my route analyzer to get 300× faster. It analyzed around 800 million routes within 3 hours.1 The exact multiply of speedup does not matter; rather, I find it valuable to discuss the data structure changes, profiling, and algorithm experiments, the major gains, and the wasted effort.
No, I did not rewrite a Python implementation to gain a trivial 50× speedup; I started with a multithreaded Rust implementation. I bet I would have lost all my hair if I had tried to squeeze out this much performance from some garbage-collected language!
Note that I aim this article at any programmer at the intermediate level or above. Despite the Rust-like pseudocode, you should feel at home if you are familiar with the syntax of Python or any other C-family language. Let’s start!
The main bottleneck of the route analyzer lay in finding inexact matches of routes’ IP address prefixes in nested sets. In our research, this matching is a core functionality for matching routes on the Internet against public routing policies. The technicality of the research does not matter here. Instead, let’s look at the context from a programming perspective to understand the optimizations!
Simplified background
As the pseudocode below illustrates, our task is to implement the match_nested_set method (fn) on the Matcher data structure.2 This method should output whether the Matcher’s (IP address) prefix (self.prefix of type IpNet) matches a nested set of prefixes called name. Additionally, it should accept a Range Operator op that can modify how the prefix matching is done.
struct Matcher {
prefix: IpNet,
sets: BTreeMap<u32, Vec<IpNet>>,
nested_sets: BTreeMap<String, NestedSet>,
}
impl Matcher {
fn match_nested_set(self, name: String, op: RangeOperator) -> bool {
unimplemented!()
}
}The example pseudocode below checks if the prefix 193.254.30.0/24 matches the nested set CUSTOMERS when we apply the Range Operator Plus. The nested set CUSTOMERS has a member 69 that contains the prefix 193.254.0.0/16. Since 193.254.0.0/16 contains 193.254.30.0/24, and Plus specifies the “contains” relationship, then the method should return true.
let matcher = Matcher {
prefix: 193.254.30.0/24,
sets: BTreeMap(69: 193.254.0.0/16),
nested_sets: BTreeMap(
"CUSTOMERS": NestedSet { sets: [69], nested_sets: [] }
),
};
matcher.match_nested_set("CUSTOMERS", RangeOperator::Plus)
// => trueTo understand the problem, I started with a straightforward implementation.
Naive implementation
impl Matcher {
fn match_nested_set(
self,
name: String,
op: RangeOperator,
visited: Vec<String>,
) -> bool {
if visited.contains(name) {
return false;
}
visited.push(name);
let Some(nested_set) = self.nested_sets.get(name) else {
return false;
};
for set in nested_set.sets {
if self.match_set(set, op) {
return true;
}
}
for nested2_set in nested_set.nested_sets {
if self.match_nested_set(nested2_set, op, visited) {
return true;
}
}
false
}
fn match_set(
self,
num: u32,
op: RangeOperator,
) -> bool {
let Some(set) = self.sets.get(num) else {
return false;
};
set.iter()
.any(|prefix| prefix_and_op_matches(prefix, op, self.prefix))
}
}Explanations:
visitedtracks the nested set names we have checked to prevent infinite recursions from nested sets that contain each other.- Using Rust’s
let elsesyntax, we look upnamein the nested sets, and either bind the result to the variable, or returnfalseearly ifnameis not found.3 We apply the same trick tonum. - The
set.iter().anyexpression uses a common declarative pattern. It loops through theprefixelements inset, callsprefix_and_op_matcheson each of them, and returnstrueiff one of the calls returnstrue. - Helper function
prefix_and_op_matcheschecks ifprefixmatches Range Operatoropand another prefix.
Standard data structure changes
For starters, profiling and standard data structure changes were the lowest-handing fruit. Although I lost the exact performance record of early implementations, my benchmark code checked only 256 routes and clearly took minutes to run. Therefore, I realized that the naive implementation would not scale, and immediately started profiling the benchmark code to find where most of the time was spent.
Surprisingly, Cargo-FlameGraph showed that most of the time was spent on checking if set names have been visited (visited.contains). Since visited was a vector (a.k.a. array list), its linear search compounded with recursion to a cubic growth. I chose to use vectors because I thought most nested sets would have less than ten members, in which case linear search would be fine, but my assumption was clearly wrong. I changed visited to use HashSet and boosted the speed by about 10×.
The other effective change was to replace the maps. Matcher contains two B-tree maps, which are amazing sorted binary trees with lookup time complexity. However, hash maps have lookup. Therefore, it was a no-brainer to try replacing BTreeMap with HashMap. I recall this find-replace change causing the get calls to occupy seemingly larger areas in the flame graph! However, I also saw a 30% faster benchmark, so the hash map was indeed faster.
The hash map being only slightly faster than the B-tree map was no surprise. The B-tree map is cache-efficient, and avoids the somewhat expensive string hashing. This means, for smaller maps, the B-tree may be faster. Though, it turned out that my maps are large enough and my string keys are small enough, such that the hash map won.
These trivial changes turned out to be clear wins, and show some basics of performance optimization:
- Code profiling helps check our assumptions of run-time complexities.
- Data structure choices can greatly affect performance, and both asymptotic complexity analysis and benchmarking help pick them.
Avoiding redundant work
Besides the bottleneck from visited, further profiling showed our recursion calls all ended up at a slow expression:
set.iter()
.any(|prefix| prefix_and_op_matches(prefix, op, self.prefix))This classic linear search naturally reminded me of binary search. Though, a regular binary search does not suffice because range operators make prefix matching inexact, therefore individual checks made sense.
However, range operators do not permit arbitrary matches; they at most relax the matching to specific ranges. Meanwhile, sorting brings similar prefixes close to each other. Combining these two facts, I created an optimized algorithm based on binary search:
fn match_ips(prefix: IpNet, prefixs: [IpNet], op: RangeOperator) -> bool {
let center = prefixs.binary_search(prefix).map_or_else(identity, identity);
// Check center.
if let Some(value) = prefixs.get(center) {
if prefix_and_op_matches(value, op, prefix) {
return true;
}
}
// Check right.
for value in prefixs[(center + 1).min(prefixs.len())..] {
if prefix_and_op_matches(value, op, prefix) {
return true;
}
if !prefix.is_sibling(value) {
break;
}
}
// Check left.
for value in prefixs[..(center.saturating_sub(1)).max(prefixs.len())]
.iter()
.rev()
{
if prefix_and_op_matches(value, op, prefix) {
return true;
}
if !prefix.is_sibling(value) {
break;
}
}
false
}Function match_ips first obtains a starting point center using a regular binary search on the sorted prefixes; the prefix at center is the most similar to prefix. From there, we search rightward and then leftward in the prefix list, until they are no longer siblings with prefix—a necessary condition for matches.
Although this custom binary search is rather a hack out of intuition than a mathematically proven algorithm, I verified it against 26 million routes and got the same results as that of linear search. Hence, I deem it correct.
Prof. Italo Cunha also suggested using a prefix trie in place of the vector, but benchmarks indicated it was only about half as fast as the binary search,4 so I stuck with what we have. In theory, the trie may be imbalanced, causing long cache-unfriendly traversals, especially for large prefix sets. Vectors are obviously the most cache-friendly… which brings up the motivation for another optimization.
Conceptually, our custom binary search saves us from checking the prefixes far from center, thus we should gain more efficiency with larger, flattened prefix sets. However, flattening nested prefix sets results in large vectors and duplicated prefixes, which bloats memory and hurts cache efficiency. After empirical testing, I chose to flatten the nested prefix sets once, which yielded a best, 2× speedup.5
Custom data structure
At this point, the analyzer was processing 26 million routes in 48 minutes,4 or 9.3 routes per millisecond, a tolerable speed. However, I was too impatient to wait more than one day to analyze 800 million routes.
After reading about Bloom filters, it was tempting for me to eliminate more bottlenecks from the visited set. Recall that visited was a HashSet that stores the seen sets’ names to prevent infinite recursion:
fn match_nested_set(
self,
name: String,
op: RangeOperator,
visited: HashSet<String>,
) -> bool {
if visited.contains(name) {
return false;
}
visited.insert(name);
// …
}This proves expensive because of hashing and memory access. First, visited.contains hashes name and tries to look for it in the hash table, which would probably fail because nested sets containing each other are rare. Then, visited.insert hashes name again and finds a bucket in the hash table to store it.
With this analysis, I initially hypothesized that the repeated probing could be a major bottleneck. I knew that Rust’s standard library HashSet does quadratic probing, i.e., when a hash collision occurs during lookup or insertion, it hops around the hash table until it finds an empty slot. As we encounter numerous names, I guessed that visited was often somewhat full when we looked up unseen names, causing it to probe around until it finds an empty slot, which seems inefficient. Thus, I thought a Bloom filter could help by providing an early rejection when a name is not in visited.
Therefore, I implemented BloomHashSet for an insertion-optimized set. I reuse the hash table from HashBrown’s “raw” module, and added a bit vector for the Bloom filter. Initially, I used a Bloom filter package that hashed each name four times, but soon realized hashing is slow. Thus, I only hash once () and reuse the hash for both the Bloom filter and the hash table. To achieve a false positive rate of , I gave the Bloom filters 16× capacity compared to the hash table (). Experiments revealed that I need to preallocate an astonishing capacity of for the hash tables to hold all the prefixes in large nested sets. Finally, I reuse the same hash for both the lookup and the insertion.6
These efforts provided an around 10% speedup, which is not worth it in my opinion. The preallocation and hash reuse, the trivial parts, probably provided most of the speedup, not the Bloom filter, the fancy part. After further reading HashBrown’s source code, I realized my initial probing hypothesis makes little sense:
- hash collision is extremely rare with preallocation,
- HashBrown reveals multiple buckets for the same hash, and
- HashBrown’s quadratic probing is basically adding , so it is inexpensive and cache-friendly.
Lessons learned:
- When modifying based on profiling results, try to understand performance bottlenecks on a finer granularity. This involves investigating deeper into the profiling results and the source code, including for your dependencies.
- Preallocate your data structures for easy and significant gains.
Tenable caching
We have gone a long way removing performance bottlenecks, however, the overall algorithm remains—we are still calling recursive functions in a loop:
fn match_nested_set(/* … */) -> bool {
// …
for set in nested_set.sets {
if self.match_set(set, op) {
return true;
}
}
for nested2_set in nested_set.nested_sets {
if self.match_nested_set(nested2_set, op, visited) {
return true;
}
}
false
}Effectively, this recursion flattens each nested set on the fly. When talking to Prof. Harsha Madhyastha, I explained how caching the flattened prefix sets is untenable because of their massive sizes. Indeed, attempting to flatten every nested set to their prefixes consumed all 300 GiB of RAM and caused our server to hang! Hence, further flattening prefix sets is clearly infeasible—not a satisfying answer!
After being unhappy for a few days, I suddenly rediscovered a tenable caching strategy—flattening outside-in instead of inside-out. Flattening prefixes takes too much memory because each prefix (IpNet) is 18 bytes and they are numerous, but sets are represented with 32-bit numbers and are much fewer. Although flattening nested sets to their set numbers does not leverage our custom binary search, it eliminates the recursion calls, along with the major overhead of tracking visited (R.I.P. BloomHashSet), thus achieving the effect of partially caching the set flattening process.
Below are two of the few surviving flame graphs that shows the differences in profiling. match_nested_set is called filter_as_set. The monolithic bar on the left of each graph is data loading, and clearly shows the left graph took much more time besides data loading.
| Before flattening the nested sets | After flattening the nested sets |
|---|---|
With this caching optimization, the analyzer achieved its current performance of processing 779 million routes in 2 hour 49 minutes,7 or 76.9 routes per millisecond. This speed is 8× that of the first version using binary search, and over 300× that of the initial version if you do the arithmetic.
Notice how most current optimizations are very basic:
- using faster standard data structures,
- customize well-known algorithms to suit the problem,
- preallocation, and
- flattening nested loops.
So are the ideas behind them:
- profile-guided optimization (PGO),
- asymptotic time complexity analysis, and
- caching.
Last but not least, the moderate CPU, memory, and conceptual overhead of Rust made these optimizations somewhat easy.
About this article
I procrastinated on finishing this article for two whole months because it is quite non-trivial to write! My goal is to separate out the optimization experience from the research context and Rust programming, but, as you can see, they are tightly coupled.
I started by trying to lay down a simplified explanation of the routing analysis problem with several mathematical definitions, and even drew a diagram to illustrate their relationships. However, I soon realized that few people would want to read such definition-heavy text. Therefore, I resorted to throw away most of the routing context by renaming the variables and functions. For ease of reading, I converted the topic to a programming problem and explained it with pseudocode.
I am moderately happy about the outcome of these efforts.
Started 2024-05-30, finished 2024-07-29.
Last edited:
I ran the experiments on a server with dual EPYC 7763 64-Core processors with hyper-threading turned off to avoid IOMMU issues. ↩
These are simplified Rust-like pseudocode based on my real code. I removed the inessential references (
&or&mut) and parsing code to be friendly to readers unfamiliar with Rust. I also changed the names to avoid explaining the research context. ↩In the real code, we record any missing entries instead of ignoring them. ↩
This Pull Request shows the trie is slower: Replace
Vec<IpNet>with trieIpTrieto improvefilter_as_setbottleneck. I ran these experiments on the same server but with hyper-threading turned on, which may yield higher speed. ↩ ↩2Here is the Issue that records the current performance: RIBs processing performance. ↩
Creating Perfect Grayscale-Gradient Colormaps
When reviewing the submission instruction for a conference, I was reminded that the figures in my paper need to be “accessible” when printed in grayscale.
Usually, this would be done by adding patterns like triangles and circles in the plot. However, we were plotting stacked areas like the left one below, which contains dense and tiny vertical bars, so a grayscale gradient seems to be our only option.
I found nice grayscale-gradient “sequential” Matplotlib colormaps like the right one above, but they make it impossible to hand-pick a distinct and pretty color for each category.
“This is not a big deal,” I thought, “I’ll just use HSL (hue-saturation-lightness), set to , to a gradient, and hand-pick the .” Except I was so wrong—lightness is not grayscale, and figuring everything out took me the whole morning.
Result: hand-picked hues and perfect grayscale gradient
After wasting an hour failing to find any implementation on the Internet, I rolled my own scripts to calculate RGB color values from hue and grayscale, which allowed hand-picking hues while still having perfect grayscale gradient:
Below is the definition of these six colors. I hand-picked the hue values so each color looks natural, but the grayscale values are sampled linearly.
COLORS6: Final = tuple(
hue_grayscale_to_srgb(hue, grayscale)
for hue, grayscale in zip(
[60, 180, 120, 240, 0, 300],
np.linspace(0.96, 0.2, 6),
)
)
As a trade-off, I spent some time doing math on a whiteboard.
Math: calculating linear RGB from hue and grayscale
After some Wikipedia’ing, I extracted the formula for RGB-HSL and RGB-grayscale conversions, and did the math on the whiteboard above. For a color with linear red, green, blue values , hue , saturation , lightness , and grayscale :
Recall that we know and , and want to solve for , , and . The easiest bit is exploiting saturation and the formula for it:
The many conditions of the hue is a source of nightmare for simplification. Fortunately, I observed the formula for and found out only the order of the three RGB values matters if I introduce a new variable :
Since we can get the order of from , we can also know the grayscale coefficient for . For example, if , then we have:
That is, we need to solve this linear system:
This is then trivial to program. In the code, I first compute a potential answer using the first case, then fall through to the second case if the resulting , and then, boom! We have the RGB values from hue and grayscale.
…except we don’t.
Linear RGB vs standard RGB
RGB values computed from a linear grayscale gradient using the code above does not produce a grayscale gradient. In fact, I found some colors to have very similar grayscale.
This is because the RGB values we computed are linear RGB values, and monitors use standard RGB (sRGB) instead, with the conversion:
Why apply a weakly concave curve to RGB values? It turns out that human eyes are less sensitive to changes in bright colors, and so the curved sRGB values better reflect the perceived brightness.
Applying this knowledge to creating a grayscale gradient colormap, we need to first generate the gradient in sRGB, then convert each grayscale to linear RGB and apply the hue-grayscale to linear RGB conversion, and finally convert them back to sRGB. And, that is it! A perfect grayscale-gradient colormap with hand-picked hues.
Exercise for the reader
We fixed above, but what if we want to be able to change the saturation? Can you solve the system for given ?
2024-05-25
Last edited:
What an mdBook Preprocessor Does—Code Walk-through of mdBook-KaTeX
What does mdBook-KaTeX do? It is an mdBook preprocessor that pre-renders math expressions. For example, if you have this following snippet in your book:
Define $f(x)$:
$$
f(x)=x^2\\
x\in\R
$$
mdBook-KaTeX would pre-rendered it as:
Define <span class="katex"><span class="katex-html" aria-hidden="true"><span class="base"><span class="strut" style="height:1em;vertical-align:-0.25em;"></span><span class="mord mathnormal" style="margin-right:0.10764em;">f</span><span class="mopen">(</span><span class="mord mathnormal">x</span><span class="mclose">)</span></span></span></span>:
<span class="katex-display"><span class="katex"><span class="katex-html" aria-hidden="true"><span class="base"><span class="strut" style="height:1em;vertical-align:-0.25em;"></span><span class="mord mathnormal" style="margin-right:0.10764em;">f</span><span class="mopen">(</span><span class="mord mathnormal">x</span><span class="mclose">)</span><span class="mspace" style="margin-right:0.2778em;"></span><span class="mrel">=</span><span class="mspace" style="margin-right:0.2778em;"></span></span><span class="base"><span class="strut" style="height:0.8641em;"></span><span class="mord"><span class="mord mathnormal">x</span><span class="msupsub"><span class="vlist-t"><span class="vlist-r"><span class="vlist" style="height:0.8641em;"><span style="top:-3.113em;margin-right:0.05em;"><span class="pstrut" style="height:2.7em;"></span><span class="sizing reset-size6 size3 mtight"><span class="mord mtight">2</span></span></span></span></span></span></span></span></span><span class="mspace newline"></span><span class="base"><span class="strut" style="height:0.5782em;vertical-align:-0.0391em;"></span><span class="mord mathnormal">x</span><span class="mspace" style="margin-right:0.2778em;"></span><span class="mrel">∈</span><span class="mspace" style="margin-right:0.2778em;"></span></span><span class="base"><span class="strut" style="height:0.6889em;"></span><span class="mord mathbb">R</span></span></span></span></span>
and then feed it back to mdBook.
All the HTML tags might look a bit scary, but this is what all HTML-based math renderers do—generate a load of nested tags. It enables the expressions to look nice in a browser:
Define :
Most renderers just do this in the browser after the users load the webpage. mdBook-KaTeX lets you pre-render upfront, so the browser would not need to run any JavaScript.
In this article, however, I want to focus on the other side of mdBook-KaTeX instead—mdBook-KaTeX as an mdBook preprocessor.
Topic: what an mdBook preprocessor does
What does an mdBook preprocessor do? Well, in a nutshell, mdBook preprocessors are used to customize mdBook, the static site generator used to render The Rust Programming Language. Preprocessors read the loaded book data from mdBook, manipulate them, and pass them back to mdBook.
This sounds abstract, though, so let’s dive into what mdBook-KaTeX does, with simplified code, as a concrete example.
mdBook-KaTeX as a CLI App
mdBook-KaTeX is, firstly, a Command Line Interface (CLI) App written in Rust. It uses Clap to parse the arguments passed in:
$ mdbook-katex --help
A preprocessor that renders KaTex equations to HTML.
Usage: mdbook-katex [COMMAND]
Commands:
supports Check whether a renderer is supported by this preprocessor
help Print this message or the help of the given subcommand(s)
Options:
-h, --help Print help
-V, --version Print version
As we can see, mdBook-KaTeX only takes one command—supports. But, if no command is specified, it reads from StdIn:
$ mdbook-katex --help
# (Nothing happens).
# (Press control + D).
Error: Unable to parse the input
Caused by:
EOF while parsing a value at line 1 column 0
We don’t use the mdbook-katex command directly. Instead, mdBook would invoke it when it builds the book.
The supports command
All preprocessors need to have this command so mdBook can check whether it supports a renderer.
Usually, we use mdBook to render Markdown into HTML with the html renderer. So, after loading the book from disk, mdBook invokes mdBook-KaTeX like this:
mdbook-katex supports html
In this case, mdBook-KaTeX would just output nothing with status code 0 to indicate that it supports the html renderer.
Reading and processing the book data from StdIn
If no command is specified, mdBook-KaTeX should read the book data as JSON from StdIn.
let pre = KatexProcessor;
let (ctx, book) = CmdPreprocessor::parse_input(io::stdin())?;
let processed_book = pre.run(&ctx, book)?;
serde_json::to_writer(io::stdout(), &processed_book)?;Here, we read the context ctx: PreprocessorContext and the book data book: Book from StdIn using mdbook::preprocess::CmdPreprocessor. We then run it through our preprocessor pre and get the processed_book: Book. Finally, we print the book data back to StdOut, where mdBook would catch it and use it for the next steps.
So far, the process above is basically universal for any mdBook preprocessors. Yes, you can copy the code from the main.rs of mdBook-KaTeX and start your own preprocessor; the only change would be replacing KatexProcessor with another struct that implements mdbook::preprocess::Preprocessor:
pub trait Preprocessor {
fn name(&self) -> &str;
fn run(&self, ctx: &PreprocessorContext, book: Book) -> Result<Book>;
fn supports_renderer(&self, renderer: &str) -> bool;
}name and supports_renderer are trivial, but run is where the fun lives. For KatexProcessor, it finds the math expressions in each chapter of book and render them.
Processing book
Simply stated, we just loop over the all the chapters in the argument book above. For each chapter, we loop over its bytes, find the math expressions, and replace them with rendered HTML. Then, we stick these chapters back into book.
fn run(&self, ctx: &PreprocessorContext, mut book: Book) -> Result<Book> {
// …
book.for_each_mut(|item| {
if let BookItem::Chapter(chapter) = item {
chapter.content = process_chapter(&chapter.content, /* … */)
}
});
Ok(book)
}
Above, we use the for_each_mut method on book to iterate over its items and mutate them. We filter out the item: &mut BookItems that are BookItem::Chapter. We then call process_chapter on their content: String and assign the results back.
Below, we have a simplified version of process_chapter. scan: Scan is a custom scanner that scans through each byte in raw_content and produces Events that indicate the beginnings and ends of blocks.
fn process_chapter(raw_content: String, /* other args */) -> String {
let scan = Scan::new(&raw_content, /* … */);
let mut rendered = Vec::new();
let mut checkpoint = 0;
for event in scan {
match event {
Event::TextEnd(end) => rendered.push((&raw_content[checkpoint..end]).into()),
Event::InlineEnd(end) => {
rendered.push(render(&raw_content[checkpoint..end], /* … */));
checkpoint = end;
}
// …
}
}
// …
rendered.join("")
}Based on the types of the Event, we identify text blocks and math blocks, and apply the render function to the math blocks. The render function then uses the katex crate to render HTML. Finally, we join all the strings in rendered: Vec<String> into the new content of the chapter.
What next
If you have been following along, I hope you got a gist about how an mdBook preprocessor works and probably how to write one yourself! (If not, leave a question below).
In reality, though, the code for mdBook-KaTeX is way more complicated due to:
Configuration options
mdBook-KaTeX offers a wide range of options. We read these options from the ctx: &PreprocessorContext argument passed into the run method. Then, we further parse the configurations and pass them around.
Parallelism
Parallelism is more interesting.
Since the katex crate uses QuickJs to render KaTeX, which is ironically slow, KaTeX rendering has been the performance bottleneck. Initially, by manually scheduling rendering tasks using Tokio, I was able to get 5x speed on an M1 Mac, from 10sec to 2sec rendering my 30-thousand-word notes.
In v0.5.0, we switched to Rayon for simplicity, but the basic ideas are the same. To spawn threads and get parallelism, each thread ideally needs to own its data. So, we need to scan for tasks first, save them in vectors, and then execute the tasks in the vector in parallel. For example, this is how we actually parallelize processing each chapter:
let mut chapters = Vec::with_capacity(book.sections.len());
book.for_each_mut(|item| {
if let BookItem::Chapter(chapter) = item {
chapters.push(chapter.content.clone());
}
});
let mut contents: Vec<_> = chapters
.into_par_iter()
.rev()
.map(|raw_content| process_chapter(raw_content, /* … */))
.collect();
book.for_each_mut(|item| {
if let BookItem::Chapter(chapter) = item {
chapter.content = contents.pop().expect("Chapter number mismatch.");
}
});- We have to clone each chapter’s content and save them into a vector
chaptersfor each thread to own the chapter they process. - We use the
into_par_itermethod forVecand themapmethod, which Rayon provides, to process the chapters in parallel. - We have to use
for_each_muteven when gathering the chapters becauseiterunfortunately iterates them in a different order. - We call
revto iterate the chapters in reverse order, so when we put the rendered chapters back into the book, we can simply callpopon the contents to get them in the correct order.
Conclusion and preview
In summary, we have walked through mdBook-KaTeX as an mdBook preprocessor example to show what a preprocessor does:
- Handle
supportscommand. - Read the book from StdIn and parse it.
- Process the book by looping through its content and changing them.
- Print the book back to StdOut.
- Other enhancement such as option handling and parallelism.
The reality, however, is that, like many other projects, mdBook preprocessors get messy easily. We will talk about the mess mdBook-KaTeX was in next time.
2023-05-27, edited: 2023-06-11, 2024-05-24
Last edited:
Learn Like Machine Learning Models
This summer, my parents and I have been giving advice to more than a dozen of relatives and friends in mainland China on their kids’ education. I sense that Chinese parents are facing unprecedented challenges:
- Schools, and people generally, judge kids almost solely by their exam scores.
- The society spreads the common belief that each step of a kid’s education the later steps and eventually their life success.
- The parent community is highly anxious and comparing.
Schools work the asses out of kids in the hope of higher scores. Kids have more homework than they can finish without going to sleep late, even in elementary schools. After school, most kids are sent to tutoring organizations by their parents. High school kids study at school Monday through Saturday, 7 am to 9 pm. A kid is almost treated as a mere number.
We all know a person is not measurable as a single number, but the important question is what to do under the environment’s pressure. I believe it is time we revisit first principles and rethink the purpose of education. My conclusion is we should borrow many ideas from machine learning for human learning, both for kids and adults.
Last edited:
We are Learning Async Rust Wrong
A Rust conference talk recommended beginners to slap async on every function and .await on every function call when programming async Rust. I believe such suggestions reveal that many of us are stuck at surface-level understanding of async Rust. However, such phenomenon has to do with the way we get introduced to async Rust: many of us were fooled too much when we started learning async, we patched our understandings as we hit confusing walls. Instead, I believe we should adequately explain to newcomers the important bits of async Rust in the first place.
Lies: a common learning path
A primary reason people get started with async Rust is to use certain libraries. This is the most prominent if you try Rust for web-related endeavors. Consider the following scenario for a Python developer:
Having heard that Rust is fast like C++ without the SegFault, you recently learned some basic Rust. Soon, one of your Rust scripts needs to make HTTP requests, so you naturally search for a library akin to Python’s Requests. You find Reqwest, which uses this async/await syntax in its examples. “Okay,” you think, “guess I need to learn this new async await thing.” So, you search for how to use async await in Rust and find Tokio.
In fact, most developers either do Python or JavaScript. Then, consider this other scenario for a Node.js developer:
To test Rust as an alternative to Node.js, you start a new web backend in Rust. You search for Rust backend frameworks and find Actix and Axum, both uses async/await. “Ha!” you think, “I know this. This is basically the same as async await in JavaScript.”
In either case, you get the impression that async/await is this special syntax that you stick on top of regular code to make them run “asynchronously”… whatever that means. If you are a legitimate learner, you may read the Tokio tutorial and the Async Book instead of merely watching videos online. These valuable resources teach you additional important “caveats”, including:
- Running async Rust requires a runtime.
- Async Rust is only suitable for doing many things at once, not for CPU-bound tasks.
- You need to leverage synchronization primitives and adhere to thread safety (hello
Send + Sync + 'static).
However, you probably also miss several fundamental ideas of async Rust, which would bite you in the future either in programming or performance.
The missing context for async
As async Rust becomes more prominent, more and more people start doubting whether it brings more value than troubles. Common criticism include:
- High programming complexity when lifetime or generics are involved.
E.g., lots of tricky trait bounds are needed; the error messages are contrived. - Difficulty in performance debugging.
E.g., arbitrary functions can bottleneck the system, and it is hard to reason about. - Poor integration with synchronous code.
E.g., confusing panics when running blocking code in async context.
With all these overhead, one would naturally wonder if async Rust is worth it. Many even argue that going “asynchronous” is only worth it if you have extreme concurrency loads, and that operating system (OS) threads suit most applications better. To understand these concerns, we need a clearer context for async Rust.
The key point of async is yielding the control back to the runtime (Future returning Poll::Pending when polled). Although yielding is an overhead, it enables two superb features:
- Cooperative scheduling.
One task cannot block for too long; all tasks get a chance to run soon. - Cancellation.
When the runtime gets back the control, it can then apply cancellation, check other branches ofselect!, etc.
Now, to understand the nicety of these features, let’s consider Erlang’s preemptive scheduling, since async Rust shares many goals with it. Erlang powered soft massive-scale real-time systems such as telephone services and WhatsApp. It has OS-like preemptive scheduling over lightweight green threads called Erlang processes. Therefore, every Erlang process soon gets a chance to run. Bad Erlang processes never block the whole system. These guarantees enable services like telephone to function during massive overload periods, albeit slower. Additionally, you can terminate any Erlang process, and it would exit immediately unless it traps exit (in which case you can “brutal kill” it), providing the ultimate developer-friendly and reliable cancellation. In summary, to support massively concurrent real-time systems, Erlang’s OS-like preemptive scheduling optimizes for minimum latency and reliability.
Now, comparing Erlang’s scheduling to Rust without async, you would see the significant gap in between. While Erlang is built from the ground up to achieve preemptive scheduling using a virtual machine, Rust cannot even afford a runtime in the language. Additionally, Rust offers heavyweight OS threads that cannot be terminated from other threads, a big sucker! Hence, to get the niceties of async scheduling, Rust’s users are bound to make some sacrifices in terms of ease of development.
The missing lessons
If Rust fundamentally does not support preemptive scheduling or thread termination in the language, how can it achieve features similar to Erlang’s? This brings the core idea of async Rust: you, the programmer, bears the responsibility to make your program suitable for cooperative scheduling!
- Using data structures that implement the
Futuretrait, you specify tasks that can be suspended. - To complete these tasks, you continuously try to execute (“poll”) them.
That is the core of async Rust programming! Future provides a common interface for tasks that can be suspended, so that your code can yield control back to its caller, usually a runtime; only then, the runtime retains control for cooperative scheduling, suspension, and cancellation.
The runtime cannot achieve these features if your code does not yield! This fact brings several often missing yet important lessons:
- The benefits async Rust brings are not for free.
To emulate preemptive scheduling and immediate cancellation, each yield point must be close to each other. Thus, you need to meticulously insert yield points in suitable places of your async code, a daunting task that demands experience. - A single blocking function can break the benefits of async Rust!
If you have a sucker async function that runs for a whole millisecond before it yields, it surely will eat a whole millisecond as soon as it starts.
The async/await syntactic sugar, albeit eases programming, obfuscates async Rust’s actual underlying mechanism for beginners. In handwritten structures that implements Future, yield points are obvious—they are when you return Poll::Pending. In contrast, the async/await syntax hides yield points from programmers. Consequently, most beginners have no idea what a yield point is; even those who know the concept often hold this mistake that calling .await creates a yield point, presumably from JavaScript knowledge.
The lack of understanding in async Rust among beginners causes widespread mistakes that visibly hurt their performance. Many beginners thoughtlessly slap async on their functions, and call them like regular functions but with .await, just like the aforementioned conference talk depicts.
It also revealed why Rust would always suck compared to Erlang—cancellation is not free.
- In Tokio, you can “cancel” a task, but it only may get stopped when it yields the control back to the runtime.
This means any async function needs to be carefully written, with lots of yield points inserted (using yield_now()), and all heavy sync functions need to be wrapped in either spawn_blocking or block_in_place plus a yield_now() (I have tested, block_in_place does not yield).
Last edited:
Design Patterns Reveal OOP is Inherently Unsuitable for Systems
I finally got around to read the old legendary book, Design Patterns: Elements of Reusable Object-Oriented Software. I find it depicting an OOP landscape and philosophy much different that the OOP we see today. More importantly, it claims that OOP fundamentally sacrifices control and performance in favor of manageability, a sign to me that says OOP is unsuitable for systems programming, where control and performance is crucial.
Lack of emphasis on object implementation
A type is a name used to denote a particular interface. We speak of an object as having the type “Window” if it accepts all requests for the operations defined in the interface named “Window.” An object may have many types, and widely different objects can share a type. Part of an object’s interface may be characterized by one type, and other parts by other types. Two objects of the same type need only share parts of their interfaces. Interfaces can contain other interfaces as subsets. We say that a type is a subtype of another if its interface contains the interface of its supertype. Often we speak of a subtype inheriting the interface of its supertype.
This is to say that OOP does not stress the importance of each object’s implementation, but the messages it accepts (methods). Conceptually, the problem is, implementation details often decide the suitability. Calling a costly method in a long loop is almost bound to lead to performance issues. And, modern multi-threaded systems even have additional thread-safety concerns for each function. When one opts into programming on the abstraction level of interfaces, they become agnostic to these concerns.
Concretely, interfaces-agnosticism forces inefficient implementations. Most OOP languages resolve to boxing every object and doing run-time lookups to determine if an object implements an interface. Languages like Objective C and Cpp create fat structures that bumble with them the method pointers, and languages like Python and JavaScript lies onto using dictionaries as objects for this dynamism. All of these options incur performance penalties from dynamic allocation, lookups, and pointer redirections.
The popular alternative, generic programming with monomorphization, shifts this cost to compile-time and to the programmer. This is notorious in Cpp for its atrocious template function error messages, and in Rust for the complex where clause. To know that a data structure implements an interface, some work seems to be required.
However, more powerful compilers may be able to handle this for the programmer. Roc seems to abstract automatic monomorphization away from the programmers. Cig works entirely around generic programming by evaluating part of the program at compile time. These efforts may be able to promote the idea of reuse from OOP without either run-time nor human overhead, but they still fundamentally depend on knowing the data structure implementations—the “types”.
Disconnection between code and reality
An object-oriented program’s run-time structure often bears little resemblance to its code structure. The code structure is frozen at compile-time; it consists of classes in fixed inheritance relationships. A program’s run-time structure consists of rapidly changing networks of communicating objects.
This comes to say that programmers do not see what the system actual does when they read the code. Translated to today’s OOP, when you read a module, a class, or a method, you have little idea what domain-specific tasks it performs. This just makes it difficult to map real-world problems to the code, adding hurdles to reason about the system for any given tasks.
For a concrete example, the authors details one aspect of why this indirection exists: the pervasive use of references (“acquaintance”). References connect objects into a graph, a costly task for a garbage collector, but more importantly, I believe, a constant though exercise for programmers to track.
Last edited:
Deprecated
These entries are stored only for the history.
Last edited:
How did we get here? WordPress?
This was when I set up the blog in WordPress.
WTF
Isn’t WordPress for non-technical people? Why would I use WordPress?
Also, why am I starting a blog? Didn’t I say that I don’t need a blog?
The reality
Well, if I wrote something moderately decent and long, I need a more decent place for it other than GitHub issues and Reddit.
Of course, I could use GitHub Pages to make a static site, but people wouldn’t be able to comment on that.
Of course, I could set up a whole server with a JavaScript front-end library (probably Svelte) and a back-end with Rust, deploy it on Amazon lambda, and connect it to a PostgreSQL database. That would be really cool. But, then, I would probably need to find a domain for it and pay $20 a year… I don’t want to.
Also, people don’t care about you knowing how to mess with AWS, they only appreciate the silly CSS tricks they see that makes up the front-end. So, setting up a server manually and hosting a blog probably would not be worth it.
What I get with WordPress
- A subdomain.
- Free content server.
- No setup, I just write and post.
Conclusion
For now, that is it. I’ll post random articles here. But, I will manually keep a Markdown copy on GitHub.
2023-05-26
Last edited:
Curriculum Vitae
- Education
- Research Experience
- Teaching Experience
- Awards
- Side Projects
- Outreach
- Skills
[]
Sichang He (Steven) sichangh@usc.edu
Ph.D. Student in Computer Science GitHub & YouTube @SichangHe
Networked Systems Lab, University of Southern California sichanghe.github.io
Education
University of Southern California (USC) Aug. 2024 – present Los Angeles, USA
Ph.D. student in Computer Science Advisor: Harsha V. Madhyastha
– Research focus: User-facing measurements and enhancements of the Web.
– Selected courses with projects:
∗ Advanced Computer Networking (A+): JSphere: measure webpages’ browser API calls to classify JavaScript.
∗ Advanced NLP (A): Reproduced an EMNLP LLM detection paper and challenged its generalizability.
Duke Kunshan University (DKU) & Duke University Dual Degree Aug. 2020 – May 2024
B.S. in Data Science (by DKU) & Kunshan, China &
B.S. in Interdisciplinary Studies (Subplan: Data Science, by Duke) Durham, NC
– In addition to studies in Data Science, completed many courses in Computer Science and Mathematics, effectively
emulating a triple major.
– Selected courses with projects:
∗ Computer Network Architecture (A+): async TCP server and client in Elixir and CLI REPL shell in Rust.
∗ Data Acquisition and Visualization (A): Poster using D3.js, Svelte, and TypeScript.
∗ Computer Organization and Programming (A+, at Duke): Binary search tree in MIPS assembly and ring buffer
in C; fifth place in PizzaCalc assembly length optimization competition (68 lines).
∗ Numerical Analysis (A+); Intro Abstract Algebra (at Duke), Complex Analysis (A).
– Achieved full grade on all five courses at Duke University in the Fall 2022 semester.
Zhixin High School Aug. 2017 – Jun. 2020 Guangzhou, China
– Chemistry Olympiad competition team; Biology Olympiad competition team.
Publications
[1] Sichang Steven He, Calvin Ardi, Ramesh Govindan, and Harsha V. Madhyastha. “DeGenTWeb: A
First Look at LLM-Dominant Websites”. In: under submission. 2026. url: https://github.com/SichangHe/
DeGenTWeb_docs/releases/tag/preprint-imc2026.
[2] Sichang Steven He, Ramesh Govindan, and Harsha V. Madhyastha. “Poster: Did I Just Browse A
Website Written by LLMs?” In: Proceedings of the 2025 ACM Internet Measurement Conference and Student
Workshop (IMC, Dual Submission). Oct. 2025. url: https://github.com/SichangHe/DeGenTWeb_docs/
releases/tag/cam-ready-imc2025.
[3] Sichang He, Italo Cunha, and Ethan Katz-Bassett. “RPSLyzer: Characterization and Verification of
Policies in Internet Routing Registries”. In: Proceedings of the 2024 ACM Internet Measurement Conference
(IMC). Nov. 2024. url: https://github.com/SichangHe/internet_route_verification/releases/tag/
imc-camera-ready.
[4] Sichang He, Beilong Tang, Boyan Zhang, Jiaqi Shao, Xiaomin Ouyang, Daniel Nata Nugraha, and
Bing Luo. “FedKit: Enabling Cross-Platform Federated Learning for Android and iOS”. In: IEEE INFOCOM
2024-IEEE Conference on Computer Communications Workshops (INFOCOM WKSHPS). May 2024. url:
http://www.arxiv.org/pdf/2402.10464.
Sichang He (Steven) - University of Southern California Page 1 of 3
[]
Research Experience
Research Assistant Aug. 2024 – present
Networked Systems Lab, USC Advisor: Harsha V. Madhyastha
– Surveyed usage, weakness, and extensions of the Coalition for Content Provenance and Authenticity (C2PA).
– Detect, understand, and respond to AI-generated contents on the Web, their characteristics, cause, and effects.
Independent Researcher on Internet Route Verification Apr. 2023 – May 2024
Independent research, Federal University of Minas Gerais, Brazil (Remote) Advisor: Italo Cunha
– Designed and implemented an efficient and comprehensive parser for the Routing Policy Specification Language
(RPSL), a language used in the Internet Routing Registry to document public interdomain routing policies, guide
public peering, and aid routing issue troubleshooting.
∗ Studied and complied with RPSL semantics in RFCs, covering over 99% of all real-world RPSL use cases.
∗ Optimized the parser to interpret and verify hundreds of millions of routes per hour.
∗ Found RPSL usage varied widely among autonomous systems (ASes).
– Employed the RPSL parser to verify observed interdomain routes; analyzed verification reports and identified com-
mon RPSL usage patterns and usage mistakes.
∗ Provided tooling to verify routes against the RPSL, helping improve interdomain routing security.
∗ Identified and implemented checks for 6 major explanations to why routes fail to match the relevant RPSL.
Research Assistant for Mobile Federated Learning (FL) Project Mar. 2023 – May. 2024
The FedCampus Team, EdgeIntelligence Lab, DKU Advisor: Bing Luo
– Authored FedKit, open-source SDKs to streamline real-world FL experiments across Android and iOS devices,
enabling training shared ML models collaboratively without sharing private data on smartphones.
∗ Contributed to the Flower FL framework: revamped the Android example; helped correct the iOS example.
– Led and managed the systems development for the FedCampus Android/iOS app, leveraging personal health data
from over 100 participants to conduct real-world FL and federated analytics experiments on DKU campus.
∗ Supervised and mentored 4 undergrads and 1 M.Eng. student in mobile and web development.
∗ Investigated and led core technology adoption, including Flower, Kotlin, and Flutter, facilitating development.
Research Assistant for Search Engine Research Project Dec. 2021 – May 2023
The Search So Team, DKU Advisor: Jiang Long
– Developed a feature-rich open source web scraper in async Rust to scrape DKU sites, intranet, and Duke sites.
– Improved backend HTML processing, frontend interface, and version control.
Presentation
[1] Bing Luo and Sichang He. FedCampus: a Privacy-preserving Data Platform for Smart Campus with
Federated Learning and Analytics. Flower AI Summit, 2024. Mar. 2024. url: https://www.youtube.com/
watch?v=K7yu2jvu_t8.
Teaching Experience
Teaching Assistant, Introduction to Programming, DKU Nov. 2021 – Mar. 2022
– Hosted weekly lab sessions; created the course’s first video tutorial on development environment setup.
Math & CompSci. Tutor, Academic Resource Center, DKU May 2021 – May 2022
– Obtained CRLA’s International Tutor Training Program Certification, Level I .
Sichang He (Steven) - University of Southern California Page 2 of 3
[]
Awards
• ACM Internet Measurement Conference (IMC) Travel Grant (Sep. 2025)
• ACM Internet Measurement Conference (IMC) Student Travel Grant (Aug. 2024)
• Senior Scholar-Athlete Award through the Running Club, DKU Athletics (Apr. 2024)
• Silver Medal, International Genetically Engineered Machine (iGEM) 2022 DKU Team (Oct. 2022)
Developed the team wiki independently; helped non-technical members adopt Git; validated protein designs with
modeling software.
• Dean’s List (Spring 2021) & Dean’s List with Distinction (Fall 2021, Fall 2022, Spring 2023), DKU
• Chancellor’s Scholarship & UGRD Entrance Scholarship, DKU (merit-based, Fall 2020 – Spring 2024)
Side Projects
Open Source Developer & Maintainer of Rust Crates Nov. 2022 – present
– mdBook-KaTeX, a math expression preprocessor for mdBook with over 160k+ downloads on crates.io.
∗ Took over maintainership by publishing a fork when it was unmaintained.
∗ Fixed numerous bugs and developed new features, resolving more than 20 GitHub issues others had opened.
∗ Improved speed by over 10 times by adopting parallelism and avoiding repeated rendering.
– mdBook Language Server for instantaneous live previews. Diff-friendly plain-text and Markdown formatters.
Author of Open Source Web Forum Using Ruby on Rails Jun. 2022 – Aug. 2022
– Featured infinitely nested comments; deployed on Heroku.
Outreach
• Chinese Editor & Translator at DKU Intersections Journal Jun. 2021 – Aug. 2021
Co-translated three English articles into Chinese; reviewed and edited multiple articles and Intersections’ website.
Skills
Natural Language Mandarin (native), Cantonese (fluent).
Programming Language
– Invested and proficient: Rust, Python, Elixir, JavaScript.
– Used in projects: Kotlin, Dart, Swift, Ruby, Java, Lua, TypeScript, Svelte, HTML, CSS, C, SQL, Racket, L
A
T
E
X,
PL/pgSQL.
– Familiar: C++, Fish, Bash, Julia, Go, Erlang, Gleam, VimScript, Elisp, Mathematica, MATLAB, Scala, R.
Computer Software
– Selected frameworks/libraries: SQLite, Playwright, Django, Phoenix Framework, Tokio, Tailwindcss, D3.js.
– Selected development experience: SSH, Tmux, Neovim, Docker, Kubernetes, Evcxr, Arch Linux, Hackintosh.
Sichang He (Steven) - University of Southern California Page 3 of 3
[]
Last edited:
Business
Last edited:
Auction Package Redirection
- combined package need expensive & slow business-level custom control
- need to split down to 1 (set of) item per package
- packaging material: auction company should give enough cushion, but need boxes
Delivery
- can use EMS?
- delivery company personnel may be under-educated
- need additional insurance
- FedEx is easy on Chinese custom
- UPS is hard on Chinese custom; but include insurance
Last edited:
Phone Screen Protector
- Jieyi: should directly mail to buyer wholesale
Popularity
- Peter: most USC student have latest 2 gen iPhone
- Ayman: most Pro model; some Pro Max, mainly parents
Price
- low end: $1~2 per count on eBay
- mid end $5~10 on Amazon
- high end to $60 on Amazon
- $20 ZAGG InvisibleShield Glass+ Screen Protector for iPhone 16e/ 14/13/ 13 Pro - 3X Shatter Protection, High Scratch Resistance, Oil-Resistant, Reinforced Edges, Easy Install
- $60 ZAGG XTR4 Screen Protector for iPhone 16/15-11x Stronger Tempered Glass, Blue Light Filtration, Anti-Reflective Technology, Graphene Reinforced, InvisibleShield, Easy Dust-Free Installation
Specs
| brand | style | box dim. (cm) | box dim. (inch) | wholesale |
|---|---|---|---|---|
| Magic Box | smooth | 21.8x11.8x2 | 8.6x4.6x0.8 | 7.5 |
| Magic Box | privacy | 21.8x11.8x2 | 8.6x4.6x0.8 | 10 |
RTego LLC
- start w/ https://www.michaels.com/
Cost
recurrent:
| item | cost | unit |
|---|---|---|
| Hubstudio Subscription | 40 | ¥/month |
Last edited:
Diary
Guests: don’t read this. This is private.
Last edited:
start
2022-03-17
I have this feeling that I am about to be unable to write.
Been having all sorts of math, stats, and CS courses, there is really not much writing to do. DKU provides little paper to write, specifically, little literature-ish things.
All said, I decided to start writing diaries. Not for people to read, but more for me to stay sane on the writing side.
choice for the diary
my take on blogs
Some people have blogs.
It’s a good idea to have your things on the web, so it lasts longer than your local file, or worse, a piece of paper made in the 2020s. But, I dislike the idea that you write something solely about yourself for others to read.
That does not affect my adoption of the shell of blogs. I will put this diary on the web.
generate HTML
To post something on the web, you need HTML, and there are different ways to make HTML.
WordPress
The most popular way is WordPress.
43% of the web is built on WordPress. More bloggers, small businesses, and Fortune 500 companies use WordPress than all other options combined. Join the millions of people that call WordPress.com home.
What a great ad from WordPress themselves! I would have fallen for it if I did not know how bloated WordPress is.
The DKU website itself runs WordPress. And, the performance is “insane”. You can open a small webpage in 5 seconds! Imagine? And also some webpage in 30 seconds! Amazing!
The Intersection uses WordPress for its website (not published yet). I saw the source code it generates for a simple article: 7 layers of nested divs! And, it also has “insane” performance.
If I look back from the future and see WordPress’s dominance, what would I think? People were crazy?
No, people are lazy and will not change if things work.
hand write
It is possible, but the HTML part probably would take much more time than the text part.
Plus, the CSS part would be the most annoying.
Markdown
Markdown is a lightweight markup language that looks nice as source code. It is rendered by converting to HTML.
I feel fast and delightful writing Markdown for my notes. Also, I used Markdown to write presentation slides and it is just minimum effort.
Without more trash talk, it is sure that I would choose Markdown if possible.
But, what flavor?
Markdown flavor
Markdown has a shit ton of different flavors.
Some does not eat your \n, some support \(\TeX\), and some support PHP.
What I need is:
- Math support
- Code block support/ highlighting
- Nice look
- Simplicity
- Git friendliness (short lines)
- Live Preview
I ended up considering Hugo and mdBook only for fast and simple Markdown-HTML conversion.
Hugo
I found Hugo by searching Markdown website (or something like that) for DKU iGEM Wiki (a future thing). It is marketed as an easy-to-use and fastest static site generator.
It has many themes that the community made. Most of them look like PowerPoint templates (no offense).
I spent way too much time looking around to find a nice looking theme, and found hugo-book and Doks.
hugo-book just looks like a crappy version of GitBook, might as well use GitBook. But, GitBook is “converted” from open source to “proprietary services” (what a shame). Might as well use mdBook which is still open source.
Doks look nice, but it shocked me by taking 500MB on my disk (how does some HTML and CSS text take so much space?). It is absolutely not anything lightweight, and it reminds me of WordPress…
Without a good theme, I have no Nice look nor Simplicity and I need to implement Math support and Code highlighting myself (which, is just adding some <link> on top of the file, but still, annoying). Also, some themes I tried are buggy and do not even work if I added the math support.
mdBook
mdBook basically supports everything I mentioned out of the box.
The “downside” is that it has only 5 themes (which you can try by clicking the brush top-left), and they all have the same structure. However, I don’t need a thousand custom themes that are crappy, instead, one good theme is good.
It saves me the burden to fight with CSS (great!).
That is why you are seeing this diary in mdBook form.
web server
I need a server to host the diary.
I can host it on my machine, but a domain name is just a waste of money in my opinion. And, getting a paid server provider is the same.
Then, I saw GitHub as a free service provider: GitHub pages. And, it actually does the thing: host your website. It also is fast.
The downside is that GitHub is blocked from PRC using DNS pollution (or something). GitLab is not and it works in PRC. However, I do not like the GitLab interface, and GitLab is much slower and laggier.
Eventually, I decided to choose GitHub.
coda
That will do. I just “wasted” a whole morning on this thing.
Now, I will go to lunch and then put this on GitHub.
Last edited:
VSCodium
2022-04-04
I switched from Visual Studio Code (VSCode) to VSCodium.
I am writing this text using VSCodium.
the reason to switch
This may be a weird reason, but I switched from VSCode to VSCodium because of performance.
the problem with VSCode
I was happy using VSCode. However, Saa told me VSCode was resource-intensive. She said her Lenovo laptop fans ramped up as soon as she opened VSCode.
Being on an M1 MacBook Pro, I have never experienced ramping fans. However, I did experience warm keyboard when I browsed the web with VSCode in the background, but I blamed it on the external monitor and too many browser tabs. I checked Activity Monitor, Visual Studio Code.app seemed to be using very little CPU and memory, but there were also several “renderers” using as many resources, and they combined to above 1GB of memory and 1% or 2% CPU.
After some searching about VSCode being resource-heavy, I found out that VSCode uses Electron, which uses a Chromium engine to render everything, which means VSCode is essentially just an app running in its bundled browser. It turned out Electron used about 2% CPU and half a Gig of memory.
Using a browser at its core guarantees that VSCode is sure to be as resource-heavy as any browsers. Thus, it is fundamentally flawed.
searching for an alternative
I spent some time looking for other text editors.
Sublime Text seems to be the most popular alternative, however, it is strictly proprietary, and I caught words that you need to buy it and join its developer version to get the latest version and support. Atom is automatically excluded from the possibilities because it started this “mini-browser app” shenanigan in the first place.
Neovim is a “pure,” performant text editor. I actually tried VimR and Neovide. They provide something far from a drop-in replacement to VSCode, though. I imagine I would need to spend days configuring everything.
Then, I read about VSCodium. I learned that although the VSCode project is open source under the MIT license, the Visual Studio Code app Microsoft ships is built using Microsoft’s custom configuration with their telemetry. This reminds me of how bloated Windows’s are… I decided that switching to VSCodium will probably disable a lot of trash processes Microsoft forces me to run when using VSCode. And it would make a drop-in replacement.
installation via Homebrew
Brainlessly, I ran this to install VSCodium:
brew install vscodium
I sim-linked ~/.vscode-oss to ~/.vscode and ~/Library/Application Support/VSCodium to ~/Library/Application Support/Code. I also deleted everything that I don’t recognize as my configuration file nor extensions.
Upon opening, VSCodium was glitchy. It opened deathly slowly and was far from as responsive as VSCode. I was wondering whether that was because of some magical configuration Microsoft does when they build VSCode. But, I soon recognized bigger problems.
the extension problem with VSCodium
Right out of the box, Remote SSH does not work anymore. I uninstalled it and tried to reinstall it from the marketplace, but it turned out that VSCodium uses an open-source marketplace instead of the one VSCode uses. This marketplace does not have anything from Microsoft. Installing the extension from a file downloaded using the browser show it in the list of installed extensions, but it still does not work. It turned out that Remote SSH is strictly proprietary and only works on Microsoft’s Visual Studio Code build.
After some fiddling around, I found SSHFS works pretty nicely. It has all the features Remote SSH has, and it allows you to save the password of the remote users’, and to enable it only at certain workspaces instead of forcing you to enable it globally. It actually seems better than what Microsoft offers. I wonder why there are so few downloads.
I also followed the instruction from VSCodium’s GitHub to enable VSCode’s marketplace by adding a product.json. This change broke the Python extension and did not give me the VSCode marketplace.
I can tell easily that the VSCodium marketplace has way fewer extensions available, but I guess as long as the extensions I need are not “Visual-Studio-Code-only,” I can just install them via the browser and some commands.
performance and macOS ARM support
Why is VSCodium so slow? Why? Why on earth?
I opened Activity Monitor and found that it is “Intel” —the app from Homebrew works via Rosetta translation…
I immediately went and searched for a macOS ARM build. I saw a GitHub issue, where they discussed not being able to build VSCodium for MacOS ARM because the GitHub CI did not have a macOS ARM worker option. It turns out that they have not figured it out yet by now.
However, there is a guy that has an M1 Mac Mini, and they built MacOS ARM binaries and released up-to-date versions on GitHub. I downloaded their build and it works nicely. I checked Activity Monitor, VSCodium seems to use much fewer resources than VSCode while still using quite a lot…
Last edited:
The Run
2022-05-08
It is 7 on the morning. I woke up at 6:30 because of the noise on the train—people talking, watching videos while letting the sound out loud, and noise from plastic bags when someone grabs something to eat.
I am on a “fast” train from Jinhua to Guangzhou. “Fast” is the type of train prefixed with K and it is ironically the slowest. The train goes about 100km/h and it was considered “fast” when it came out.
I am writing this in a bed with narrow space around me.
The lockdown
I have been in a lockdown in Kunshan for a month. During the time, we have been having courses fully online. The total places that we are allowed to go is the union of campus, the apartment, and the school shuttles that travel between them. We are also forbidden from delivery food due to “potential contamination” while the school shut down all canteens but one.
Permission to leave
Near the end of April, we received an email that says something about students telling the school that they need to leave to apply for the visa because they are going aboard, and asks those who want to leave before May to fill in a questionnaire so that they can send them out of Kunshan on a bus to Suzhou. I did not want to leave just in a few days because I have all the belongings to pack. There is also a catch that the school will throw away all the personal belongings left.
On May 1, they sent a similar email “to collect information.” I calculated and decided to leave on May 7. I bought the plane ticket and filled in the questionnaire.
If that worked as expected, I would have arrived home by now. But, the airline was cancelled on May 4. After a lot of searching, the alternative is “fast” train from Jinhua.
The questionnaire was a mystery. Nothing came back from the school. On May 5, because the airline was cancelled, I called Chinese Students Services (also CSS, ironically). They answered the phone after a few attempts. The answer was that the school was “collecting information,” and they just sent the people leaving on May 5 to Suzhou. CSS told me that the information for us will come in a day or two. They also implied that the bus usually leaves around 9 or 10. My impression was basically: we don’t ensure anything would happen so we have no responsibility.
Anyway, at 9 a.m. on May 7, I got the bus and left Kunshan the jail.
A crowded square
The ride to Suzhou North Railway Station was smooth, with no questions asked on the way. This was because because Suzhou was just downgraded to “low risk area” and the travel code would be green as opposed to green with an astroid for a city with COVID cases.
The station has two layers of gates, each with several guards who check people’s tickets and travel code. Only those who have already bought the tickets and have a green code can enter the station.
After I enter the station gate, a man behind me commented: “so many stuffs! You are moving house? Where are you going to?” I told him Jinhua. He said he was going to Jinhua as well and asked me where am I from. “Hunan.” “That’s great! I am from Hunan as well, we can have companies.” said the young man wearing glasses with a large suitcase.
We entered the station, which has a large square in front of the building, enclosed by large fences. The people at the door of the building checked our tickets and told us that we may only enter after 1:30 p.m. because our trains are in the afternoon.
It was still 10 a.m. The sum was shining above us and the weather was hot. We found a tree in the square, parked our luggage, and sat there.
The square was so crowded. It is about 100m wide with a lot of stone seats, but nearly every seat is occupied, and luggages are everywhere.
The man told me that there was a wave of people going home. He said now that Kunshan has green travel code without the astroid, people can finally leave after one month of lockdown. He showed me a few videos on his cellphone. One of them was people raiding a shop for food in April. Another was blood everywhere on the ground, and people standing around doing nothing. He told me that people in his factory had a fight and the policemen had just entered. The leading policeman laughed in the video: “killed someone, huh?” as if he was watching a comedy show.
The man complained to me that Jiangsu people are less kind than Hunan people. He said that Jiangsu people tend to put up a fight easily. Apparently, he was leaving this place and going home, and he must have quit his job in the factory.
With this new “friend” watching out for my luggages, I checked around the square for shops. It was quite a walk. The square spans a whole area and was full of people. There was no sign of shops open except for two shops at the edge of the building, but both of them are closed. The men’s and women’s room were outside of the station. There was an exit by the entrance of the station. Two men sat there, one of them holding the fence gate handle. They told me to leave my National ID on the bench with the other people’s, and take it when I came back.
The real problem was lunch. There wasn’t even a place that sells water. Our “friend” spotted a man eating delivery food. I asked the eater, who told me that he received the delivery food across the fence. I ordered and ate delivery food for lunch, which was handed into the square above the fence.
When I was eating my lunch by the tree, a few aged women came to water the tree. We had to move all our luggages and watch the women water the tree until everything around the flowerbed is wet. They laughed and watered more trees while yelling at people to leave.
Enter the station
At 1 p.m., our “friend” suggested that we join the queue to enter the station building. At that time there were already two dozen people in the queue, and everyone could only enter half an hour later.
As time goes by, the queue grew longer quickly. I took out the laptop and tried to read, but the laptop was so hot under the sun, that I gave up soon and started to stand still.
After 25 minutes or so, the queue began to move forward and people started to sneak in. The sneakers either smiled and just jumped in the queue, or pretended to be dumb. A station staff came to argue with some of the sneakers, but there were so many of them that the staff did not see some.
Nonetheless, I entered the station and enjoyed the air conditioner.
The rest
I jumped into the train to Jinhua 2 hours later. The train was full of luggage and I had to put my luggage between the carriage. The situation was not better in the train from Jinhua to Guangzhou. So many people are running away from Jiangsu and it makes total sense.
Last edited:
Feeling Lost
2022-05-15
It is 12 p.m. at night and I’m the only one up at home. I just had a shower and my hair is still half-dry. During the shower, I was thinking and I was feeling lost. I thought again about my Signature Work, which does not exist at the moment.
I wrote to a computer science professor for recommendation for mentors. In that email, I stated that I wanted to deploy a server with Rust and WASM but I felt that it would be impossible to accomplish anything alone and I considered scientific computing as well. One move I think I did wrong was to mention a project with another computer science professor, who the professor I wrote to recommended for mentor without a reason. I guess they are just pushing me back to whatever I have.
The reason I asked another professor for recommendation for mentors is right because I sensed that there are something wrong with the way the current project runs. I feel like that we are not doing anything special while getting excited —we are just reinventing the wheel and trying to enjoy it. Text searching and test processing, both are something that countless people have done before, and our team is just importing Python libraries, smashing it into the project and writing glue code, and calling it a progress.
A while ago there was a seminar where computer science professors and students showed what they had done. All of them used machine learning to treat some problems that may or may not have any meanings. I have this impression that people are machines learning for machine learning. It looks tempting, but I know that machine learning is extremely data-demanding and therefore hard. I decided that machine learning would not be a main theme in any research of mine unless I really have a huge amount of preprocessed data, which I probably won’t have.
I have this feeling that computer science people in DKU tend to play with little toys that people from a more academic background would discard. This could be similar for data science people. I am considering to do some mathematics studies… I thought about it and recall that my mathematics is a huge pile of mess, being taking all these “applied” math classes at DKU. I just took the advanced linear algebra last session and I had zero motivation to study it along side with CS301 with our lockdown and online classes. I don’t really know what the heck I learned in these courses. I know they have a lot of proofs that is important, but I don’t really understand why any of them is constructed like that. I also did horrible in CS301, which I confirmed today by checking the final exam grade.
I thought to myself that I don’t care grades that much. I figured that I care more about my experiences. But, I do care about grades. The way this shows is that bad grades make me visibly unhappy, and good grades does not make me happy. It is just poisonous.
I am now thinking that I really should reread the books that I ought to read but instead attended “slides classes.” I think learning mathematics is not about taking those freaking classes. The classes that I did well, I learned them in advance by book. I am guessing that I actually learn much less effectively taking classes than reading books for the following classes. But, I have been too lazy to read all the books before taking all these classes. A lot of the time definitely went to YouTube.
Right now, I’m learning JavaScript, while also planing for more Rust, Python, and C exercises. But, I suspect that these are not as important as reading more mathematics books for me. I need to change…
Last edited:
Linux VM And Neovim
20220806
After a long time, I decided that I should write something again. I’ve been sick multiple times during the months since coming back to Canton. I highly doubt that the pathogen density here is much higher than in Kunshan. Despite that, I have actually done quite a lot of stuff recently.
Linux VM on M1 MBP
After fiddling with qemu and virt-manager on my M1 MBP, I gave up and went back to Parallels Desktop.
virt-manager and qemu
I used virt-manager with qemu on Arch Linux and Ubuntu Linux. On M1 MBP, though, KVM does not exist, and virt-manager cannot connect to hvf in my experience. Therefore, I was merely using qemu’s emulation and the performance was dreadful.
Parallels Desktop
Having met obstacles using virt-manager, I decided to try out Parallels Desktop again.
The problem was how to get it.
At first, I searched for the good old Russian TNT. The search took a long time and the results were diminishing. I then looked for Chinese cracks.
All of the Chinese cracks use PD runner, which I knew about and also tried. Basically, it is a standalone program that calls functions from Parallels Despite to launch VMs after the trail period has ended. Some sites even sell PD runner for quite an amount of money.
I don’t like the idea of getting a caller program somewhere randomly on the internet and using it just to launch an official program. I remembered vaguely that this thing was leaked from GitHub. And, that was the right place to search for it. The program was hidden behind a non-default branch for some reason, but I managed to download it.
I simply got Parallels Desktop from their official website. It turned out later that the PD runner from GitHub works just fine. Now, the problem became which distro I should use.
The distro for the VM
A big thing about Linux distros is that no all of them support ARM that well. It also come with the actual reason why I need a Linux VM. There are certain tools, such as valgrind, that cannot be used on macOS. And, I want to be able to get my hands on some of them. Because that’s the reason, I decided that compatibility is the top requirement. Therefore, Alpine, which is very lightweight and “suckless,” is excluded from my choices. I use Arch Linux for my other laptop, but I believe ARM is not a first class support for them. It usually comes to Ubuntu as the choice for such VMs. But, I dislike distros like Ubuntu because they fiddle on the original repos (like Debian’s repos) and produce what effectively is a Frankenstein of repos.
Their base, Debian is good though, but Debian stable provides packages that are on average one or two years old. Luckily, I recently got to know that Debian testing is actually very usable. It is also a rolling-release distro. It seems like a very good choice for development which is what I would do on the VM anyways.
Installing the VM
I grabbed a weekly build ISO and installed it as a Parallels Desktop VM. The first time, I got it wrong. I used TUI install, partitioned the drive, gave it 100MB for the boot partition and the rest for the home partition. At the end of the installation I selected “install system utilities” and did not install any desktop environments. As the installation process proceeds, I was watching the virtual disk growing larger and larger in size on Finder. It grew from under 1G to over 2.5G.
I wanted a minimum installation, and that was not. I deleted the VM and tried a second time. This time, I did not select anything to preinstall during the installation process. However, I made another mistake. At the end of the installation, it prompted me to remove the installation media, which I did later by deleting the ISO. What happened was, it said that the VM did not have any OS installed! I reconnected the ISO and booted into rescue mode, but I didn’t know what to do to rescue it. So, I installed it again on the same virtual disk.
Upon fresh install, the VM was about 2G, which makes me happy. However, I tried to install packages using sudo and found out that sudo wasn’t installed. So, I used su to install doas because I heard that doas is smaller and simpler to use. I began to understand why people just stick to Ubuntu. Most people would not be able to handle this. They would just go online and type in whatever command they see in a guide to install something. And, the guide would most certainly tell they to sudo. I installed both clang and GCC and both of them are about 0.5G, therefore the VM grew much bigger. It was still much smaller than it could be if I were to install a desktop environment. My previous VMs took around 5G to 7G even without the compilers.
I decided that I want to stick with the terminal for this VM. So, the text editor choice would naturally be Neovim.
Neovim
My main text editor is Code - Insiders at the moment. The reason why I switched from VSCodium was that the fantastic Pylance extension would only run on Microsoft’s builds. Also, the insider build is slightly faster in my experience. I also tried Emacs, but ended up not using it. That would be for another story. Previously, I was using SpaceVim, which is a Vim distribution. It has numerous plugins built-in and supports various languages out of the box. The problem though, is that it is large and hard to install. The installation depends on GitHub connection, but my VM is not guaranteed to have that. I decided to go vanilla on the VM. But, at the same time, I want to go full vanilla Neovim because that is how I can learn.
I went ahead and read the neovim-lua guide on GitHub, and added the configurations I want to my pure-Lua config files. To keep things small, I found a theme on GitHub based on One Light and copied it to my repo.
After all that was done, I was pretty happy about my Neovim setup on the VM. But, I was less happy about my Neovim setup on my Mac. I tried to port my configurations to the macOS side but apparently those conflict with SpaceVim settings. I finally decided to ditch SpaceVim, which also meant that I would need to have my own plugin manager. I landed on dein for its lazy-loading features for performance. It took two days to fiddle my Neovim setup and learn Lua. After using some language servers, I concluded that Neovim cannot replace VSCode for me. It is much more convenient to open up a file instantly from terminal with Neovim. But, it lacks features like toggling comments on keyboard shortcuts. Although one could probably configure Neovim to do all that, it take quite a amount of time. Also, the way VSCode is used is that you start it and let it stay, therefore, you get much faster startup speed when you open another file. But, you start and close Neovim frequently, and each time, the language server or whatever extensions you have loads for a while.
Lua
However, I am largely happy about how the configurations turned out. I got to fiddle with Lua, which is a different beast than the other scripting languages I used. Lua’s performance is simply fantastic while it sucks at not having arrays. It also took me a while to learn Lua’s custom Regex. After gaining some familiarity with Lua, I decided to write the yabai helper in Lua. The helper takes the information about all of the windows in the current space and calculates the next window to switch to. In this way, I managed to let yabai switch window in a circular fashion, including the windows yabai does not manage.
Last edited:
Back from Duke
20230313
I have abandoned this diary for a long time since I went to Duke last fall semester. This could be reasoned at follows:
- I was taking five courses at Duke and was busy.
- I made suboptimal ex-relationship decisions that are time-consuming.
- I was occupied with shiny new tech, trying out Neovim, Elixir, etc.
Duke semester
Duke seemed like a real school. People walked around carrying books and talking to others. In all my classes (except perhaps CS 203), class activities were unmatched compared to DKU classes.
The courses have loads of homework, almost as much homework as DKU courses each week. But, the courses are not difficult as DKU courses in that you have the time and chance to “breathe.” Unlike crappy DKU seven-week courses, Duke courses last for 14 weeks, and give you one extra week for reviews, one extra week for final exams.
I took:
- CS 203, Discrete Mathematics for Computer Science
- CS 205, Computer Architecture
- CS 371, Intro to Machine Learning
- MATH 401, Abstract Algebra
- MATH 431, Real Analysis
I have not much motivation to talk about them in details.
In general, Duke CS classes taught me real stuff, unlike DKU CS classes…
Ex-relationship
The relationship ended with a special COVID related drama that I could not foresee.
What I did foresee, though, was its nature of temporariness. Back then, I wrote the relationship contract with a clause regarding break ups.
What I think went wrong, was that I pet them too much and they behaved more and more like a pet, dependent, purposeless, and naughty.
Last edited:
Elixir Phoenix
I need a back end technology. First, I thought Ruby on Rails was the most suitable. Now, I am turning to the Elixir Phoenix Framework.
Leaving Rails
Rails was said to be the most productive back end framework.
I learned Ruby and walked through the Rails “getting started” document last summer. Then, I made a forum.
Pain started to increase when I was making the forum:
- The template Rails generated became less useful as the project went on.
- For adding functionalities such as history, tags, and search, I introduced more and more plugins, each of them:
- needed me digging documentation to find my usecase
- had part of their documentation out-of-date, so I had to dig the GitHub issues as well
- introduced more “magic” to the codebase
Main reasons why Rails suck:
Too much “magic.”
- Everything works highly relying on metaprogramming.
- Global namespace pollution means it is hard to figure out what things are, where they are defined, and the language server couldn’t find those either.
Backwards incompatibility.
- Rails 7, as I was using, clearly made a lot of solutions that worked in Rails 6 not working any more. Devise, the authentication plugin, e.g., wouldn’t work properly.
Hotwire was not fun to play with.
It’s like playing a puzzle game, instead of helping me.
Learning Elixir
- Went through Elixir official doc.
- Did a few Exercism exercises.
- Went through Functional Web Development with Elixir, OTP, and Phoenix until they started to use Phoenix channels and the API has changed.
- Technically, only learned about Elixir, not Phoenix.
- GenServer is the main way to handle states and side effects.
Learning Phoenix
I have not actually started using Phoenix yet.
When following the Functional Web Development book, I wanted to separate the Elixir project into several modules, so I created an umbrella project and initialized a Phoenix project inside it. The project straight-up could not build.
I then initialized a Phoenix umbrella project. It builds and runs fine. But, it creates a weird project structure that intertwines with Phoenix. So, I guess I will just not use umbrellas when I want true separation.
Last edited:
mdbook-katex
20230315
What and why I use it
As I progressed in developing the 2022 DKU iGEM Wiki using mdBook, I realized that the iGEM competition requires that all content be hosted on iGEM, so using MathJax from a CDN was technically against the rules. Instead of hosting a MathJax ourselves, I tended to another option I found—compiling math expressions into HTML using KaTex, provided by mdBook plugin mdbook-katex. Previously, my notes have already being using it, so I was confident that it works well.
Advantages above MathJax:
- No need to write weird
\\(delimiters, just use$and$$. - Page load is fast.
- No jumping around when reloading when doing
mdbook serve.
The project was in a bad condition
It was November 2022, the owner of mdbook-katex, lzanini, had not made any updates on the project for a year.
The last stable release it has was 0.2.10, the CI started failing after that and never got fixed. Despite that, another contributor, Matthewacon, added many features. Therefore, the README suggested users to install mdbook-katex via Cargo and Git:
cargo install --git "https://github.com/lzanini/mdbook-katex"
There were also several very old issues lying there, such as math blocks breaking tables and code blocks. Pull requests were made, but they got no response neither.
The option static-css was extremely slow for me, taking around 20 seconds on my slow network. I later would find out that I was downloading all the fonts twice every time the book gets rebuilt.
I posted an issue asking whether the repo was being maintained. That issue got no response.
mdbook-katex2
I decided that I should fork the project and maintain it myself because I relied on it.
An issue with a simple fork would be that I could not cargo install it. Cargo has a “first come first server” policy so that new packages can never take old packages’ name. I still wanted to have my fork on crates.io so I changed the package name to mdbook-katex2.
I did many tries to fix the CI on my fork, creating an array of “CI failed” message in my mailbox, and eventually got the CI to pass.
I published the crate and people could install it using just Cargo and no Git. So, I opened an issue introducing mdbook-katex2 and thanking the original author.
To my surprise, that issue lead to a speedy response from lzanini. The original author offered to add me as a collaborator so I can maintain the original repository. They argued that it would be more convenient for the users.
It turned out quite well, in my opinion. I accepted the collaborator invitation and started to maintain mdbook-katex.
Last edited:
Spring 2024 Ideas
Last edited:
Rethinking The Web
Browser space
- HTML is messed up.
- It is a “markup”, but it can contain scripts (logic). It should be the other way around.
- Cannot share and reuse HTML because of its side effects. HTML does not have
#include, only the bad<iframe>. - Same reason why HTML is seldom cacheable ⇒ dead links ensured.
- HTML is not safe: cross-site scripting (XSS).
- Even CSS is messed up in the same way.
- Cannot share and reuse HTML because of its side effects. HTML does not have
- If it were to exist:
- It should be strictly content-based, without the ability to be scripted.
- It should be a templating language. Just look at how many HTML-based templating languages we have.
- It should be called by other “real” programming languages to manage logic, not the other way around like we do now.
- Alan Kay: HTML should not exist at all. Content on the web should contain the specification of how they should be interpreted and rendered. (Source: The Computer Revolution Hasn’t Happened Yet, 1997).
- It is a “markup”, but it can contain scripts (logic). It should be the other way around.
- WebAssembly (WASM) is a wasted potential.
- It does not have feature parity with JS: No DOM manipulation, no direct access to browser APIs.
- Browsers are fundamentally screwed in the first place: browser APIs are in JS, dynamic and complex. (I hope I am wrong).
- The realistic way WASM could have saved the world is for it to lie under JS.
- We now have to choose between the two, and do the horrible interop, but if JS compiles to WASM, we don’t.
- But, that is not going to happen because JS is so complex.
- We do have JS to WASM compilers. They just embed a JS runtime.
- We now have to choose between the two, and do the horrible interop, but if JS compiles to WASM, we don’t.
- It does not have feature parity with JS: No DOM manipulation, no direct access to browser APIs.
- The web beat other worlds for apps.
- Not because JS is amazing, but because the browser is the only accessible app development interface that works consistently cross-platform.
Last edited:
Rust
Threads & Async & Coroutines & Lunatics
Last edited:
Spring 2024 Activities
2023-03-28
Flower “AI” Summit 2024, London
Professor Nicolas Lane invited Professor Bing Luo to give a talk at Flower Summit 2024 about FedCampus. Since Professor Luo thought it to be a nice opportunity for me (or rather, he does not know how FedCampus works technically), he brought me in to co-talk.
As a result, I begged DKU Undergraduate Studies and Division of Natural and Applied Sciences (DNAS) to sponsor my trip to London, and got a whopping ¥3500 + ¥5000.
I stayed at London from 03-13 night to 03-16 morning, brought a poster about Fed Kit, and gave of a talk. The talk was live streamed on YouTube, together with all other Flower Summit talks. It was one of the only talks where the audience was laughing… But, the live stream did not catch that sound track.

On my flight back, however, I had some thermal cycles, and caught what I believed to be a bacterial infection. After I got back, I heard someone else also got sick on a plane. Man, flights are dangerous! Not because they crash, but because they are infectious.
Overall, I bought only 3 brunches at the inn, and figured out all other meals with unhealthy free food from the summit. On 03-16, my butt hurt, so I was standing and kneeing, and got really tired in the afternoon, and started sleeping in the conference. I immediately went to sleep once back to the inn, at around 18.
And then, I suffered from a -2hr jet lag when I got back to DKU.
People asked me whether it was fun. I told them the conference was “fine”.
The academics wanted to present their papers - so, yeah…
I did talk to a few Ph.D. students and some Flower Labs people. I remember people being unsatisfied when I told them to find me on GitHub, and asked for my LinkedIn. I guess I have to use this atrocious ad platform now. There was a recently-graduated dude from New Zealand - who added machine learning to his statistics research because everyone was doing machine learning - and a few people who basically told me that they “borrowed” our implementation to do on-smartphone federated learning.
I mean, FedKit is open source, and so is the code we contributed to Flower, but getting 0 credit is less fun than anticipated. I now understand why people put those corporate-style authorship and copyright notice in every single one of their source files.
Last edited:
IMC ’24
Started: 2024-11-10. Finished: 2024-11-29.
I am on an A380 flying back to Los Angeles at 0.9 mach. IMC ’24 just concluded yesterday. It was nice in that I heard several interesting talks, met enthusiastic people, and ate random Spanish food at the conference. I also gave a talk, which mostly went as planned. It was unfortunate in that I got sick midway through the trip and struggled with jet lag despite having stayed in UTC+1 for 4 days before the conference.
Let me recall the mishaps I experienced leading to the conference and the journey in Europe.
Funding issues
The $2000 trip was originally not funded at all.
After my paper was accepted, I asked three departments of DKU for travel funds, and got none. The main argument is I have graduated. I offered a proposition to the executive vise chancellor, offering to list DKU as my only institution in the paper. Apparently, they did not recognize the significance of having papers in conferences this prestige, despite DKU not having papers in conferences at this level. With that, DKU officially have zero direct contribution in my paper, so I decided not to list them as my institution.
This was at one point a huge time eater and upset moment. It is especially upsetting because I got a personal offer to partially fund my travel, in exchange for DKU being listed as my institution, which would have looked very shameful. However, this is understandable because I know DKU is experiencing a decline in administrative efficiency. Though, Italo also thought it looked bad, and listed DKU as his institution alongside UFMG.
Eventually, I followed Harsha’s advice to apply for a student travel grant from IMC, and fortunately got it. This twist, however, caused delays in my preparation for the conference, and had time implications I would discover later.
Visa shopping
IMC ’24 was in Madrid, Spain, but I did not got a Spanish visa. This would normally have meant I would not be able to enter Spain at all, as is the case for several presenters. I was at the conference thanks to a workaround for Schengen visas.
I applied for the Spanish visa through their official agency, got rejected because of minor issues, and estimated that the time line for visa appointment rescheduling was unrealistic. Not only that, they appeared to not know what they were doing when I was at the visa center, and blocked my rescheduling due to their government-grade service website. This is when I started to think about giving up with the Spanish.
I checked the rules for Schengen visas and countries that process visas quickly, and eventually chose France. The visa went through smoothly and quickly. The only downside was I needed to stay in France for the same number of nights as I did in Spain. So, I was forced to tour Paris for 4 days, a strange thing to say.
This is not exactly visa shopping because my 4-night stay at Paris makes the visa application legitimate. This is apparently a thing. Later in the community session in IMC, I heard Christophe talk about how one could get a visa appointment for Norway or some other Nordic countries when the visa topic was brought up.
Paris and how I got sick
The flight to Paris CDG went via Dallas DFW, and the DFW-CDG flight was an uncomfortable 8 hours. I got the worst seat, between the window and the aisle. No posture was comfortable. The food was also pathetic; both my neighbors left most of their meals untouched.
What was worse? American Airlines people had very little tolerance for passengers hanging around. To relieve the stress in these long-haul flights, I usually do these small standing sessions for around ten minutes at the back of the plane. This plane, however, was configured to have no room at the back, so I hung around the food lounge and the emergency gates in the middle. Flight attendants would just go by and tell me to go back to my seat. One of them even stopped by to say they cannot have people camping around.
This could have been a cultural thing. There was a fat man in a suit sitting near one of the gates I hung around. I was standing there leaning on the jump seat drinking juice, and he stared at me. After a while, he got up, so I moved around to leave him some room to go to the lavatory. Instead, he stood on my face, and said “go somewhere else”. “This guy thinks he owns this place,” I thought. I stared at him, had some more juice, and walked to the gate on the other side. Apparently, fat Americans simply get offended when you appear near them and get face to face.
When I got to Paris in the morning, though, the chaos began. Since the AirBnB reservation starts from the afternoon, I decided to hang around a park between the airport and the place I stayed at. It was a very rural area with wind blowing across. I did not bother to put my puffed jacket on, and got a bit cold. Maybe I should have taken it more seriously at the time.
The lunch at a random restaurant proved Paris’ food to be much cheaper than that in Los Angeles. This continued to be true throughout my stay, even in more central areas. What annoyed me was the lack of local food. Near the place I stayed at, it was all Pakistani, Indian, and Turkish food. Even near La Louvre, I walked in a huge block of all Asian food. I was like “what the heck is going on with this city? Where is the local food?”
On the second day, I toured Musée du Louvre for 4hr. Unfortunately, it turned out the museum sells tickets with time slots, which is basically reservation. Since I spent the time before the trip desperately preparing for my talk, I only booked the tickets on the day I arrived and got the late 13:30 entrance time. The museum closes at 18:00.
Having a late entrance to the museum did not bother to make the whole tour ultra long. I only woke up at around 10:00 due to jet lag, and walked around the famous piss river after my breakfast. Paris is really coherent with the styles of roads and buildings. I kind of see why people like the city and find it romantic. In the museum, I saw beautiful NSFW oil paintings and took selfies with the tiny transgender Mona Lisa painting people line up to see.
On my way back though, I got into trouble. I was taking the same metro line that I went to central Paris with. It stopped at a station and never resumed. Eventually, the driver said something in the announcement and people looked upset, some of them getting off. After a while, everyone got off and started waiting on the platform. The driver got of the train and walked to the other end, and drove it back!
I assumed there was a problem with the train, and waited for the next one like many other passengers did. The next train came, and we got on. And, the announcement from the driver started… People were upset, and eventually got off. Some left the station. After a while, the driver said something to the crowd, and some people got on, so I followed them. The train drove back to the previous station!
Okay, so I realized there was some problem with the line and what the driver offered us was to drive us back to the previous station which had transfer options. In the monitors that displayed information, I finally saw the English translation of the announcement. It said that the line was partially shut down due to an unattended bag, and that the service would resume after some time. I went to the platform to wait for the service to resume, but got systematically kicked out by the people shutting down the line. Some of them knew English and explained to me that I needed to change my route.
I had to take another metro line and transfer to a bus. That bus station for the exact bus line I needed to take was also moved, for some reasons, and it took me a while to figure it out. With the rush and mishaps, I also took the wrong direction once and missed a bus because of not waving for it to stop. The supposedly 50min trip took 2hr, and by the time I got to the AirBnB place it was already 22:30. I apparently did not learn this lesson that public transport in a language I completely have knowledge of is a guaranteed disaster, and did it again later in my trip to the airport.
This was when I woke up and felt something stuck in my throat the next afternoon. I realized it was almost a cold and it became dangerous to my talk because I lost my voice. I had had trouble speaking for extended periods of time in the days leading to the trip when I practiced my talk, but this one was finally the bomb detonated. I could hear my mumbling talk being very deep when listening to the recordings of my practice talks.
After a day of rest and not getting better, I decided it was time to do something other than hoping for self-healing. I asked my AirBnB host. She typed a line of text on my phone and told me to go to a medicine store nearby and show they this text. I went there, went in line, saw the guy behind a counter, showed him the text, and told him I had a throat inflammation in English. The guy replied in French, went to the back of the store, and came back with some medicine. So, I bought that random drug and took it according to my host’s instructions. I also aborted all my travel in Paris and stayed in bed until I left.
The CDG airport was super small, with no restaurants or shops in it. The counter only checked my boarding pass and simply let me onto the plane, not even checking my passport. This was how I got to Madrid.
Madrid and the talk
Madrid was surprisingly super crowded. The MAD airport has a fitting name, that the airport has many levels and a long and slow line connecting many terminals far apart. The metro was crowded, stations have direction signs only at the entrances but not at the platforms, and the platforms are connected by mazes of passage ways. The conference was near Gran Via, meaning “great road”, and it was a super crowded central area with mountains of people, mostly Caucasian, walking around the streets by the various shops. It was also much more expensive.
The hostel I stayed at was quite a place. The staff were all young people who spoke English, and they continuously organize events like free food and tours around the city. I was not in the mood for any events because the talk still had some major problems although it was only two days before I would give it. Italo wanted to show some whois queries about Spanish autonomous systems and gave me some materials last-minute. Belly lying on the twin bed in my 4-person shared room, I managed to figure out where I could sneak in that part to my talk.
But, I could not practice my talk aloud. I was lucky to meet Ethan at the reception the day before the conference. He knew I was sick and reminded me the most important thing to do was to get enough rest. That was kind of hard to do, though, because I completely did not overcome my jet lag. I would go to bed at around 22:00, think about the talk in my head, and become fully awake at around 01:00. My roommates were also nuts, and they would come back at 02:00 after who knows what. The streets outside the hostel were also loud, and the earplugs I got from the front desk was kind of weak. Anyway, I managed to get up at around 08:00 every day and stayed awake for the conference.
Maybe it could have been a good thing that I practiced my talk in my head. The midnight before I gave the talk, I thought of something nice. Italo always thought the introduction was a slow ramp and wanted something more catchy, as did Ethan. I essentially came up with a catchy clickbait intro at 01:00 after 3hr of thinking in bed. I got up, checked the Sao Paulo time, and realized I would not receive any feedback from Italo about this new intro before I give talk if I waited until morning, so I called him. He picked it up, said he liked it, and told me I am crazy and should go to sleep after finding out it was 01:00 for me. The next day, I gave the talk, and visibly saw people to be looking when I said the crazy intro. I think this last-minute idea from thinking in bed was a huge enhancement to my talk.
Anyway, the talk went most as planned. People seemed to be listening instead of focusing on their phones and laptops, and I said most of the things I planned to say. There were some minor details. During my dry run at NSL, people suggested that the projector may screw up the slides a bit and I needed more margins in each direction. At the conference, I saw that the projector was very good and we could see the whole slide, but the speaker would stand in front of the main screen and block the view. The stupid thing about the setup was that the lectern would block part of the main screen, and it blocks more after the speaker stood there and put their laptop on the lectern. I really wanted to avoid blocking more screen, although I did place a large margin at the bottom of each slide, so I essentially pressed down the laptop screen after plugging it in, which I believe made the experience much better for the audience at the center. However, I messed up with the clicker and clicked a lock-screen button near the end of my talk, although I fortunately immediately restored the setup thanks to not having speaker notes and only needing to fullscreen my Google Slides. Later, I talked to another speaker, he was like “after I saw you did that, I was saying to myself ‘DO NOT press that button’ when I did the presentation”. I think I went over time, though, because my session chair Phillippa looked unmoved and said we only had time for one quick question, although she probably simply is that style and the conference had always been overtime at that point.
Presentations are hard. I saw so many people committing “presentation crimes”: having walls of text, reading the slides or speaker notes, dumping information without giving the audience time to comprehend, having a final slide with only “thank you” in it, and standing still without eye contact. I am glad that I avoided those.
The conference overall
Jet lag made it unnecessarily hard to enjoy the conference. I could barely be excited, and I am surprised quite a few people decided to talk to me anyway during the breaks and when eating weird Spanish snacks. Most of these are PhD students. The professors are super busy doing stuff, and many of them are “chairs” of something. I later found out there were somewhere around 20 chairs…
There are a few interesting talks. I forgot most of them, but I remember learning that QUIC is not unfair against CUBIC, many Web-related research are social, and crypto is encroaching into the IMC. The community session was quite an experience, where the chairs discussed the review process, how they separated long and short paper reviews this year, and what they should do to bring PhD students into the review process. I never knew the existence of shadow PC, which sounded stupid. They also touched on the visa issue. I talked to George Smaragdakis about letting people share their visa experiences; he has not replied yet. I also saw Dave Levin, who rejected my PhD application very late. It was kind of fun to see these people.
At the end, I remembered to ask people for contact. It is quite difficult when you do not want to use social media to stay in touch. I gave in and added some people on LinkedIn, while only exchanged emails with others. It is obviously difficult to stay in the loop with emails, but I guess I will write people emails from time to time when I remember them. I really need to prioritize that over all the other dues!
Last edited:
Recovering Files on Exxact
I wanted to delete two empty log files, so I selected them in the NeoTree file explorer in Neovim, and pressed d for “delete” and y for “yes”. It lagged for a while, then, to my horror, only one folder was shown in the file explorer.
“This must be a display glitch,” I thought, but running ls confirmed that everything is deleted except the file Chromium was writing to. That is, data collected in roughly a month are all gone.
Since Exxact is a server, I asked Haodong if it had any backups. The answer was negative. Haodong suggested I run some recovery tools, reasoning that the file system should have only marked the file content on the disk as unused rather than zeroing them out.
I asked Perplexity and it first found Testdisk, but I tried it and it showed no files to undelete. I though I was using the TUI wrong, so I asked ChatGPT how to use it and was advised to use Extundelete instead, but it also did nothing, even after unmounting the disk:
% sudo extundelete /dev/nvme0n1 --restore-all
NOTICE: Extended attributes are not restored.
WARNING: EXT3_FEATURE_INCOMPAT_RECOVER is set.
The partition should be unmounted to undelete any files without further data loss.
If the partition is not currently mounted, this message indicates
it was improperly unmounted, and you should run fsck before continuing.
If you decide to continue, extundelete may overwrite some of the deleted
files and make recovering those files impossible. You should unmount the
file system and check it with fsck before using extundelete.
Would you like to continue? (y/n)
n
% sudo umount /dev/nvme0n1
% sudo extundelete /dev/nvme0n1 --restore-all
NOTICE: Extended attributes are not restored.
Loading filesystem metadata ... 28616 groups loaded.
Loading journal descriptors ... 0 descriptors loaded.
Searching for recoverable inodes in directory / ...
0 recoverable inodes found.
Looking through the directory structure for deleted files ...
0 recoverable inodes still lost.
No files were undeleted.
% sudo fsck -f /dev/nvme0n1
fsck from util-linux 2.34
e2fsck 1.45.5 (07-Jan-2020)
Pass 1: Checking inodes, blocks, and sizes
Pass 2: Checking directory structure
Pass 3: Checking directory connectivity
Pass 4: Checking reference counts
Pass 5: Checking group summary information
ssd1: 27/234422272 files (3.7% non-contiguous), 15003479/937684566 blocks
% sudo extundelete /dev/nvme0n1 --restore-all
NOTICE: Extended attributes are not restored.
Loading filesystem metadata ... 28616 groups loaded.
Loading journal descriptors ... 0 descriptors loaded.
Searching for recoverable inodes in directory / ...
0 recoverable inodes found.
Looking through the directory structure for deleted files ...
0 recoverable inodes still lost.
No files were undeleted.
I then followed suggestions from Testdisk and ChatGPT to try PhotoRec, which did recover 251591 files, but with all the file paths missing and made-up names.
I tried Ext4magic, but it also did produce recovery with file paths:
% sudo debugfs -R "dump <8> /hdd1/nvme0n1.journal" /dev/nvme0n1
% cd /hdd1
% du -sh nvme0n1.journal
1.1G nvme0n1.journal
% sudo apt-get install ext4magic
% sudo ext4magic -M -j /hdd1/nvme0n1.journal -d /hdd1/DeGenTWeb_recovery/ /dev/nvme0n1
I now have a bunch of files I do not know where they belonged. Since I point to file paths in my database, these files are not very useful…
While I reported this bug to NeoTree, I found more issues where people lost their whole work directory. I should not have trusted NeoTree for deleting files.
Update: I threw gave up on recovering the files and crawled all data again. The recovered files have their path and name lost, and the contents are mangled, so they would have required much effort to sort out. So, I chose to rerun the scripts instead.
Last edited:
IMC 2025 Record
Cost
| Cost ($) | Why |
|---|---|
| 43.07 | A0 poster printing at UW-Madison |
| 294.96 | round trip LAX-ORD |
| 81.30 | round trip Chicago-Madison |
| 650 | student non-member registration |
| 23.73 | Waymo home to LAX |
| 30.35 | Waymo LAX to home |
| 32.51 | Dinner Oct 26 (other receipts not recorded) |
| DoubleTree 5 nights (covered from UMich) |
People talked to
- Seungju Lee: reserved tan Princeton girl w/ glasses doing security & privacy; said security people open many projects and switch often; I took a picture of her during the student workshop
- Mia Weaver: corporate-behaving thin pale girl w/ very light-colored eyes; general chair’s student at UW Madison; registration chair doing random chores; publish at B-tier conference for nice food; likes outdoor rock climbing & cycling; buys BCycle monthly pass; vegetarian
- Yasin Alhamwy: U. Kassel; very active boy; switched to outage detection; met last year
- Remi Hendriks: U. Twente; super star who listens to many talks and questions
- Florian Holzbauer: U. Vienna; tall pale polite boy; presented Ukraine outage detection; met last year
- Enze Liu (Alex): UCSD PhD, CMU postdoc; many feedbacks on LLM website detection
- Olivier Benba: dark handsome happy French boy; GaTech; met last year
- Max Gao: mature-looking; KC’s student at UCSD; pessimistically doing telescope
- Harris Ransom: Ethan Kats-Basset’s new student, a little shy
- Grant Williams: chunky friendly light-colored GaTech boy whose personal gmail contains conversion ration from acre to square miles; met last time at IMC
- Sebrina Reis: friendly happy extroverted pale girl w/ messy curly hair w/ glasses doing security & censorship at UCSC; likes PL but dislikes PL research community bc they are impractical; vegetarian; ask me to tell her if I go to Bay Area
- Adrian Kunz: U. Kassel; median tall pale boy w/ glasses; not talkative near Yacin; “don’t know what I’m doing for research”
- Ben Du: UCLA postdoc chef vibe officer (CVO)
- Carl Bruhner: Linköping U. (Sweden); mature-looking businessman doing security
- Weili Wu: GaTech boy; did policy atom; spent all time at arcade bar shooting
- Elisa Luo: chill tan UCD girl studying LLM impact on Web
- Aruna Balasubramanian: program chair; let me say hi to Harsha
- Wei Hao: graduating from Columbia to co-found w/ Junfeng Yang a startup that tests agents; did spam email LLM detection while branching out to study LLM detection w/ Ran Li; did UW Madison undergrad
- Deepak Gouda: Ceilia Testart’s Indian student who remember RPSLyzer from a year ago; working on BGP, RPKI
Last edited: